You'd think reading and writing numbers would be straightforward, but anyone who's worked with raw data long enough knows it's rarely that simple. I spent three weeks last year debugging a batch import process where dates were being misread as financial figures because the locale settings on the production server didn't match the development environment. The fix wasn't complex, but tracking down the root cause took longer than it should have.
The core issue is that humans write numbers differently depending on where they come from, and machines interpret those differences literally. A comma means thousands in the US, but decimals in much of Europe. Leading zeros get dropped by default parsers. Scientific notation hides precision. None of this is wrong, but every one of these choices can silently corrupt your data if you're not paying attention.
Reading And Numbers: The Practical Side
When you're reading numbers from a file, database, or API response, the first thing to understand is that text doesn't equal value until you explicitly convert it. A string that looks like "1,234.56" is just twelve characters to a computer. You need to strip separators, identify the decimal marker, handle edge cases like leading plus signs, and then cast it to the right numeric type. Doing this manually for every input is tedious and error-prone. Most people reach for built-in parser functions, which is fine until you hit an edge case those functions weren't designed for.
I learned this the hard way when processing a CSV export from a legacy system. The numbers used angle brackets as thousand separators — like <1,000> — which every standard parser rejected. My workaround was a two-step process: first a regex pass to strip the brackets and commas together, then a locale-aware conversion that treated everything as US-format after the cleanup. It added about twenty lines of code, but it prevented the entire pipeline from failing silently.
Writing Numbers Without Losing Information
Writing numbers out is trickier than reading them because you're making choices that the reader has to interpret correctly. Decimal precision, rounding rules, grouping separators — each one is a decision. The common pitfall here is assuming the default formatting is always appropriate. If you output a floating point number using standard conversion, you might get something like 0.30000000000000004 instead of 0.3 because of how binary floating point works. That extra noise comes from the representation, not the math.
A few concrete practices that actually help. Use fixed-point or decimal types instead of floats when precision matters, especially for financial or scientific data. Set explicit locale context when generating files that will be read across regions. And always specify rounding mode when you need to truncate — half-up, half-even, and ceiling all produce different results, and nobody checks which one your library uses by default.
I once had a report generate totals that were off by a few cents because the accounting system used banker's rounding while my export script used half-up. The discrepancy only showed up when we summed over hundreds of rows. Fixing it meant aligning both systems to the same rounding rule, which took about ten minutes once we knew where to look.
Common Formats and When They Break
Different formats serve different purposes, and none of them are universal. Plain integers are safe — almost nothing goes wrong there. Decimals introduce the locale question. Scientific notation is compact but loses readability for non-technical consumers. Currency formats embed assumptions about symbols and decimal places. Date-time values stored as numbers (like Unix timestamps) are efficient but opaque without documentation.
One thing most guides don't mention: JSON doesn't have a native date type, so numbers representing dates are especially fragile. I've seen ISO strings, epoch milliseconds, and custom formatted integers all used interchangeably in the same project. If you're building something that outputs numbers for other systems to consume, document the format explicitly. A comment in the schema or an accompanying spec file is cheaper than debugging a mismatched timestamp at 2 AM.
A Note on What This Doesn't Solve
Reading and writing numbers well requires decisions about data types, formatting rules, and locale handling. There's no universal solution that works across every context. If you're dealing with extremely large datasets, batch processing with explicit format contracts is more reliable than trying to infer structure on the fly. For ad-hoc data exploration, a flexible parser with clear error reporting will save you more time than a rigid one. The tradeoff is always between convenience and correctness, and you pick which one based on what breaks when you're wrong.
Gallery Reading And Writing Numbers
Numbers Worksheet | Reading and Writing 0-100
Reading And Writing Numbers Assessment at Dorothy Bufkin blog
Reading, Writing, and Counting Numbers Worksheets - Preschool Educational Resources
Reading and Writing Numbers | PDF
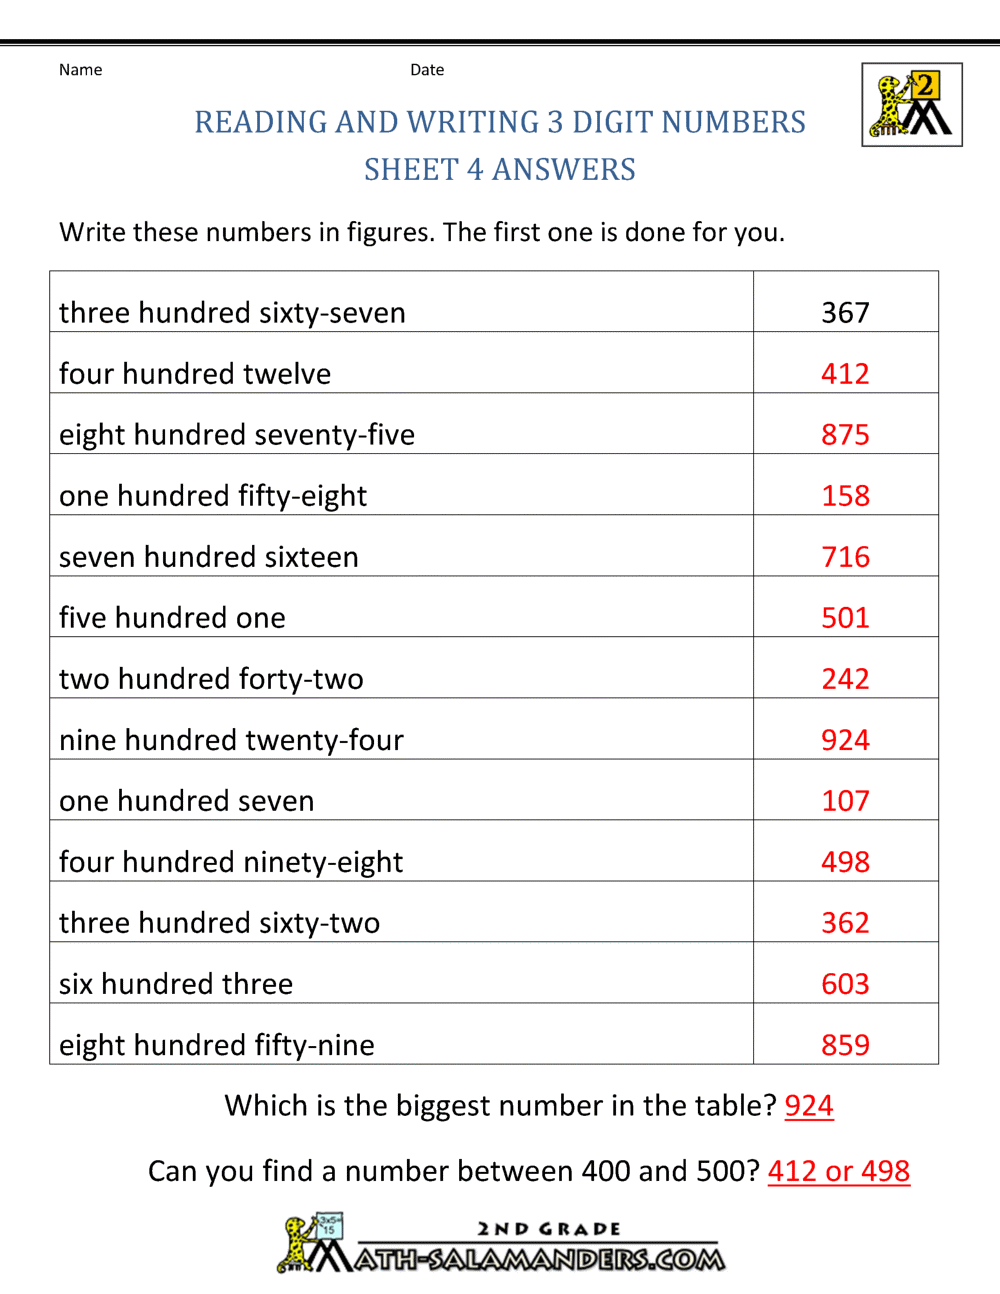
Free Place Value Worksheets - Reading and Writing 3 digit numbers