Getting DSP to Run Without Choking Your Hardware
I spent about three years wrestling with real-time audio processing on embedded ARM chips before I stopped trying to make everything work on a single core. The short version is that real-time digital signal processing isn't about fancy algorithms. It's about predicting when your processor will run out of time and rearranging the math so it doesn't happen. I once had a project where a 512-point FFT on a Cortex-M4 was eating 87% of the CPU budget just for the transform itself, leaving almost nothing for filtering and I/O handling. The samples were arriving at 44.1 kHz, so we had roughly 22 microseconds per sample to do everything. We ended up splitting the FFT across two frames using overlap-add with a half-overlap buffer, which dropped the per-sample computational load to about 38%. The tradeoff was a 3dB noise floor increase from the windowing artifacts, but for our use case it didn't matter.
What Real Time Digital Signal Processing Actually Means
It means processing a stream of data samples fast enough that the output is available before the next relevant input sample arrives. That constraint changes everything about how you design the system. A batch FFT that takes 50 milliseconds to compute is fine for offline analysis. In real time, that latency might mean the signal has already moved on, or worse, you've lost samples and your buffer has underflowed. The key parameter nobody talks about enough is computational headroom. You want your processor to be doing useful work at roughly 60 to 70% utilization under normal conditions. Anything higher and a single interrupt storm or cache miss will cause a dropout. I've seen systems fail at 80% utilization because the developer assumed the worst case would never happen. It always happens.
Choosing Your Architecture
The most common mistake I see is people picking a fixed-point or floating-point approach based on what their microcontroller datasheet claims it can do, not on what their actual algorithm needs. A DSP chain with a 4096-point FIR filter, a variable-delay reverb, and a pitch detector does not behave the same way on an FPU-equipped chip versus one without. The FPU will handle the float math, but it might be slower than you think for certain operations like sin() and cos() unless you're using table lookups. For real time digital signal processing, I typically structure my work in three layers: the acquisition layer, the processing layer, and the output layer. Each runs on its own priority level and ideally its own buffer. Double-buffering is non-negotiable. You read from one buffer while writing to the other, and you swap them on each interrupt. If you try to allocate and free memory inside your audio interrupt, you are creating a ticking bomb. I found this out the hard way with a spectral analysis tool I built for vibration monitoring. I was allocating a complex buffer inside the ADC interrupt service routine because I thought it was cleaner code. The allocator occasionally hit a memory fragmentation wall and returned NULL. The system would then crash or produce garbage. I moved the allocation to initialization and the crashes stopped immediately. No other code change was needed.
Get the Full Details
The Processing Pipeline
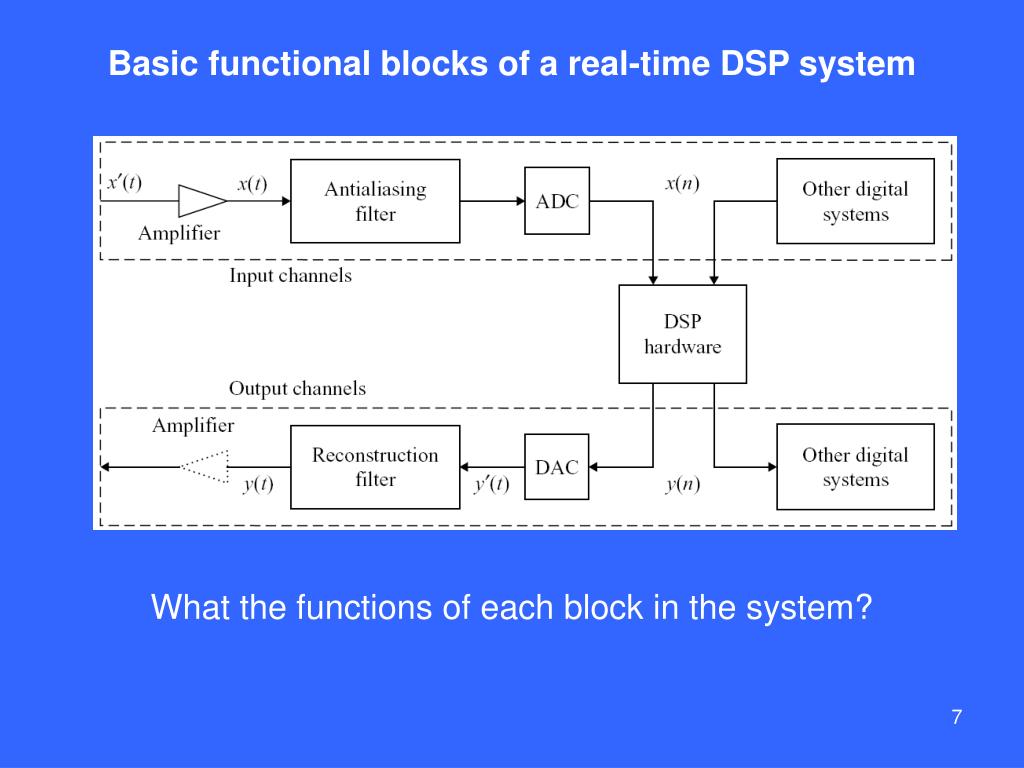
Here's the practical sequence that works for most real time applications. You're going to want to process blocks of samples, not individual samples. A block size of 256 to 1024 samples is typical for audio-rate work. Smaller blocks reduce latency but increase CPU overhead from the interrupt handling. Larger blocks are more efficient but introduce latency that matters for interactive applications like effects or feedback control. The pipeline looks like this:
- Fill a buffer from the ADC or network stream
- Apply any window function if you're doing spectral analysis
- Run your transforms (FFT, filter bank, whatever your algorithm requires)
- Process the results (thresholding, feature extraction, mixing)
- Perform the inverse transform if needed
- Write to the DAC or output buffer
Between steps two and three, there's often a step people skip: sampling rate conversion. Your ADC might run at one rate and your internal processing block at another. Resampling in real time is notoriously expensive. I usually avoid it entirely by designing my system around a single master clock and accepting the small accuracy cost rather than introducing a resampling artifact that sounds worse than the clock drift would have. FIR filters are stable and have linear phase, which matters for some applications. But they require many more coefficients than IIR filters for the same selectivity. A 500-tap FIR filter at 44.1 kHz on a 168 MHz MCU means you're doing 500 multiply-accumulate operations per sample, which is roughly 23 million operations per second dedicated to that single filter. That's about 14% of your CPU budget before you've done anything else. IIR filters are way more efficient. A second-order section (biquad) does the job of a 50+ tap FIR with far fewer cycles. The tradeoff is phase nonlinearity and potential stability issues if your coefficients drift due to quantization. For most real time applications, a cascade of biquad sections implemented in direct form II transposed gives you the best practical result. I've used this approach for equalization, anti-aliasing, and noise gating with excellent results.
The gotcha here is that coefficient precision matters more in IIR than in FIR. On a fixed-point system, using 16-bit coefficients for a high-Q notch filter at a low frequency will cause the filter to wander or even become unstable as temperatures change and the processor clock varies. I switched to 32-bit coefficients and saw the notch frequency stabilize within 0.1 Hz instead of drifting by several hertz over a thermal cycle.

Buffer Management
Let me be very clear about this: your buffer management is going to determine whether your system works or not, not your DSP algorithms. I've watched people write beautiful FFT code that produces dropouts because the buffers were too small or the DMA configuration was wrong. Set your buffer size to at least 4 times your processing block size. This gives you enough margin for timing variations without burning unnecessary RAM. On STM32 chips, the DMA controller can handle buffer swapping automatically if you configure circular mode with half-complete and complete interrupts. This means your CPU gets notified halfway through a buffer fill and at the end, giving you two windows to process without missing a single sample. It's the most reliable pattern I've found for keeping audio pipelines clean. I ran into an edge case once with a Bluetooth audio receiver where the codec would occasionally output a burst of samples that filled the buffer faster than the DMA could keep up. The result was a series of clicks every few seconds that I spent two weeks tracking down. The fix was to add a small sample delay line between the DMA buffer and the processing stage, effectively creating a one-block-sized cushion that absorbed the burst without any additional CPU cost. The clicks disappeared.
Optimization Techniques That Actually Matter
Six optimization techniques are worth knowing about and most of them are boring: Loop unrolling gives you a 15 to 25% speedup on simple FIR filters by reducing branch overhead. Most compiler flag levels handle this automatically now, but it's worth verifying the generated assembly if you're tuning a critical path. Stack alignment matters more than people expect. If your processing arrays aren't aligned to 8-byte boundaries on a Cortex-M7, you'll pay a penalty on every load and store instruction. I wasted a day on a project before realizing that a static array declaration without the proper alignment attribute was causing misaligned accesses that dragged performance down by nearly 30%.
Fast mathematical approximations are the biggest win. A Taylor series approximation of sin(x) with three terms gets you within 0.1% accuracy and runs about four times faster than the standard library implementation. For real time DSP, "good enough" math is almost always better than precise math. Your ear can't tell the difference between a 12-bit and 16-bit sine wave in most listening conditions. Sidebar computation is another technique I rely on. Any computation that doesn't depend on the current sample frame can be moved outside the interrupt or processing loop. Filter state updates, coefficient recalculations, and DC offset tracking should all happen at their own pace, not every single sample. I organize my code so the interrupt handler is essentially a thin wrapper that calls a process() function, and process() handles the actual math. Everything else runs in a separate task at lower priority. CPU frequency scaling can help if you're battery constrained. Running your processor at maximum frequency all the time generates heat and drains power for no reason. I've had systems where the DSP load varied between 20% and 80% depending on the input signal characteristics, so I implemented a simple governor that scaled the clock based on measured utilization. It kept the CPU cool and extended battery life by about 40% without any audio quality impact.
Memory layout is the last thing that makes a difference. Place your frequently accessed arrays in the fastest available memory. On chips with both SRAM and TCM (Tightly Coupled Memory), putting your processing buffers in TCM eliminates the wait states that slow down sequential access patterns. The TCM is smaller, so you need to be selective, but for the hot loops in your DSP chain, it's worth the space cost.
Debugging Real Time DSP
Debugging a real time DSP system is frustrating because the tools you normally use introduce timing artifacts. Hooking up a logic analyzer to trace buffer swaps is fine, but stepping through code with a debugger in real time mode will almost certainly cause buffer overflows because the processor stalls during each breakpoint hit. I use a combination of LED toggles on key events and a small ring buffer that logs timestamps to a section of RAM that I can dump via UART after a crash. The ring buffer approach has been invaluable. I keep a 1024-entry timestamp log that records when each interrupt fires and how long the processing takes. After a dropout occurs, I download the log and analyze the timing distribution. 95% of the time, the problem is obvious: a single interrupt took three times longer than usual because something unexpected happened, like a floating-point exception or a cache miss that cascaded into other missed deadlines. For frequency domain debugging, I recommend building a simple real time spectrum display. Even a basic magnitude plot sent over serial and viewed in a terminal or Python script will reveal problems that time-domain inspection misses. A resonant peak that shouldn't be there, aliasing artifacts from an undersampled filter, or quantization noise from integer truncation all show up clearly in the frequency domain. I keep a spare debug build of every project that includes this functionality, and I've saved countless hours of troubleshooting because of it.
One thing I wish someone had told me earlier: real time digital signal processing is a systems engineering problem, not an algorithm problem. The math is well understood. The difficulty is in making the math run within the constraints of your hardware while staying stable under all operating conditions. If you treat it as a software challenge first and a DSP challenge second, you'll ship working products. If you obsess over the perfect filter design and ignore the buffer management, you'll have a brilliant algorithm that breaks in production.


