Getting Started with Recon-ng Without Losing Your Mind
Recon-ng is one of those tools that looks intimidating on the surface because it borrows so heavily from the Metasploit framework syntax. If you already know how to use msfconsole, you are halfway there. The command structure is nearly identical: use, search, info, run. The difference is that recon-ng is scoped entirely to open-source intelligence gathering rather than exploitation. One thing people get wrong right away is thinking they need to install the whole thing from scratch every time they spin up a new machine. It isn't that complicated. Clone the repo from GitHub into your tools directory, cd into it, and run pip3 install -r requirements.txt. That handles most of the dependencies. The one dependency that trips people up is the lxml package. On Ubuntu-based systems, installing libxml2-dev and libxslt1-dev first and then rerunning the pip install fixes it. I wasted about forty minutes on a fresh Kali box once because I skipped the system packages and just ran the pip command.
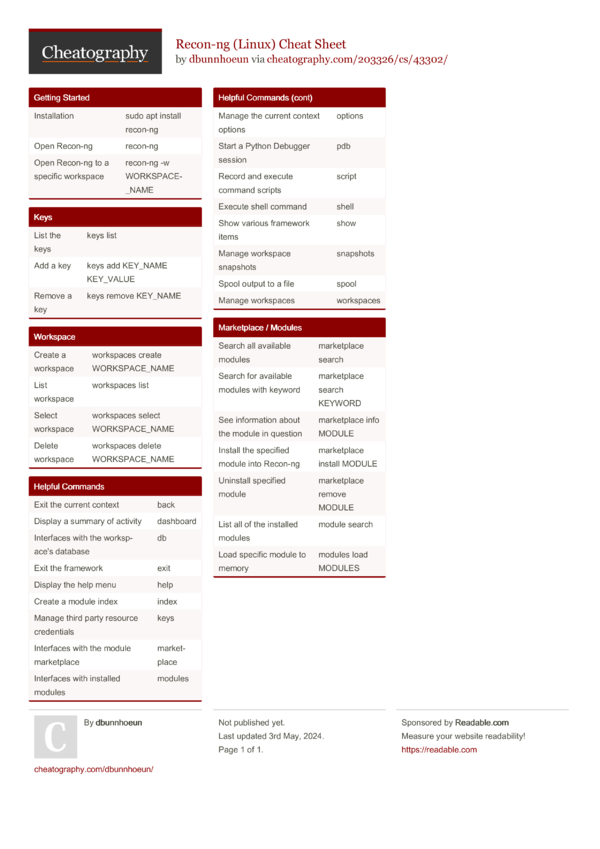
Recon Ng Cheat Sheet for Working Sessions
Here is what actually matters when you are sitting in the recon-ng shell and trying to move through a target without stopping to look up commands. Workspaces are everything. Every recon-ng session is organized around workspaces. You create one with workspace new target_name, and every module you run, every data you pull, every module configuration stays isolated inside that workspace. Switch between them with workspace list and workspace switch name. If you skip this step and just run modules blindly, your data gets mixed together and you end up chasing contacts and credentials from a completely different target three hours later. Key module categories you will use constantly:
Modules under the recon/domain/module/ directory handle DNS enumeration, subdomain discovery, and WHOIS lookups. The recon/contact/module/ directory pulls social media and professional network data. recon/hosts/module/ covers IP analysis and netblock lookups. recon/scripts/module/ contains Python scripts you can drop in and run directly. Working with API keys is where most people stall. recon-ng does not come preloaded with working API keys for anything useful. You need to register for services like Google Custom Search, Shodan, Twitter, and others, then add them inside recon-ng using the keys add command. Without API keys, half the modules return empty results or hit rate limits immediately. I usually set up a dedicated Google Cloud project for Custom Search API access because it gives you a generous quota and is stable. The default free tier on Google's standard API is too low for serious recon work. The database is automatic but easy to lose track of. recon-ng uses SQLite by default. All results, harvested contacts, discovered hosts, and notes live in the workspace's database file. You can query it directly with db contacts, db hosts, db accounts, and similar commands. These are faster than re-running modules. If you lose the workspace directory, the data is gone. I keep a backup script that copies the workspace folder after every session because recon-ng does not do incremental backups for you.
Get the Full Details

What the Tool Actually Does Well and Where It Fails
Recon-ng excels at automated enumeration across many data sources in a single pass. A single module run can hit Google, Bing, Shodan, and WHOIS simultaneously depending on which API keys you have configured. That parallelism is what makes it faster than chaining individual bash scripts together. A typical full-scope domain recon with good API coverage runs in about ten to fifteen minutes for a medium-sized target. Without API keys, the same scope takes considerably longer and returns fragmented results. The tool's biggest weakness is that it is entirely dependent on the availability and API changes of third-party services. When Twitter changed its API access policy around 2023, a large number of recon-ng's social media modules broke overnight. They did not recover fully. Several Google modules also started returning throttled or empty results during periods of high API cost concerns. You need to check the GitHub issues page periodically to see if your active modules are still functional. There is no built-in health check. Another limitation that is not obvious at first: recon-ng does not handle rate limiting gracefully on its own. If you blast a module across too many targets too quickly, you will get IP-banned from the underlying data source. I learned this the hard way when I ran a broad subdomain enumeration module against forty domains in sequence and hit a Cloudflare block on Shodan. The workaround was simple but easy to miss — use the set DELAY 2 command between module runs. It adds a two-second pause that keeps most services from flagging your traffic. For aggressive recon, I usually set it to DELAY 1 or 2 depending on how many API keys I have spread across different providers.
Practical Workflow That Actually Saves Time
Start with a workspace. Add your API keys before running anything. Pick a single module to start with, usually recon/domains-hosts/enumeration_checks, and run it against your target domain. Export the results with export csv or export json to a known location. Then branch out into subdomain enumeration with recon/domains-hosts/subdomain_enumeration. After that, move to host discovery and port scanning through recon/hosts-hosts/fqdn_lookup and any port scan modules available in your version. One trick that is not documented well: you can chain module output into another module's input using the input option. If module A discovers subdomains and outputs them to the hosts table, module B that reads from the hosts table can pick them up automatically. This means you do not need to manually copy-paste results between modules. Check each module's info output for what input tables it expects. That alone cuts my recon time roughly in half compared to the first pass I ever did, which took me about two hours for a scope that now takes twenty minutes. Exporting and importing data between workspaces is also useful. If you are running recon on multiple targets that share infrastructure, you can export hosts from one workspace and import them into another using the import command. This catches overlapping subdomains and shared IP ranges that you would otherwise miss.
Realistic Edge Case That Broke My Workflow
I was doing recon on a target that used a lot of third-party CDNs and cloud services. The subdomain enumeration module returned thousands of results, but nearly all of them were CDN hostnames like cdn.example.com or static.provider.net. Most of those IPs resolved to Cloudflare or Akamai ranges, which meant zero useful attack surface. I spent about twenty minutes looking at useless results before realizing the problem. The fix was running a netblock filtering step after enumeration. The module recon/hosts-hosts/netblock_whois can help identify which ranges belong to hosting providers. I then manually filtered the hosts table to remove known CDN and cloud provider ranges. It is not an automated step built into recon-ng, so you have to do it yourself or write a small filter script. If your target is heavily cloud-deployed, skip this step and you are looking at a lot of noise. For targets with heavy CDN usage, I also found that combining recon-ng with passive tools like sublist3r or one-for-all before running the active recon-ng modules gives cleaner results. recon-ng is not designed to be a pure passive recon tool, so starting with passive enumeration and then feeding those results into recon-ng's workspace saves a lot of module runtime and API quota.

Alternatives Worth Knowing About
If recon-ng feels too heavy or the module ecosystem is not covering your target, recon-ng-ng is a community fork that has added some improvements and keeps certain modules updated after the original project slowed down. For pure subdomain enumeration, amass is more thorough even if it lacks the workflow structure of recon-ng. For automated all-in-one recon pipelines, the reconftw script does a lot of what recon-ng does manually but ties it together with better defaults and multiple tool integration. Recon-ng remains useful when you need a structured, database-backed workflow with module-level control. It is not the fastest tool for every single recon task, but the workspace system and import/export functionality make it practical for repeated use on the same target over time. The learning curve is about two to three hours to get comfortable, after which a standard domain recon takes roughly fifteen minutes with good API coverage.