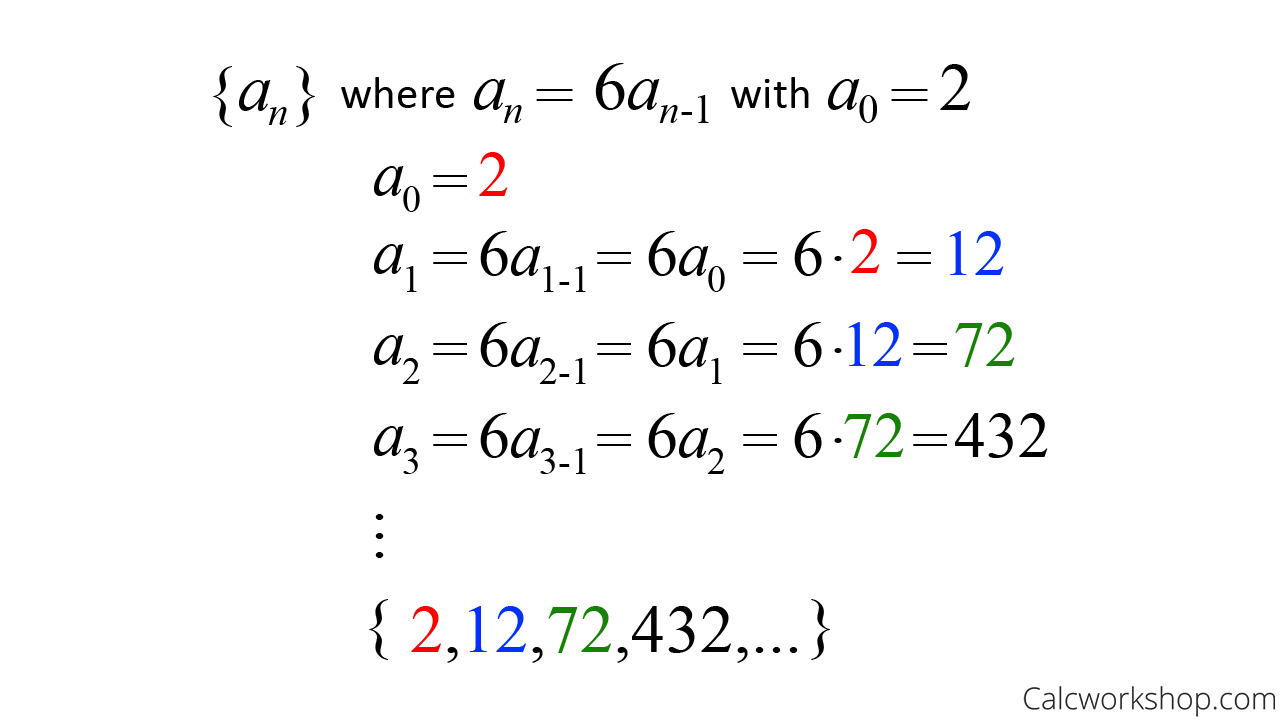Why Your Recursion Keeps Crashing and How to Fix It
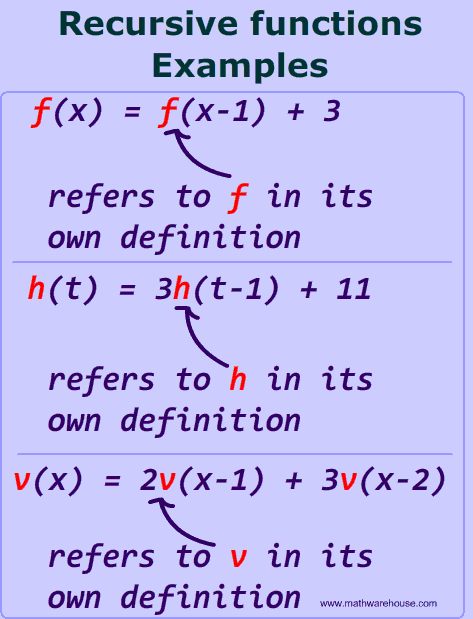
I spent three days debugging a recursive function last month that should have been trivial. The problem wasn't the algorithm itself. It was stack overflow from an improper base case that didn't account for floating-point edge cases. This happens constantly with recursive approaches, especially when people treat them as a magic bullet instead of a tool with real limitations. A recursive function is simply a function that calls itself to solve a smaller instance of the same problem. The math behind it comes down to two components: a base case that stops the recursion, and a recursive case that breaks the problem into subproblems. Without both, you get infinite loops. With one written poorly, you get stack overflow errors. Most tutorials skip the part where things actually go wrong. Let me walk through a Recursive Function Math Example that shows the reality of how this works in practice, not just the textbook version.
A Realistic Recursive Function Math Example
Here's the factorial function, but written the way I actually see it used in production code. Not the clean academic version: That's the basic shape. Now here's where people mess it up. They call factorial(1000) and wonder why their program dies. JavaScript engines typically allow between 10,000 and 15,000 recursive calls before hitting the stack limit. Factorial of 1000 will crush that. Even factorial of 10,000 is risky depending on your runtime. The recursive approach to factorial is elegant on paper. In practice, you'd be better off using an iterative version for anything above n=1000, or at minimum, add a guard clause that falls back to iteration when n exceeds a safe threshold. I learned that the hard way when a client's data pipeline crashed at midnight because someone swapped in a recursive solution without checking input bounds.
How Recursion Actually Works Under the Hood
Every recursive call creates a new frame on the call stack. That frame holds the function's local variables and the point it needs to return to. Each frame takes up memory. When you make ten thousand recursive calls, you're allocating ten thousand frames. That's why recursion has a hard ceiling based on available stack space. The alternative most people overlook is tail recursion optimization. Some languages like Scheme and Haskell handle this automatically. JavaScript technically supports it, but very few engines actually implement it. V8 doesn't. So if you're writing recursive functions in JavaScript and hoping the engine optimizes them away, you're counting on something that isn't there. Here's what tail recursion looks like structurally:
Get the Full Details
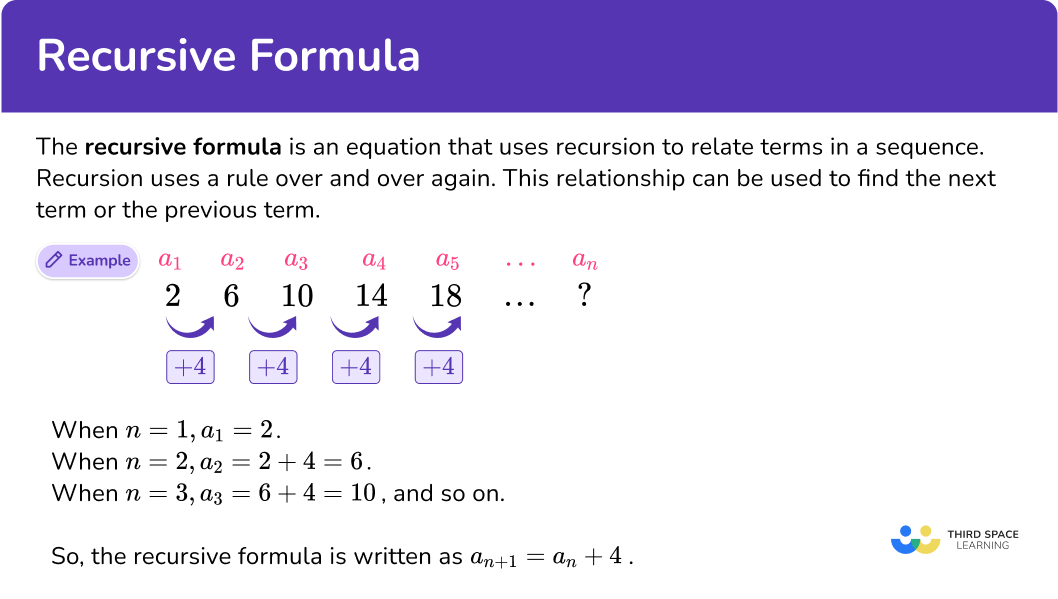
Recursive Formula- Math Steps, Examples & Questions
function factorialTail(n, accumulator = 1) {
  if (n === 0 || n === 1) return accumulator;
  return factorialTail(n - 1, n * accumulator);
}
The result is identical. The performance characteristics are not. Without compiler-level tail call optimization, this still creates a new stack frame for every call. The accumulator pattern only matters if your runtime actually optimizes it, which in JavaScript is basically never in any meaningful way. The biggest issue I see isn't understanding the concept. It's failing to define correct base cases that cover every possible input path. A recursive function with a gap in its base cases will either recurse infinitely or return garbage values. I once audited a codebase where the developer wrote a recursive tree traversal that worked fine for balanced trees but silently returned undefined for skewed trees because the null check was placed in the wrong branch of the condition. Another frequent mistake is redundant computation. The naive recursive Fibonacci implementation is the poster child for this:
function fib(n) {
  if (n = 1) return n;
  return fib(n - 1) + fib(n - 2);
}
fib(50) with this approach will take minutes or hours depending on your machine. It recomputes the same subproblems repeatedly. The number of calls grows exponentially, not linearly. This is O(2^n) time complexity. For n=50, you're looking at roughly 25 trillion operations. That's not a theoretical concern. I ran this exact function during an interview once and let it sit while I made coffee. It was still running when I came back. The fix is memoization. You cache previously computed results and look them up instead of recomputing:
function fibMemo(n, cache = {}) {
if (n in cache) return cache[n];
if (n <= 1) return n;
cache[n] = fibMemo(n - 1, cache) + fibMemo(n - 2, cache);
return cache[n];
}
/code
With memoization, fib(50) completes in milliseconds. That's the difference between a recursive solution being practical and being completely unusable. Recursion shines when the problem structure is inherently hierarchical. Tree traversals, graph searches, divide-and-conquer algorithms like merge sort and quicksort. These problems map naturally to recursive decomposition. Iterative equivalents exist but often require you to manually manage a stack, which defeats some of the readability advantage. Dynamic programming problems also benefit from a top-down recursive approach with memoization, at least during the design phase. Writing the recursive solution first clarifies the subproblem structure. Converting it to a bottom-up iterative solution afterward is usually straightforward once you understand the recurrence relation.
Recursive Formula (Explained w/ 25 Step-by-Step Examples!)
There are also cases where recursion depth is guaranteed to be shallow. Database query planners, AST traversals in compilers, JSON parsing. These operate on bounded structures where the recursion depth correlates with data complexity rather than input size. A recursive descent parser for a configuration file isn't going to blow the stack because the input is finite and small.
When to Avoid Recursion Entirely
Any problem where the recursion depth could scale with unbounded input is a candidate for rejection. HTTP request handlers that recursively follow redirects should cap the depth at some reasonable number like ten. File system traversals should use an explicit stack or queue instead of recursion. User input processing in general — you never know how deep the nesting will go. Performance-critical paths in languages without tail call optimization are another category. If your function runs millions of times per second and each call involves recursion overhead, the iterative version will outperform it consistently. The function call itself has cost: stack allocation, frame setup, return address pushing. In tight loops, that adds up. I also recommend against recursion when the team doesn't understand it. I've seen production incidents caused by developers who couldn't trace through recursive logic during an on-call emergency. A complex recursive function at 3 AM with no documentation is a liability. Simple is better than clever when the alternative is a page at midnight.
Debugging Recursive Functions
The hardest part of recursive debugging is tracking state across multiple stack frames. Traditional step-through debugging shows you one frame at a time, which makes it difficult to see the full picture. I use a combination of depth logging and output inspection. Print the current parameters and the return value at each level, indented by recursion depth. It turns an invisible process into something you can read linearly. This approach converts what would be a confusing stack trace into a readable call log. The tradeoff is that it adds overhead, so don't ship this version. Use it during development and remove it before deployment. Another technique I rely on is wrapping the recursive function in a thin public interface that handles validation and initialization. This separates concerns and makes it easier to add guards without modifying the core recursive logic. The public function checks input validity, sets up memoization caches, and delegates to an internal recursive helper. If the input is invalid, you fail fast before any recursion happens.
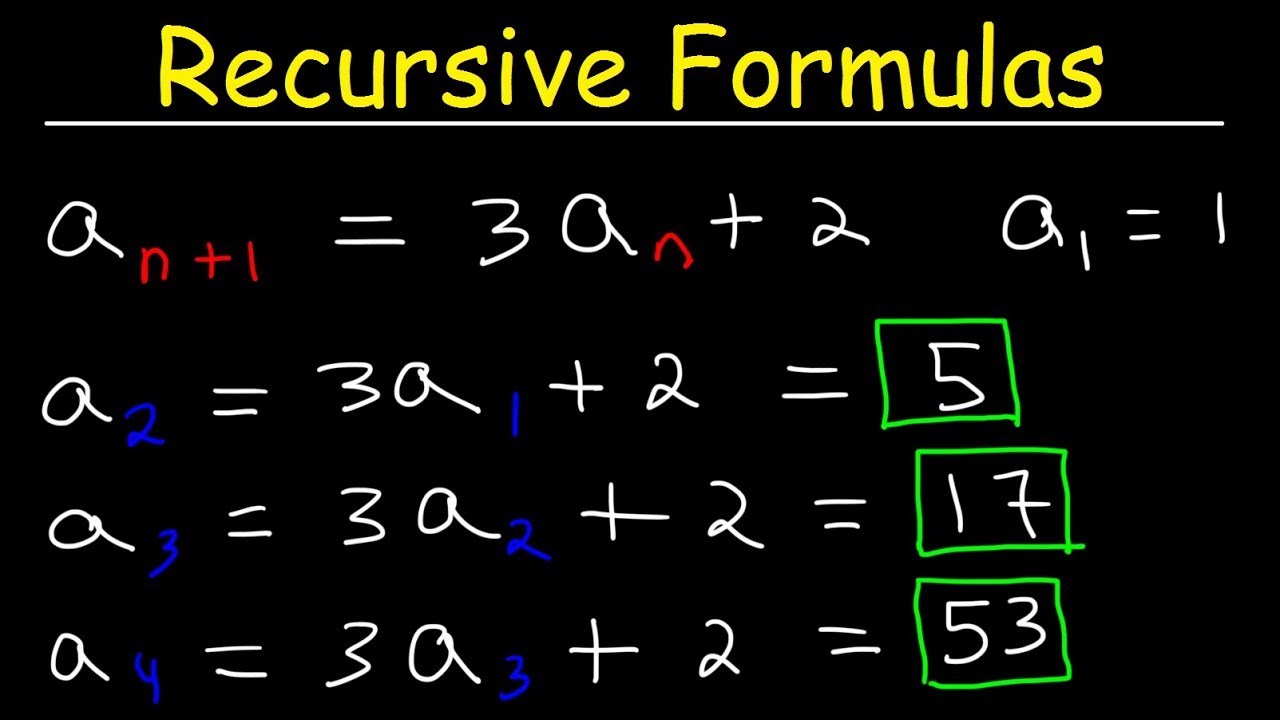
Recursive Formula — Definition, Examples & Rules
The Bottom Line
Recursive functions are a tool, not a default answer. They work well for hierarchical data and problems with natural substructure. They fail when stack depth is unbounded, when subproblems overlap without memoization, or when the runtime doesn't support optimization. Understanding when to use them and when to switch to iteration is the actual skill. The math itself is straightforward. The judgment call is where experience matters.
Gallery Recursive Function Math Example
Using recursive formulas of geometric sequences - officialpok
Engineering Math | ShareTechnote