Getting Past Red Black Tree Practice Problems
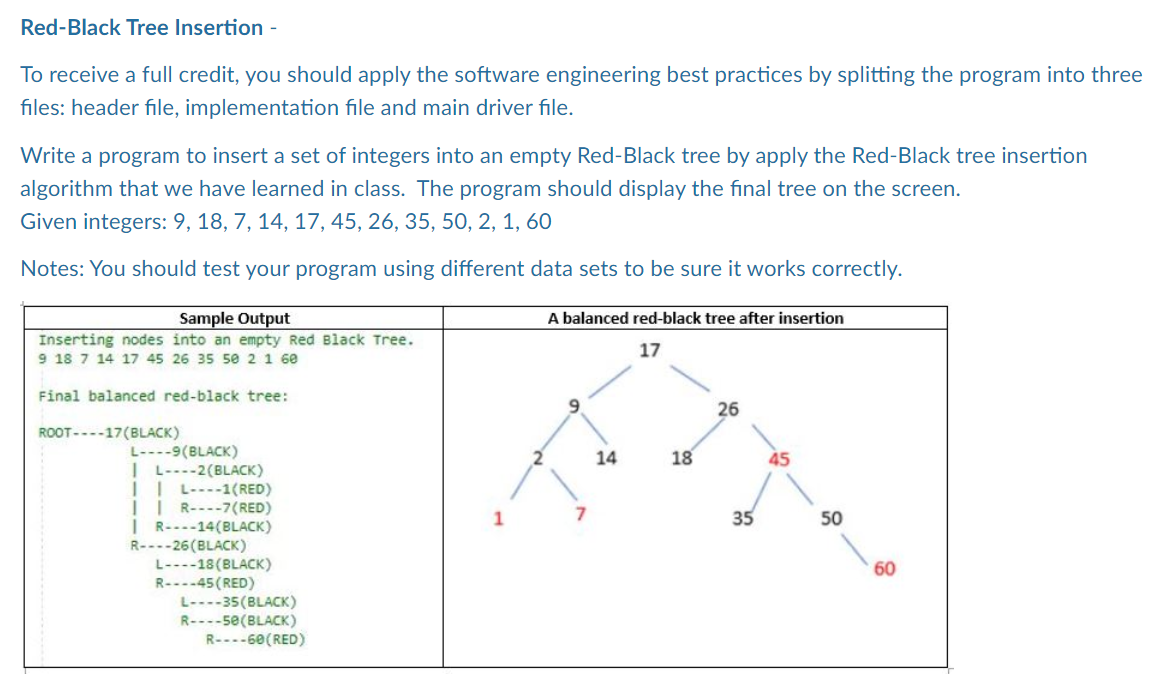
Red Black Tree Practice Problems hit most students somewhere between their second and third coding interview prep cycle. You understand the basic rules — every leaf is black, red nodes can't touch red nodes, every path from root to null has the same black height. The theory sounds clean on paper. Implementing it without bugs is another story entirely. I spent three weeks last year debugging a BST insertion that seemed correct at every step. It wasn't until I wrote a randomized test harness that fed 50,000 sequences of integers and compared the tree's properties after each insertion against a reference implementation that I found it. The bug was in the rotation sequence during a double-red rebalancing case where the uncle was black and the inserted node was a right child of a right child. The code handled three out of four case patterns correctly. One pattern had a swapped rotate direction. My mistake.
Red Black Tree Practice Problems
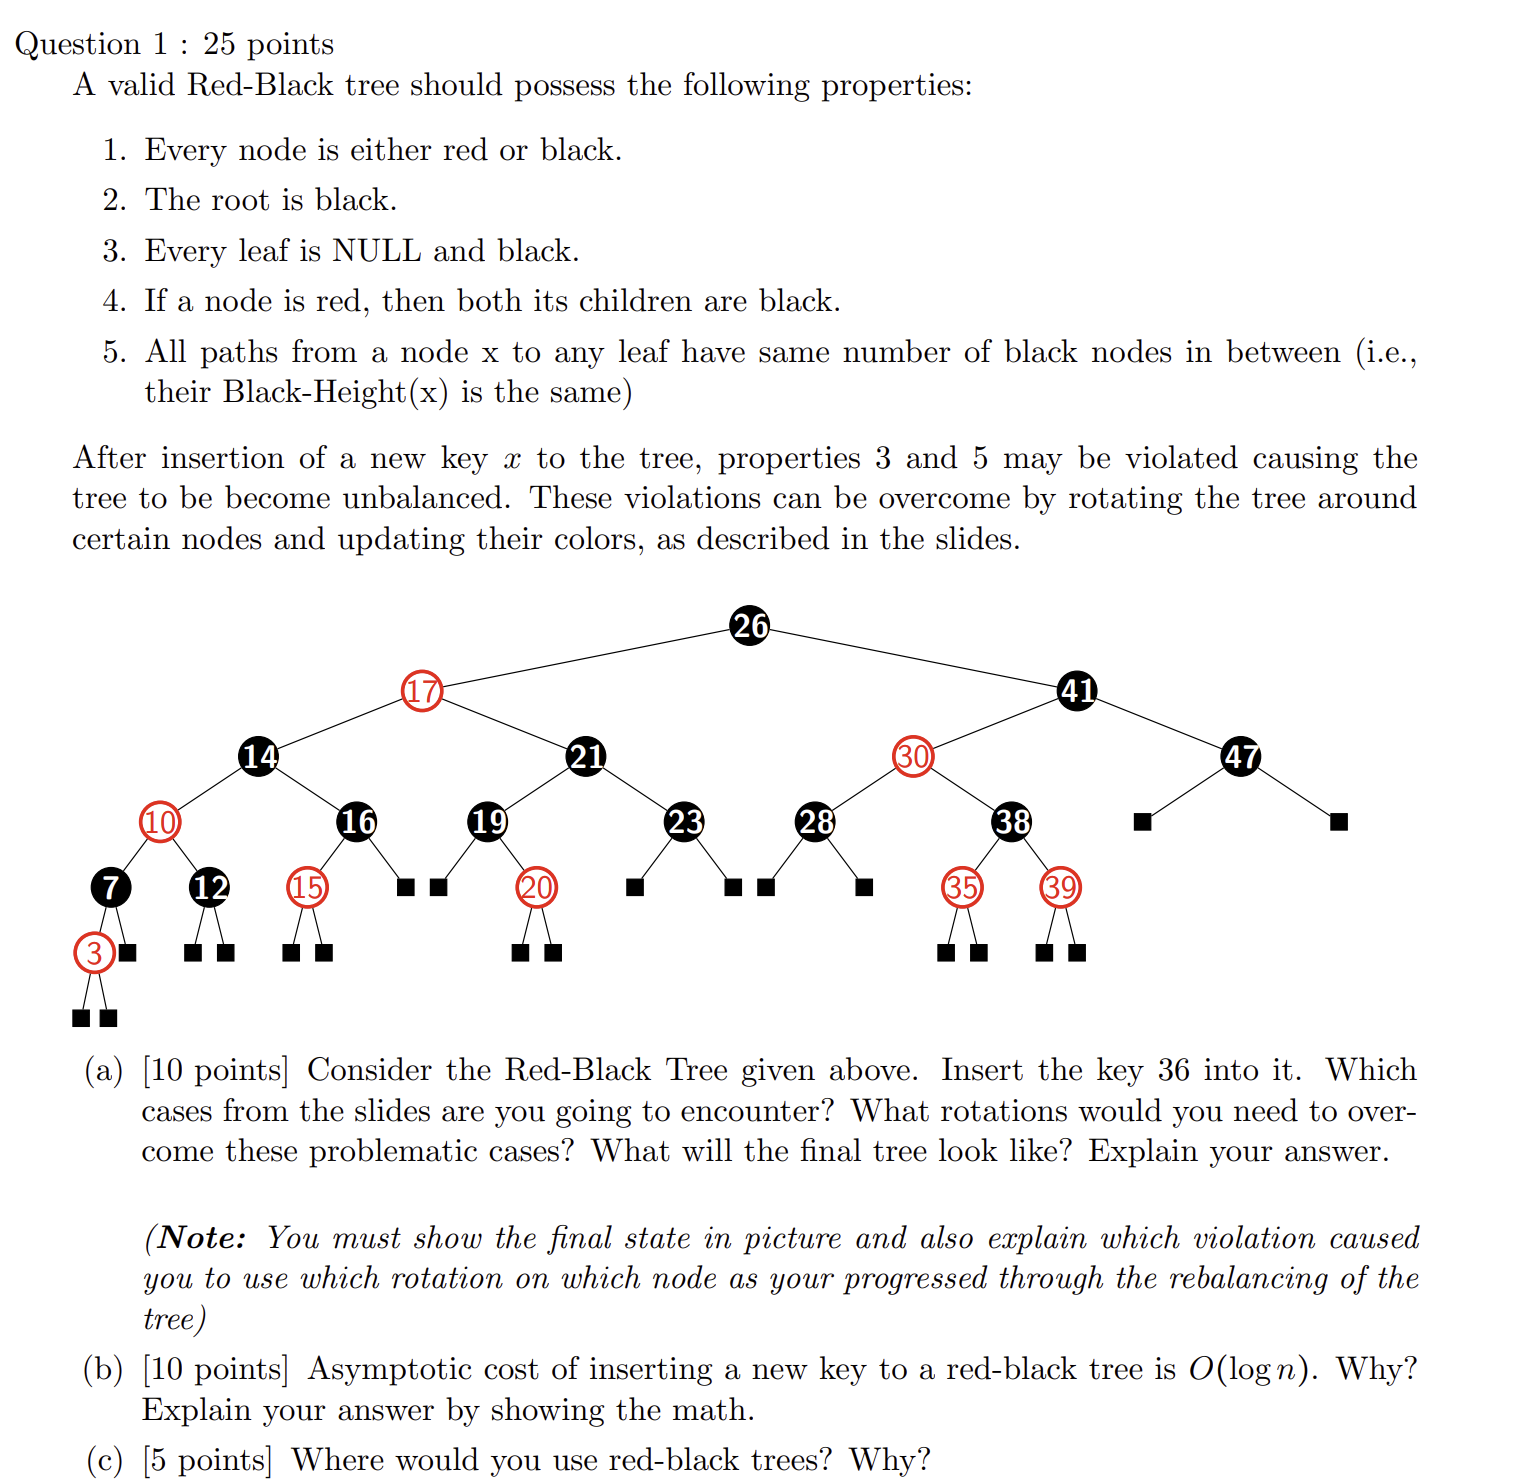
Start by implementing only insertion, not deletion. Insertion alone touches maybe six rotation cases when you factor in all the tree color patterns. Deletion adds another dozen. Many resources rush you into deletion too quickly. Get insertion solid first. Write a test validator that checks all five Red-Black properties after every single operation and run it with thousands of random insertions before you ever attempt delete. Here are the actual insertion cases you need to handle, in order of complexity: The simplest case is inserting a red node into an empty tree. Just color it black and you're done. Next is inserting as a child of a black parent with a black uncle — no rotation needed, just flip colors. The rotation cases begin when your uncle is red. In that scenario you don't rotate at all. You recolor parent and uncle to black, recolor grandparent to red, and recurse up. That's it for one entire branch of the decision tree, yet most beginners skip this and immediately jump into rotations.
The rotation cases split into four sub-cases based on whether your parent is a left or right child and whether the new node is a left or right child of that parent. LL, LR, RR, RL. But the names are misleading because the logic isn't always a single rotation. LR and RL are double rotations. LL and RR are single rotations. Write out the color assignments for each one before touching code. For deletion, the hardest case is removing a black node whose replacement is also black, or removing a red node whose parent is red. The double-black state is the conceptual trap. You don't actually create a "double-black" node in most clean implementations. Instead you treat the situation as excess black propagation and work your way up. When a node carries excess black, either redistribute from a sibling, recolor, or rotate until the excess resolves. If you implement the explicit double-black struct, you'll write twice as much conditional logic for the same outcome. I found that maintaining a separate parent pointer in each node cuts my debug time roughly in half during rotation operations. Without parent pointers, every rotation requires traversing from the root to re-link, which introduces off-by-one errors in pointer assignment that are brutal to trace. With parent pointers, each rotation is maybe eight lines instead of eighteen. The trade-off is an extra pointer field and slightly more complex insertion logic to keep parent references consistent, but that cost pays for itself immediately once rotations start failing in production tests.
Get the Full Details
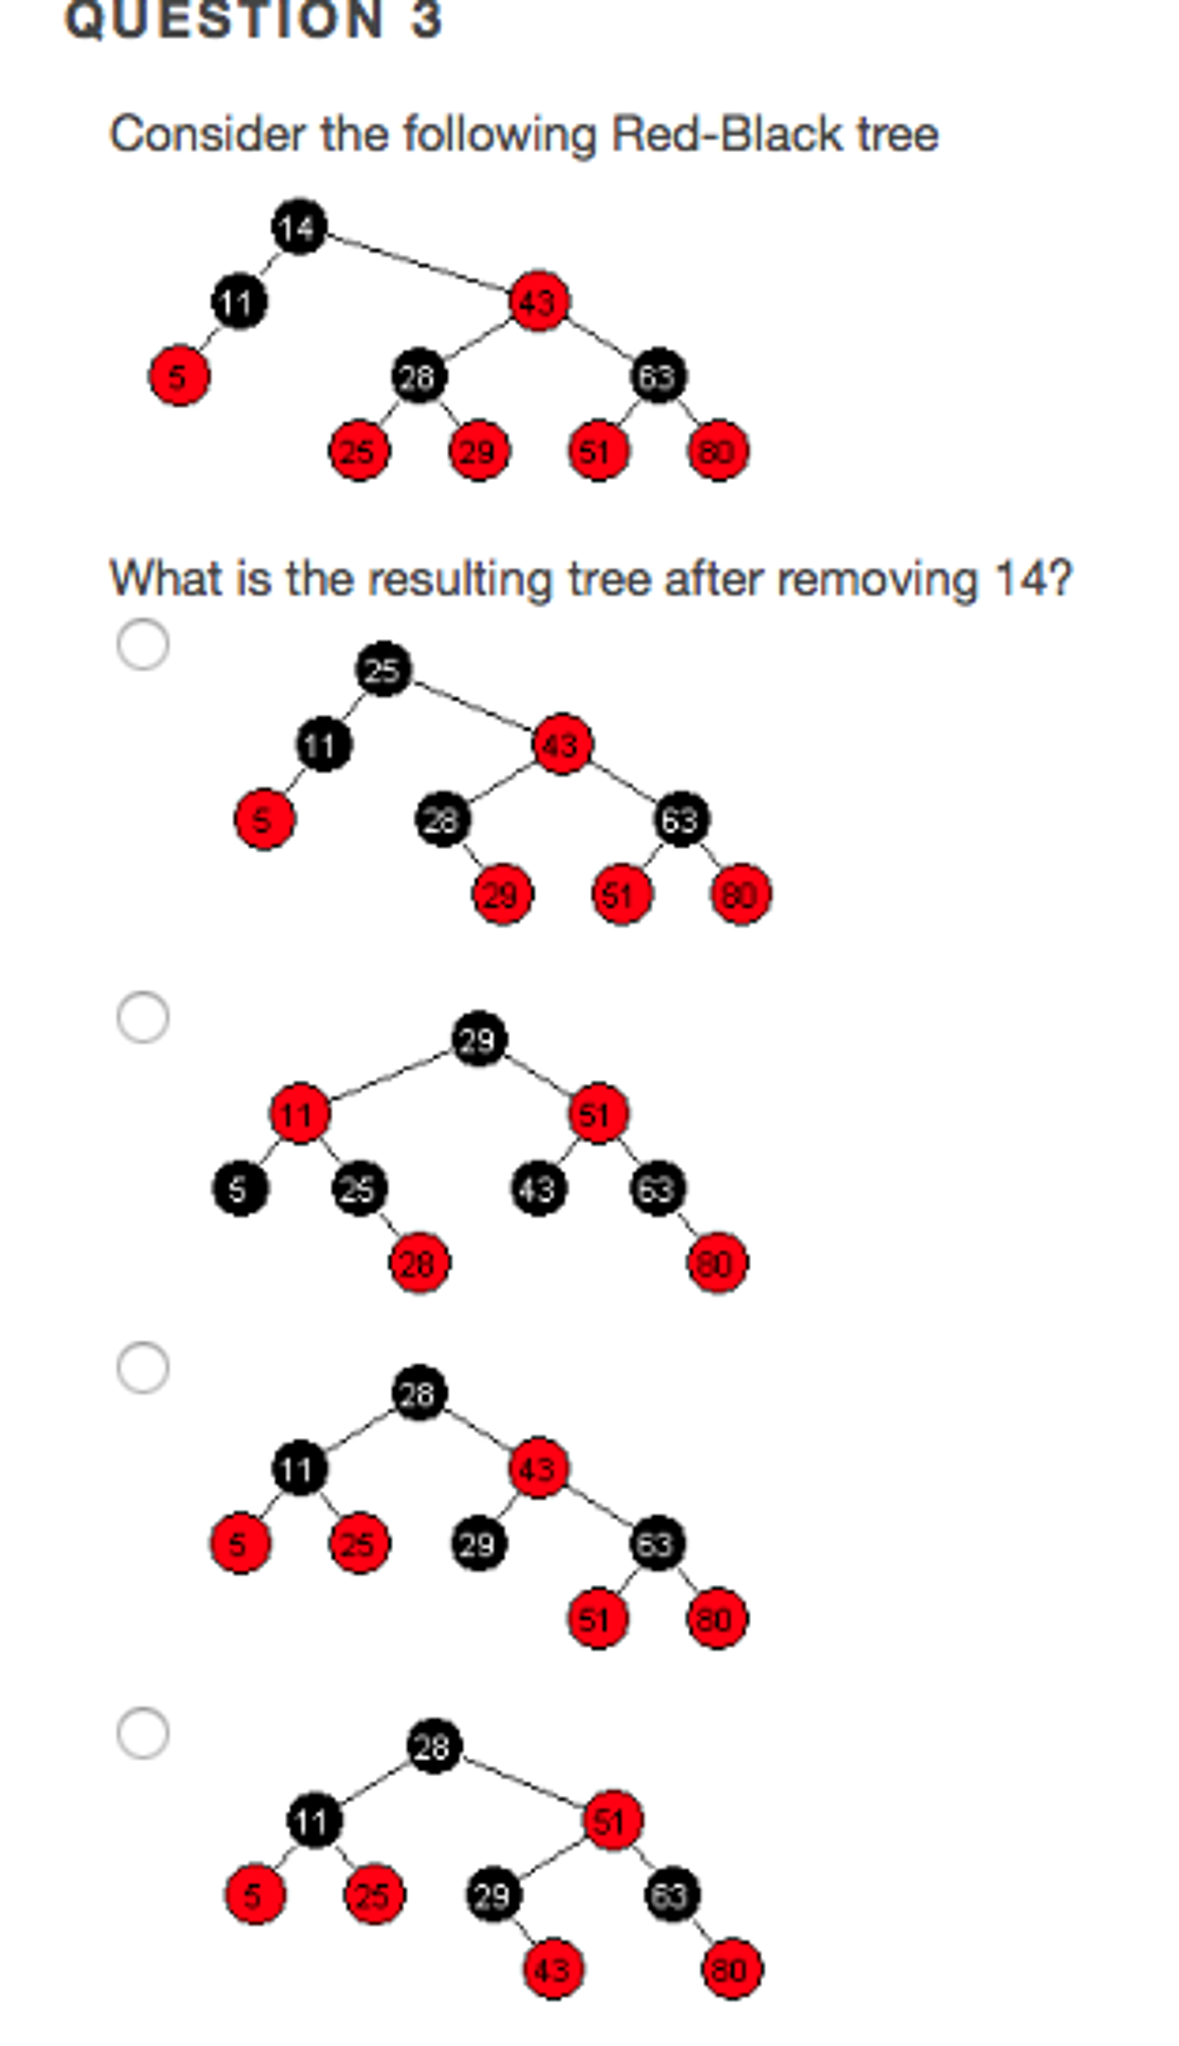
Another detail people miss: the root must always be black after every operation, including after recursive recoloring from deletion. If your deletion propagates black excess all the way to the root, you simply remove the excess black rather than recoloring the root red, because the root can't be red. Getting this wrong produces trees that violate property two and take forever to catch in validation. If you want practice data, write a script that generates insertion and deletion sequences, feeds them into both your implementation and a known-correct reference (there are several open-source C++ implementations of Red-Black Trees on GitHub you can use as a verifier), and diff the resulting tree structures node by node. This catches structural bugs that property-check-only validators miss, like incorrect child pointers that still maintain valid coloring. The main limitation of Red Black Trees that you should know about: they're overkill for most everyday use cases in production systems. For a dictionary or symbol table in a language runtime, a simple AVL tree or even a skip list will give you comparable performance with simpler code. Red Black Trees shine when you need guaranteed logarithmic performance with frequent insertions and deletions mixed together and can't afford the higher rotation count of AVL trees. They also don't cache well in modern CPUs due to their pointer-chasing nature. If you're building something that processes sequential data, consider whether a B-tree variant or sorted array with binary insertion might serve you better.
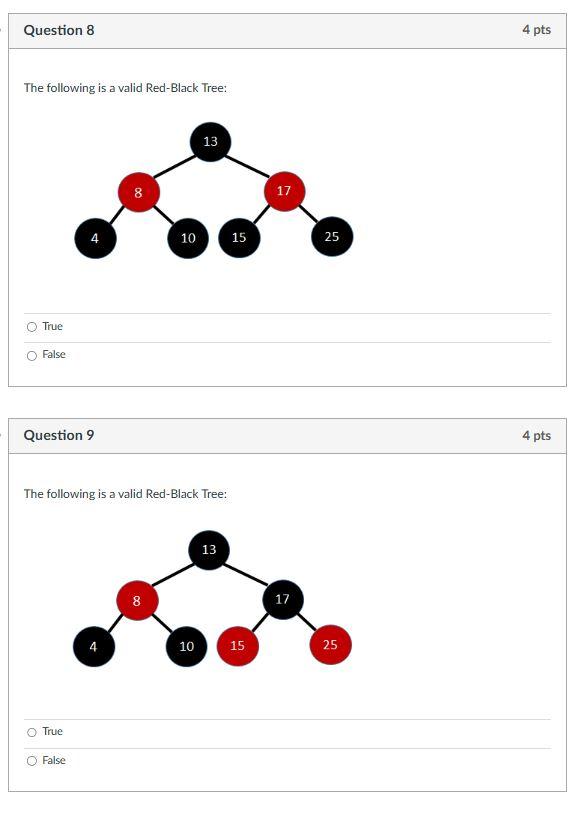
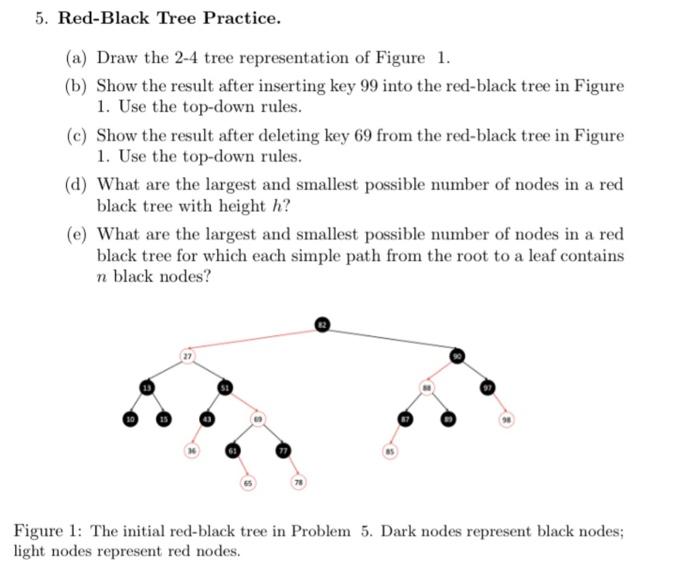
For interview prep specifically, the most commonly tested operations are insertion and deletion. Know deletion inside out. Practice writing it on a whiteboard without a reference. The color-flipping and rotation logic for deletion is what separates students who've memorized from those who actually understand the structure. Start by implementing deletion only for the case where the removed node has zero or one child. Add the two-child case last. That two-child case requires finding an in-order successor, swapping values, and deleting the successor, which introduces its own rebalancing subtleties. One more thing. There's a common exam question variant where you're given a tree and asked to determine if it's a valid Red Black Tree, then perform an insertion or deletion and redraw the tree with rotations. The trick here isn't the theory, it's drawing cleanly. Number your nodes, label their colors explicitly, and show each rotation as a separate diagram with arrows. Examiners lose points for ambiguous drawings more often than for wrong rebalancing steps. A clean, numbered diagram with the rotation sequence labeled step by step is worth more than a correct answer written in cramped scribbles. If you're looking for practice problems, LeetCode 114 and 124 (validate BST variants), LeetCode 938 for range queries, and the general BST problem sets from Cracking the Coding Interview cover most interview expectations. For deeper work, implement a complete RB-tree with iterator support and write unit tests for every rotation case. The full implementation is roughly 150 to 200 lines of code in C or Go, maybe 100 in Python if you're willing to use object overhead liberally. That's a reasonable project to build and it covers everything an interviewer would ask about.