How I Actually Shrink PDFs Without Ruining Them
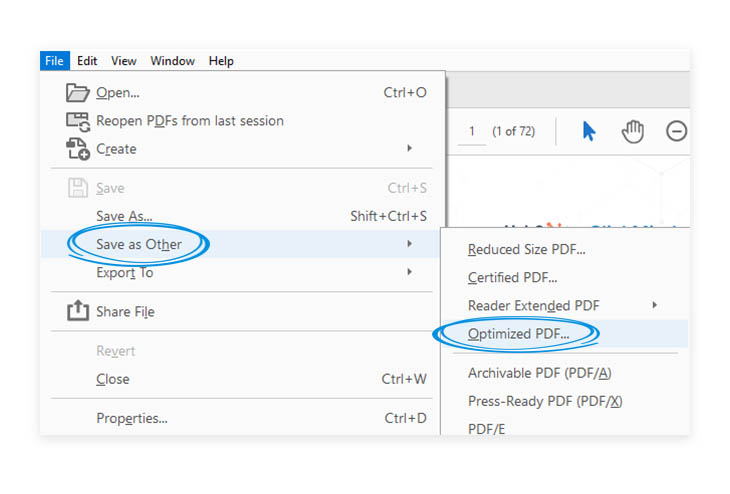
PDF compression is one of those things that sounds simple and isn't. You drop a file into a tool, it spits out a smaller version, and you assume everything went fine. It doesn't always work that way. I've spent years dealing with people who send me 80-megabyte PDFs for no reason, and I've learned that reducing file size is really a negotiation between quality and utility. Sometimes you can get 90% compression with no visible difference. Sometimes you lose everything and end up with a blurry mess that nobody can read. The trick is knowing which files are easy targets and which ones fight back. For most people, the fastest path is just using a dedicated compression tool. There are a ton of them out there, both free and paid. I generally reach for Adobe Acrobat's built-in PDF Optimizer when I'm working in a professional environment, and for quick jobs outside of that, I use smallpdf.com or ilovepdf.com. They're not fancy, but they get the job done without requiring a software installation. If you're doing this routinely at work and dealing with sensitive documents, going with a desktop solution like Acrobat Pro or even a local tool like PDFgear avoids sending your files to some random server. That's not a small consideration anymore. The process itself is straightforward. Open the PDF in your chosen tool, select the compression level, and let it run. Most tools give you options like "Low," "Medium," and "High" compression, or they let you choose target file sizes. The reality is that these presets are mostly marketing. They don't actually behave consistently across different tools. I've run the same PDF through three different online compressors and gotten files ranging from 2 megabytes to 15 megabytes, with varying quality levels. The only way to know what you're getting is to actually look at the output before you send it anywhere.
What's Actually Inside Your PDF That Makes It Bigger
PDFs get large for a handful of reasons, and understanding which one is hitting you matters more than just clicking compress. The biggest culprit is usually embedded images. A PDF with twenty high-resolution photos can easily hit 50 megabytes or more, even if the text inside is completely trivial. Images are stored at their original resolution inside the PDF container, and unless something explicitly compresses them, they stay there at full quality. This is true whether the PDF was created from a Word document, a scanned brochure, or a screenshot. The second common cause is embedded fonts. If someone used a lot of custom or decorative fonts and didn't subset them, the entire font file gets packed into the PDF. Some fonts are legitimate megabytes in size on their own. A well-behaved PDF subsetting problem means only the characters actually used in the document get embedded, but not every tool does this properly. I've seen PDFs where the font embedding added 4 or 5 megabytes for a ten-page document that used maybe twenty distinct characters from a fancy font. A third cause that people miss is multiple versions of the same content. Some PDFs, especially ones created by certain publishing workflows, contain both compressed and uncompressed versions of images, or include embedded thumbnails and preview data that most viewers never need. A proper compressor can strip all of that out. I once had a PDF that was 38 megabytes, and after running it through a proper optimizer, it dropped to 3 megabytes with zero visible quality loss. The issue was that the original file contained uncompressed scanner data alongside the actual rendered pages, basically a digital receipt of every processing step along the way.
Scanned PDFs Are a Different Problem Entirely
If your PDF is a scan, all of the above rules shift. Scanned PDFs are just images stuffed into a container, and compression behaves differently because there's no text layer to protect or optimize. The most common approach here is re-compressing the existing image data. Tools will typically downsample images to a lower DPI or switch them from uncompressed or lossless formats to JPEG compression. Going from an uncompressed TIFF inside a PDF to a JPEG at 150 DPI usually cuts the file size by 70 to 90 percent on scanned documents, and the difference is often barely noticeable unless you're zooming in very close. The problem with scanned PDFs is that aggressive compression can make text harder to read. I ran into this exact issue recently with a batch of scanned invoices. I compressed them to fit an email attachment limit, and the recipient complained that some of the smaller printed numbers were now illegible. The fix was to keep the compression moderate and instead re-run the PDF through OCR afterward, which creates a clean text layer on top of the compressed image. That way the file stays small, but the text is still selectable and readable. It added about three minutes to the workflow but completely solved the problem.
Get the Full Details

When Compression Fails and What to Do Instead
There are cases where no amount of compression will make a PDF smaller, and you should know about this before you waste time. PDFs that are already heavily compressed, PDFs with vector-heavy content like technical drawings or architectural plans, and PDFs that contain encrypted or locked elements won't shrink much regardless of what tool you use. I had a PDF that was 12 megabytes and was made almost entirely of vector graphics. Every compressor I tried managed to shave off about 300 kilobytes max. In situations like this, the only real solution is to export or re-save the original source file at a lower resolution, or to split the PDF into separate files so each one is smaller individually. Another failure mode is when compression destroys readability in ways that aren't obvious at first glance. Text that looks fine on screen can become pixelated when printed, or colors can shift in ways that matter for branded materials. I learned this the hard way with a marketing PDF that a client sent me compressed through a free online tool. The file looked acceptable on my monitor, but when they printed it, the colors were noticeably off and the fine typography had artifacts around the edges. The lesson was to always check compressed PDFs at 100% zoom and, if possible, print a test page before committing to a compressed version for anything that matters.
A Practical Workflow That Actually Saves Time
Here's how I handle PDF compression now, after enough mistakes to make me careful about it. First, I open the PDF and check its contents quickly. If it has lots of images, I note that. If it's scanned, I note that too. Then I run it through a compressor with a moderate setting rather than the most aggressive one. I always review the output on screen at full size, scrolling through every page. If it looks fine, I check the file size difference. If it's still too large, I try a second pass with slightly higher compression or, in the case of scanned documents, I re-process it through OCR first and then compress the image layer. This usually takes me about five to ten minutes per PDF, and it's faster than dealing with follow-up emails about unreadable files later. For batch processing, which I do sometimes when clients send me twelve or thirteen PDFs at once, I use a desktop tool with batch capabilities rather than an online service. Online services often have file count limits and upload times add up quickly. A desktop tool lets me queue everything up and walk away. The trade-off is that you need to install software, but if you're doing this more than once a week, it pays for itself almost immediately. Tools like Adobe Acrobat Pro, PDFgear, or even the command-line tool Ghostscript if you're comfortable with that, handle batch jobs cleanly.
Reduce Size Of Pdf Without Losing What Matters
The bottom line is that reducing PDF file size is not a single click solution that works identically every time. It's a process that depends on what's inside the file, what you're willing to sacrifice, and what the end user will actually do with it. Most of the time, a moderate compression pass with a proper review will get you where you need to go. The files that resist compression usually need a different approach entirely, and the files that look fine after compression sometimes cause problems later when printed or viewed at different sizes. Checking your work before sending it out is the part that saves you the most trouble, and it takes about thirty seconds per page that you'd otherwise spend cleaning up a mess you didn't notice.