Documentation that gets used
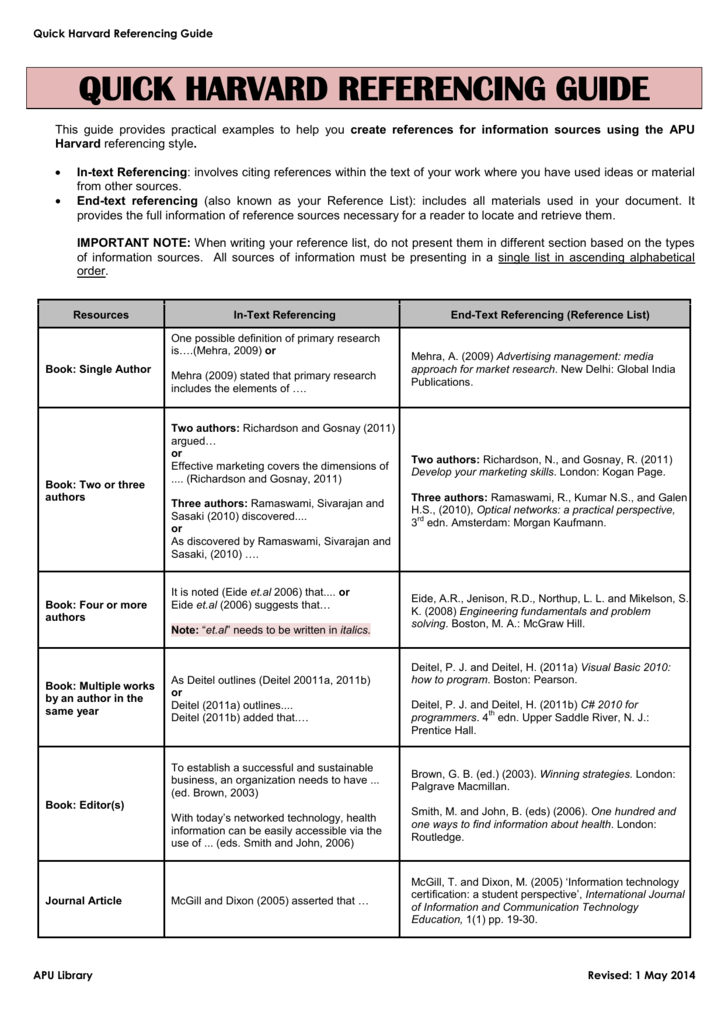
I've written enough reference guides to know most of them are useless. Not because the information is wrong, but because nobody actually uses them. I learned this building internal docs for a product that had dozens of configuration endpoints. The first version we shipped was thorough. Every field documented with descriptions, examples, and notes. Nobody opened it. People just paged through Slack asking the same questions we'd answered three times. What changed things wasn't adding more information. It was restructuring everything as a dense lookup table. Field name. Type. Default value. Required? Example. That's it. Usage went up noticeably within the first week after we made the switch, and it stayed there. People weren't reading the guide for learning. They were opening it to confirm something specific while configuring their environment. That distinction matters more than most teams acknowledge.
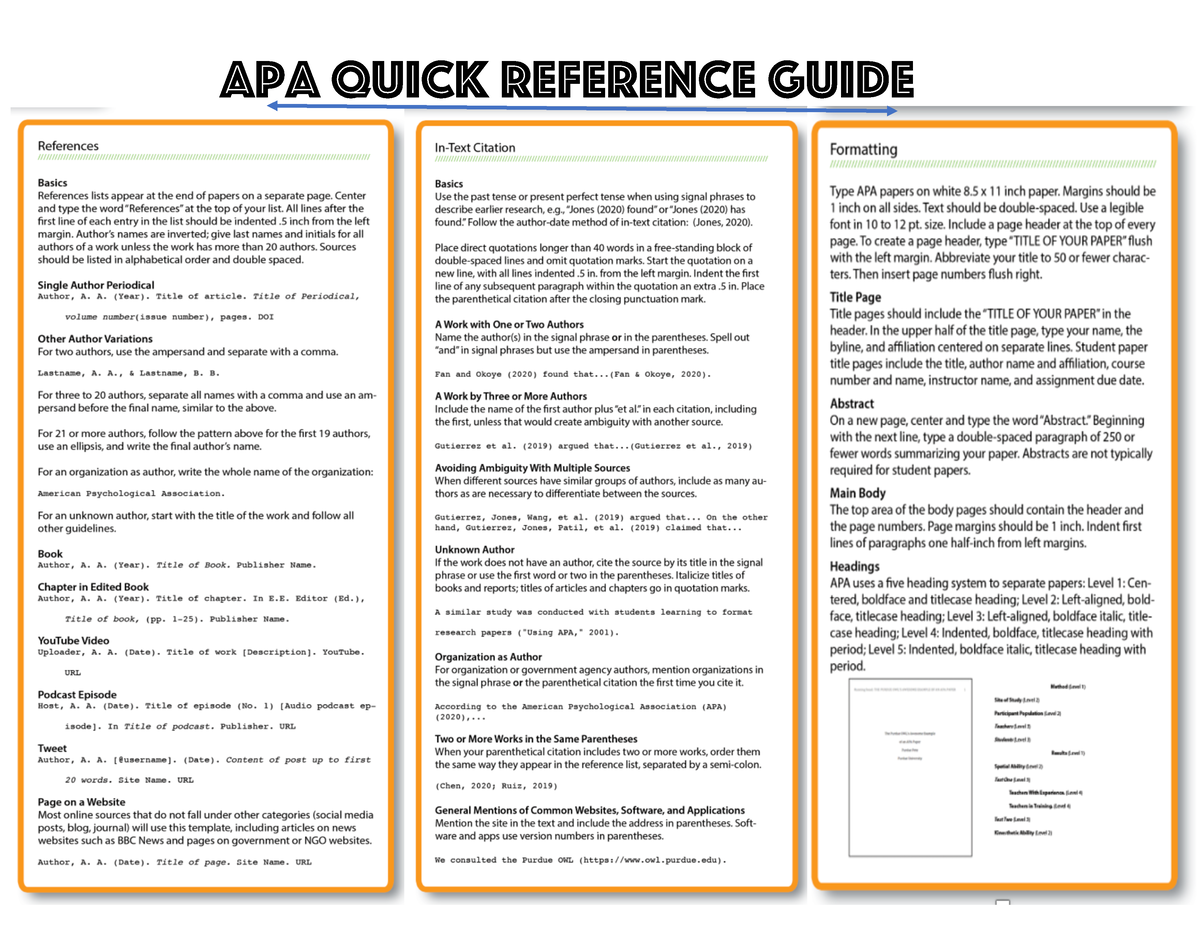
Reference Guide Best Practices
Structure by lookup pattern, not by logic. Reference guides are not tutorials. They are lookup tables with explanations attached. The moment you organize entries topically, you've made a conceptual guide and you should label it as such. If someone needs to find "authentication methods," they should be able to scan a section header and immediately see the options, not read three introductory paragraphs about why authentication exists. I've reorganized entire pages that started as conceptual essays because developers told me they couldn't find the parameter they needed while debugging at 2 AM. That feedback is more valuable than any design review. One thing most people miss: the order of properties within a single entry matters. I used to list properties in the order they appeared in the schema, which seemed logical. But developers typically look up the same two or three fields repeatedly. I switched to ordering by frequency of lookup instead. Required fields first, then commonly overridden fields, then the obscure ones. It took me about ten minutes per reference entry to audit the data, but it cut down follow-up questions significantly over the next few months. Example quality is where most reference guides fail. Beginners always include the happy-path example because it's satisfying to write. The example that prevents a support ticket is the one showing what happens when the optional field is missing, or when two fields conflict with each other. I once spent a week tracking down a bug that turned out to be caused by a default value behavior nobody had documented. We added a single warning note under that field explaining the default, and the issue stopped appearing in tickets entirely. The fix was three sentences and a code block.
Definitions matter more than most teams realize. If you're describing a standard term like idempotency or eventual consistency, link to or quote the source. Don't rephrase it in your own words and present it as your own definition. I learned this when someone cited my rephrased definition of a caching strategy, got it slightly wrong, and it caused real confusion across two engineering teams. I went back through every reference entry and added source citations where applicable. It took an afternoon and probably prevented a long-term credibility problem. Maintainability is the hidden bottleneck. A reference guide that isn't updated alongside the codebase becomes worse than no guide because it creates false confidence. I've seen teams ship a reference guide and then never touch it again for eighteen months while the API evolved. The outdated guide got more traffic than the current implementation actually matched. The solution I ended up implementing was pulling parameter definitions directly from the source code or OpenAPI spec rather than maintaining them manually. Documentation-as-code. It cuts the update time from hours to minutes because regenerating the reference is mostly automated now. There are tradeoffs. Automated generation means you lose the ability to add contextual notes that aren't in the schema. A manually maintained guide lets you explain why a default value exists, or warn about a known issue. Automation strips that out. You have to decide which tradeoff hurts less for your audience. For most internal tools I've worked on, the accuracy benefit of automation outweighs the loss of narrative context. For external developer-facing references, the narrative context sometimes carries enough weight that a hybrid approach makes sense.
Get the Full Details
Formatting consistency is non-negotiable, and I mean across the entire document, not just within a single section. If property names use code formatting in one entry and bold in another, readers unconsciously stop trusting the document. I enforce this with a strict lint rule in our documentation pipeline. Broken cross-references cause similar trust issues. Nothing destroys confidence faster than clicking a link labeled "see also" and landing on a 404 page. I validate all internal links as part of the build process now. It adds about thirty seconds to the build but catches the vast majority of broken references before they reach production. If your reference is growing beyond a single document, consider whether a static reference guide is the right format at all. Some tools end up with hundreds of reference pages because each endpoint gets its own entry. That's manageable at first but becomes unmaintainable quickly. I've worked on projects where we replaced hundreds of reference pages with a single searchable configuration dictionary paired with a separate troubleshooting guide. The reference dictionary was machine-generated from the schema. The troubleshooting guide covered the nuance that the reference couldn't capture. This split usually takes longer to set up initially, roughly a day or two of engineering time for a moderate-sized project, but the long-term maintenance burden drops dramatically compared to keeping hundreds of overlapping pages in sync. The metric that actually matters isn't page views. It's whether people are finding the information they need without opening a separate support channel. I started tracking the ratio of reference guide visits to related support tickets for each major section. When that ratio stayed stable or improved after a documentation update, the update was working. When it got worse, the new content was either misleading or insufficient. That signal has been more honest than any usability test I've run on documentation.
For teams just starting out, the simplest upgrade path is to take your existing reference and strip every example down to two: one correct usage and one failure case. That alone usually brings a meaningful improvement without requiring a complete rewrite.