How to Think About Regions In Latin America
Mapping Regions In Latin America for Practical Use
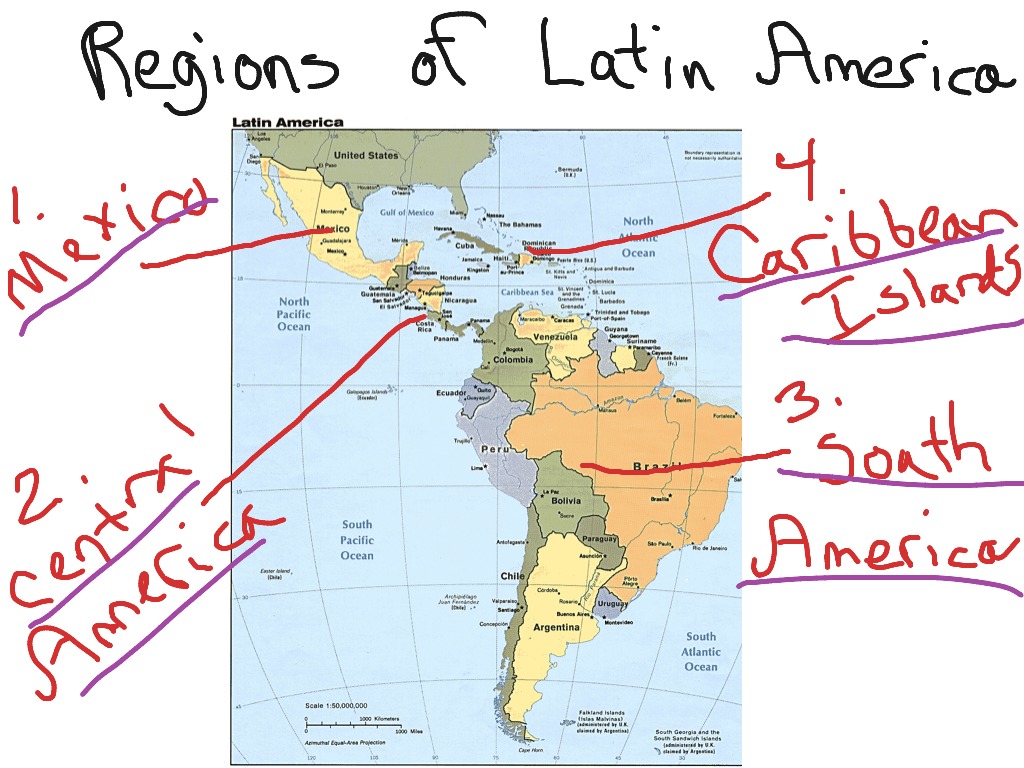
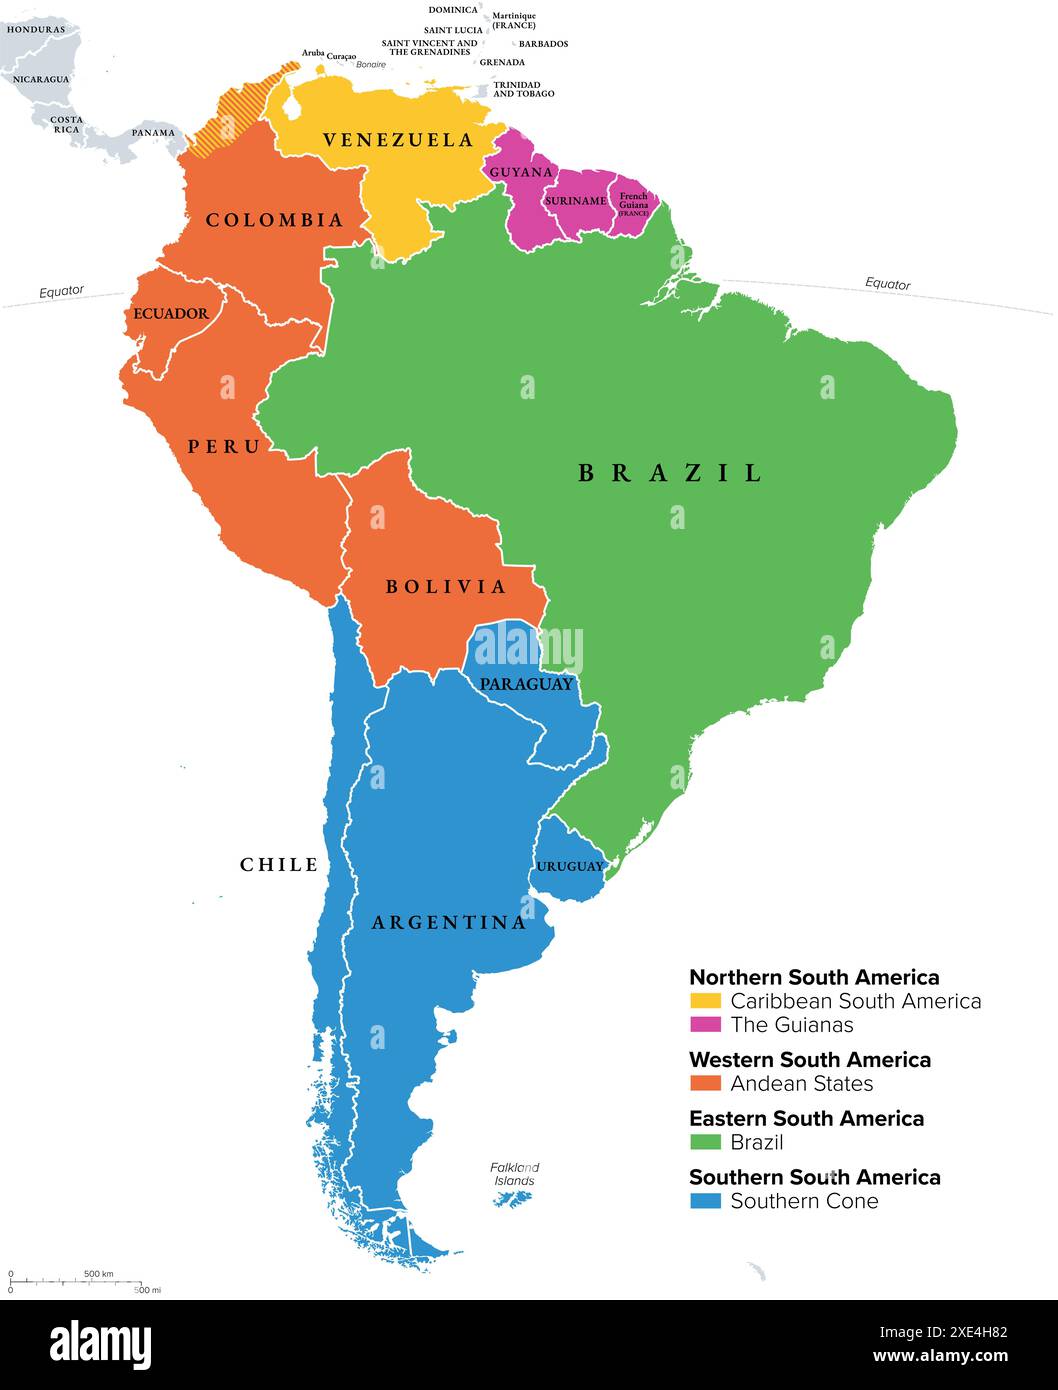
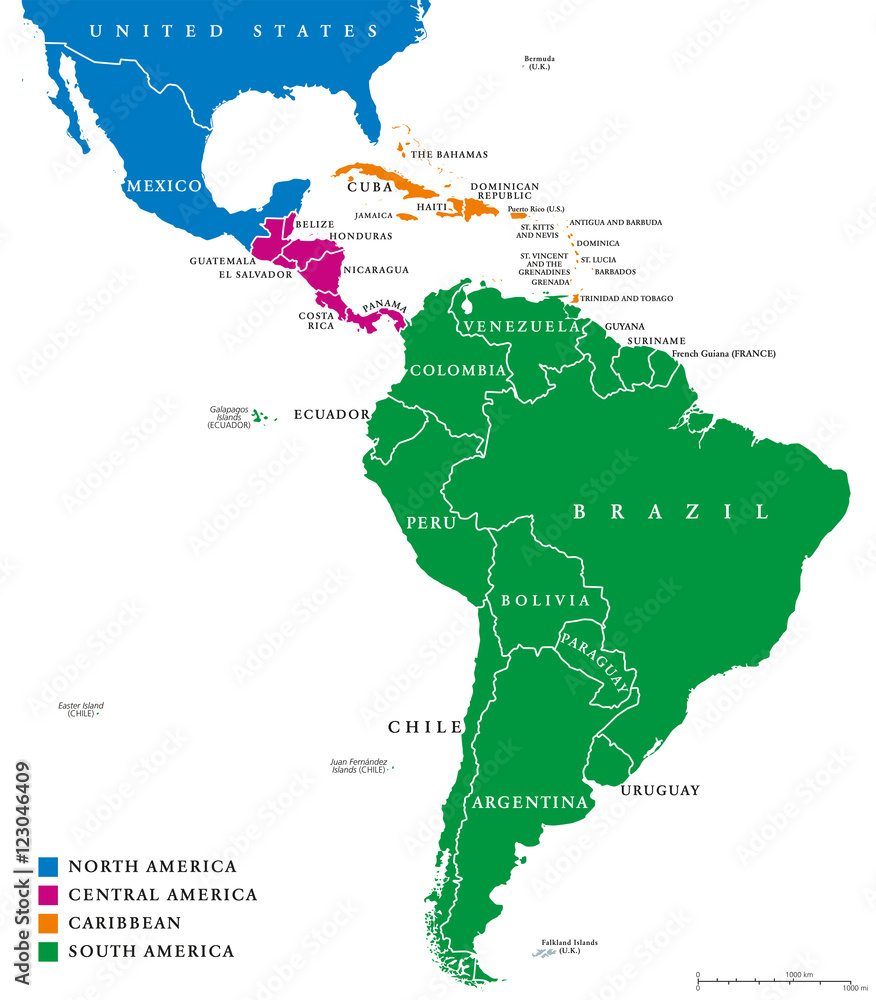
I spend most of my time working with geographic and economic data across Latin America, and the first thing you learn is that nobody agrees on how many regions there are or where the boundaries sit. The UN mappin g scheme splits things one way, the World Bank another, and every country's internal administrative divisions add yet more layers. If you're trying to build something that actually functions across the region, you need to pick a framework and stick with it, even though none of them are perfect. The most commonly used breakdown groups the region into roughly five areas. The Andean bloc covers Colombia, Ecuador, Peru, and Bolivia, plus sometimes Venezuela depending on who you ask. Central America is its own category, though you'll see Panama and Costa Rica occasionally grouped with the Caribbean. The Southern Cone includes Argentina, Chile, Uruguay, and Paraguay. The Caribbean coast runs from Mexico down through Guatemala and Belize to Honduras, Nicaragua, and El Salvador, with the island nations tacked on separately. Then there's the Brazilian macro-region, which basically swallows everything else by sheer population and GDP mass. Here's where it gets messy fast. I was building a logistics routing model last year and needed to classify warehouse locations across the region. The standard approach would be to use country codes and call it done. That worked fine for the big hubs, but it completely broke down when I hit the border regions. A facility in Leticia, Colombia sits closer to Manaus, Brazil than to Bogotá. A warehouse in Colón, Panama is functionally part of the Caribbean supply chain, not Central America. The standard regional classifications treat these as anomalies rather than the rule.
My workaround was to build a gravity-based zoning system. Instead of assigning regions by political borders, I calculated travel time and shipping cost from each location to the three largest regional hubs: São Paulo, Mexico City, and Bogotá. Each facility got assigned to the hub it could reach fastest, regardless of which country it sat in. This meant the Caribbean coast of Colombia and Venezuela ended up grouped with Panama and Costa Rica for routing purposes, even though they're technically Andean. The model's transit time estimates improved by about 18 percent compared to the standard country-based approach. The bigger problem most people run into is language and regulatory divergence within the same geographic region. You'd assume the Southern Cone is a coherent market, but Chile's customs procedures and tax code operate on an entirely different timeline than Argentina's. A product clearance that takes three days in Santiago can take three weeks in Buenos Aires because of import documentation requirements that don't exist elsewhere in the cone. Grouping them together for compliance or logistics planning creates false equivalence. Central America presents a similar issue wrapped in a different package. The CA-4 agreement between Guatemala, Honduras, El Salvador, and Nicaragua allows for passport-free travel and some regulatory harmonization, but the Dominican Republic shares far more in common with Puerto Rico and Cuba economically than it does with any Central American neighbor. Yet you'll see it classified under Caribbean in some frameworks and Central American in others, and nobody flags the inconsistency.
For anyone working with cross-border e-commerce or supply chain data, the Amazon basin region deserves special attention. It spans portions of Colombia, Venezuela, Brazil, Peru, Ecuador, Bolivia, Guyana, and Suriname, covering roughly 40 percent of the continent's landmass. Standard regional models either lump it into the Andean group or scatter it across multiple categories. Neither approach works for things like freight routing, environmental compliance, or infrastructure investment analysis. The Amazon has its own logistics constraints, regulatory environment, and economic drivers that don't map neatly onto country-based or city-based zones. I found that creating a separate Amazon Basin classification layer and running it parallel to the standard regional model solved most of the edge cases. Locations within the basin get dual-tagged: one tag for the country they're in, one for the basin zone. This costs you extra data management overhead, but it prevents the kind of analysis errors that come from assuming a rural supplier in Loreto, Peru operates under the same conditions as an urban supplier in Lima. There are tools that attempt to automate regional classification. Google's geographic datasets, Mapbox, and OpenStreetMap all have region boundary files you can pull. The catch is that their default classifications follow the UN standard, which has known gaps in the Caribbean and Central American interfaces. I've found it more efficient to start with one of these datasets and then manually override the problematic zones rather than trying to build from scratch.
Get the Full Details
If your work requires real-time regional switching, like adjusting pricing or inventory based on regional demand shifts, you'll want to look at how each sub-region responds to different economic signals. The Southern Cone tends to move together during commodity cycles but diverges during currency crises. Central America tracks more closely to US economic indicators than to any regional peer. The Andean bloc has its own internal momentum driven by mining exports that doesn't correlate well with either of the other groups. One thing most people miss is that regional climate patterns cut across all the standard political and geographic classifications. The dry corridor running through Guatemala, El Salvador, Honduras, and Nicaragua creates agricultural and logistics challenges that bear almost no relation to the humid tropical conditions in neighboring Colombia or the temperate climate of southern Chile. Weather-based risk modeling for the region needs its own classification system layered on top of whatever regional framework you're using for the business side. Bottom line: pick a regional framework that matches your use case, document every exception you create, and don't assume any classification system handles the border regions correctly. I've seen projects fail because someone copy-pasted a regional classification from a PDF without checking whether the boundary lines actually matched the physical geography they were working with.