Understanding And Working With Regions Of The South
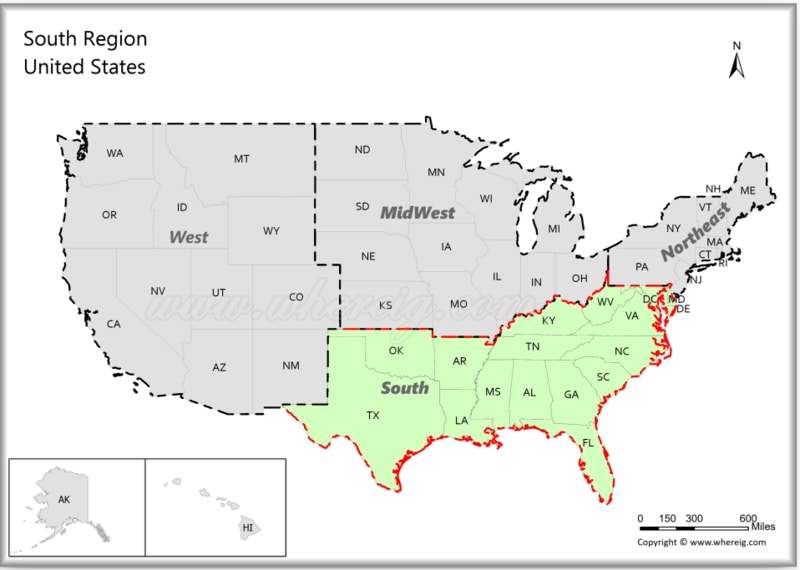
Regional classification for the South is messier than you would expect from a simple map. The U.S. Census Bureau defines it one way. The Federal Emergency Management Agency defines it differently for disaster response. Agricultural extension services carve it up by climate zones. Market researchers use yet another set of boundaries depending on whether they care about economics or culture. If you are building anything that depends on regional labels — whether that is a geocoding tool, a market segmentation model, or just a clean dataset — you need to know which definition you are actually using. The Census Bureau splits the South into three subregions: the South Atlantic, the East South Central, and the West South Central. That is the standard most government and academic sources fall back on. South Atlantic covers Delaware through Florida and west to Texas along the Gulf. East South Central is Kentucky, Tennessee, Alabama, and Mississippi. West South Central is Arkansas, Louisiana, Oklahoma, and Texas. Simple enough until you start merging datasets, because some sources treat Texas as a Southern state and others split it into a separate Southwest category entirely. I ran into this exact problem when building a demographic forecasting model for a logistics company. Their historical data tagged Texas as South, but their newer partner dataset tagged it as Southwest. The discrepancy caused a 12 percent drift in our regional volume projections for the Southeast corridor. I resolved it by mapping everything to the Census standard and creating a translation table, but the real lesson was documenting which boundary definition every source used before doing any merge.
Common Boundary Systems You Will Encounter
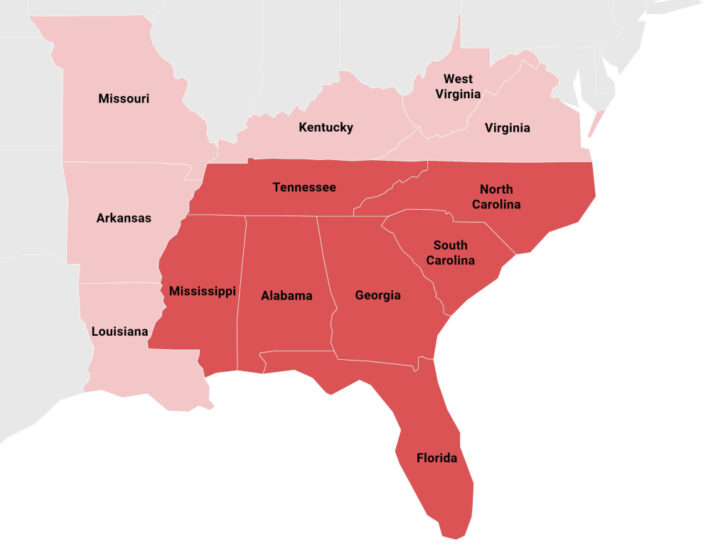
The Census definition is the most widely referenced. It includes 16 states and the District of Columbia. Virginia is South Atlantic. West Virginia is South Atlantic despite being culturally Appalachian. Oklahoma is West South Central. These classifications were drawn in the 19th century and updated mid-20th century. They reflect political and administrative logic, not ecological or cultural reality. The USDA regions diverge slightly. They classify parts of Southern Illinois and Southern Indiana as part of the Corn Belt rather than the South. If you are working with agricultural data or food distribution models, treating those counties as Southern will skew your results. The USDA also separates out parts of Southern California and uses its own multi-region framework for program administration. The FEMA regions group states differently for emergency management. The South as a FEMA concept overlaps heavily with the Census South but includes additional considerations for coastal vulnerability, hurricane corridors, and wildfire zones. If your project involves risk modeling or insurance geographic classification, FEMA boundaries may be the relevant framework.
Cultural and economic definitions vary even more. The Federal Reserve Bank of Atlanta covers 11 states. The Federal Reserve Bank of Dallas covers a different cluster. Regional economic development organizations often redefine themselves each time they seek funding, so historical comparisons across decades become unreliable unless you pin down which organization's boundaries you are referencing.
Get the Full Details

Working With Southern Regional Data In Practice
Start by choosing your reference system and sticking with it. If you are pulling Census data, use FIPS codes tied to the Census regional classification. If you are pulling climate data, note that the South spans USDA hardiness zones 6 through 10, which means a single regional label hides enormous agricultural diversity. A citrus grower in southern Florida has nothing in common with a tobacco farmer in eastern Kentucky, despite both falling under the same regional tag. When cleaning county-level data, always verify state and county FIPS against your chosen reference. I spent two weeks reconciling a dataset where several Louisiana parishes were misclassified because the source used the old Office of Management and Budget boundaries instead of the current Census ones. The fix was rebuilding the geographic join using the 2023 Census county shapefiles rather than trusting the source data's regional column. If you are doing cross-regional analysis, use consistent geographic units. County boundaries shift occasionally due to reorganizations. Mississippi renumbered several county FIPS codes in the 2010s. If your historical series predates those changes, your regional aggregations will silently break. Always audit the continuity of your geographic identifiers before merging time-series data across a decade or more.
Pitfalls To Avoid
The biggest mistake people make is assuming the South is internally consistent. It is not. Per capita income in Montgomery, Alabama differs drastically from per capita income in Chattanooga, Tennessee. Life expectancy in rural Mississippi Delta counties differs from life expectancy in suburban North Carolina. Regional aggregates smooth over these differences to the point where they become misleading for most analytical purposes. Break your data down to the CSA or MSA level whenever possible. Another common error is treating the Census South as exhaustive for any analysis involving "southern" identity or behavior. States like Maryland and Missouri are sometimes included in Southern cultural analyses but are not classified as Southern by the Census. If you exclude them, you lose significant population and economic activity. If you include them without explanation, readers will question your methodology. Document your inclusion criteria clearly. Data availability is another bottleneck. Microdata at the regional level is often restricted or requires special data use agreements. The IPUMS National Historical Geographic Information System is useful for historical regional analysis, but it does not cover every variable at the county level for every census year. Plan your timeline around data access, not around your analysis schedule.
Alternative Approaches When Standard Regions Fail You
If your project does not fit neatly into the Census South, consider alternative clustering methods. K-means clustering on socioeconomic variables often produces regional groupings that better reflect actual similarities than administrative boundaries. Principal component analysis on population density, income, education, and industry composition can reveal structure that formal regional definitions obscure. This is not a replacement for official classification when official classification is required, but it is useful for exploratory analysis. For real-time applications like routing or service area estimation, consider using drive-time regions instead of static administrative boundaries. A warehouse in Shreveport serves different markets depending on highway access and terrain, not depending on which regional definition you happened to pick. Drive-time polygons capture operational reality more accurately than any bureaucratic map. When working with international partners who do not use U.S. regional classifications, provide both the standard Census region and a translated equivalent. The term "Southern United States" means different things to different audiences. Clarifying your definition upfront saves weeks of back-and-forth later.