Getting Regression Analysis by Example Solutions Right
Most people learning regression analysis get stuck because the math side is presented in a vacuum. You learn least squares, you memorize the slope formula, and then you have no idea what happens when you actually run it on a messy dataset. That gap between textbook theory and working code is where I spent years figuring things out the hard way. Regression Analysis By Example Solutions is essentially a collection of worked-through problems that walk you from the mathematical setup all the way to interpreting the output on real data. The best ones don't just show you the answer, they show you the mistakes along the way and why certain assumptions break down in practice.
Why Most Tutorials Fail You on Regression
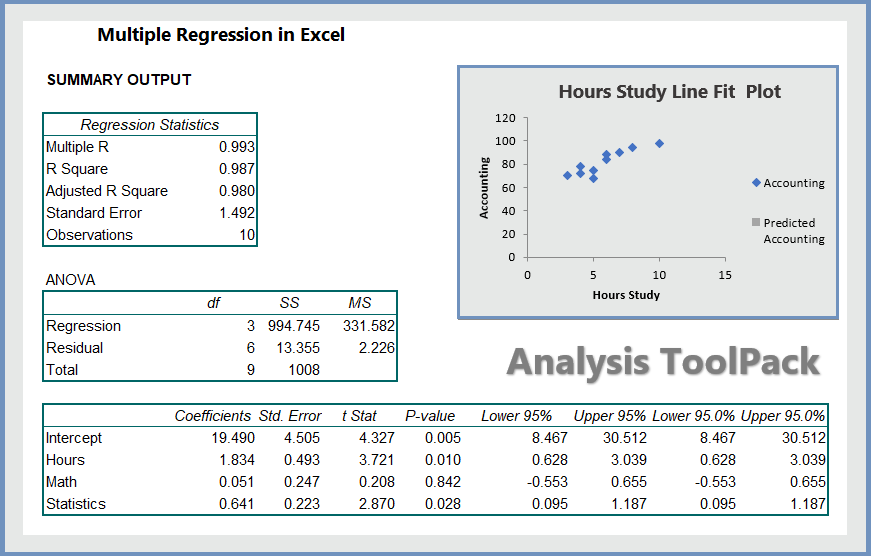
I see the same pattern over and over. Someone watches a video where the instructor runs a clean regression on a toy dataset, everything looks perfect, the coefficients are all significant, and R-squared is 0.89. Then they go back and try to apply it to actual business data or research data, and the model collapses. The residual plots look like garbage, the standard errors are enormous, and the coefficients flip signs depending on which variables you include. The issue is that most solutions skip the diagnostic phase entirely. They treat regression like a button you push rather than a modeling framework you build incrementally. When I was starting out, I spent weeks thinking I was bad at statistics because my models never matched the clean examples. The problem wasn't me, it was that nobody showed me what the output actually looks like when assumptions are violated. Here's a specific example from my own work. I was fitting a multiple regression model to predict project completion times based on team size, budget, and scope complexity. The textbook procedure said to just dump all the variables in and check the overall F-test. The initial model had an R-squared of 0.71 and all the individual t-tests came back insignificant. That contradiction should have been a red flag, but I didn't know what it meant yet. After running the diagnostics, I found severe multicollinearity between team size and budget. The variance inflation factors were all above 15. I ended up switching to a ridge regression approach instead, which stabilized the coefficients enough to get usable estimates. A well-constructed Regression Analysis By Example Solutions document would have shown this exact scenario and walked through the diagnostic steps before jumping to the final model.
What Actually Makes a Good Example-Based Solution
A solid worked example needs to cover the full pipeline, not just the final equation. Start with the data structure and why you chose regression in the first place. Show the exploratory phase. Then build the model, interpret each coefficient, check assumptions, and revise if needed. The revision step is where most resources skip ahead, but that's where the actual learning happens. When evaluating solutions to follow, look for these markers. The examples should include residual plots, not just text descriptions of them. They should show how to test for heteroscedasticity and what to do when you find it. They need to address missing data honestly instead of listing observations dropping from 500 to 478 without explanation. And they should discuss when regression is the wrong tool entirely, which happens more often than people admit. I ran into a situation last year where I had count data with heavy zero-inflation and I was trying to force a standard linear regression onto it. The predicted values kept coming out negative, which is impossible for a count. The solution wasn't better model fitting, it was recognizing that Poisson or negative binomial regression was the right framework. A good Regression Analysis By Example Solutions resource would show that pivot point explicitly, explaining how to read your data distribution and decide on the model family before writing any code.
Get the Full Details
Key Pitfalls Even Experienced People Miss
One counter-intuitive thing about regression that doesn't get enough attention is that adding more variables doesn't always help, even when they're statistically significant. I've seen people include ten control variables because their supervisor asked for it, and the model became overfit to noise in the sample. The in-sample fit looked great but it had zero predictive power out of sample. Cross-validation catches this, but too many example solutions don't mention it. Another thing that surprises people is that correlation between predictors can make individual coefficients unstable while the overall model predictions stay perfectly fine. If you're doing prediction, you might not care about individual coefficient interpretation at all. The model works, move on. If you need causal interpretation, then the instability matters and you need to think about identification strategy before you touch the data. The assumption check phase deserves more space than it typically gets. Normality of residuals matters for inference, especially with small samples. But with large datasets, the central limit theorem takes care of most concerns about the sampling distribution of coefficients. Heteroscedasticity matters much more in practice, and it's easy to overlook until your standard errors are way off. Robust standard errors are a one-line fix in most software packages, but you have to know to ask for them.
Where These Solutions Fall Short
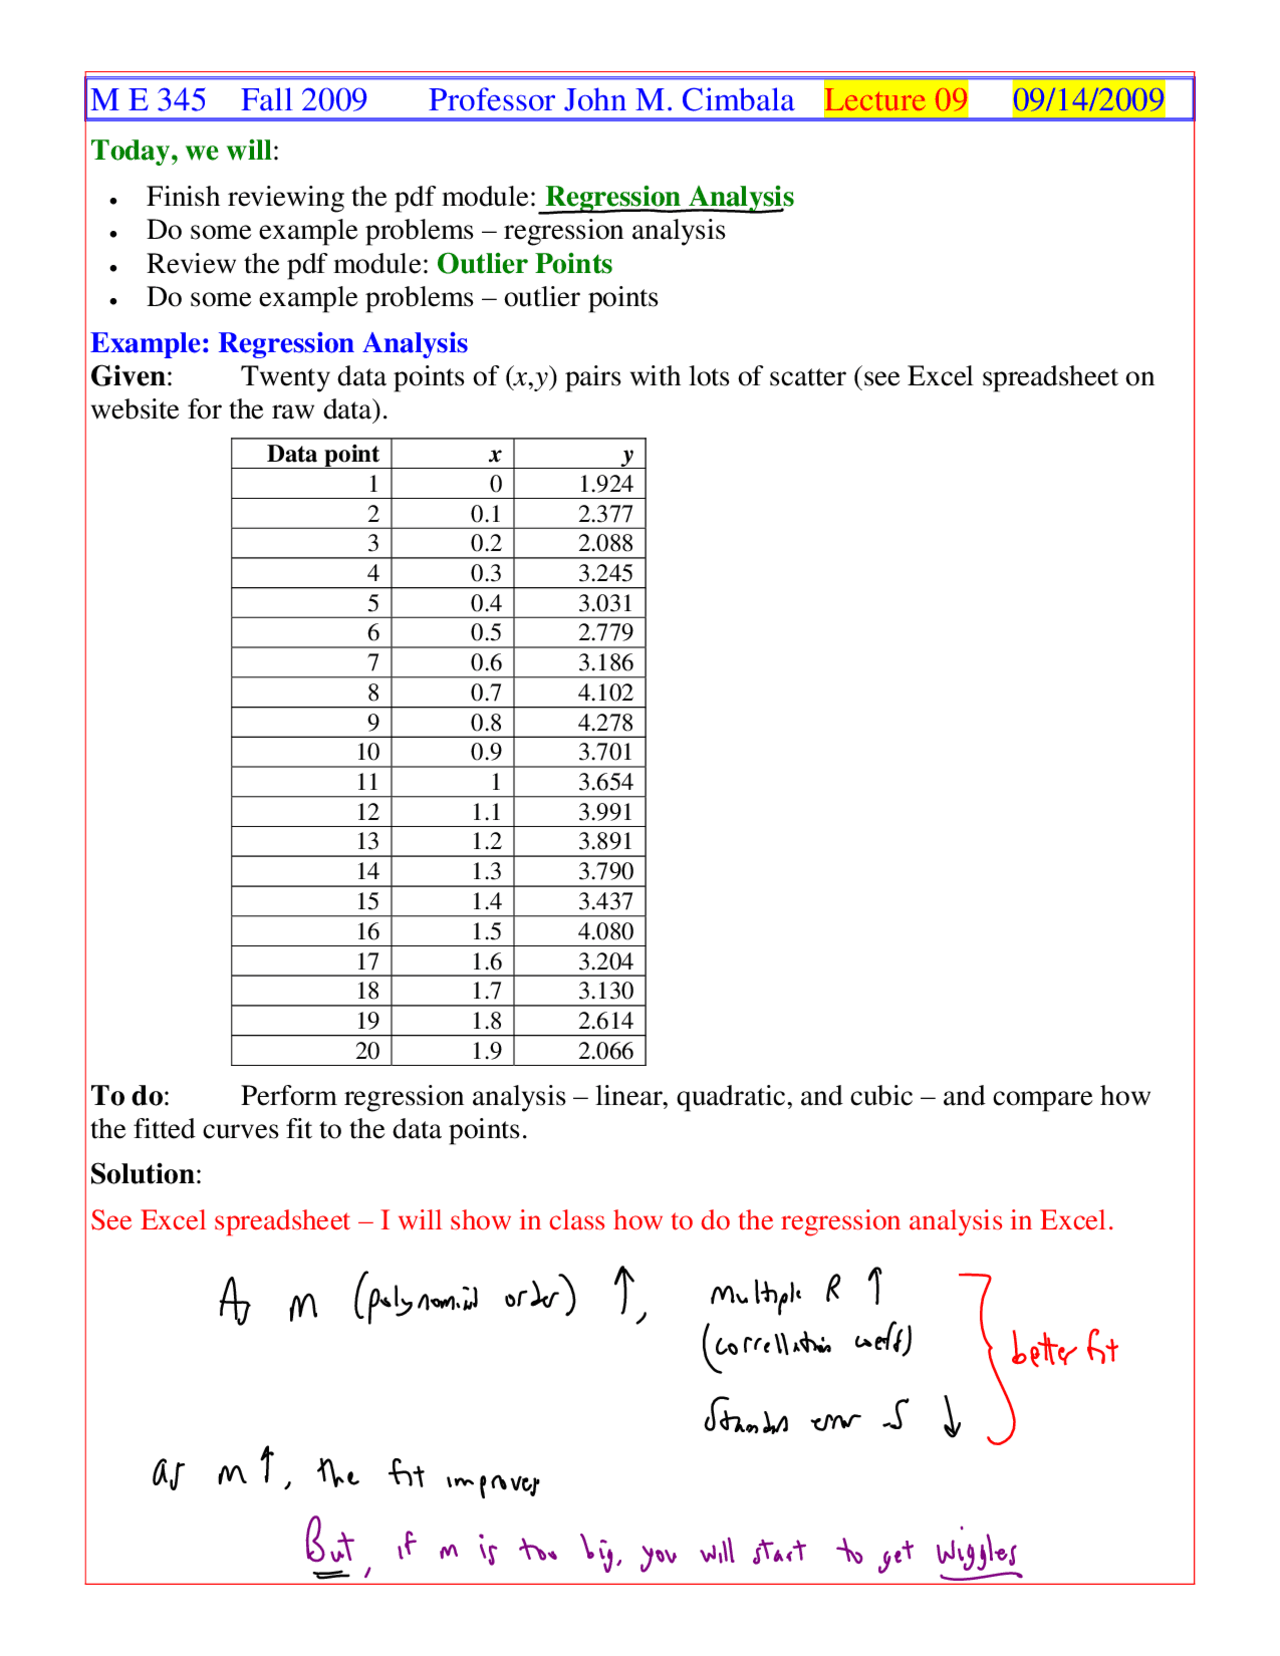
Linear regression is limited in ways that beginner tutorials rarely emphasize. It assumes linearity in the parameters, which means if your true relationship is nonlinear, you need to either transform variables or switch frameworks. It assumes the effects are additive unless you explicitly add interaction terms. It gives you a single average effect across your entire dataset, which can mask important subgroup differences. For predictive work, regularized methods like lasso and elastic net often outperform standard regression, especially with many correlated predictors. For nonlinear relationships, tree-based methods or GAMs are more appropriate. Regression is still the default for a reason, but it's not the best tool for every job. Good example solutions should acknowledge this boundary rather than presenting regression as a universal solution. The biggest gap in most available resources is that they don't cover the decision-making process around model selection. Which variables go in? How many? On what basis? Stepwise selection is widely taught but statistically flawed, and most textbooks don't do a good job explaining why. Information criteria like AIC and BIC help but they're not silver bullets. Subject matter knowledge should drive the process, and example solutions that ignore that trade-off are doing their readers a disservice.