
Getting started with regression in R isn't as clean as people make it sound
R comes pre-installed with a lot of what you need for basic regression work. The lm function does the heavy lifting, and that's honestly where most people stop. They run a model, look at the summary output, and call it a day. That's usually enough to get you into trouble, because the summary output will happily give you coefficients and p-values even when your model is fundamentally broken. I'm going to walk through the practical side of Regression Analysis With R, not the textbook version. You'll learn how to actually validate what you're doing instead of just staring at a regression table and nodding along.
Setting up the environment for Regression Analysis With R
You need R installed first. Go to CRAN and grab the latest version for your operating system. The standard installer works fine. After that, install the packages you'll actually use. Most people reach for tidyverse right away, but for regression work specifically, you want broom, car, and performance. Broom tidies model outputs into data frames, car handles diagnostics you'd otherwise code by hand, and performance checks model quality metrics. That's the whole setup. Takes about two minutes on a decent connection. Don't bother with RStudio if you don't want it. The base R console handles everything I'm about to show you. But if you do use RStudio, the plot viewer and environment pane save you from typing capture.output() constantly. Load your data. If it's a CSV file, read.csv does the job. If it's already in R format, just load it. Let's say you have a dataset called housing with variables like price, square_feet, bedrooms, and age.
That's it. One line of code builds the model. The summary(model) command gives you coefficients, standard errors, t-statistics, p-values, R-squared, adjusted R-squared, and the F-statistic. It looks impressive. It also doesn't tell you whether your model is any good. Here's where beginners miss things. R-squared will always increase when you add predictors, even if those predictors are pure noise. Adjusted R-squared corrects for this partially, but it's still a lazy metric. AIC and BIC are better for model comparison because they penalize complexity more rigorously. When I'm choosing between models, I look at AIC first and use it as my primary sorting metric. Lower is better. The difference matters more than the absolute value.
Get the Full Details
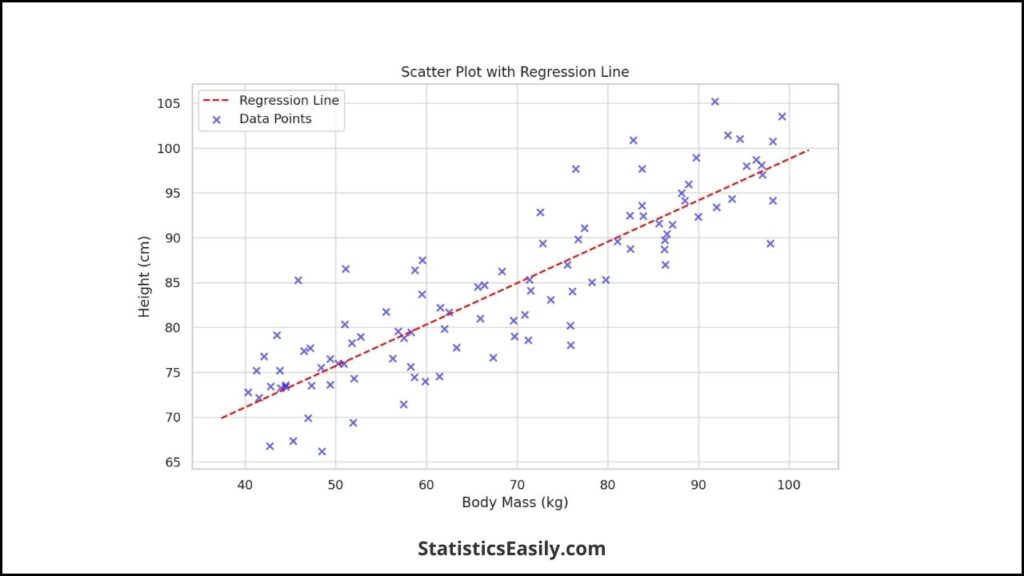
Diagnosing what's actually wrong with your model
This is where the real work happens. Run these four diagnostic plots before you trust any coefficient. The residual versus fitted plot should show a random scatter around zero. If you see a curve, you have non-linearity. If you see a funnel shape, you have heteroscedasticity. The Q-Q plot checks normality of residuals. Deviations from the diagonal line at the tails mean your residuals aren't normal, which matters for inference but less for prediction. The scale-location plot catches heteroscedasticity more clearly than the first plot. The residual versus leverage plot flags influential points that are dragging your coefficients around. Don't skip the numerical diagnostics either. The ncvTest from car checks for non-constant variance. The Shapiro-Wilk test checks residual normality. The vif function checks for multicollinearity. If any predictor has a VIF above 10, you have a serious collinearity problem. Between 5 and 10 is worth investigating but not panic-worthy.
I ran into a specific issue recently with a model predicting loan defaults. The dataset had about 40,000 observations and twelve predictors. The model looked fine on the surface. R-squared was reasonable, p-values were significant, everything checked out superficially. Then I looked at the residuals against each predictor individually using conditional effect plots from the effects package. Two of my predictors had a subtle U-shaped relationship with the outcome that the linear model completely missed. Adding polynomial terms for those two variables improved the AIC by about 200 points and fixed the residual patterns. That's the kind of thing you miss if you only look at the summary output.
Handling common problems in Regression Analysis With R
Multicollinearity shows up constantly in real data. When two predictors are highly correlated, the coefficients become unstable and standard errors inflate. You might see a predictor flip sign between models or become non-significant when added to a model with a correlated partner. The workaround is straightforward but requires judgment. You can drop one of the correlated predictors, combine them into a composite variable, or use ridge regression through the glmnet package. I prefer dropping or combining when I can justify it theoretically. Ridge regression is a safety net, not a solution to bad model design. Heteroscedasticity is another frequent issue. The White test and the Breusch-Pagan test detect it. If you find it, weighted least squares or robust standard errors fix the inference problem. Robust standard errors are easier in R. Just wrap your model with coeftest from car and specify vcovHC.
library(car)
coeftest(model, vcov = vcovHC(model, type = "HC3"))
HC3 is the default recommendation for small to medium datasets. It adjusts for degrees of freedom better than HC1 or HC2. Outliers and influential points need separate treatment. They're not the same thing. An outlier is an observation with an unusual response value. An influential point is one that significantly changes your coefficients when removed. A point can be an outlier without being influential, and vice versa. Cook's distance above 1 is the conventional cutoff for influence, though that's quite generous. I use 4/n as a stricter threshold, which for most datasets means anything above 0.01 to 0.05 warrants investigation. When I find influential points, I don't automatically delete them. I check the data entry, run the model with and without the point, and decide based on whether the change is substantively meaningful.
Model selection without shooting yourself in the foot
Stepwise regression is widely taught and widely wrong. Forward selection, backward elimination, bidirectional stepwise based on AIC or p-values. It sounds efficient. It produces optimistic results that don't replicate. The selected model will almost always overfit your particular dataset. I avoid it entirely unless someone hands me a dataset with genuinely unmanageable dimensionality. Instead, I use a combination of theory and cross-validation. Start with a model based on domain knowledge. Check diagnostics. Add or remove predictors based on substantive reasoning, not automated selection. If you must compare many models, use k-fold cross-validation to estimate out-of-sample performance. The caret package makes this trivial.
library(caret)
train_control <- trainControl(method = "cv", number = 10)
grid <- expand.grid(.degree = 1:3, .n.splits = c(2, 3, 5))
model_cv <- train(price ~ ., data = data, method = "lm", trControl = train_control)
That gives you a cross-validated estimate of performance that's actually useful for comparing models. Ten-fold CV is standard. For small datasets under a thousand observations, consider leave-one-out or repeated CV to reduce variance in the estimate. Linear regression in R assumes a continuous outcome. If your dependent variable is binary, count-based, or categorical, lm is the wrong tool. Use glm with the appropriate family argument. Logistic regression uses family = binomial. Poisson regression uses family = poisson. Negative binomial through the MASS package handles overdispersed counts. R supports all of these natively without extra packages, though those packages make things easier. Mixed effects models for clustered or hierarchical data require lme4. The syntax is different from lm, and the output interpretation changes. Fixed effects are the usual coefficients. Random effects capture group-level variation. If your data has repeated measures or nested structure, ignoring that structure invalidates your standard errors. Use lmer from lme4.

library(lme4)
mixed_model <- lmer(price ~ square_feet + (1 | neighborhood), data = data)
The random intercept by neighborhood accounts for the fact that houses in the same area share unmeasured characteristics. This changes both the coefficients and their standard errors compared to a plain lm. Another hard limitation: regression assumes your predictors are measured without error. In practice, survey data, self-reported values, and proxy variables all introduce measurement error. This biases coefficients toward zero in simple regression and creates more complex attenuation in multiple regression. No amount of R code fixes this. You need better data collection or instrumental variables, which are a separate topic entirely. Finally, regression is terrible at capturing complex interactions and non-linear relationships unless you explicitly model them. Decision trees and random forests handle non-linearity natively. Gradient boosting with xgboost or lightgbm often outperforms regression on prediction tasks. If your goal is prediction rather than inference, consider whether a regression model is the right choice at all. Regression is excellent for understanding relationships and testing hypotheses. It's mediocre for accurately predicting values in complex, high-dimensional data.
The speed of fitting a linear model in R is essentially instantaneous for datasets up to a few million rows. Beyond that, you'll want biglm or data.table approaches. But for typical research and business datasets, the built-in lm function is more than adequate. The bottleneck is never the computation. It's the diagnostics and the model validation. Spend your time there.


