How These Two Concepts Actually Interact In Practice
The data life cycle and the data analysis process aren't the same thing, but they overlap more than people usually admit. The life cycle is the broader container—acquisition, storage, processing, maintenance, archival, deletion. Analysis is one of those processing stages, though in practice it bleeds into nearly every other phase. You can't design a useful analysis pipeline without understanding where the data came from and where it will go afterward. I spent three weeks last year debugging an analysis that kept producing wildly inconsistent results. The issue wasn't in the model or the query. It turned out the raw data was being ingested from a legacy system that silently dropped nulls during ETL, but the analysis pipeline assumed nulls were present and handled them with imputation. The lifecycle stage—the ingestion and transformation step—had silently altered the data before anyone ever touched it for analysis. The fix was straightforward once I traced it back: I added a checksum comparison between the source export and the ingested dataset to catch silent data loss. That check alone cut false anomalies by about eighty percent on subsequent runs.
Understanding the Relationship Between Data Life Cycle And Data Analysis Process
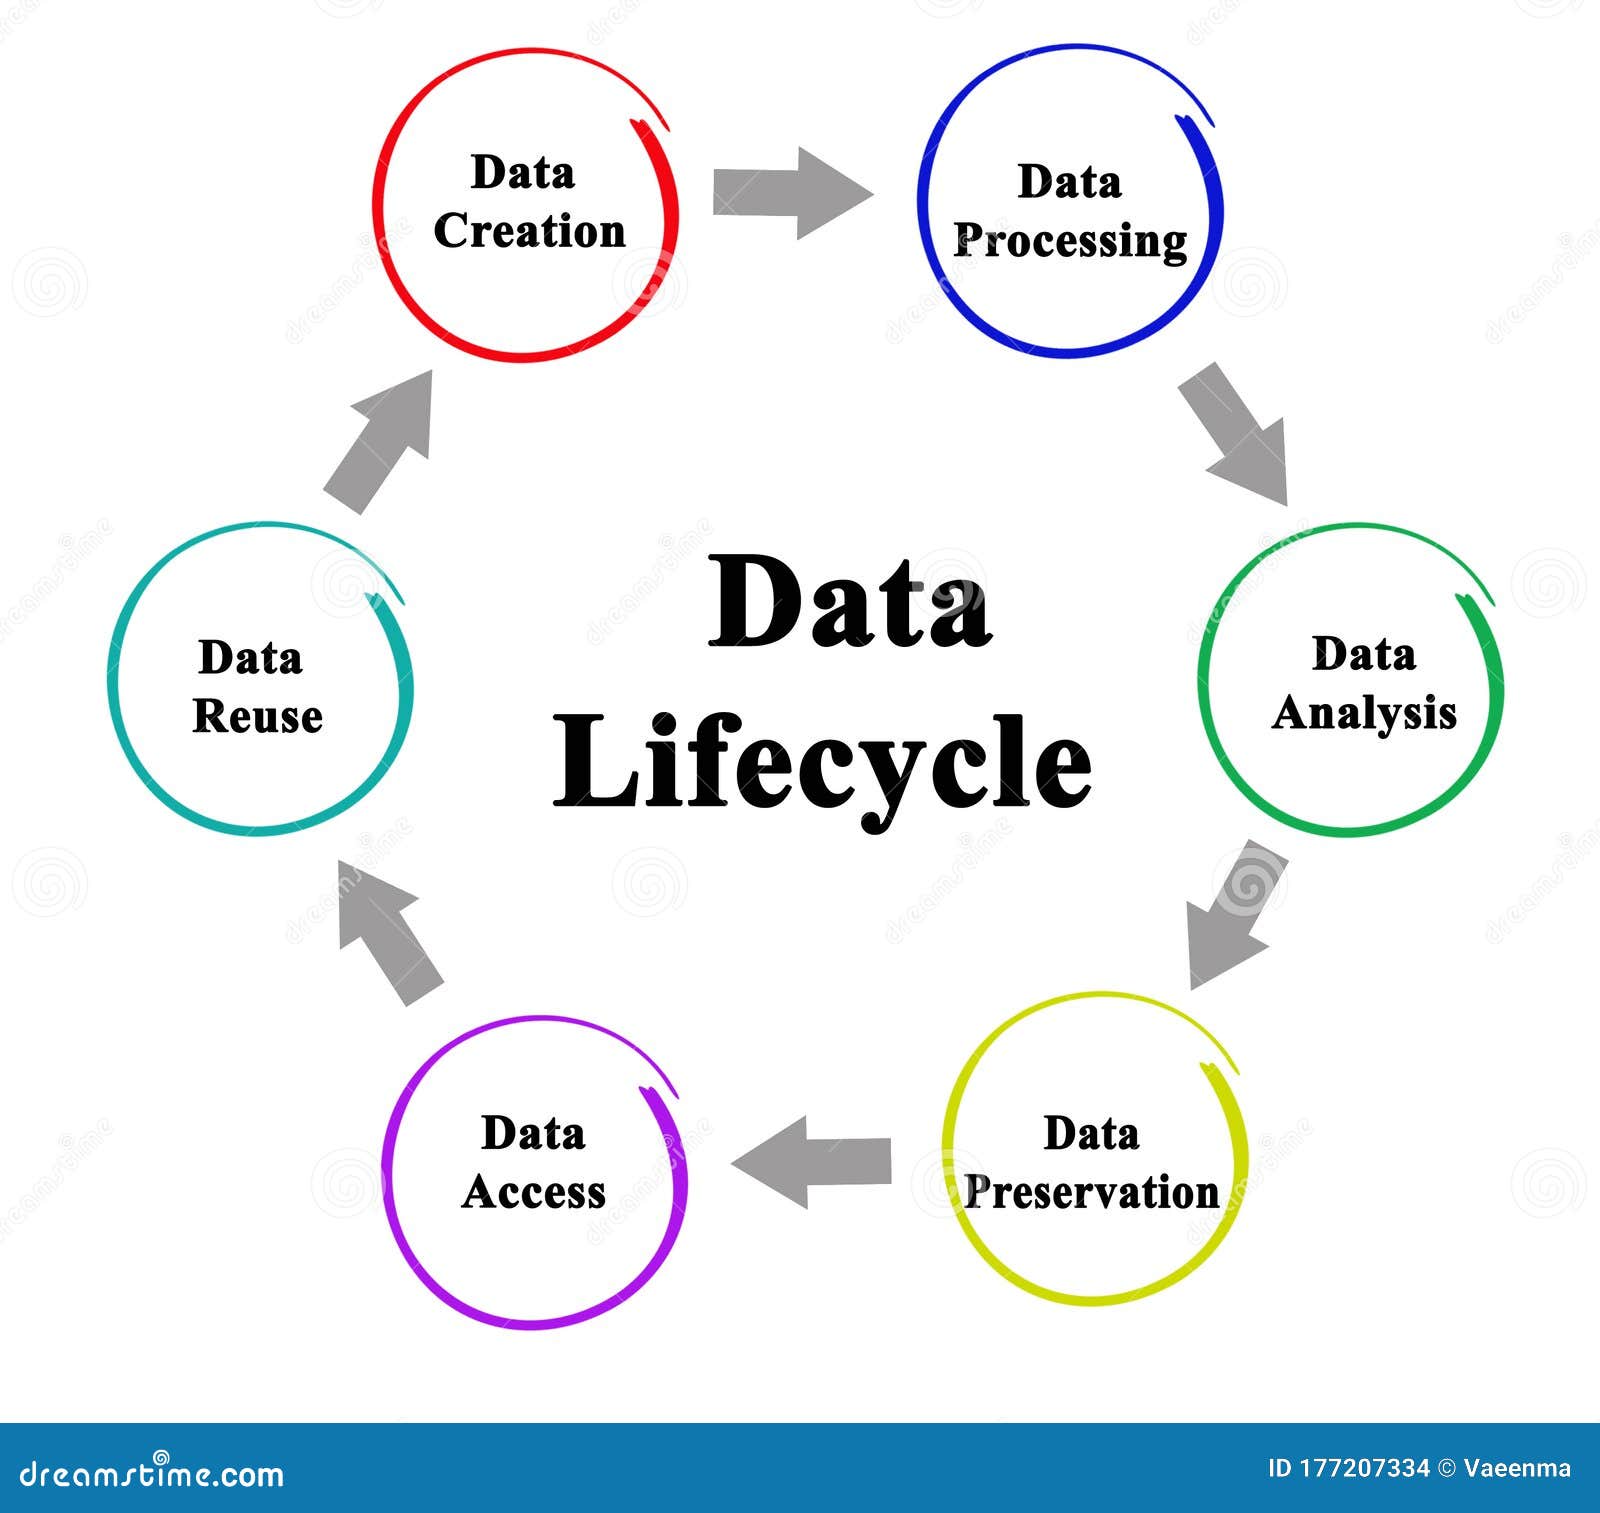
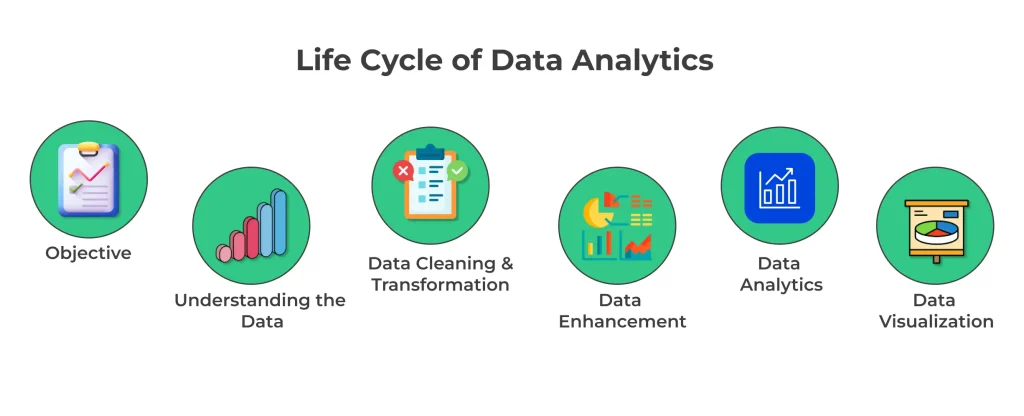
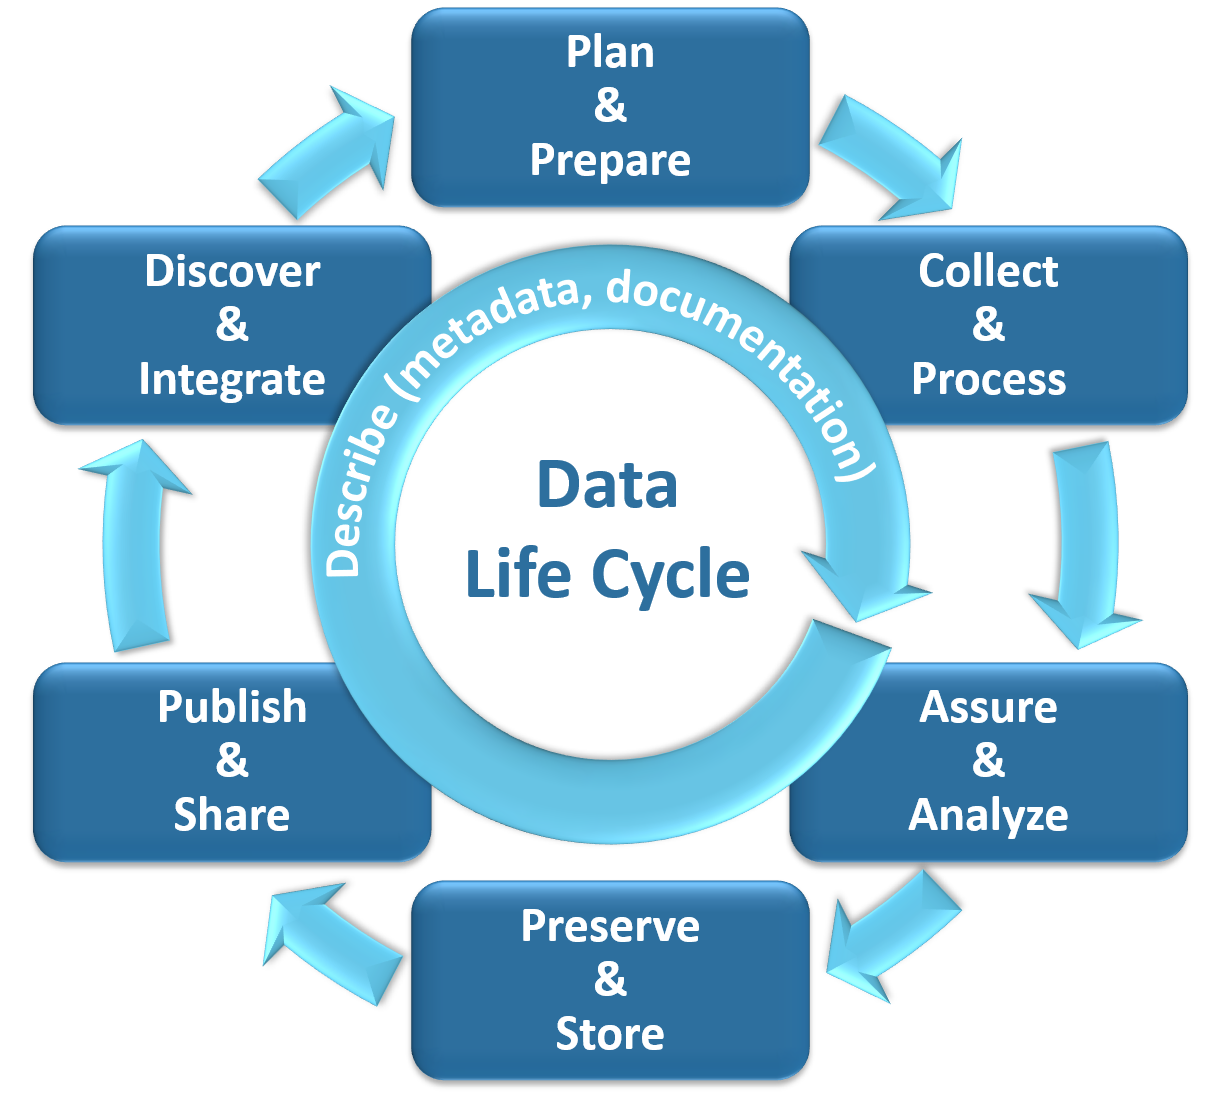
Here is the practical breakdown without the textbook framing. The data life cycle has six recognized stages. Acquisition pulls data in from whatever source you are using. Storage is where it sits, whether that is a data lake, warehouse, or flat files on a disk somewhere. Processing transforms it—cleaning, joining, aggregating. Distribution moves it to where people or systems need it. Archival tucks away the old stuff you don't need day-to-day but might need later. Deletion destroys it when it hits its retention limit or becomes useless. Data analysis sits inside the processing stage but also depends on everything else. Your acquisition methods determine what quality you start with. If the data was ingested poorly, no amount of sophisticated analysis will fix it. Storage structure affects how quickly you can query it and whether you can join datasets efficiently. Distribution dictates who sees what version of the truth, which matters enormously if you are building reports for different stakeholders. Archival and deletion are often overlooked during analysis planning, and they come back to bite you when a regulator asks for records you already purged or when you need historical data that got archived without proper documentation. The counter-intuitive part most people miss is that analysis often feeds back into earlier lifecycle stages. When you analyze data, you generate metadata about data quality, completeness, and usage patterns. That metadata should feed back into your acquisition and storage decisions. I have seen teams run analysis for months, discover systematic gaps in the source data, and then continue running the same flawed pipeline because nobody closed the feedback loop. The lifecycle isn't linear in a real organization. It is a series of loops, and analysis is the point where you mostly see what is broken.
Another thing beginners rarely grasp is that the relationship changes depending on your analysis type. Exploratory analysis tends to operate in a messy loop with the lifecycle—you pull data, look at it, realize you need different data, pull more, repeat. This can take days or weeks and rarely follows any clean procedure. Confirmatory analysis is more rigid. You define your question, extract exactly what you need from the stored data, run the analysis, and move on. Productionized analysis sits somewhere in between, often automated into pipelines where the lifecycle stages are codified into code. That automation is where things tend to break quietly. A pipeline that worked fine on small data will produce garbage when volume increases, and you won't know until someone asks you a question the pipeline can't answer. I used to run analysis workflows on CSV exports from a Salesforce instance. Everything looked fine until our sales team doubled in size mid-year. The pipeline started timing out during the processing stage, and queries that took seconds suddenly took forty-five minutes. The issue was that I had stored intermediate results in temporary tables without partitioning, so every run had to scan the entire dataset again. Moving to a partitioned BigQuery setup reduced query times to under thirty seconds and eliminated the timeout failures entirely. This is the kind of lifecycle decision that makes or breaks analysis at scale, and nobody warns you about it until it happens to you. The main limitation of treating these as connected processes is organizational. Most companies separate the people who manage the data lifecycle from the people who do the analysis. The data engineers own acquisition, storage, and distribution. The analysts own the analysis. They rarely talk to each other. This means analysts build models on data they don't fully understand, and data engineers build pipelines for use cases they didn't anticipate. The workaround is simple but easy to skip: involve the analysis team in lifecycle design decisions and involve the engineering team in analysis review meetings. Even one joint meeting per quarter prevents most of the problems that show up later.
Get the Full Details

There is also a tool-level consideration. Most analytics platforms assume a linear lifecycle because that is how they were designed. You connect to a source, transform, and analyze. But real data doesn't work that way. Data comes from APIs, databases, spreadsheets, manual entry, third-party vendors, and sometimes handwritten notes that someone typed in later. Each source has different retention policies, quality levels, and update frequencies. Building an analysis pipeline that accounts for this variability requires understanding the full lifecycle, not just the processing stage where your analysis lives. If you are starting fresh, map out each stage of the lifecycle for your specific data before you write a single line of analysis code. Identify where each dataset enters, how it is stored, who touches it, and what happens to it after the analysis is complete. Write that down somewhere visible. Then build your analysis around that map, not the other way around. It saves time you won't realize you are wasting until you are three months into a project and wondering why your results don't match what the source system shows.