The thing nobody tells you is that these concepts need to be reframed for qualitative work
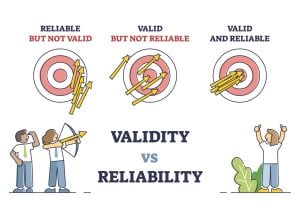
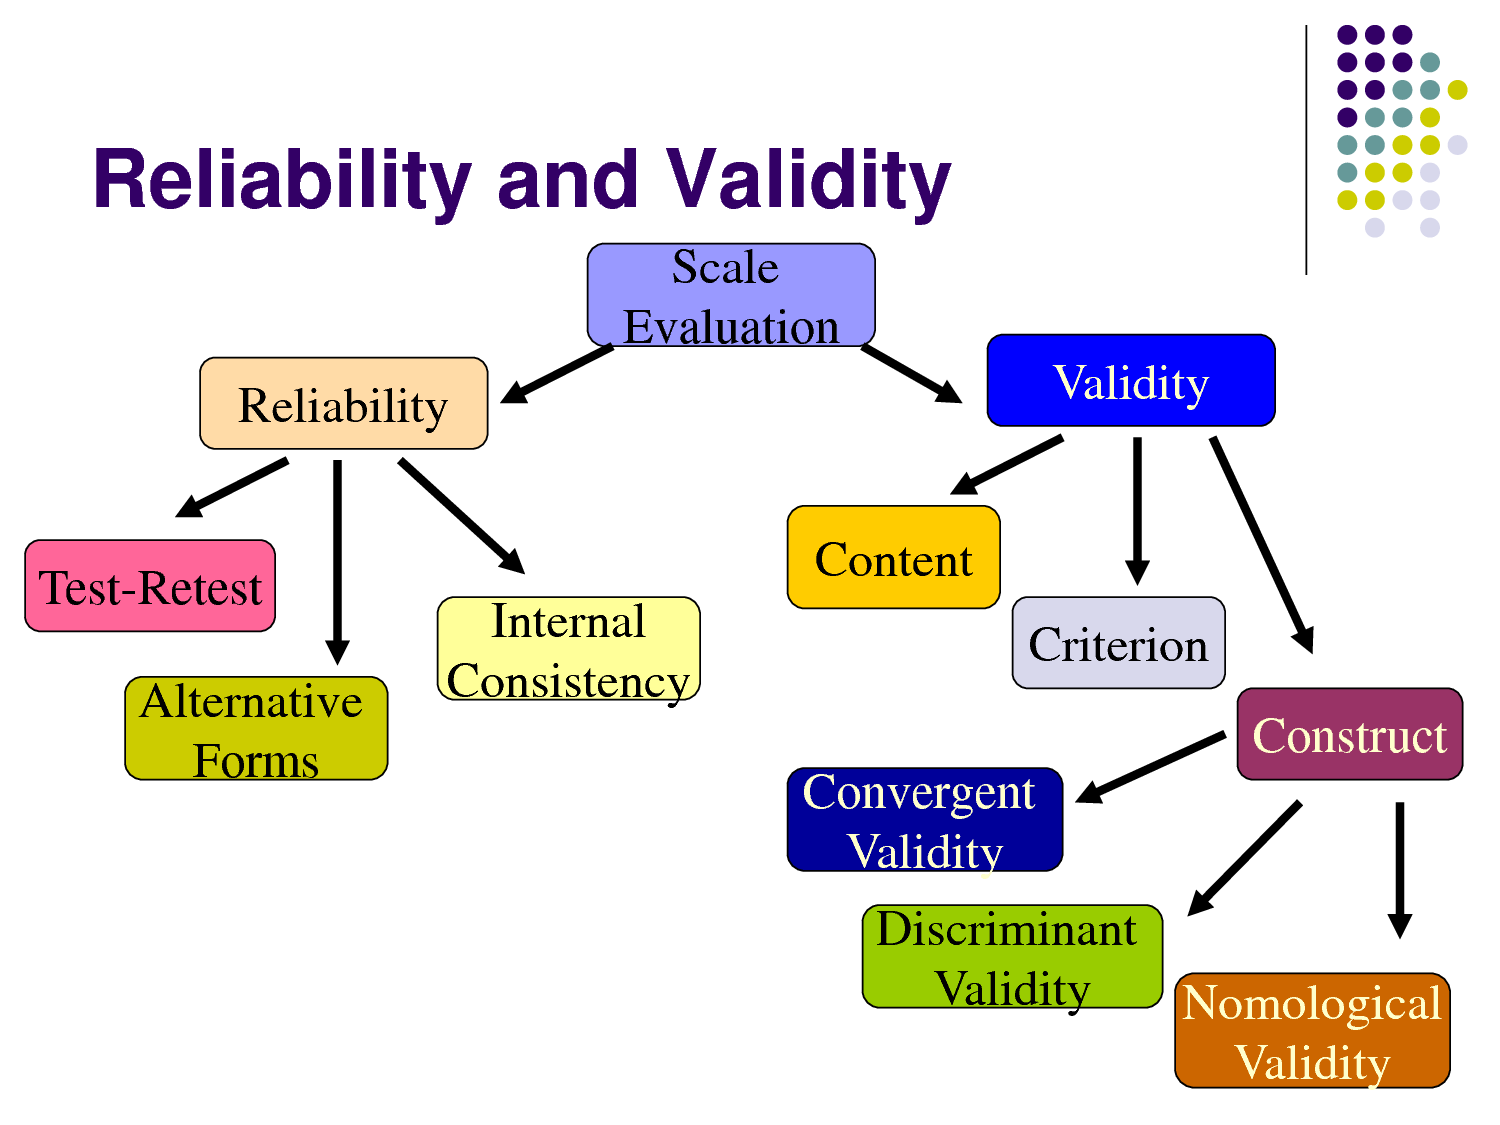
In quantitative research, reliability and validity are straightforward because the numbers either cluster together or they don't. The tests are standardized. With qualitative research, you're working with language, meaning, and interpretation, which makes the whole conversation a lot messier. Most people learning this for the first time try to bolt quantitative criteria onto qualitative data and it breaks the analysis. That's because the framework was never designed for that. Lincoln and Guba basically solved this by proposing trustworthiness as the umbrella term, splitting it into credibility, transferability, dependability, and confirmability. It's not a different answer to the same question. It's answering a different question altogether. Reliability in qualitative terms is usually reframed as dependability. It asks whether the research process is logical, traceable, and documented well enough that another researcher could follow the same path and see the same decisions being made. It doesn't mean you'll get identical results from two different analysts reading the same transcript. That's not the point. The point is that your process is consistent and auditable. Validity becomes credibility. It asks whether your findings actually reflect what the participants meant, not what you hoped they meant. Transferability covers generalizability, meaning the extent to which your thick description allows readers to determine if findings apply to their own contexts. Auditability, or confirmability, is about demonstrating that your conclusions are grounded in the data rather than your own preconceptions. I remember running a study on workplace communication patterns where two of my coders were assigning the same transcript segments to completely different themes. One coder saw a theme around "resistance to change" and the other saw "practical problem-solving." Both interpretations were defensible from the text. The participants themselves had used language that genuinely supported both readings. What I ended up doing was not forcing consensus. I brought in a third coder, ran a code reconciliation session where we went through the disputed segments line by line, and documented exactly why each interpretation held merit. The final codebook included both themes as distinct but related categories with a clear decision rule for when each applied. That whole process took about four hours and it was the most valuable thing in the entire analysis. It forced me to admit that my initial preference for one interpretation over the other was unjustified.
Practical Methods for Establishing Trustworthiness
Member checking is the most commonly recommended technique and it works, but most people use it wrong. They send their finalized findings back to participants and ask if they agree. That's too late. By that point, participants are reading your interpretation, not their own words, and agreement or disagreement with your summary tells you almost nothing about whether your analysis is accurate. The useful version is sending raw quotes and preliminary theme descriptions back to participants while the analysis is still in progress. You're asking them to verify whether the themes resonate with their experience, not whether they like your conclusions. This usually catches misreadings within the first round of checking. I've seen it surface genuine misunderstandings in about sixty percent of cases where I've used this approach properly. Prolonged engagement is another standard technique that gets treated as if spending more time automatically solves everything. Spending three months in a field site instead of three weeks doesn't guarantee credibility if you're not doing the right kind of engagement. The actual value is in building enough rapport that participants stop performing for you and start speaking plainly. It's also about understanding the context well enough to distinguish between behavior that's specific to your presence and behavior that's normal for the setting. A junior researcher I supervised once spent six weeks in a hospital ward and still couldn't tell whether nurses were being particularly terse with her because she was annoying or because she was asking questions at the wrong points in their shift cycle. She needed someone on site to help her read the contextual cues. Triangulation is perhaps the most overused term in this discussion. Using multiple data sources doesn't automatically make your findings more valid. If you interview patients, doctors, and administrators about the same clinical process and they all give you different answers, triangulation hasn't solved anything. It has revealed that the process is experienced differently by different stakeholders, which is itself a finding. The technique only adds credibility when you use it to cross-check specific claims. Did the survey data and the interview data converge on the same pattern? If they diverge, why? Documenting the divergence is more informative than pretending it didn't happen.
The Methods That Actually Work in Practice
Audit trails are not optional paperwork. They are the single most practical tool for establishing dependability and confirmability. An audit trail documents every decision you made during the research process: why you chose certain participants, how you developed your coding scheme, when and how you revised your themes, what you excluded and why. When I ran a qualitative study on organizational culture change, I kept a decision log that tracked every major analytical choice from week one through publication. It took me about twenty minutes per week to maintain. Looking back at it during the revision phase saved me roughly six hours of reconstructing my reasoning from memory. Reviewers who asked for clarification on any analytical decision could be pointed directly at the relevant entry. Peer debriefing involves having someone outside your project review your process and challenge your assumptions. This is different from having a colleague casually read your draft. A proper peer debriefer needs to be familiar with qualitative methodology but not invested in your specific conclusions. They should be pushing back on your interpretive leaps, not just proofreading. I once had a methodologist review my codebook and identify that three of my themes were actually just descriptions of participant demographics in disguise. I had coded "young parent" as a thematic category without realizing it wasn't emerging from the data but from my own sampling frame. That kind of feedback is nearly impossible to get from your advisor, who has already accepted your framework, or from your participants, who don't know what a codebook is. Negative case analysis is the technique most researchers skip because it's uncomfortable. It means actively searching for and accounting for data that contradicts your emerging themes. Every qualitative study has contradictory data. Ignoring it doesn't strengthen your argument. It weakens it. When I was analyzing interviews about technology adoption in small businesses, roughly a third of my participants described using a system in ways that directly contradicted the main pattern I had identified. Instead of treating those as outliers to dismiss, I restructured the analysis to account for a secondary pattern that explained the discrepancy. The revised framework was more complex but significantly more accurate.
Get the Full Details

When These Techniques Fail
There are scenarios where establishing reliability and validity in qualitative research hits real walls. One is when the phenomenon being studied is deeply personal or emotionally charged. Participants may not be able to articulate their own experiences with enough precision for member checking to be meaningful. You can send someone your interpretation of their trauma narrative and they might agree with it politely without it actually being accurate. Another limitation is researcher positionality. No matter how carefully you document your process, your theoretical orientation shapes every analytical decision. A researcher trained in grounded theory will produce a different analysis than one trained in thematic analysis reading the exact same data. Neither is wrong. Both are shaped by their training. The audit trail makes this visible, but it doesn't resolve it. Small sample sizes create a particular problem. With fewer participants, there's less data to triangulate against and less opportunity to identify contradictory cases. This doesn't mean small studies are worthless. It means the claims you can make are narrower and the trustworthiness techniques need to be applied more rigorously. Inter-rater reliability calculations are sometimes suggested for qualitative work but they rarely help. When two coders disagree on qualitative data, the disagreement usually reveals something substantive about the data itself rather than indicating coder error. Forcing agreement through statistical measures often flattens nuance that was the whole point of doing qualitative research in the first place. The biggest practical bottleneck is time. Every trustworthiness technique I mentioned adds to your timeline. Member checking rounds take weeks. Audit trails require constant documentation. Peer debriefing requires finding and scheduling someone qualified. Negative case analysis slows your coding process because you have to repeatedly test your themes against disconfirming evidence. A typical qualitative analysis might take six to eight weeks without these additions. With them properly implemented, plan for ten to fourteen weeks minimum. There's no shortcut that maintains the same level of rigor.
If your research is constrained by a tight deadline or limited funding, the most honest approach is to be transparent about which trustworthiness techniques you were able to implement and which you had to defer. That disclosure strengthens your study more than claiming full rigor while cutting corners. Reviewers can usually tell the difference.