Getting your study off the ground without losing your mind
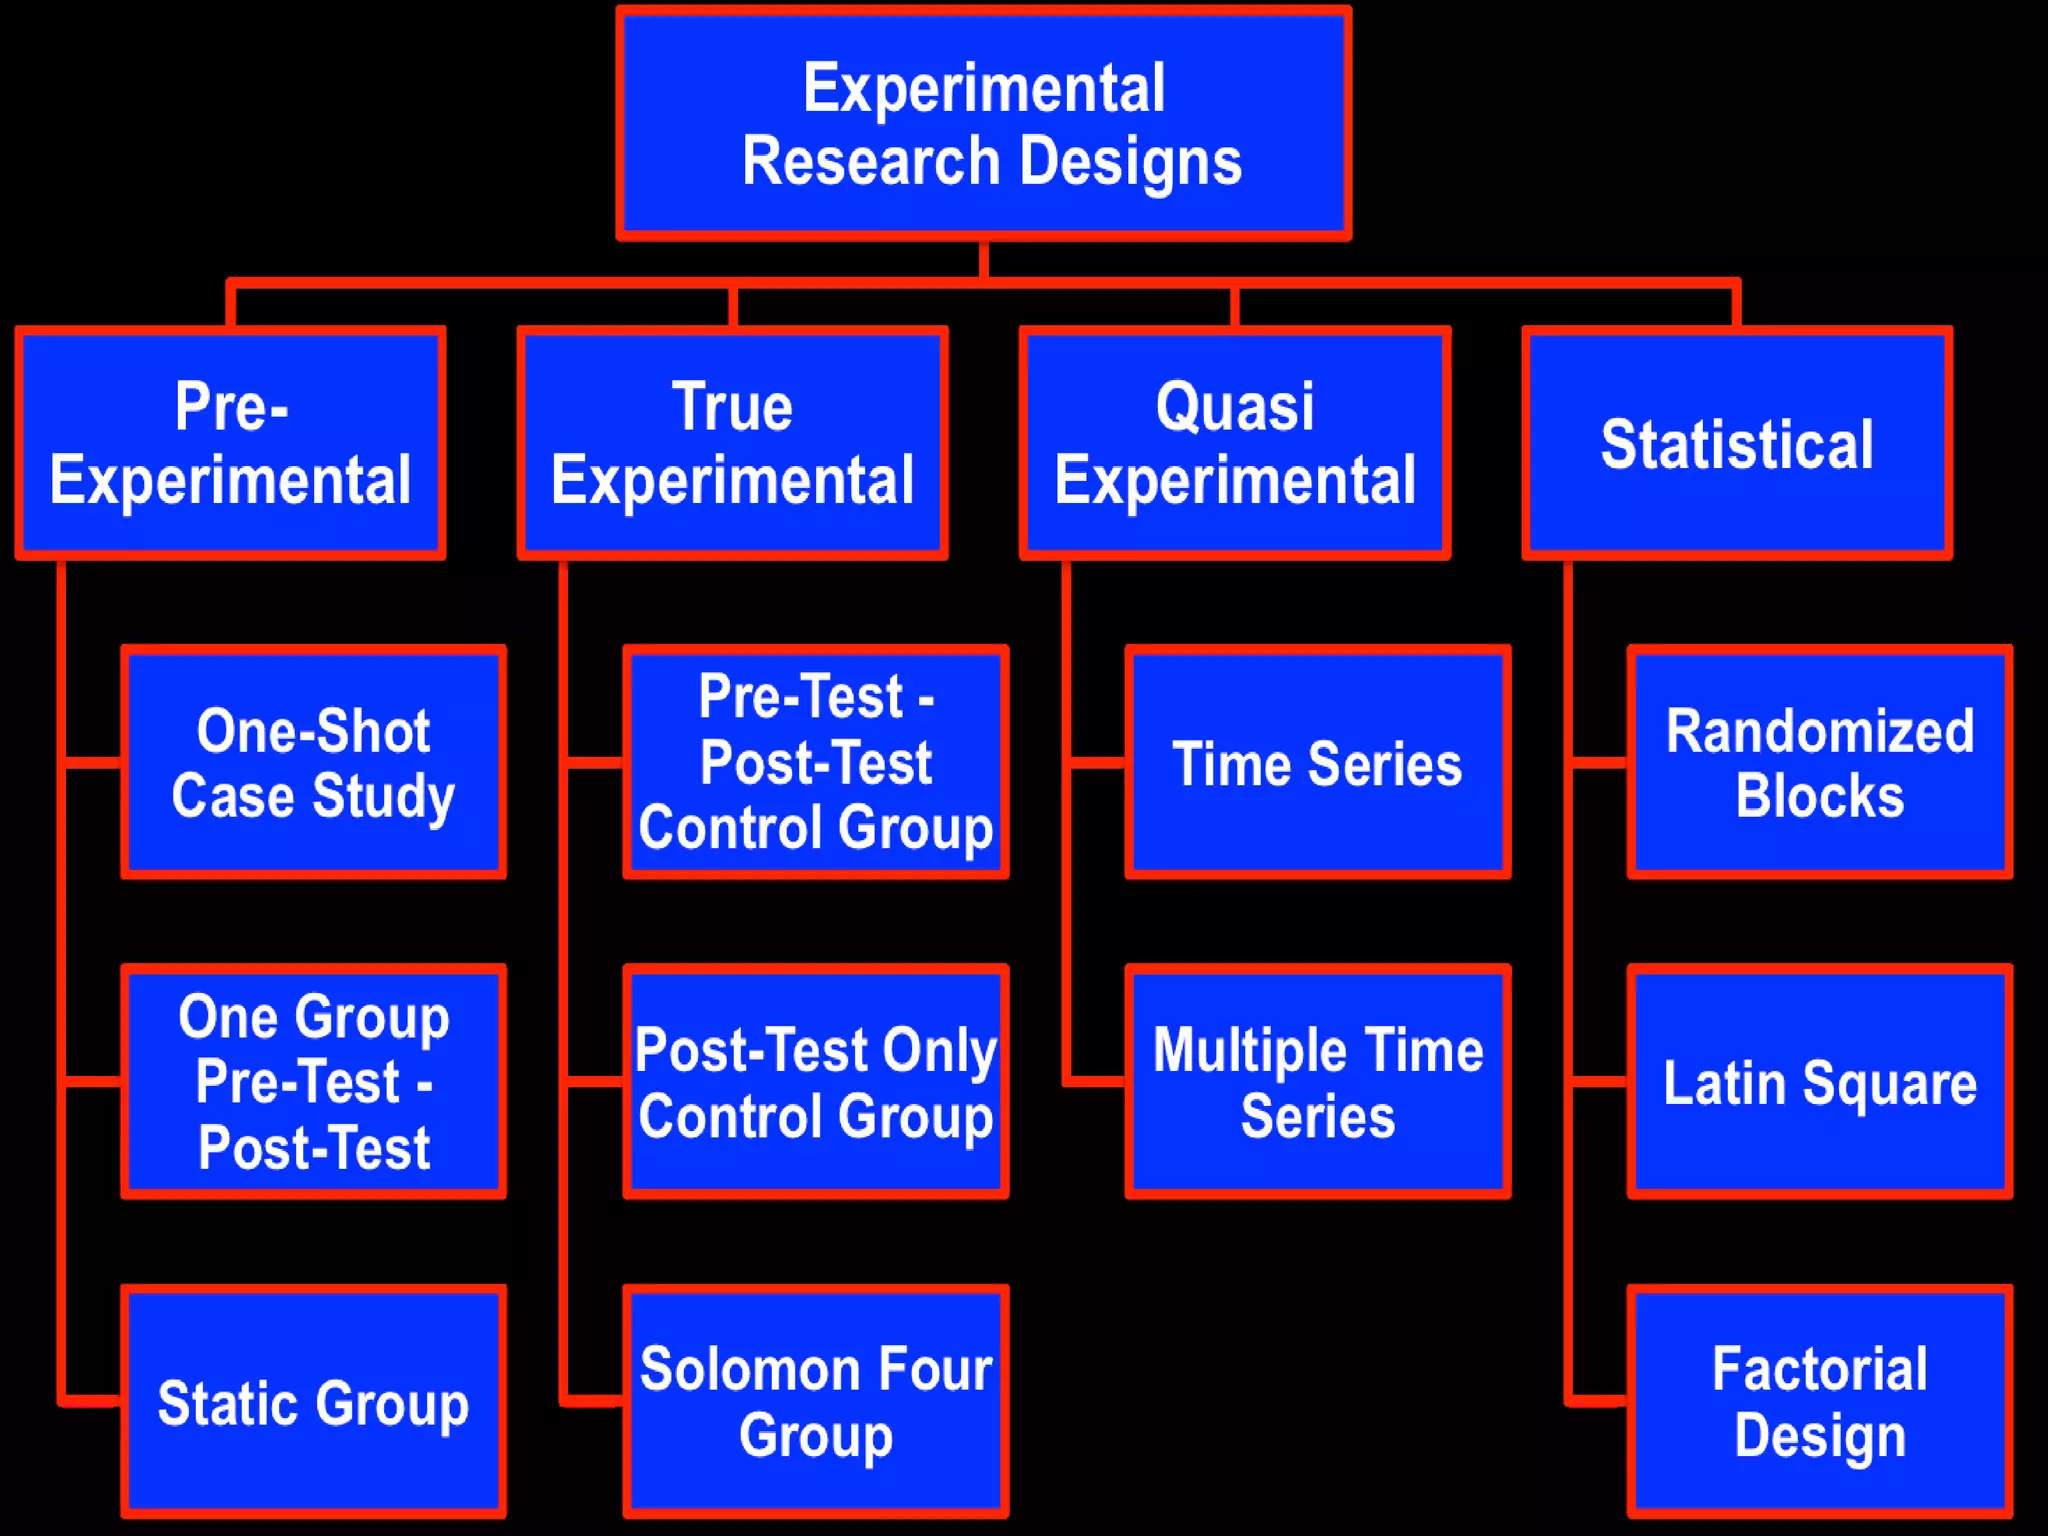
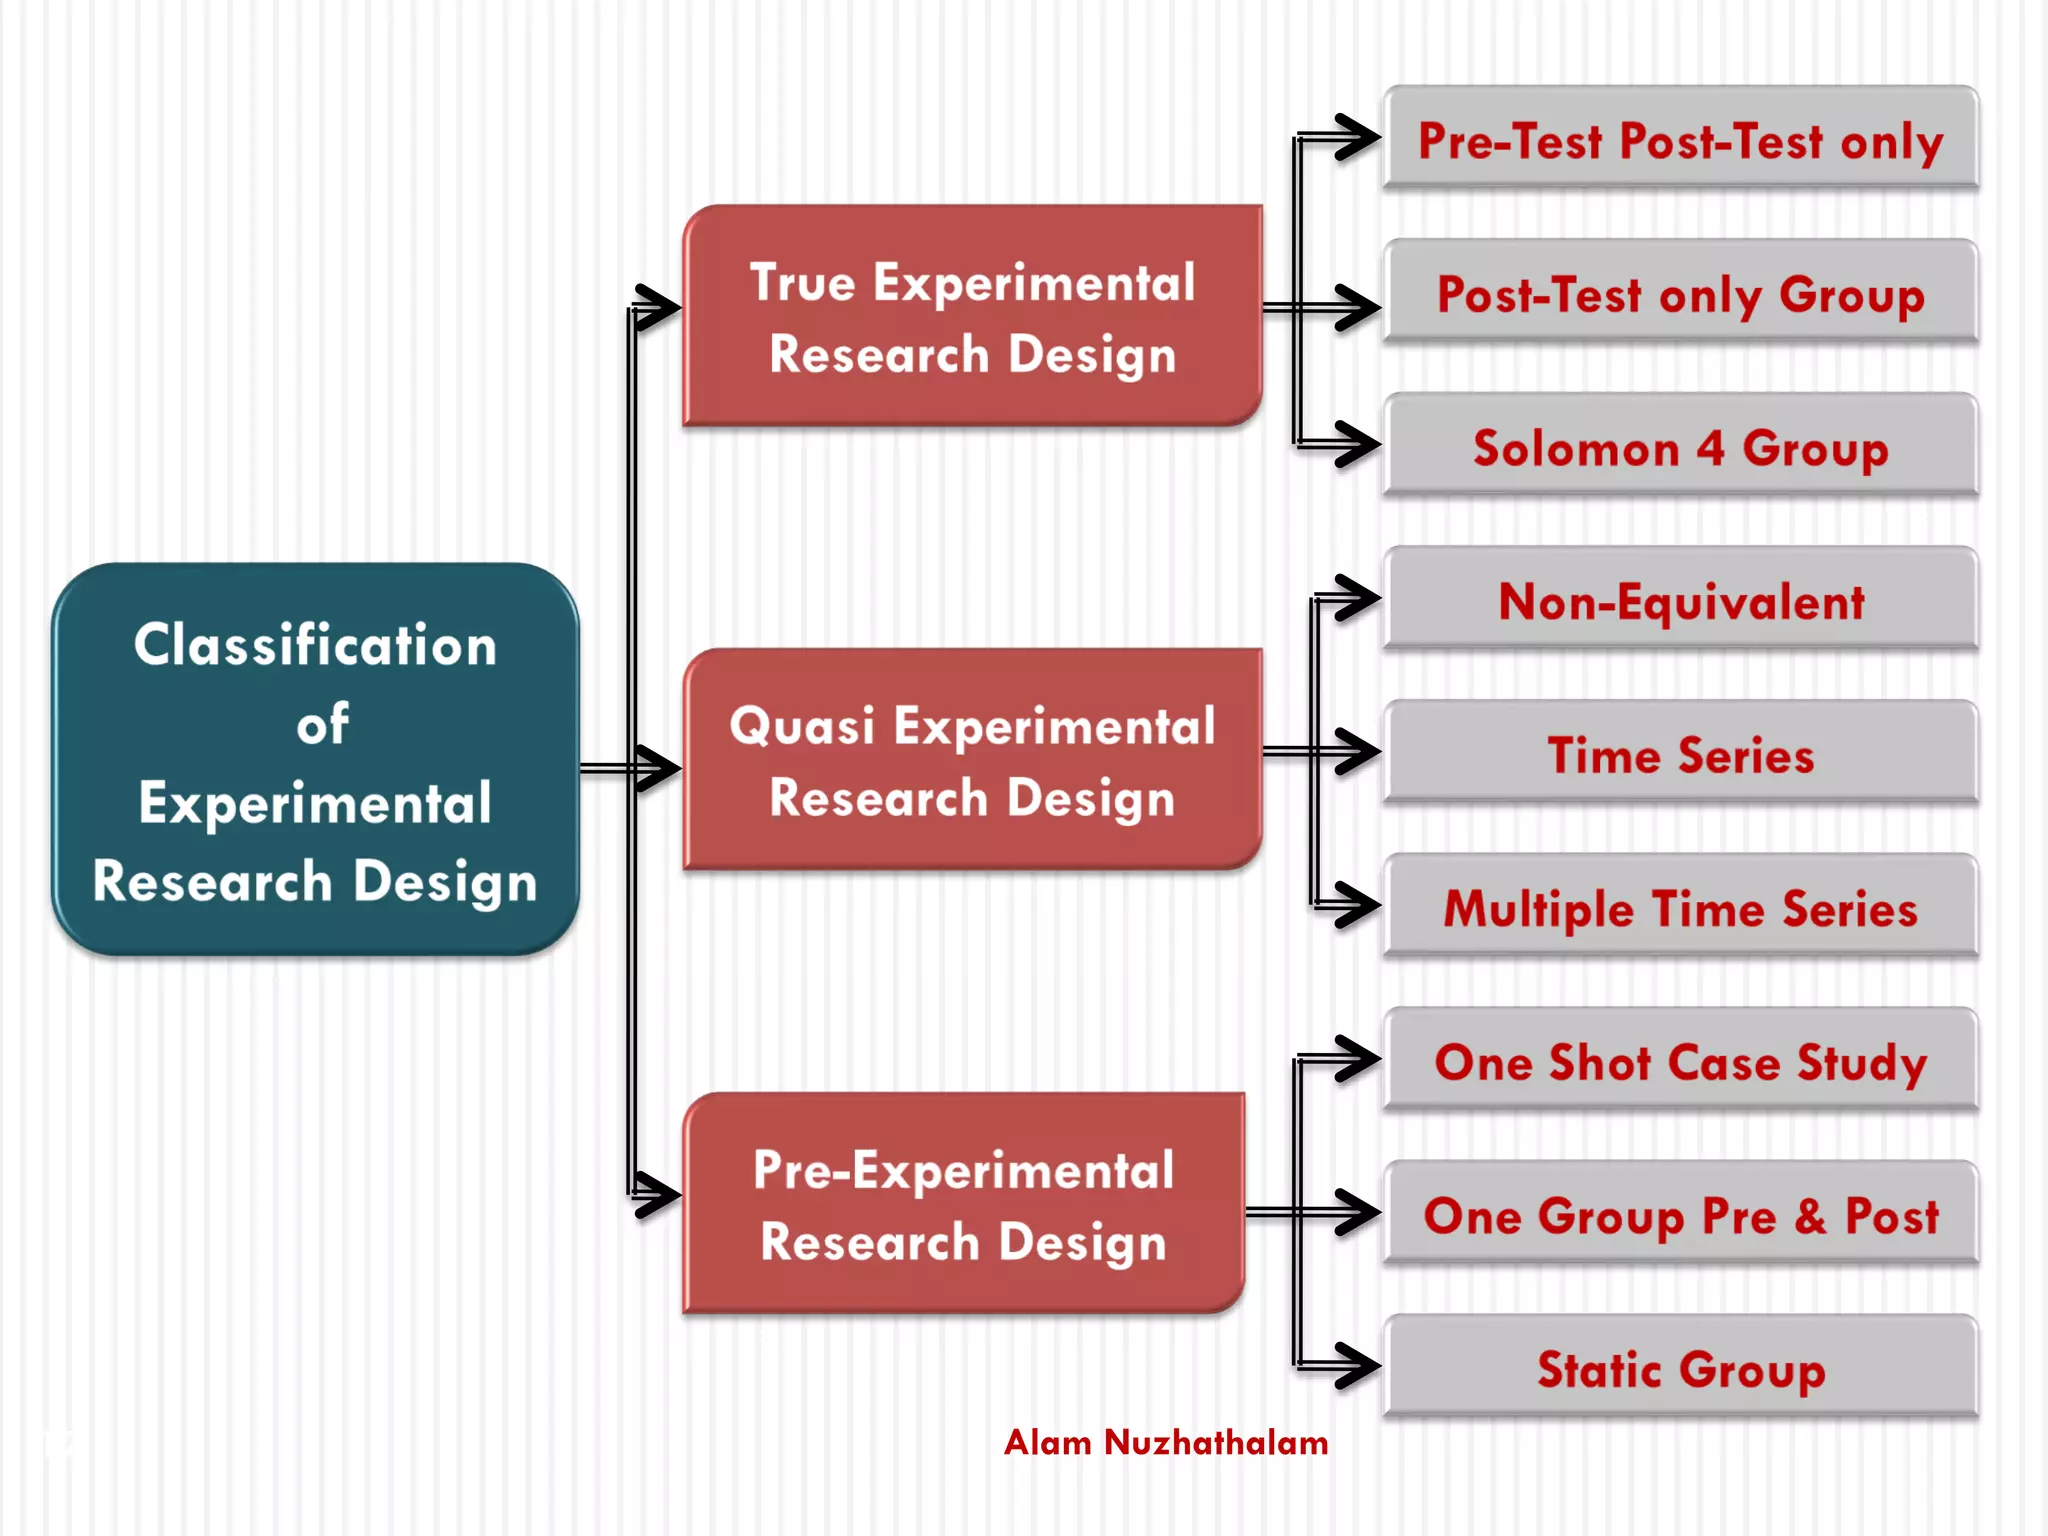
Most people jump straight into picking a method. That is usually where things go wrong. You need to think about the whole structure first. Research Design And Experimental Design are often lumped together, but they are not the same thing. The research design is the blueprint. It tells you what question you are answering, what units you are studying, and how you will collect data. The experimental design is a subset of that. It is the actual manipulation of variables, random assignment, control groups, and the mechanics of the intervention itself. I have seen plenty of proposals get torn apart by reviewers because the researcher confused the two. They wrote a whole experimental design chapter when the real issue was that their research design had no clear unit of analysis. Once I make that distinction, things get a lot simpler.
How to build it out properly
Start with the question. Not the method, not the tools. The question. If you cannot write it in one sentence without using jargon, you do not have a question yet. Write it down. Then figure out what kind of data would actually answer it. After that, you pick your design. The design follows the question, not the other way around. When you move into the experimental portion, you need to nail down three things. The independent variable, the dependent variable, and the confounding variables you need to control. Write them all out before you recruit a single participant. I spent two weeks once running a pilot because I forgot to account for time of day as a confounder. Half my subjects were tested in the morning, half in the afternoon. The results were garbage. I had to scrap the whole thing. After that, I always write down the time window for testing as a controlled variable, even if it seems obvious.
Common mistakes that waste months
Here is one thing most people miss. They assume random assignment eliminates all bias. It does not. Random assignment balances groups on average, but it does not fix measurement error, attrition, or instrument drift. If your measurement tool is noisy, no amount of randomization will save you. I once worked on a study where we had perfect randomization but our survey instrument had a ceiling effect. We could not detect any difference between groups because everyone scored at the top. We caught it during the pilot phase, but we lost six weeks fixing the instrument. Always run a small pilot before you commit resources. Another pitfall is confusing statistical significance with practical significance. A large sample size can make a trivial effect look significant. A small effect with a p-value under .05 is still a small effect. Report effect sizes. Report confidence intervals. The numbers will tell you more than the binary yes-or-no of significance testing.
Get the Full Details

What works in practice
For a typical controlled experiment, here is the sequence I use. Define the hypothesis. Identify the variables. Select the population. Determine the sampling method. Choose the design type. Run a pilot. Refine the instrument. Collect data. Analyze. Write it up. The pilot is non-negotiable. Skip it and you are gambling with your entire dataset. A pilot usually takes two to three days for a modest study. It can save you two months of rework. If you are working with limited resources, a within-subjects design gives you more power than a between-subjects design with the same sample size. The trade-off is carryover effects. Practice effects, fatigue, order effects. Counterbalancing fixes some of that, but not all of it. I use a Latin square when I have more than two conditions and cannot afford the sample size of a between-subjects design. It is a bit more work to set up, but it is far more efficient than recruiting twice as many people. One edge case that trips people up is cluster randomized trials. When you randomize by group instead of by individual, you lose statistical power. The intra-class correlation matters. If you ignore it, your standard errors are wrong and your p-values are inflated. I always calculate the design effect before I finalize the sample size. It adds maybe ten minutes to the planning phase and prevents you from being underpowered by a third.
Downsides and when to pivot
Experimental designs are not always feasible. Sometimes you cannot randomize. Sometimes the intervention is too costly or too slow. In those cases, a quasi-experimental design might be your only option. Difference-in-differences, regression discontinuity, instrumental variables. These are not inferior because they are less fancy. They are inferior because they make stronger assumptions, and those assumptions are often untestable. Be honest about which assumptions you are making and why you think they hold. If your study involves human subjects, you also need to think about IRB approval. That process can take anywhere from two weeks to three months depending on your institution. Plan for it. Do not submit your methods before you know the approval timeline. The tools are straightforward. G*Power for sample size calculation. R or Python for analysis. Qualtrics or similar for survey deployment. No special software is required beyond that. The hard part is thinking clearly about what you are trying to learn and designing the study so the data you collect can actually answer the question.