Why Most Psychology Experiments Fail Before You Even Collect Data
I spent three days last month untangling a mess caused by not randomizing participants properly. Three days of cleaning code, re-running analyses, and explaining to my advisor why the original results were garbage. It happens all the time. The difference between a clean study and a dead end is almost always in the method, not in how clever your statistical model is. The core issue is that psychology research sits in a weird middle ground. You can't control every variable like a physicist, but you also can't just observe behavior the way an anthropologist does. You have to design an artificial situation, predict what will change people's responses, and then figure out whether that predicted change actually happened. That process is what constitutes the research method in psychology, and it's where most students and even some experienced researchers make costly mistakes.
The Research Method In Psychology: What It Actually Looks Like
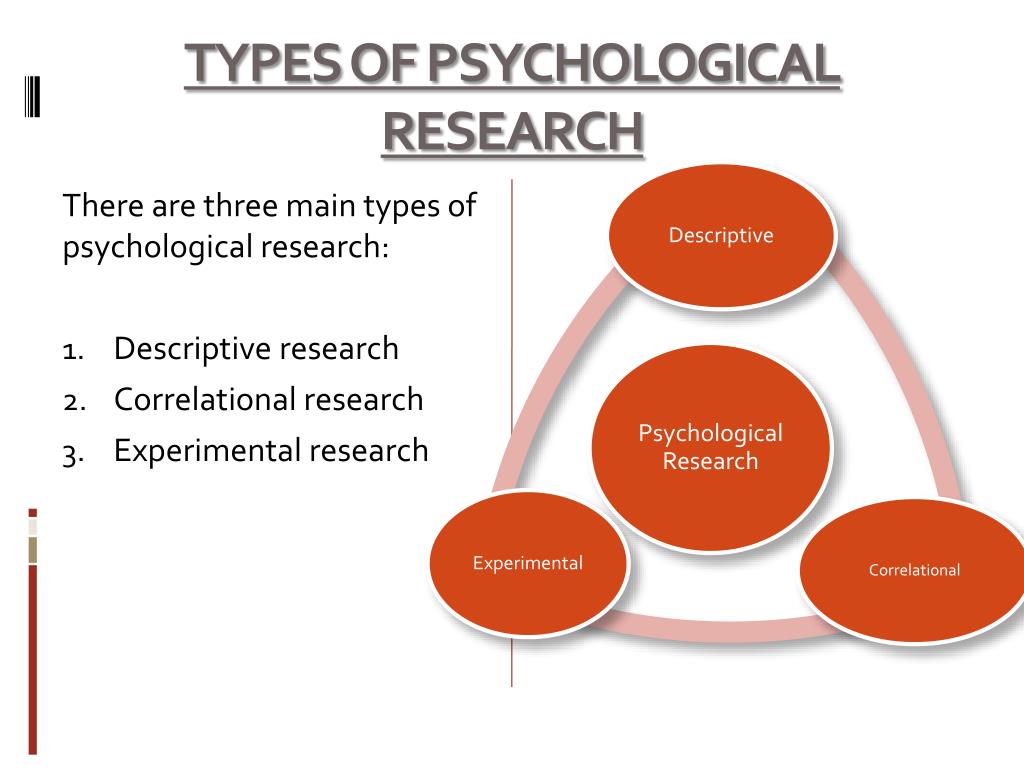
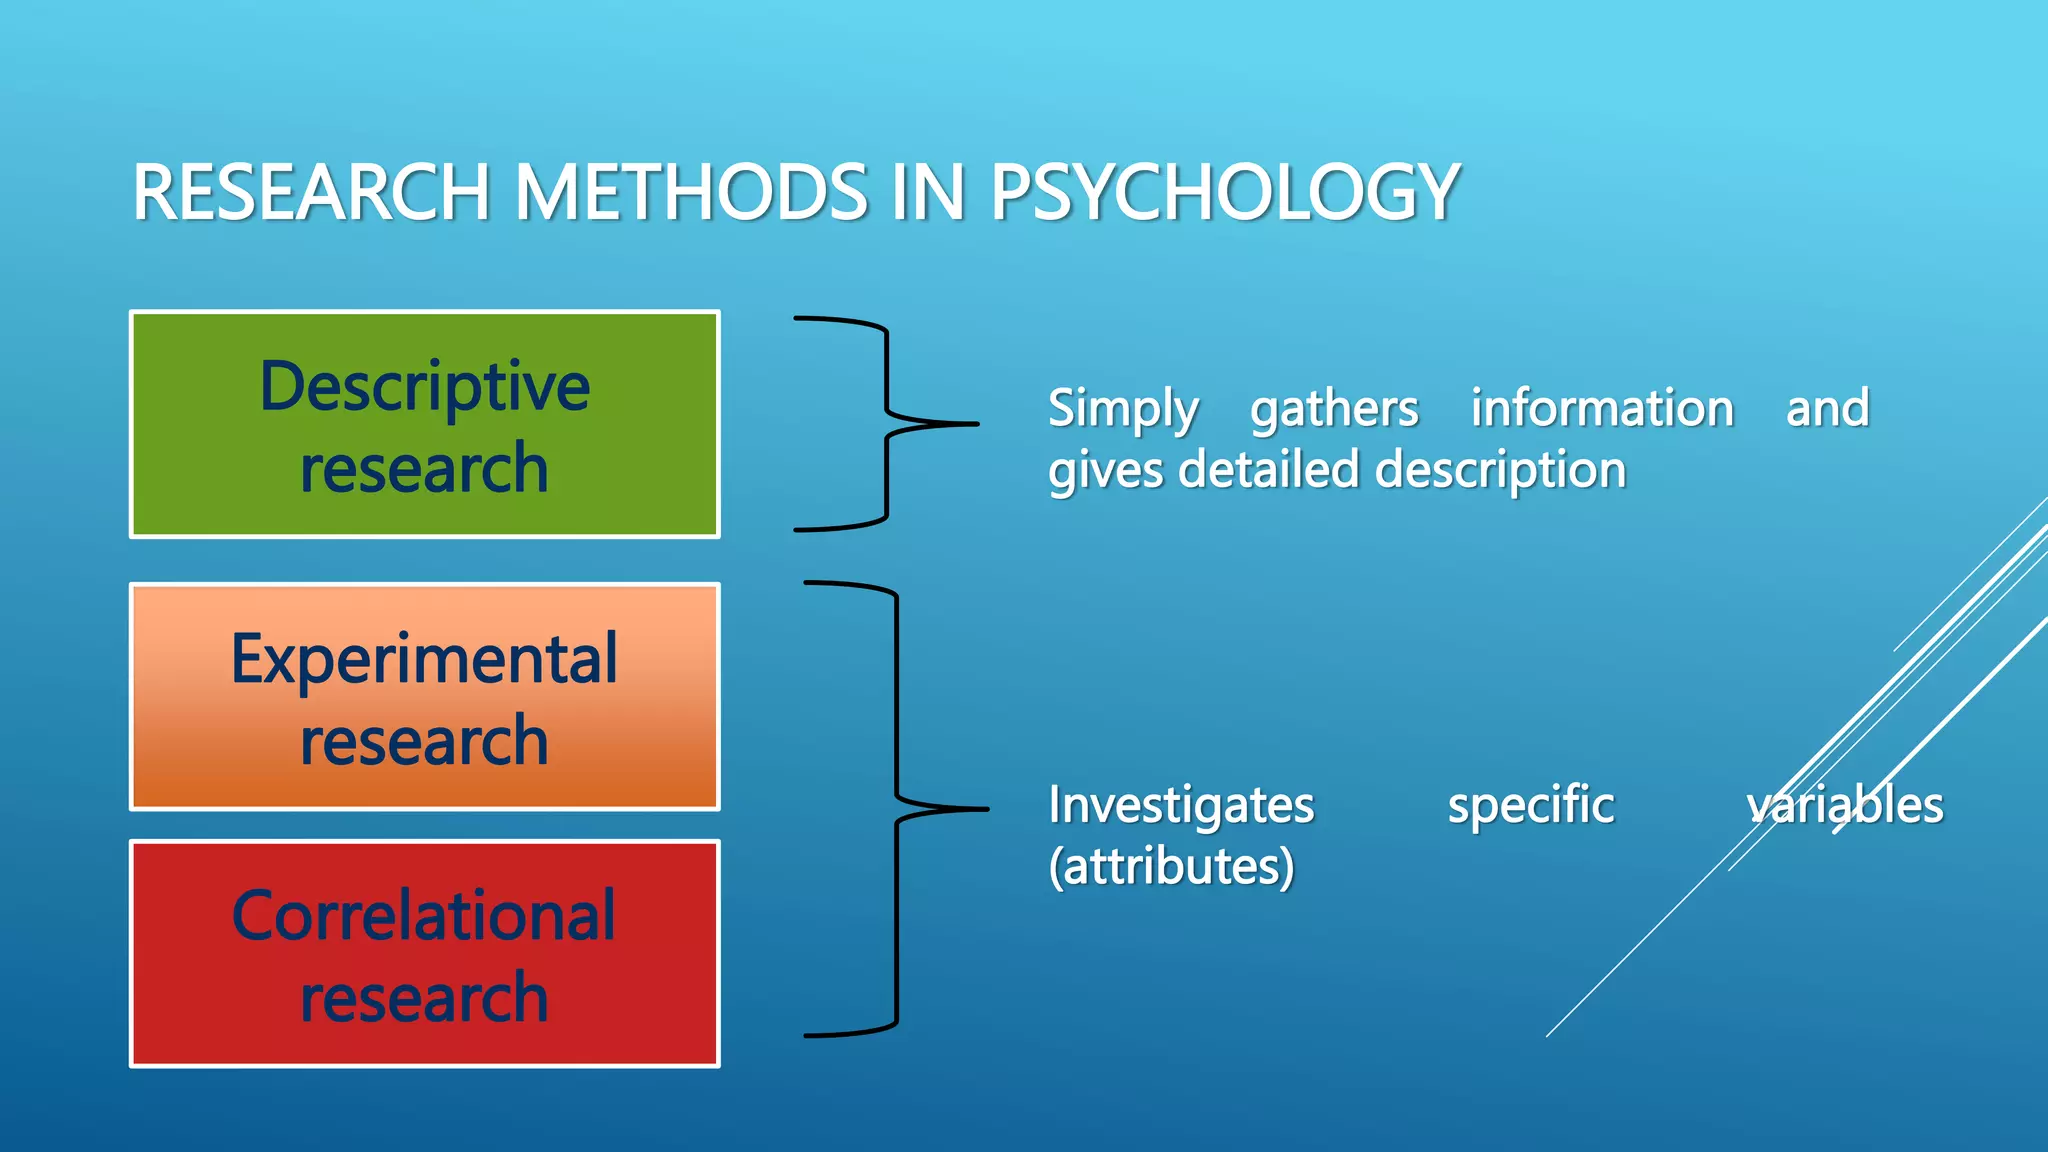
It starts with identifying a question that hasn't been answered cleanly. Not a broad philosophical question, but something testable. Does sleep quality affect short-term memory recall in college students? That's testable. Is life meaningful? That's not, at least not in any way your statistical software can handle. Once you have the question, you pick a design. The standard ones you'll encounter are experiments, correlational studies, longitudinal designs, and qualitative approaches. Each has real tradeoffs that matter far more than what any textbook says. Experiments give you causal claims, but only if you can properly control confounds. A between-subjects design means you need enough participants to detect a meaningful effect, which typically runs 64 to 128 per group for medium effect sizes. If you're working with a clinical population or hard-to-recruit subjects, that number might be impossible. I ran into this when studying trauma responses in veterans. We needed 80 participants per condition for adequate power, but recruitment took eight months and we only got 34. The study was published, but the confidence intervals were wide and the conclusions weak.
Correlational designs are easier to run. You measure two variables and see if they move together. The trap here is everyone knows you can't infer causation from correlation, but nobody warns you about how often intermediate variables silently break your model. If you find that social media use correlates with anxiety in teenagers, you still have to figure out whether social media causes anxiety, anxious teens use social media more, or a third factor like family conflict drives both. I usually add a screening survey and collect demographic and environmental data upfront so I can at least check for these alternatives later. Longitudinal studies sound ideal because they track change over time. They're also expensive and prone to attrition that introduces its own bias. People who drop out aren't random. They're often the most stressed, the least engaged, or the ones your intervention affected the most. If you lose 40 percent of your sample and the dropouts differ systematically from completers, your remaining data tells a different story than the one you thought you were studying.
Get the Full Details
.webp)
Building a Study That Won't Collapse Under Its Own Weight
Start with a power analysis. Not the rough one you do in your head. Run it in G*Power or R with realistic effect size estimates from the literature. If no prior study exists, use a small meta-analysis or conservative estimates. I once designed a study based on an optimistic effect size of d = 0.8 and ended up with zero statistical power. The result was a null finding that wasn't actually null, just underpowered. I wasted six months of work on it. Write your hypothesis before you collect a single data point. Pre-registration has become standard practice now, and it should be. Journals increasingly expect it, and it stops you from fishing through your data until you find something significant. When I first started pre-registering, I thought it was just bureaucratic overhead. After seeing how many of my own instincts would have led me to exclude outliers perversely, I became a convert. Your measurement tools need validation before you deploy them. If you're adapting an existing scale, check the internal consistency in your population. Cronbach's alpha below 0.7 is a red flag. If you're creating a new measure, run exploratory factor analysis on a pilot sample first. I learned this the hard way when I used a translated version of a well-known personality inventory without checking whether the factor structure held in the target language. The results looked clean until I ran the EFA and discovered the items loaded onto completely different factors than intended.
Randomization isn't optional. Consecutive assignment, alternating by birthday, or letting participants choose their condition all introduce selection bias that contaminates your groups. I use block randomization with concealed allocation, preferably through a web-based system like Random.org or a dedicated tool like Research Randomizer. It takes maybe two minutes to set up and saves you from having to explain away group differences during analysis. Blinding matters more than people admit. Single-blind is standard in psychology, meaning participants don't know their group assignment. Double-blind is harder to achieve but worth pursuing when possible, especially in intervention studies. The experimenter's expectations can subtly influence participant behavior through tone, timing, or body language. I've seen it happen repeatedly, and it's nearly invisible to anyone not actively watching for it.
Common Pitfalls That Waste Weeks of Work
Not accounting for multiple comparisons is the most common statistical mistake I see. Every additional test increases your family-wise error rate. If you run 20 comparisons at p = 0.05, you should expect one false positive by chance alone. Bonferroni correction is conservative but safe. The Benjamini-Hochberg procedure controls false discovery rate and is often more appropriate for exploratory work. Pick one and justify it in your methods section. Ignoring assumption violations in your statistical tests is another habitual problem. Normality, homogeneity of variance, independence of observations. ANOVA assumes all three. If your data violate them, you either transform the data, switch to a nonparametric alternative, or use robust regression methods. I recently analyzed reaction time data that was heavily right-skewed. Log transformation fixed the distribution, and the results stayed consistent with the original untransformed analysis, but the assumptions were now satisfied and the model diagnostics looked normal. Small sample sizes that produce underpowered studies are perhaps the single biggest structural problem in psychology research. The replication crisis was largely driven by this. Most published studies in the field have less than 80 percent power, meaning there's a significant chance that a statistically significant result is a false positive. This isn't a failure of individual researchers. It's a system that rewards novelty and significance over precision and replication.
Data peeking during analysis inflates false positive rates dramatically. Checking your results after every participant and deciding to stop when you reach significance is essentially p-hacking with extra steps. You should collect your full sample before looking at the data, or use sequential analysis methods that account for interim looks.
A Practical Walkthrough of a Standard Experimental Design
Here's what a typical experiment looks like from start to finish. Let's say you're testing whether brief mindfulness practice improves attention compared to a control activity. You recruit 120 participants through a university subject pool. You confirm the sample size gives you 80 percent power to detect a medium effect using a prior meta-analysis showing d = 0.55 for mindfulness interventions on attention tasks. You randomly assign them to either the mindfulness or control group using block randomization with blocks of four to ensure balance. The mindfulness group completes a five-minute guided breathing exercise. The control group reads a neutral article for the same duration. Both groups then complete the Attention Network Test, which measures alerting, orienting, and executive control. The test is computerized and auto-scores, which eliminates scorer bias entirely. The person administering the study doesn't know which condition participants are in, so you're double-blind at the point of data collection.
You collect demographic information and a brief screening questionnaire beforehand to check that your randomization actually produced comparable groups. Age, gender, prior meditation experience, caffeine consumption within two hours of the session. If the groups differ on any of these, you include them as covariates in your analysis rather than trying to fix the imbalance post hoc. After data collection, you run your analysis plan exactly as pre-registered. Primary outcome is the executive control component of the ANT. You check assumptions, run an independent samples t-test or ANOVA depending on whether you're including covariates, and report effect sizes with confidence intervals. You don't look at secondary outcomes first and then decide whether to report them. That's post-hoc reasoning dressed up as discovery. This whole process from design to analysis report usually takes about three weeks for a straightforward experiment like this. The data collection itself is four to five days. Analysis and writeup take another week. The rest is IRB approval, recruitment, and managing unexpected delays like no-shows or technical problems with the test software.
.webp)
Qualitative Methods Deserve Equal Respect
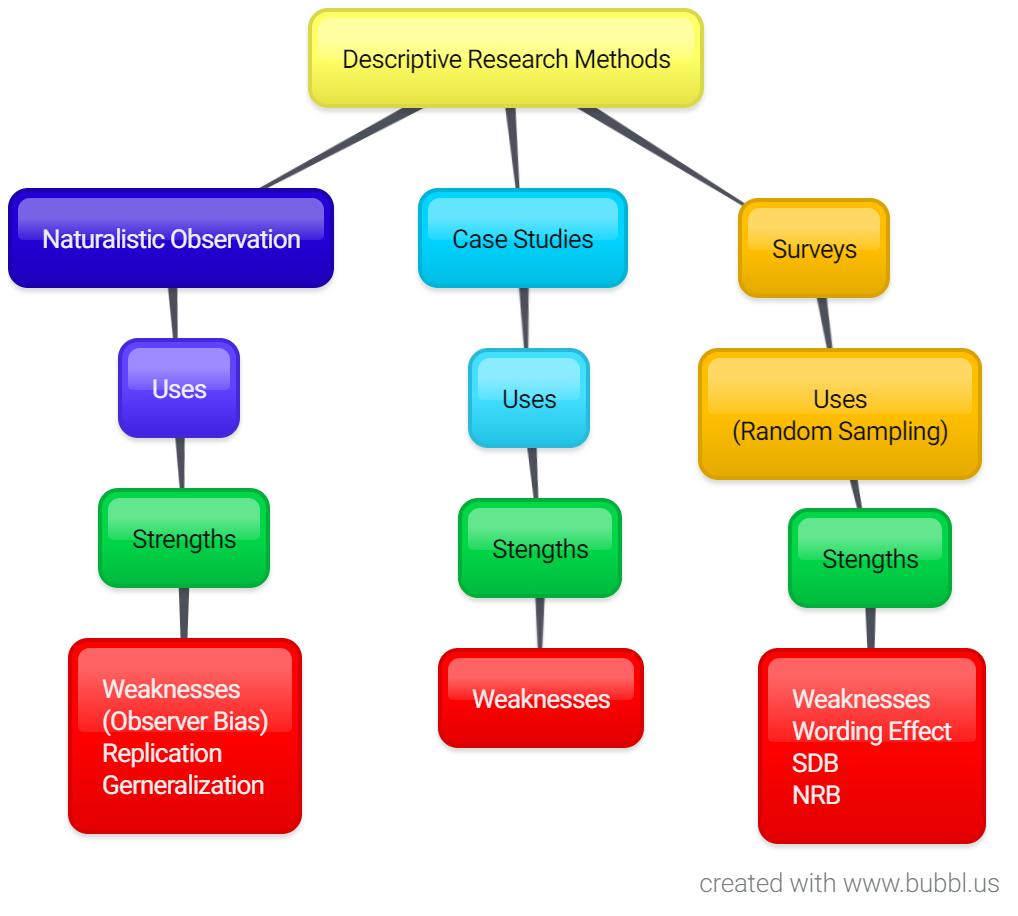
Quantitative approaches dominate psychology departments, but qualitative research methods serve a different purpose and are often the right tool for the job. If you're exploring a phenomenon that hasn't been studied, understanding subjective experience, or examining cultural context, structured surveys and experiments will miss the actual texture of what you're investigating. Thematic analysis is the most accessible entry point. You conduct interviews or focus groups, transcribe them, and code for recurring patterns. Braun and Clarke's six-phase framework is the standard reference. It's not as rigorous as some people claim, but it does require discipline. You need to document your coding decisions, maintain an audit trail, and be willing to revise your themes when the data pushes back against your initial categories. Grounded theory is more demanding. You collect and analyze data simultaneously, letting categories emerge rather than testing pre-existing hypotheses. This is valuable when you're building theory from scratch, but it requires significant time and iterative refinement. A typical grounded theory study might involve 20 to 30 interviews and multiple rounds of coding before saturation is reached.
The limitation of qualitative work is generalizability. Your findings apply to the specific context and participants you studied. That's not a flaw. It's a feature. Qualitative research answers different questions than quantitative research. Expecting it to generalize is like expecting a microscope to measure distance. Wrong tool for the job.
What No One Tells You About Running Studies
Participant dropout is inevitable. Plan for it. If your power analysis says you need 100 people, recruit 115 to 120. Attrition rates of 10 to 20 percent are normal in most psychology studies. In online studies they're often higher because there's no personal relationship between researcher and participant to motivate completion. Incentives matter more than ethics boards usually consider. Paying participants fairly affects who shows up and how seriously they engage. I stopped using course credit as the sole incentive after noticing that students who needed the credit rushed through tasks to get it over with. Cash payments, even small ones, produced more thoughtful responses and lower dropout rates. IRB review is a bottleneck that will slow you down regardless of how simple your study is. Budget at least two to four weeks for approval, longer if your research involves vulnerable populations or sensitive topics. I've seen ethics committees request changes that were reasonable and others that were outright nonsensical, like requiring me to explain why I wasn't studying a population that my research question had nothing to do with. Just answer their questions directly and resubmit if needed.
The biggest practical problem I face repeatedly is inconsistent instruction delivery across testing sessions. Even with scripted protocols, small variations in how you explain tasks, demonstrate examples, or respond to participant questions can introduce noise. I now record myself administering instructions and watch the recording to catch any deviations. It sounds excessive, but it catches things you won't notice in the moment.
Software Choices That Actually Matter
R is the standard for analysis now, though SPSS and JASP remain common. R has a steeper learning curve but it's free, reproducible, and infinitely more flexible. The tidyverse packages make data wrangling fast once you learn the syntax. I spend less time cleaning data in R now than I used to in SPSS, and my analysis scripts are fully documented and repeatable, which matters enormously for reproducibility checks and journal reviews. PsychoPy is the go-to for stimulus presentation. It runs on Windows, Mac, and Linux, handles millisecond-level timing accuracy, and integrates with most response boxes and eye-tracking equipment. LabVIEW and E-Prime do similar jobs but cost money and are Windows-only. If your department has licenses for E-Prime, fine, but don't feel obligated to use it if R and PsychoPy cover your needs. For pre-registration and open science practices, OSF is the platform most journals accept. It lets you store protocols, materials, and data in one place with time-stamped versions. Your analysis scripts and output can live there too. This isn't optional anymore for many top journals. Even if you're not publishing in those venues, keeping your work organized on OSF saves enormous time when you need to revisit a study six months later.
When to Call It Done and Move On
You'll never have a perfect study. You'll always have limitations worth acknowledging. The goal isn't perfection. It's a method that's transparent, justified, and executed as rigorously as your resources allow. A study with a small sample but clean methodology and full disclosure is more useful than a large study with hidden shortcuts and selective reporting. If you're starting out, pick a question you care about, design the simplest study that can answer it, and execute it carefully. Don't try to build the definitive study on your first attempt. Build a solid study, learn what went wrong, and improve the next one. That's how the method actually gets better. Not through grand theorizing about methodology, but through repeated practice and honest reflection on what didn't work. The field needs more researchers who understand that the research method in psychology isn't a formula to memorize. It's a set of decisions made under real constraints, and every decision carries a cost. Understanding those costs is what separates competent research from competent-looking research that falls apart under scrutiny.

