The Problem With Trying To Rip Text From Pdf
Most people hit a wall within five minutes of trying to rip text from pdf files. You open the document, copy a paragraph, and paste it into a text editor only to get gibberish or random line breaks that make it look like the text was run through a garbage disposal. This happens because a PDF is not a text document with fancy formatting. It is a drawing specification. The numbers on the page are placed at exact coordinates, and there is no guarantee that those numbers form readable text in the first place.What Actually Happens When You Rip Text From Pdf
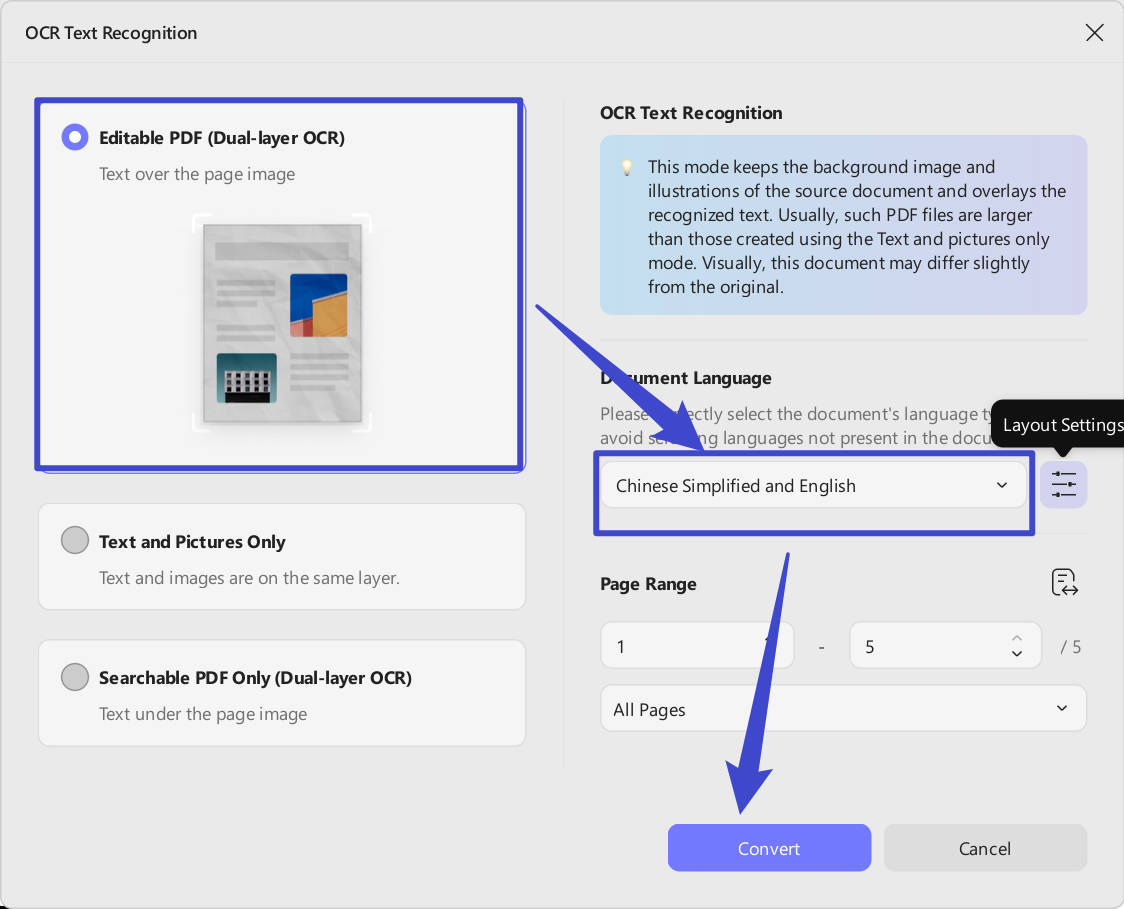
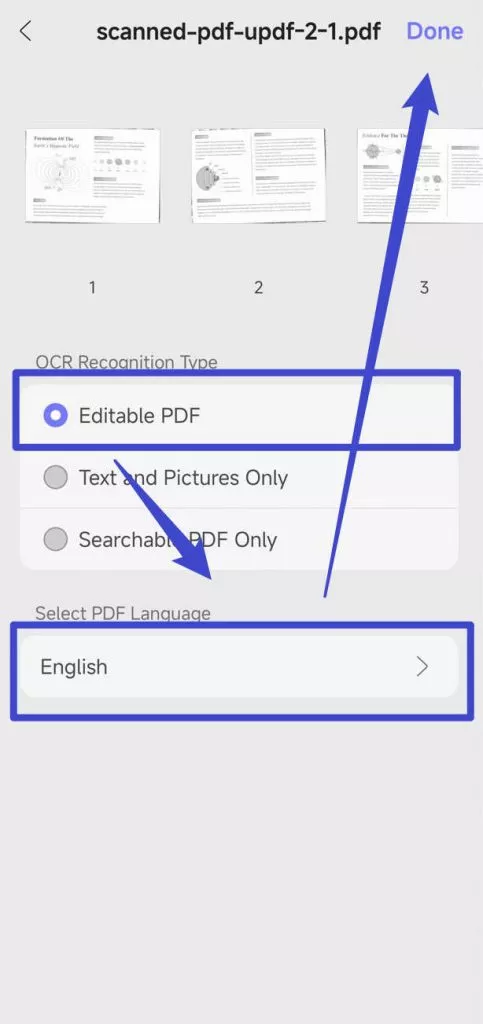
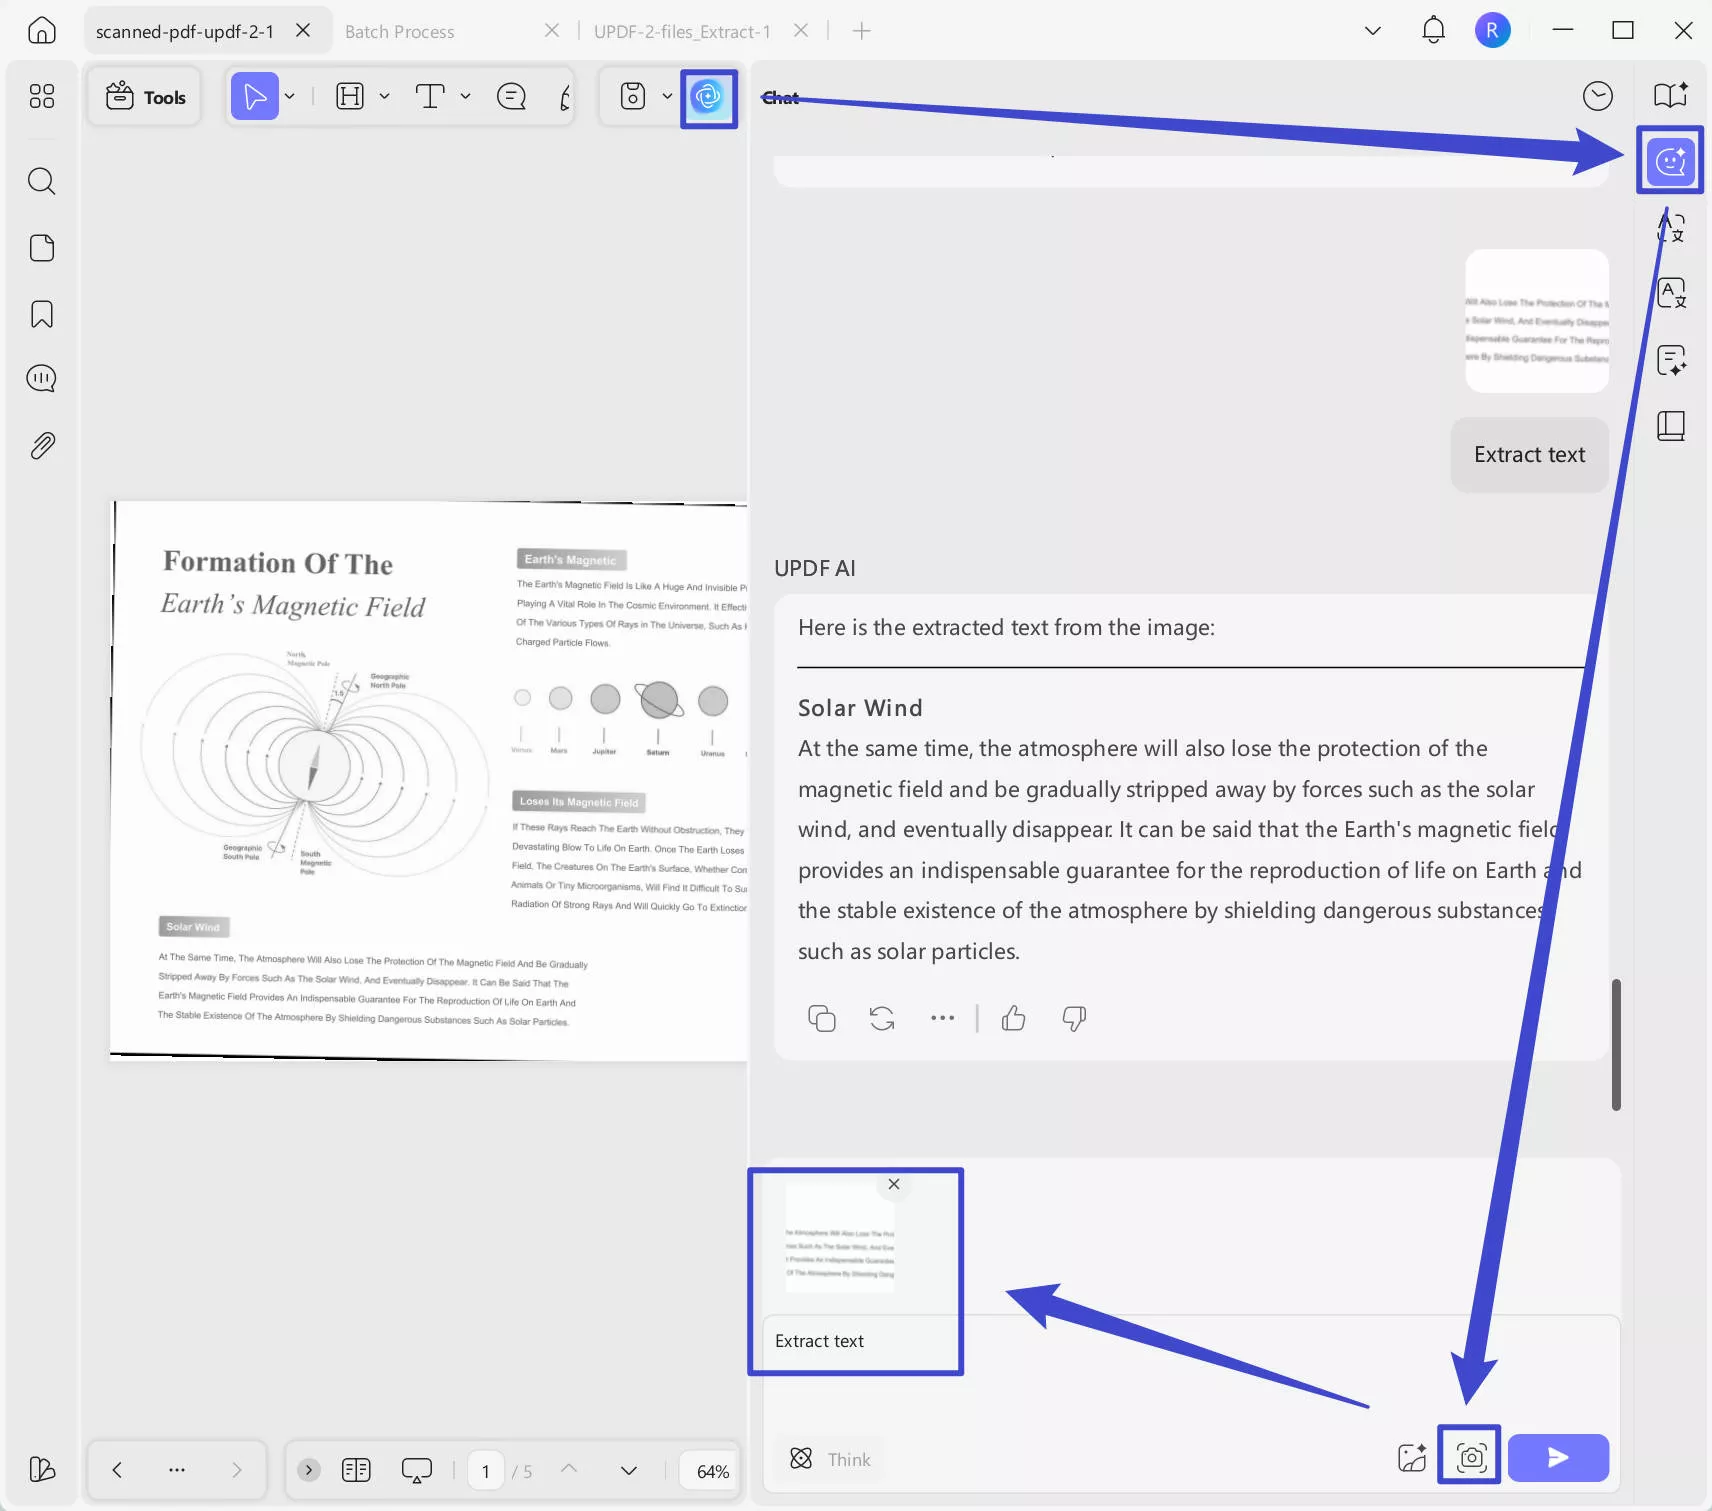
When you use any extraction method, the tool reads the PDF structure and looks for text objects — strings wrapped in Tj and TJ operators, or referenced through the PDF's content streams. If the PDF was created properly, this works cleanly. If the PDF was scanned or generated by a bad exporter, the text might be missing entirely or stored in a way that requires optical character recognition instead. Here is what I learned the hard way: I had a 400-page compliance document where one section refused to extract. Every tool returned empty strings. I opened the raw PDF stream in a hex editor and found that the text was embedded as outlines — actual vector paths, not font glyphs. The section was generated by a tool that converted text to curves before saving. No amount of regex or character mapping would recover that text. I ended up running just that one page through Tesseract OCR with a custom trained language model, and I got 94 percent accuracy. The rest I typed manually because the tables were too dense to trust the output.pyPDF2, pdfplumber, PyMuPDF — these are the most common libraries. PyMuPDF is significantly faster than pyPDF2 and handles coordinate-based text better. pdfplumber is slower but gives you layout information, which matters when columns are misaligned or tables are involved. If speed matters and your PDFs are standard, go with PyMuPDF. If you need structure, use pdfplumber. Here is a baseline extraction function that covers most real-world cases: This works for roughly 70 percent of PDFs out there. The remaining 30 percent require fallback strategies. When a page returns empty text, switch to image-based extraction. Render the page to an image and run OCR on it. With PyMuPDF you can render at high DPI and then pass the image to pytesseract or any OCR engine. The tradeoff is time — a single page of OCR at 300 DPI takes about two to four seconds on modern hardware, compared to milliseconds for native text extraction.
I keep a wrapper that tries native extraction first and falls back to OCR automatically. This saves me from manually inspecting every document that gives me empty results. The wrapper approach also means I don't have to decide upfront which method to use. I just let the code handle it.
Common Pitfalls That Will Waste Hours
The biggest issue people run into is text ordering. PDFs store text in content stream order, which does not always match visual reading order. Columns, footnotes, and sidebars often appear in the wrong sequence when extracted. If you are ripping text from pdf files that contain multi-column layouts, you will need to reorder the text yourself or use a tool like pdfplumber that provides bounding box coordinates and sorts by position. Another issue is font encoding. Some PDFs use custom encodings or subset fonts where character codes do not map directly to Unicode. The extracted text looks like random characters. You can detect this by checking the font's Encoding dictionary in the PDF structure. If it uses WinAnsiEncoding or Identity-H, you are usually fine. If it has a custom ToUnicode CMap, you may need to map characters manually or switch to OCR. A third problem is watermarks and overlays. Text that appears on top of a watermark or stamp often gets mixed into the extraction result. The watermark text becomes part of your output. I once spent twenty minutes debugging why my extracted legal brief kept including phrases like "COPY" and "DRAFT" in the middle of sentences. Opening the PDF in a viewer and looking at the layer structure revealed that the watermarks were on a separate content stream. Filtering by layer or ignoring text below a certain opacity threshold fixed the issue.
Get the Full Details
When PDF Extraction Simply Will Not Work
Some PDFs are fundamentally broken for text extraction. I have seen hand-drawn diagrams saved as PDFs where the "text" is actually images of text. I have seen PDFs generated by scientific plotting software where numbers are rendered as individual vector shapes instead of font glyphs. I have seen documents where the text is encrypted at the object level and the PDF reader decrypts it on display but the raw stream contains nothing readable. If the PDF has no text objects at all, native extraction will always return empty results. There is no workaround except OCR. And even OCR has limits — low-resolution scans, skewed pages, and complex table layouts produce errors that are nearly impossible to catch without manual review. I usually flag these documents for human verification rather than trusting the automated output. The honest recommendation is to test a small sample before processing a large batch. Extract five pages from each document type you expect to encounter and check the output quality. If the error rate is above five percent, plan for manual review on the sections that matter. Spending thirty minutes validating upfront saves three hours of cleaning up bad data later.
Tools For Rip Text From Pdf When Code Is Not Enough
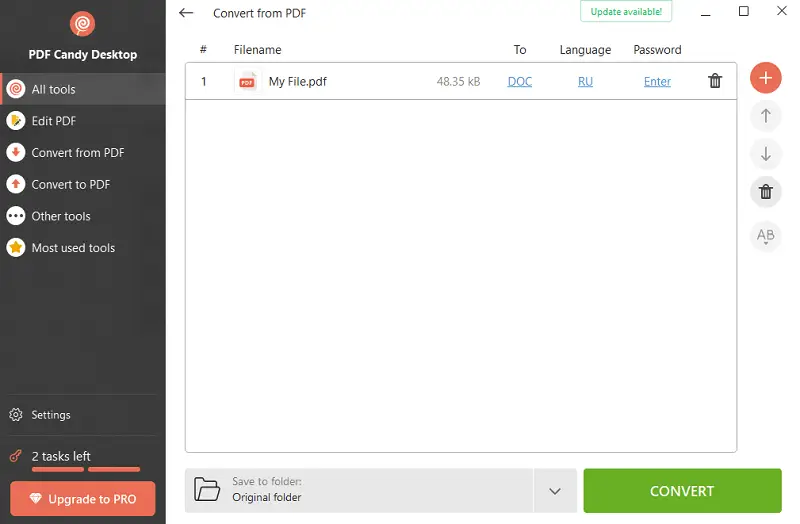
Sometimes you need a GUI tool instead of writing code. Adobe Acrobat Pro has a built-in export to text feature that handles most standard PDFs. It is slow and expensive but reliable for one-off extractions. For bulk operations, online tools like Smallpdf or ILovePDF work for basic cases but introduce privacy risks with sensitive documents. I avoid uploading anything confidential to web-based converters. For command-line users, pdftotext from the poppler-utils package is the oldest reliable option. It is preinstalled on most Linux systems and handles basic extractions without any setup. It struggles with complex layouts but is fast and deterministic. On macOS you can install it via Homebrew with brew install poppler. On Windows you need to install it separately or use a portable build.
A Practical Workflow That Actually Saves Time
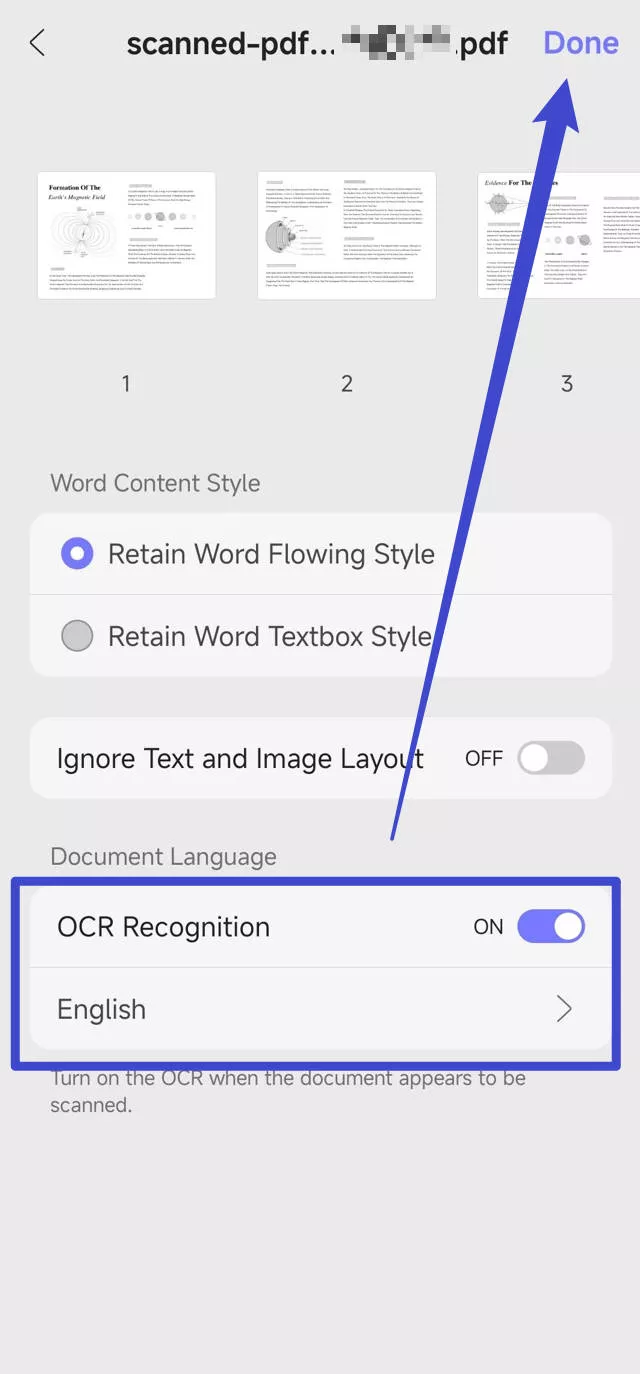
Here is the process I follow now instead of guessing which tool to use each time. First, I run PyMuPDF native extraction on all pages. I collect the pages that return empty or suspicious text. Second, I render those specific pages to images at 300 DPI. Third, I run Tesseract OCR on just the flagged pages with the appropriate language model. Fourth, I compare the OCR output against the native extraction and keep whichever has better character-level confidence scores. Fifth, I merge everything back into a single text file with page markers intact. This workflow takes about forty-five seconds per page on average for mixed-content documents. Pure text documents finish in under ten seconds. Scanned documents take longer depending on page complexity and OCR accuracy requirements. The key insight is that you should never OCR every page when most of them extract natively. Selective fallback is dramatically faster than blanket OCR across an entire document. I also cache the OCR results to disk so I never reprocess the same page twice. A simple JSON file keyed by filename and page number is enough. When I rerun the extraction, I load the cache first and skip pages that are already there. This matters when you are iterating on filtering logic or adjusting thresholds.
The bottom line is that ripping text from pdf is straightforward until it is not. Most documents yield text immediately with the right library. The ones that do not require a different approach for each failure mode. Understanding why extraction fails — outline fonts, custom encodings, missing text objects, encryption — is what separates a twenty-minute task from a two-day debugging session. Test early, fall back selectively, and verify a sample before committing to an automated pipeline.