The boring truth about risk analysis reports
Most people treating a risk analysis report like a compliance checkbox are going to produce garbage. A proper Risk Analysis Report Example should show stakeholders exactly what you stand to lose, how likely it is, and what you plan to do about it. That's it. Nothing fancy. I've spent years watching teams build elaborate documents that somehow fail to answer the question "should we proceed?" People love matrices and color codes. They skip the actual data.
What goes into a solid Risk Analysis Report Example
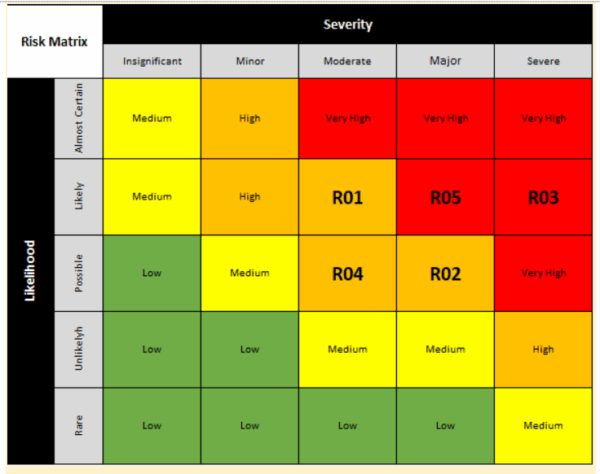
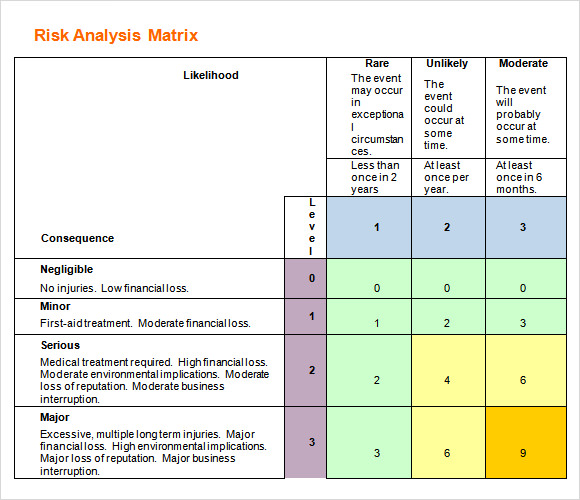
Start with the scope and the context. A risk analysis doesn't exist in a vacuum. You need to know what asset, system, or project you're analyzing before you can identify anything meaningful. I see too many reports where the risk register just appears out of nowhere with no definition of boundaries. That's a red flag. Then list the identified risks. For each one, you assign a likelihood score and a consequence score. The standard approach uses a 5x5 matrix where 1 is negligible and 5 is catastrophic. Multiply them and you get a risk rating from 1 to 25. Rating 1 through 4 is low. 5 through 9 is medium. 10 through 16 is high. Above 16 is critical. These thresholds are conventional but arbitrary. Adjust them for your industry if they don't fit. After the ratings come the mitigation strategies. This is where most reports fall apart. People write things like "reduce risk" or "monitor closely." Those aren't strategies. A real mitigation plan names a specific owner, a deadline, and a measurable outcome. If someone reads your report and can't tell who is responsible for what, you haven't written a plan. You've written a wish list.
The residual risk section is non-negotiable. After all mitigations are applied, recalculate the risk rating. Stakeholders need to see what risk remains. Hiding this number makes the report useless for decision-making.
Get the Full Details

A practical example from a real project
Last year I worked on a cloud migration where the original risk register listed twelve items. The team had rated seven of them as medium or low and filed them away. One risk, a third-party API dependency with a documented 40 percent downtime rate during peak hours, was sitting at a 12 on the matrix and was labeled "acceptable." The vendor's SLA explicitly excluded force majeure events that included their primary data center outages. That's the kind of thing that gets missed when you're rushing to complete the report. I pulled the actual incident history for that API going back eighteen months instead of trusting the vendor's marketing pages. The numbers were worse than the SLA implied. I recalculated the impact by modeling a worst-case scenario where the API went down for seventy-two straight hours during a product launch window. The revised risk rating jumped to 22. That changed the entire conversation. The migration plan got restructured to include a fallback authentication method and a local cache layer. Without that re-evaluation, the project would have launched into a known single point of failure. This is the part nobody puts in the template. The risk you miss isn't the one on the register. It's the one you rated too low because you accepted incomplete information at face value.
Common mistakes that waste everyone's time
Using stale data is the most damaging error. I've seen risk reports where the likelihood scores were based on incidents from three years prior, in a completely different operational environment. The infrastructure had changed. The threat landscape had shifted. The report looked professional and the numbers seemed reasonable. It was entirely wrong. Another mistake is aggregating risks incorrectly. If you have three separate risks each rated at 8 and you sum them to get a total project risk of 24, you're doing math that doesn't reflect reality. Risks interact. Some compound. Some cancel each other out. A proper analysis should note correlations and dependencies between risks, not treat every item as an independent variable. Quantitative versus qualitative is another area where people choose the wrong approach and then act confused when the results don't convince anyone. Qualitative matrices work fine for small projects with limited data. When you're dealing with millions of dollars in potential loss and you have historical incident data, a qualitative matrix gives you a false sense of precision. A cost-benefit analysis with actual dollar figures and probability distributions will serve you better. The problem is that quantitative methods require real data, and most organizations don't have it. So they fake it with gut feelings and call it quantitative.
Building the report efficiently
If you're starting from scratch, you don't need expensive software. A spreadsheet with a clean structure works. I usually organize it with tabs for risk identification, scoring, mitigation tracking, and residual risk summary. The identification tab captures the risk description, category, source, likelihood, consequence, current controls, and initial rating. The mitigation tab tracks the action, owner, target date, and expected rating after implementation. The summary tab shows the final numbers and highlights any risks above threshold. For larger projects, dedicated risk management tools like RiskWatch or Diligent HighBond can help, but they add complexity and cost. A well-structured spreadsheet will get you 90 percent of the way there in about fifteen minutes, whereas setting up a tool properly can take two days. The tool only pays off when you're managing dozens of ongoing risks across multiple teams and need version control and audit trails. One thing I do differently from the standard approach is including a risk closeout section. When a mitigation action is completed and verified, the risk gets moved to a closure log with the date, the evidence of completion, and the updated residual rating. This creates a paper trail that auditors actually find useful, instead of a static document that looked good at launch and never got updated again.
When a risk analysis report simply won't work
The 5x5 matrix approach breaks down when you have continuous variables. Financial market risk, for instance, involves probabilities that don't fit neatly into five categories. A Value at Risk model with Monte Carlo simulation is more appropriate there. Using a qualitative matrix for cybersecurity risk in a regulated environment is also problematic if your regulator expects quantitative evidence. NIST 800-30 and ISO 31000 both allow qualitative methods, but examiners often push back when the underlying assumptions aren't documented. Another hard limit is when stakeholder disagreement on risk appetite is extreme. If the board thinks any risk above 10 is unacceptable and the operations team considers anything below 20 to be ignorable, no amount of documentation will resolve the conflict. The report becomes a weapon rather than a tool. In those situations, the best move is to surface the disagreement explicitly and escalate it to the appropriate governance body instead of pretending the analysis will settle things. Finally, risk analysis reports don't predict the future. They frame uncertainty based on available information. Any report that implies certainty has failed. The goal is to make the unknowns visible, not to eliminate them.
A Risk Analysis Report Example you can actually use
Here's a stripped-down version that covers the essentials without the usual padding: Project: Legacy system migration to cloud infrastructure. Reporting date: March 2025. Scope: All systems within the customer data segment. Identified risks: Third-party API dependency with historical 40 percent peak-hour downtime (rating 22 after correction, originally rated 12). Insufficient failover capacity for regional outages (rating 18). Key personnel dependency on two engineers with undocumented processes (rating 14). Data compliance gap in cross-border transfer handling (rating 16). Mitigation in progress: API fallback authentication and local caching being implemented by the infrastructure team with a target completion of April 15. Failover capacity increase being procured with a three-week lead time. Knowledge documentation and cross-training scheduled for April. Compliance review with legal underway. Residual risk after planned mitigations: API dependency drops to 11. Failover risk drops to 9. Personnel dependency drops to 6. Compliance gap drops to 8. Highest residual risk remains the API dependency at 11, which still exceeds the organizational threshold of 10. Recommendation: proceed with migration only if the API fallback is validated before launch. All other risks fall within acceptable range once mitigations are complete. This is shorter than most reports you'll encounter. It's also easier to act on.