Most Incident Response Frameworks Are Built for Perfect Conditions. Here Is What Actually Works.
Start with the workflow you need at 2 AM when PagerDuty is burning holes in your phone. The rest follows. When an alert fires, your team should not be debating what the process is. They should be executing it. The incident command structure exists for exactly this reason - someone calls ITIL, NIST SP 800-61, or whatever framework you picked three years ago out of a brochure, reads it for six pages, then gives up because none of it addresses the specific failure mode you are looking at right now. I have seen this happen repeatedly.
The Core Workflow: Detection Through Post-Mortem
Every functional incident response pipeline has five stages, listed in order but sometimes collapsing into each other during fast-moving events: Detection. Something triggers an alert. This could be an automated monitoring system flagging anomalous behavior, a user reporting unexpected results, or a security tool correlating data across multiple endpoints. The detection phase matters more than most teams realize because your entire response timeline depends on how quickly and accurately this happens. False positives waste resources. Missed detections let problems compound. Triage and Escalation. Someone with authority decides whether this is a real incident and what severity it carries. Use a defined severity matrix - P1 through P4, or critical, high, medium, low. Whatever you choose, document the criteria so the next person does not have to guess. The common mistake here is making severity decisions based on the noisiest voice in the room rather than objective impact thresholds.
Containment. Stop the bleeding. This might mean isolating affected systems, rolling back deployments, blocking IP ranges, or enabling failover procedures. Short-term containment actions often conflict with long-term resolution goals. A firewall rule that blocks an attacker's access path might also block legitimate traffic. Document every containment decision with timestamps. These logs become critical during the post-mortem. Resolution and Recovery. Fix the root cause. Restore normal operations. Verify that systems are stable before declaring recovery complete. The temptation is to declare victory as soon as the immediate symptom subsides. This is how incidents recur. Require a stabilization period - typically 24 hours minimum for infrastructure changes, 48 hours for security incidents - before closing the incident formally. Post-Mortem and Learning. This is where most organizations fail. Write a document that covers what happened, why it happened, what went well, what went poorly, and what specific changes prevent this class of incident from recurring. Assign owners and deadlines to each action item. Track them. If you skip the tracking, you skipped the learning.
Get the Full Details
Risk And Incident Management: Connecting the Two Tracks
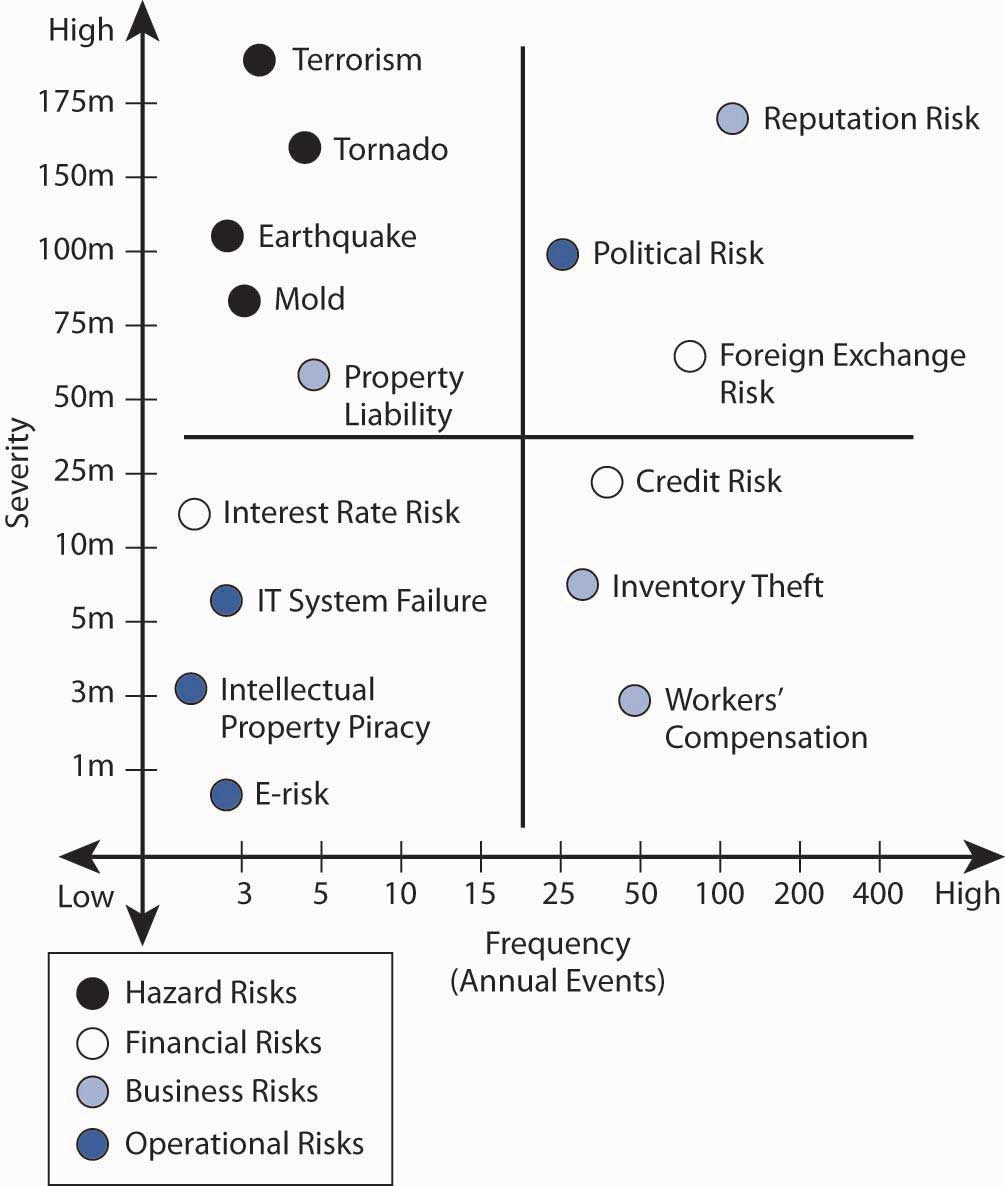
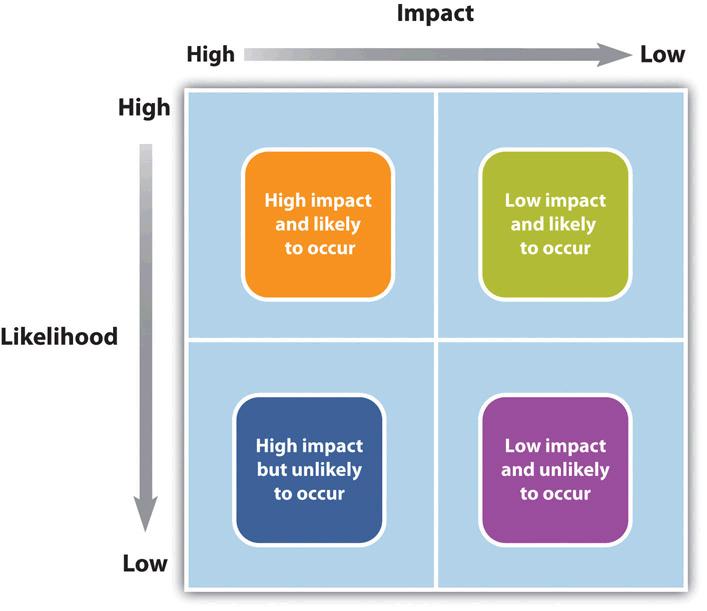
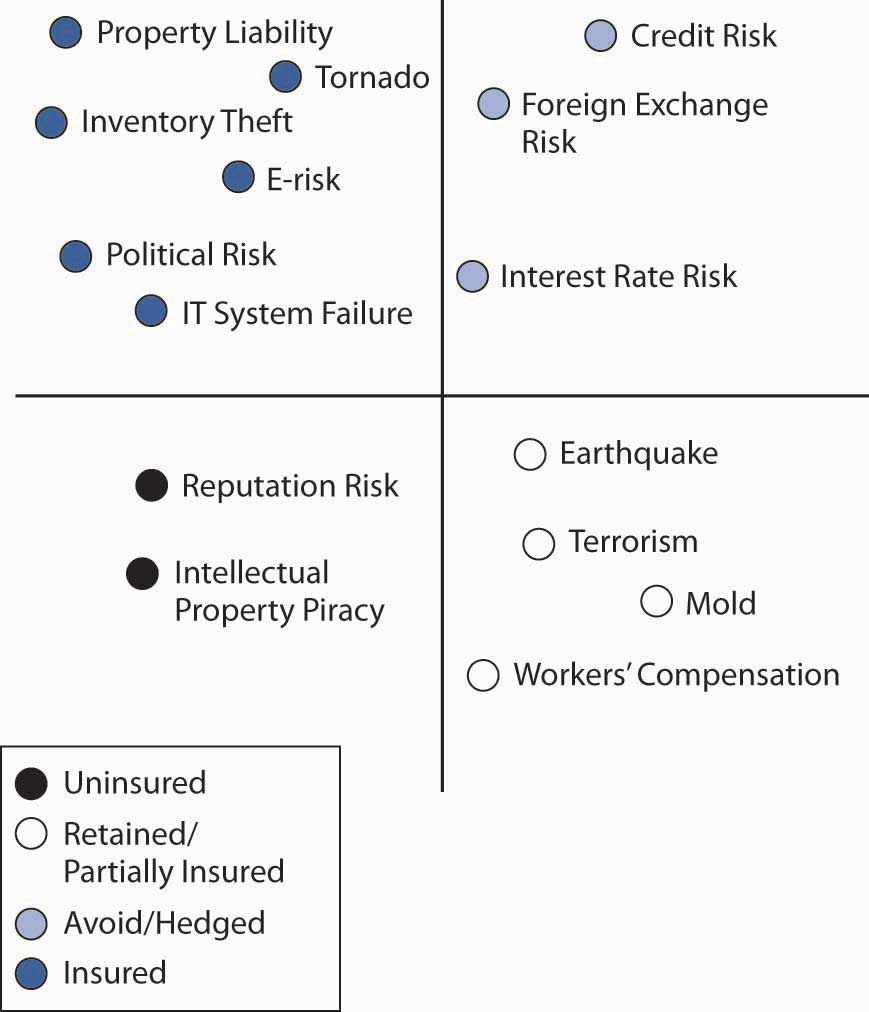
Risk management and incident response are usually handled by separate teams with different reporting lines. This separation creates blind spots. Known risks never make it into incident playbooks. Incident patterns never feed back into risk assessments. The connection between them is the single most underutilized mechanism in operational resilience. Build a risk register that maps directly onto your incident response plan. Each identified risk should have a corresponding response procedure. Each incident should have a corresponding risk entry. The review cycle should be quarterly minimum, and you should treat it like a living process, not an annual compliance exercise. A risk register that has not been updated in six months is a liability, not an asset, because it creates false confidence in outdated threat assumptions. The practical workflow looks like this: risk identification happens during quarterly reviews where you analyze threat models, vulnerability assessments, and historical incident data. Each risk gets a probability rating and an impact rating. Probability uses a five-point scale from rare to almost certain. Impact uses a five-point scale from negligible to catastrophic. Multiply them for a risk score. The high-score risks get mitigation plans. The medium-score risks get monitored. The low-score risks get accepted with documentation.
A Specific Edge Case I Encountered
During a major infrastructure migration at a previous employer, we ran into a scenario where the risk register listed cloud storage credentials as a managed risk with standard rotation procedures. The incident response playbook referenced the same controls. Everything looked correct on paper. The actual failure mode was a race condition between our credential rotation automation and a stale service configuration that had been cached on three compute instances. The rotation succeeded cleanly according to logs. The cached configurations continued using expired credentials. Authentication failures cascaded across the application layer during a traffic spike, and our monitoring alerts fired for resource exhaustion but not for the underlying authentication failures because those were buried in application logs that nobody had set up alerting for. The workaround was straightforward but tedious. I wrote a configuration drift check that compared live service states against the known-good configuration from our deployment pipeline. It runs every 15 minutes and flags any deviation from the expected credential set. We also added authentication failure rate as a primary alert metric, not something secondary to resource utilization. The total implementation took about two days. It has prevented at least four similar incidents since deployment.
Tools: What Actually Gets Used
Most organizations either over-invest or under-invest in tooling for incident and risk management. The truth is that your tooling should serve the workflow, not the other way around. For incident management, you need alerting, communication, tracking, and reporting. Alerting can be as simple as PagerDuty, Opsgenie, or the built-in notification systems in tools like Datadog or Prometheus. Communication happens on whatever channel your team already uses during crises - Slack, Microsoft Teams, or occasionally good old phone calls for anything that breaks the usual platforms. Tracking lives in ServiceNow, Jira, or increasingly lightweight options like Incident.io or FireHydrant if you want something faster than an enterprise ITSM suite. For risk management, you need identification, assessment, and monitoring. Tools like ISM, RSA Risk Manager, or even a well-structured spreadsheet in GRC platforms like OneTrust or LogicGate can work depending on organizational size. The tool matters less than the discipline of keeping the data current and actionable.
Integration between these two toolchains is where the real value appears. When a risk assessment flags a new threat vector, that information should automatically populate the relevant incident response procedure. When an incident concludes, the post-mortem findings should feed back into the risk register as either new risks or modifications to existing ones.
Common Pitfalls That Slow Everything Down
Severity misclassification is probably the most expensive mistake teams make. Treating a P2 like a P1 wastes specialized resources. Treating a P1 like a P2 delays response. Define your severity criteria explicitly and include concrete examples. "Customer-facing data breach" is a P1. "Internal dashboard performance degradation" is probably a P3. The line between these categories is where most disagreements happen. Another pitfall is the post-mortem that becomes a blame exercise. This shuts down information flow. People stop reporting issues early. Problems get hidden until they become incidents. The fix is structural - make post-mortems about systems and processes, not individuals. Use phrases like "the deployment process did not catch" instead of "John forgot to update." This is easier said than enforced, but the difference in team behavior after three or four properly handled post-mortems is noticeable. A third pitfall is relying on a single detection channel. If your monitoring, your application logs, and your user reports all point to the same failure mode, you have no fallback when one channel goes dark. Diversify detection. Synthetic monitoring, log analysis, user feedback channels, and external uptime checks should all feed into your detection pipeline independently.
Metrics That Actually Matter
Mean Time to Detect (MTTD) and Mean Time to Resolve (MTTR) are the standard metrics. They are useful but incomplete. A team that minimizes MTTD by escalating everything to P1 and then minimizes MTTR by declaring quick fixes as resolutions will look great on paper while producing increasingly fragile operations. Track recurrence rate for incident types. This tells you whether your post-mortem actions are effective. If the same category of incident appears more than three times in a quarter, your corrective actions are not working or you are not implementing them consistently. Track the ratio of planned versus unplanned work. Teams with high unplanned work ratios are operating reactively, which means their risk management is failing to prevent incidents before they happen. For risk management specifically, track the age of your oldest risk assessment item that has not been reviewed. Anything over 90 days is stale. Track the percentage of high-priority risks that have documented mitigation plans with assigned owners and deadlines. Anything below 80% indicates a gap between identification and action.
When Standard Approaches Break Down
The biggest limitation of formal Risk And Incident Management frameworks is that they assume a relatively stable environment. In fast-moving development cycles with continuous deployment, risk assessments become outdated within weeks. Static incident response procedures cannot keep pace with architectures that change daily. The workaround is shifting toward iterative risk management. Instead of quarterly reviews, implement monthly micro-reviews focused on recently changed systems. Instead of comprehensive playbooks, maintain lightweight scenario guides that cover the top five most likely incident types for each system. This approach trades completeness for relevance, which is usually the right tradeoff in dynamic environments. Another scenario where standard approaches fail is when dealing with novel or zero-day threats. Your risk register will not contain entries for attack vectors you have never seen. Your incident playbook will not have procedures for situations with no precedent. In these cases, the framework provides structure for the known unknowns. The unknown unknowns require adaptive response capabilities - trained personnel who understand the underlying systems well enough to reason through unfamiliar failure modes rather than following documented procedures blindly.
The practical implication is that training and system knowledge matter more than procedural documentation for senior responders. Junior responders benefit most from well-written procedures. Senior responders benefit most from deep contextual understanding. Invest in both, but do not assume that better documentation substitutes for deeper knowledge.