How Risk And Information Systems Control Actually Works When You Stop Guessing
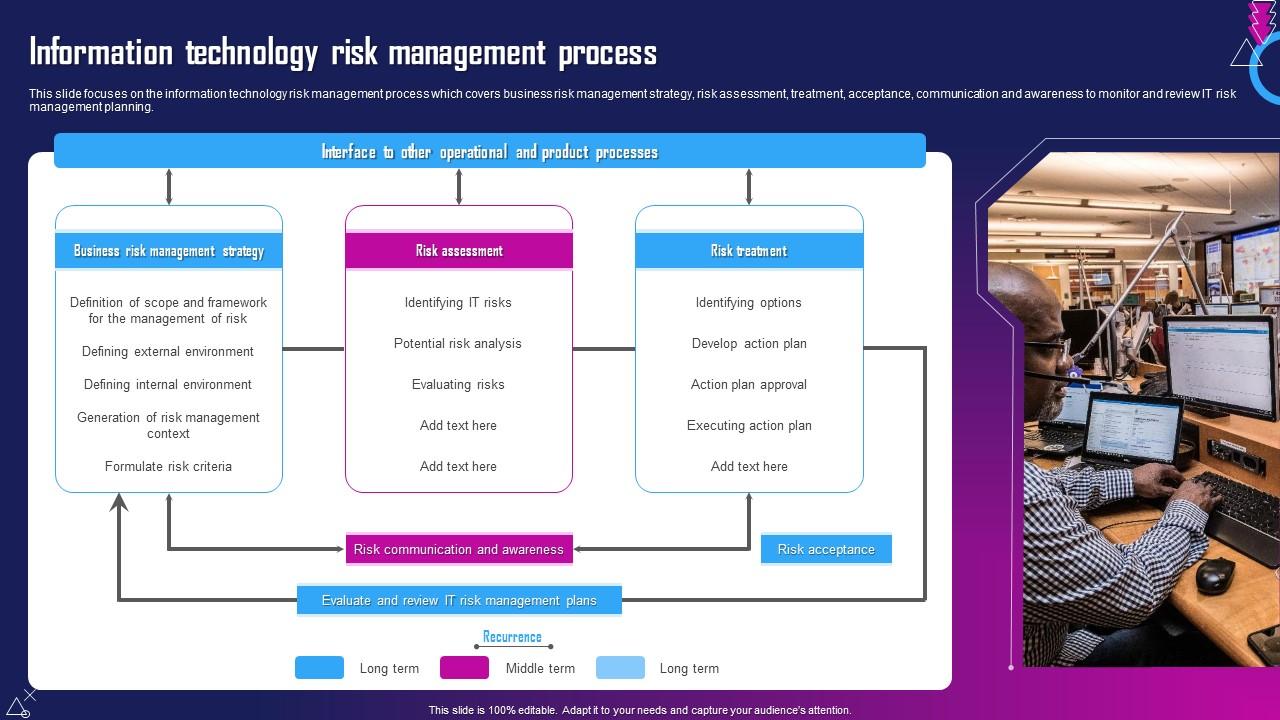
I spent three years trying to build a control framework that felt real instead of just being a binder sitting on a virtual shelf. The usual approach most people start with is reading NIST 800-30, cobbling together a risk register in Excel, and hoping compliance auditors won't notice the gaps. That works until it doesn't, which is usually when something breaks in production at 2 AM and suddenly everyone needs to know who approved the config change six months ago. The method that actually stuck for me involved flipping the process. Instead of identifying every possible risk and then hunting for controls, I started with the systems themselves and worked backward from failure modes. You map your critical information assets first, then ask what happens if each one becomes unavailable, corrupted, or exposed. From there you can derive which controls are actually necessary instead of which ones look good on paper. This cut our control framework review cycle from about three weeks down to roughly four days because we stopped trying to cover everything.
Implementing Risk And Information Systems Control in a Live Environment
The first practical step is building an asset inventory that you actually trust. Most organizations have these lying around in some form, but they're usually out of date within a month. I found that pulling from automated discovery tools like Nessus or LanSweeper combined with a manual walkthrough of network diagrams gave me about 94 percent accuracy on critical assets. The remaining 6 percent was usually shadow IT or decommissioned servers that still had active IP addresses because nobody updated the firewall rules. Once you have a working inventory, you categorize each asset by its sensitivity level and the systems it connects to. Not just what it stores, but what it touches. A seemingly minor development server that had read access to the production database endpoint turned out to be my biggest exposure vector during a penetration test I ran internally. It held no customer data directly, but it held credentials that did. Risk assessment in this context means scoring each asset against three variables: likelihood of a threat event, potential impact if it occurs, and the existing controls you already have in place. I used a simple 1 to 5 scale for each and multiplied them together to get a risk score. Anything above 12 on that scale went into the mitigation queue immediately. Below 12 went into monitoring. Below 6 got ignored unless something changed in the environment.
The controls themselves fall into categories. Preventive controls stop incidents before they happen. Detective controls identify them after they start. Corrective controls fix the damage afterward. Most frameworks over-index on preventive controls because they're easier to document and audit. But detective and corrective controls often matter more in practice because prevention always fails at some point. A misconfigured IAM role, a zero-day vulnerability, or a lazy contractor is enough to bypass your firewall rules. I built a control library mapped to each identified risk, then assigned ownership. Each control needed a clear owner who could actually testify to its operation during an audit. Having a control owned by "the security team" is worthless when someone asks who last tested it and when. I started requiring a date field and a validation method for every control entry. Controls older than six months without validation got flagged automatically. The hardest part turned out to be continuous monitoring. Initial assessments are straightforward. Keeping them current is where most programs stall. I set up automated alerts for configuration drift on critical assets using a combination of Ansible and a lightweight SIEM pipeline. When a server's settings changed without an approved ticket, the system notified the owning team and logged the delta. This replaced the old monthly manual review process that nobody completed on time anyway.
Get the Full Details
One edge case I encountered involved a third-party vendor API that our internal risk assessment had scored as low risk because it only exchanged non-sensitive telemetry data. Two years later, that same API had accumulated persistent authentication tokens with elevated privileges due to a vendor patch that changed the token scope. We didn't catch it during our annual review because the original assessment still listed it as low risk and nobody had revisited the actual token permissions. The workaround was implementing quarterly automated permission audits on all external integrations, not just internal assets. That alone uncovered five other cases where vendor updates had quietly expanded access. It took me about two hours to write the audit script and maybe another hour to get leadership to approve the recurring schedule.
Where This Approach Breaks Down
This method assumes you have reasonable visibility into your environment. If you're running on cloud infrastructure without proper logging enabled, or you have hybrid environments where one side uses active directory and the other runs on something completely different, your asset inventory will have blind spots that no amount of scanning will fix. In those cases you need to supplement automated discovery with contract reviews and architectural documentation from the teams that actually provisioned the systems. Another limitation is that risk scores are only as good as the assumptions behind them. A risk score of 15 might look urgent but if it's based on an inflated likelihood estimate from a single near-miss incident, it could crowd out legitimate high-risk items that haven't triggered an alert yet. I learned this the hard way when a genuinely critical database encryption gap got deprioritized because a more visible but less severe phishing incident had spiked its risk score temporarily. The fix was adding a decay factor to risk scores so they dropped back toward baseline if no related events occurred within ninety days. Documentation overhead is also a real concern. A fully maintained control framework with validated ownership, dates, and evidence attachments can add roughly fifteen to twenty hours per month to whatever security team is responsible for it. Small teams without automation often abandon the process entirely because the administrative burden outweighs the perceived value. If your organization has fewer than five dedicated security staff and no budget for tooling, consider adopting a simplified framework like CIS Controls instead of building something custom. CIS gives you a prioritized list of actionable controls without the configuration management overhead.
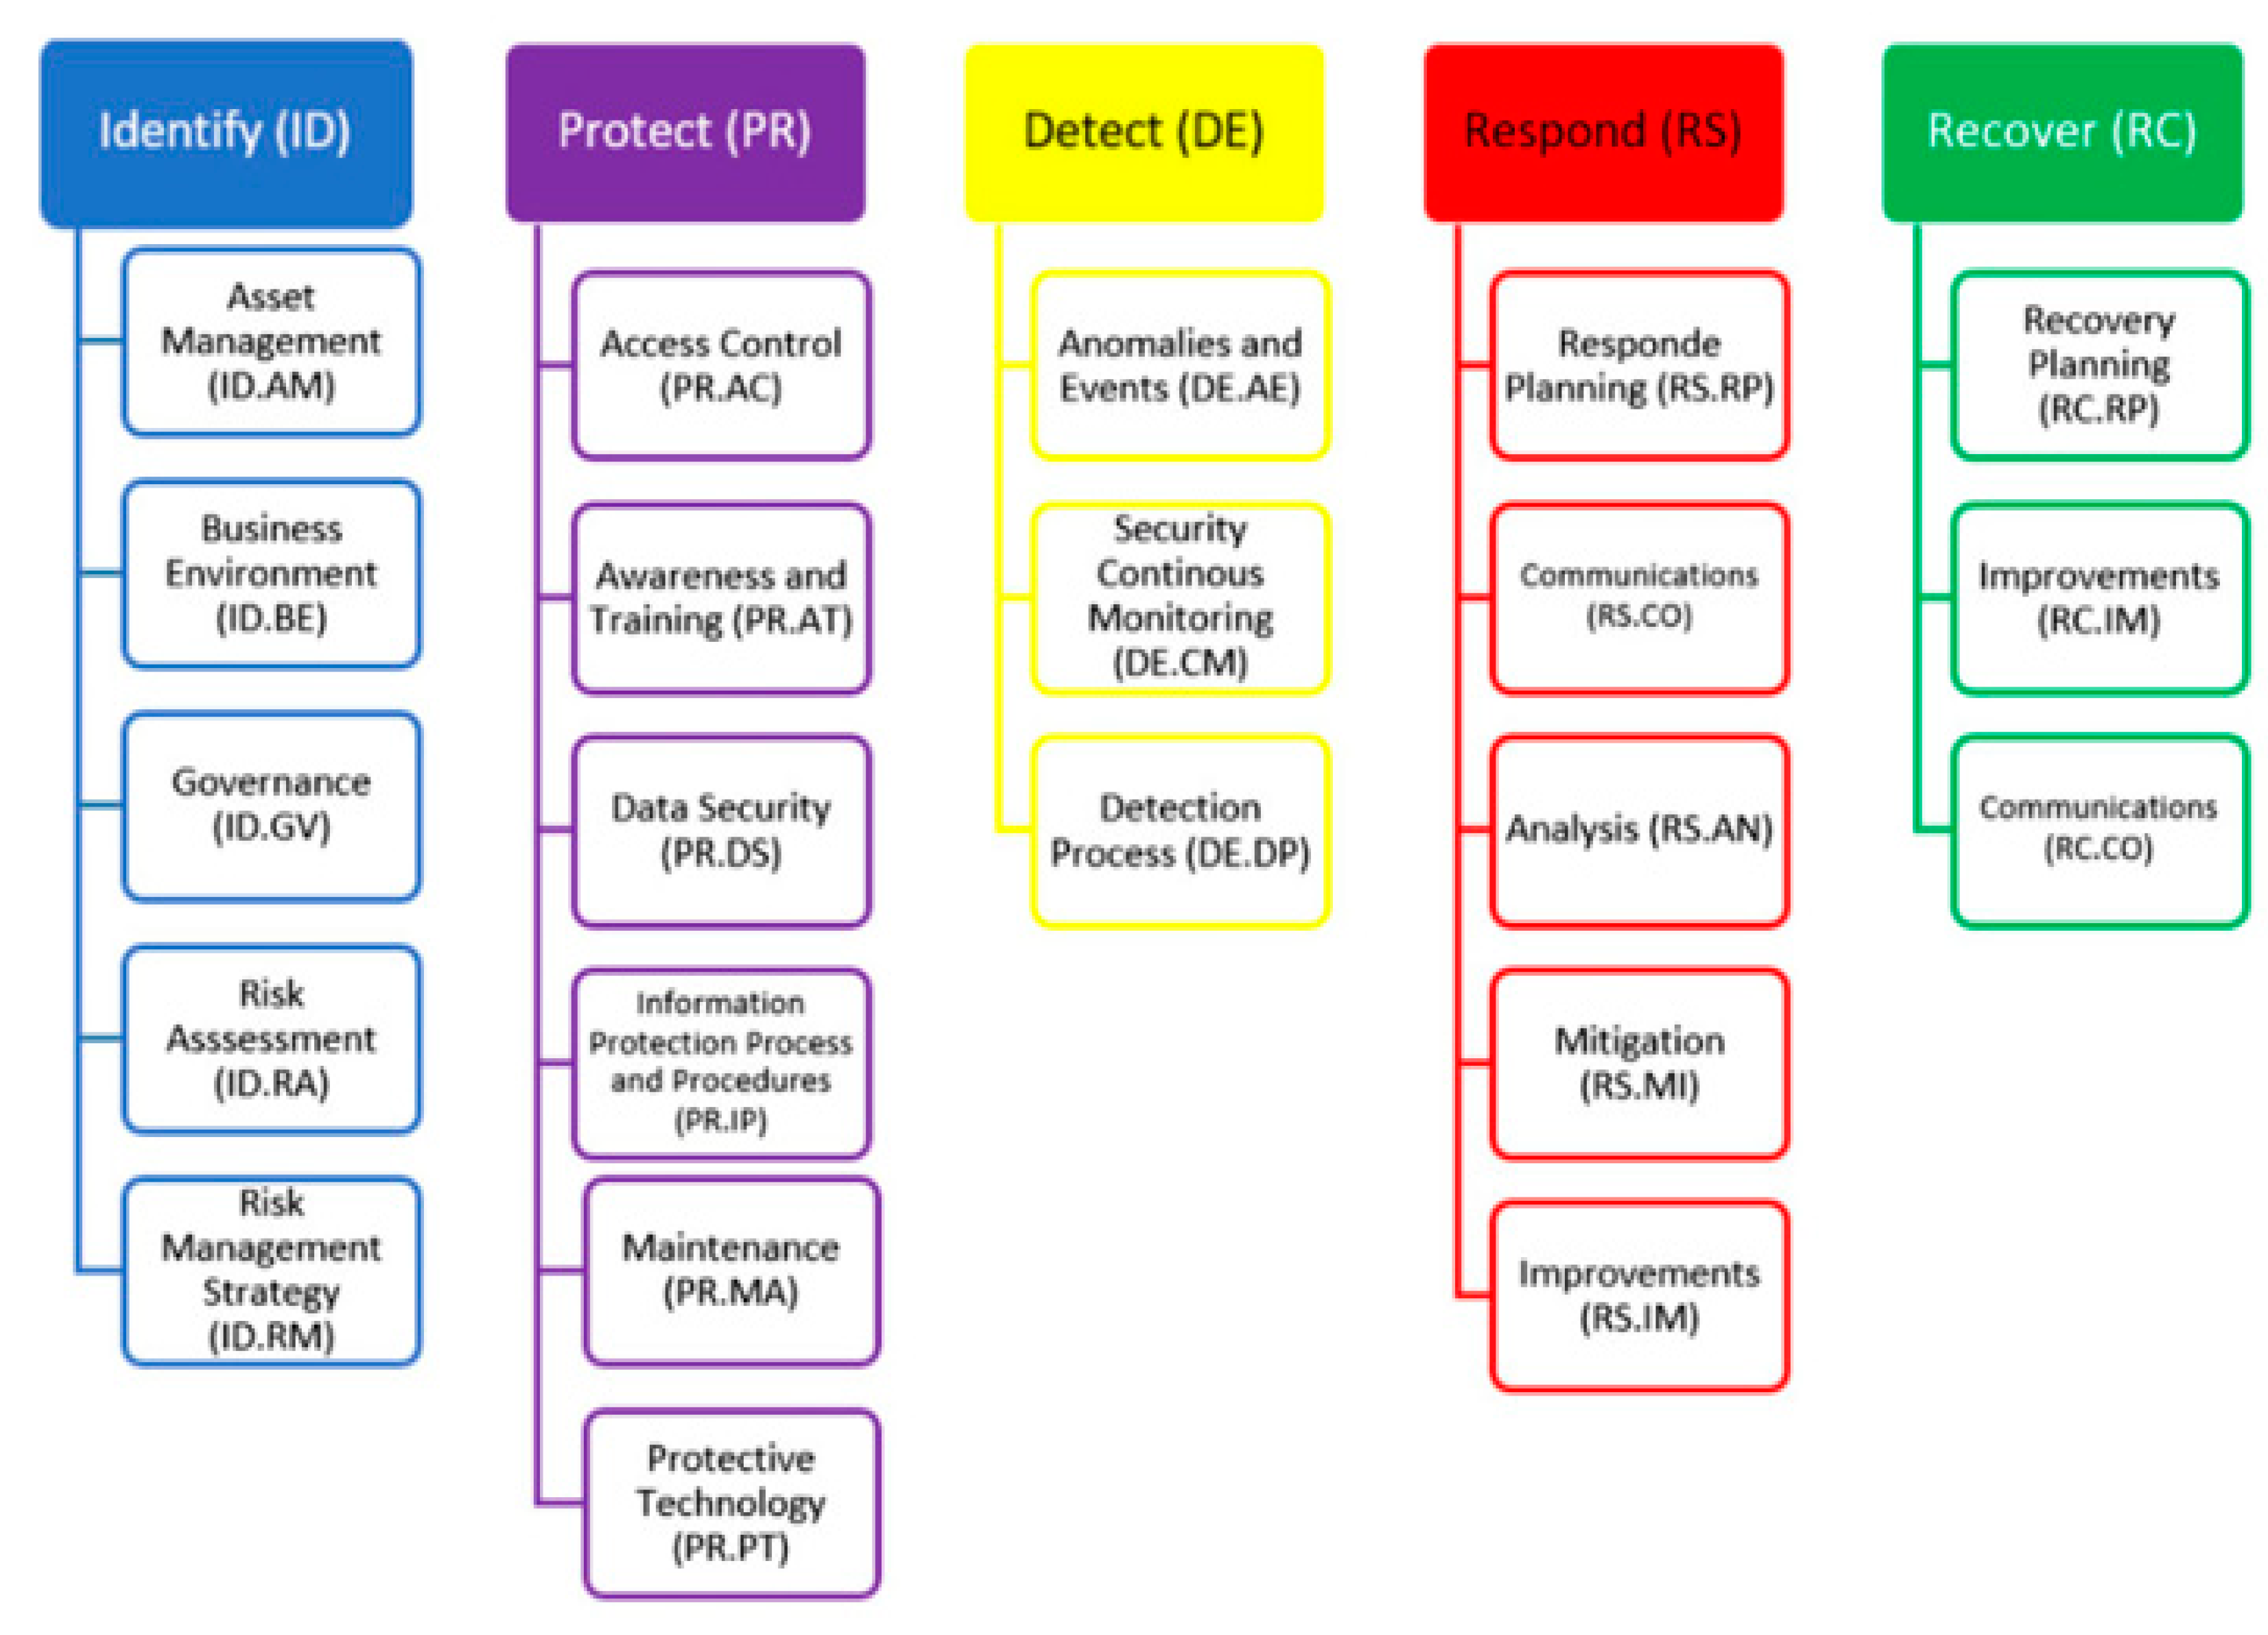
The biggest mistake I see is treating Risk And Information Systems Control as a one-time project instead of an ongoing operational discipline. The environment changes constantly. New services get deployed, old ones get forgotten, permissions drift, and threat landscapes shift. A framework that isn't revisited at least quarterly becomes a historical document rather than a living control system. Schedule regular reviews, automate what you can, and don't let perfect documentation become the enemy of actual risk reduction. For reference materials, the NIST Cybersecurity Framework and ISO 27005 provide structured approaches you can adapt rather than starting from scratch. COBIT offers a more governance-focused angle if your organization answers to a board or regulatory body. These aren't complete solutions on their own but they save significant time compared to writing everything yourself. Pick one, map it to your asset inventory, and iterate from there instead of trying to implement every control in every framework simultaneously.