Building a Risk Assessment Decision Tree That Actually Works
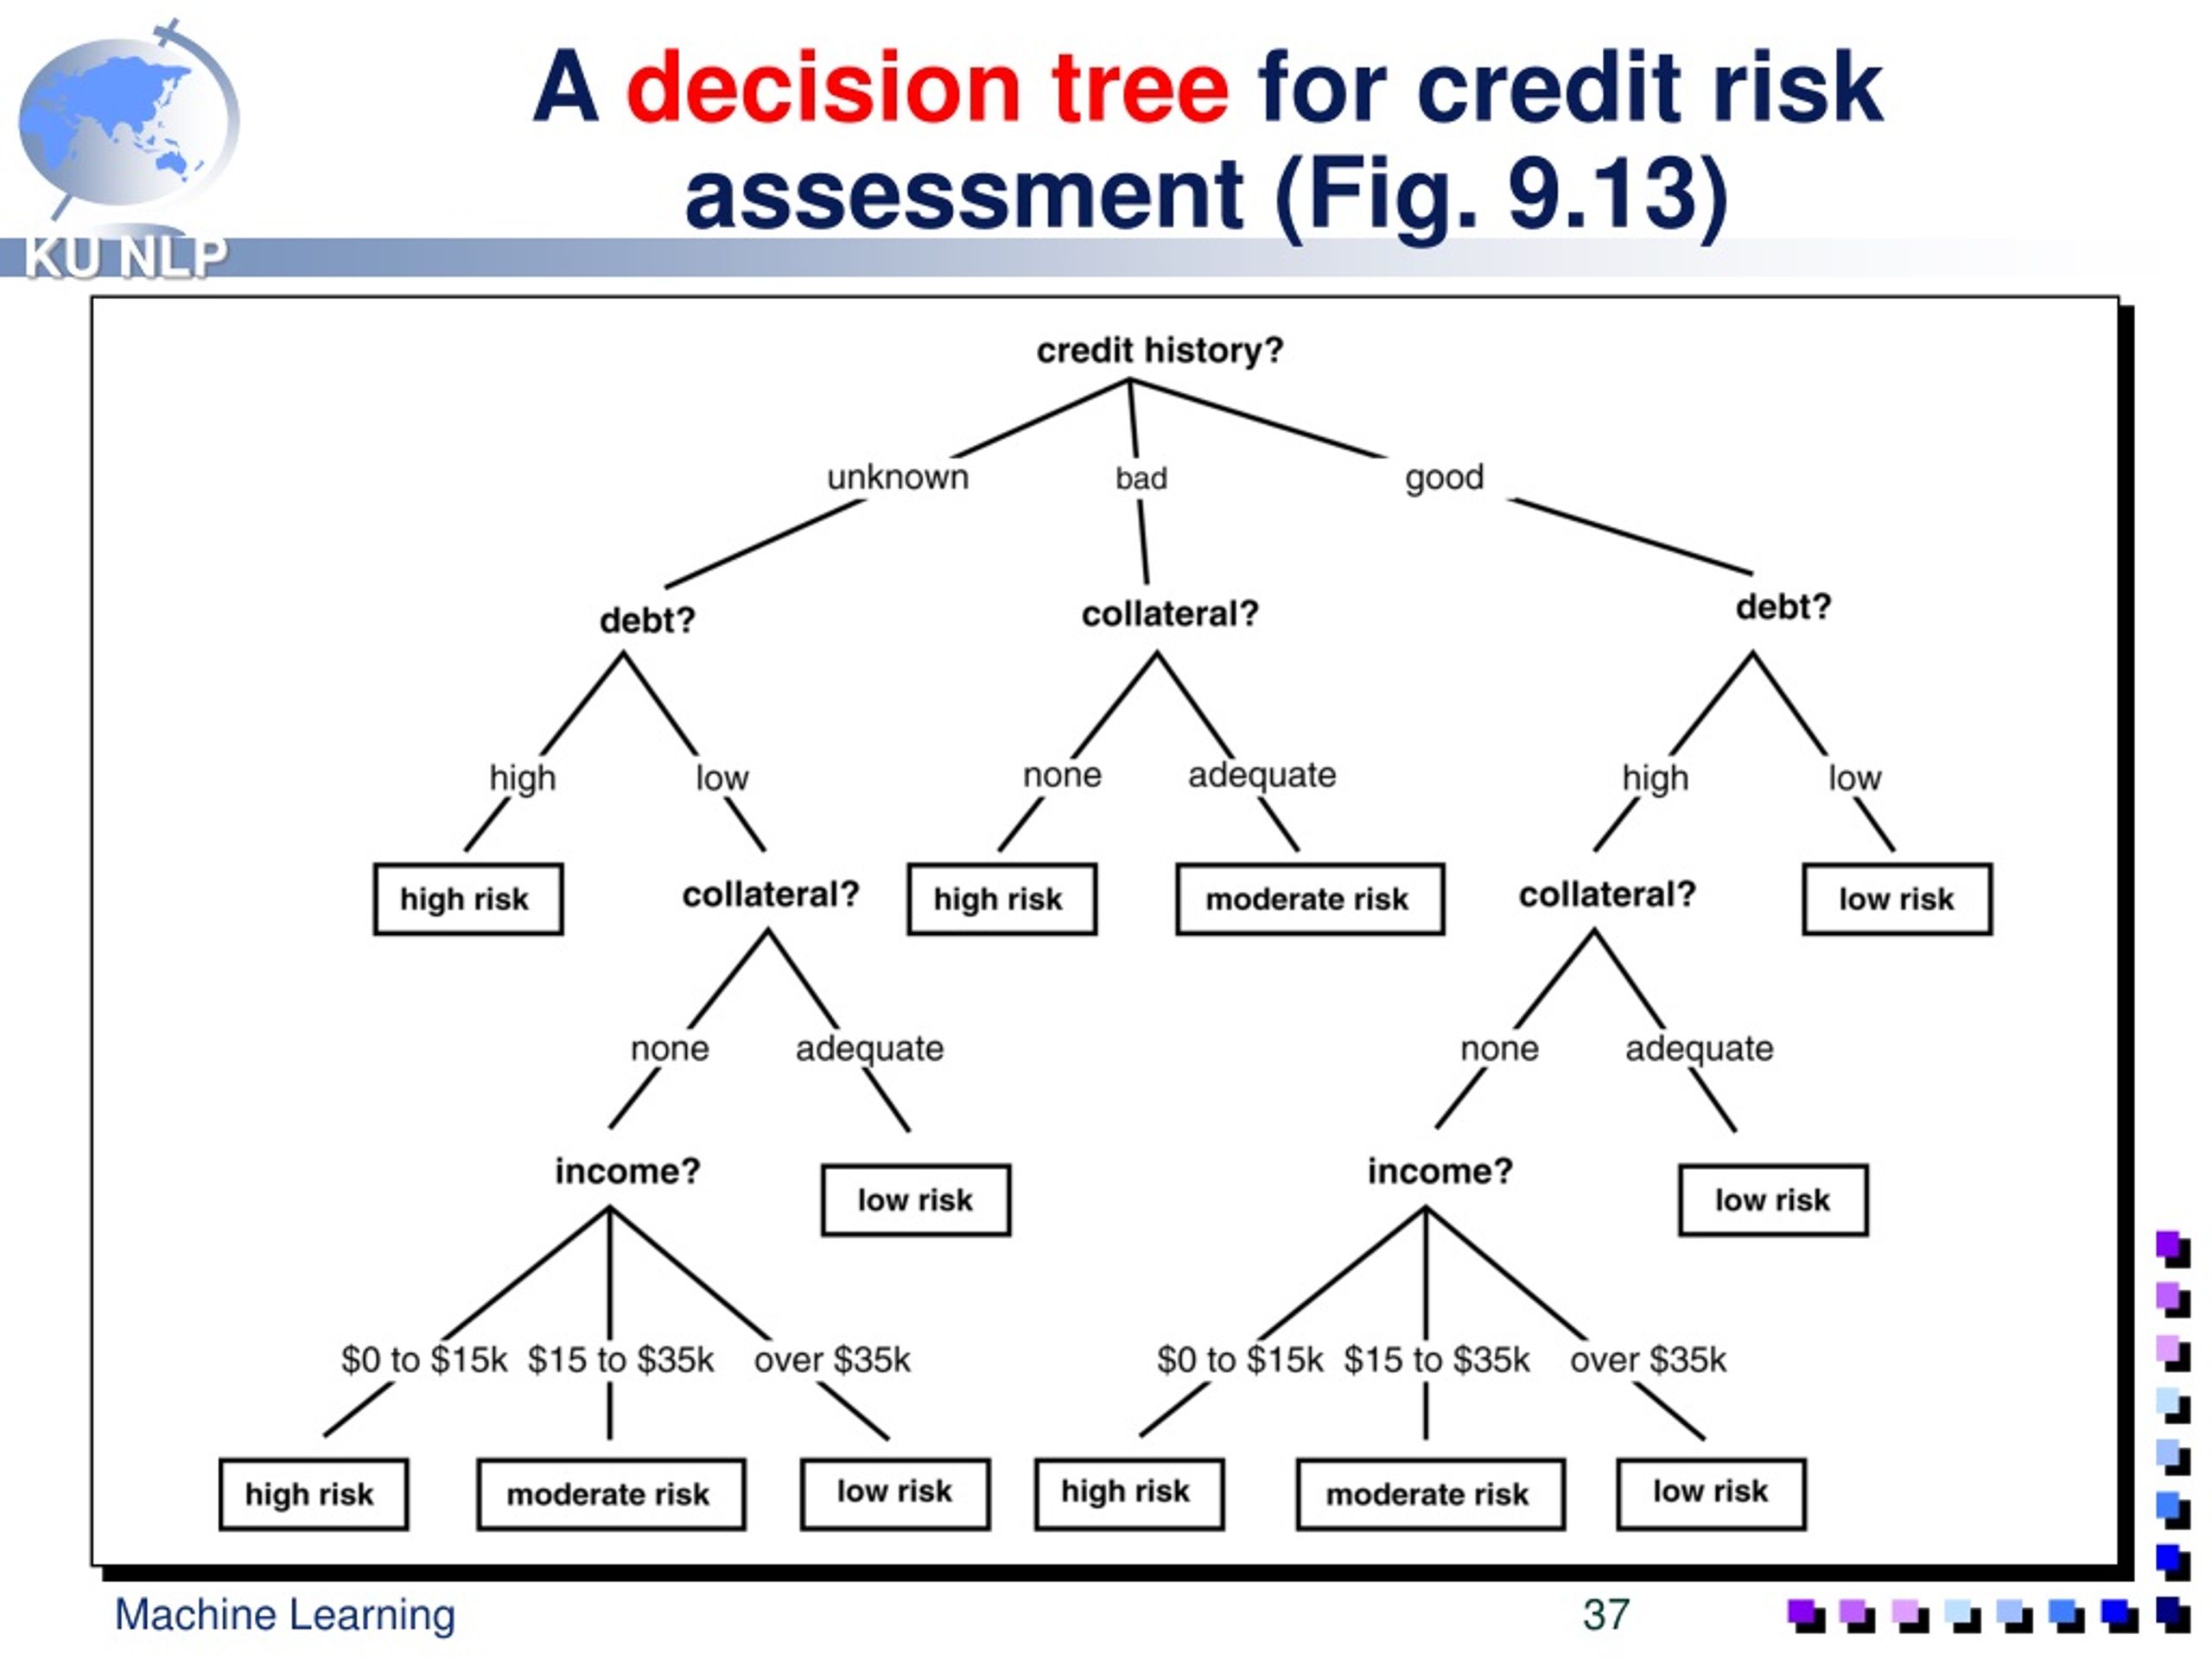
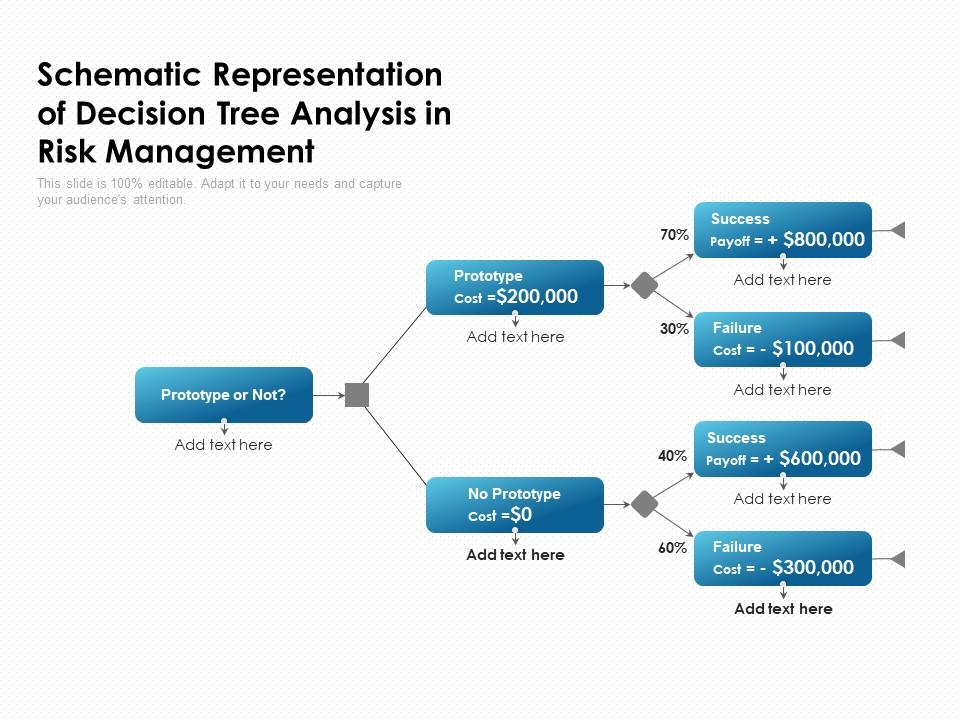
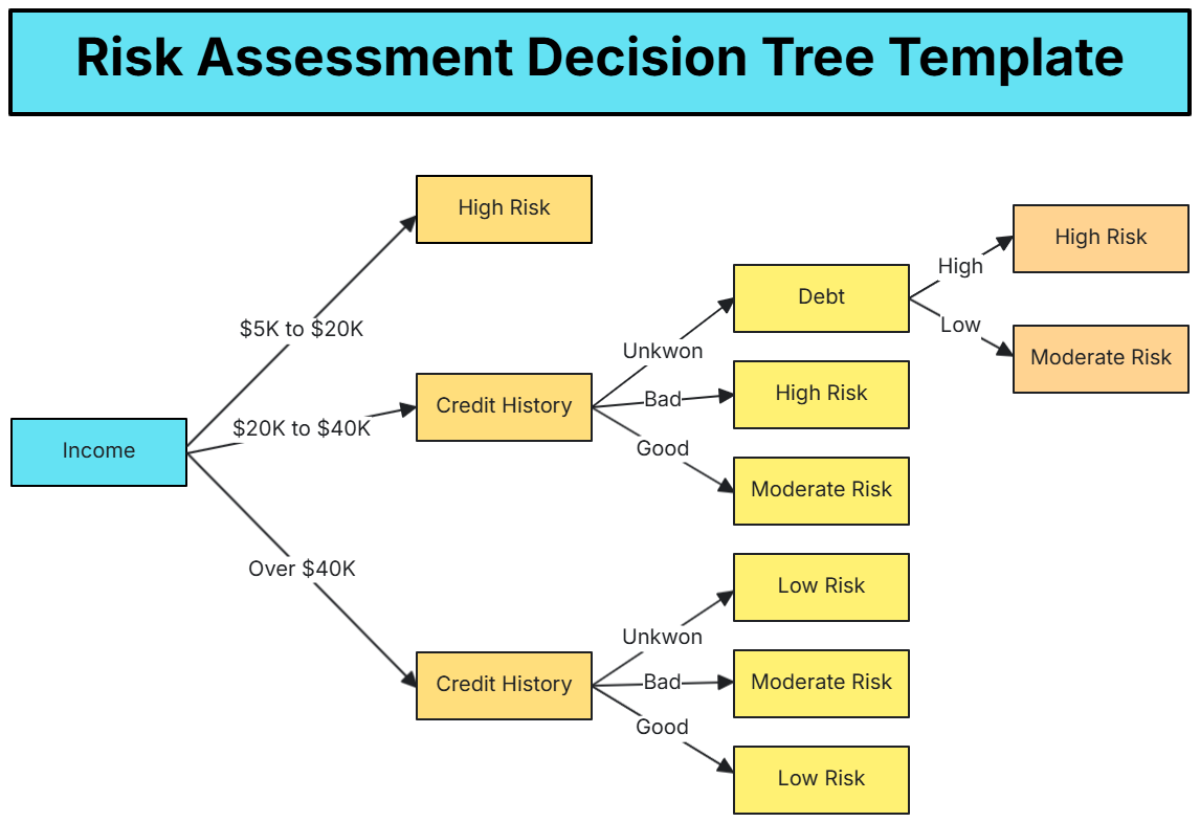
Most people treat risk assessment like it's a one-time checkbox exercise. It isn't. I built and maintained risk decision trees for financial services, healthcare compliance, and manufacturing safety over several years. The ones that actually survive contact with real operations look nothing like the flowcharts you see in textbooks.A Risk Assessment Decision Tree is just a structured way of routing a scenario through a series of yes-or-no questions until it lands on a risk rating and a required action. That's it. Nothing mystical about it. The problem is that most templates are so generic they become useless the moment you try to apply them to anything complicated. Start with the trigger event. That's whatever situation you're assessing risk for. "Third-party vendor breach" or "equipment failure on assembly line" or "unauthorized API access attempt." Don't start with the risk categories. Start with the actual event you're worried about. From there, branch by severity indicators, not by risk types. I've seen too many trees that ask "is data personal?" before "is this happening right now?" Order matters because the sequence determines how fast you can route something to a resolution. A well-ordered tree gets most cases to a decision in three to five questions. A poorly ordered one makes people click through twelve screens before realizing the answer was obvious from the start.
Branch logic should be mutually exclusive and collectively exhaustive. That means every possible path leads somewhere and nothing overlaps. When your branches overlap, you get inconsistent risk scores for the same situation depending on which path the assessor happened to take. This happens constantly in practice. I found it in a vendor risk tree where "data encryption status" and "transit method" both fed into likelihood calculations, and the same vendor got rated "high risk" through one path and "medium risk" through another. Same data. Different answers. That's a broken tree.
What Actually Goes Into Each Branch
Each node needs three things: the question, the answer options, and the downstream result. That downstream result is either another question or a terminal risk rating with an assigned action. Don't skip the action. A risk rating without a required response is just a number. It doesn't change behavior. The answer options should be binary when possible. "Yes or no," "Present or absent," "Controllable or uncontrollable." Multi-choice options introduce ambiguity. "Partial encryption" is not a useful branch point. Either the data is encrypted or it isn't. If it's partially encrypted, that's a separate finding that goes into the evidence log, not a middle-ground branch in your decision tree. I ran into a specific edge case with a healthcare client's Risk Assessment Decision Tree where we were assessing breach notification requirements under HIPAA. The tree had a branch asking whether the breached data was "encrypted per HHS guidelines." The problem was that the guidance had changed six months prior, and our tree still referenced the old standard. Two different risk assessments of the exact same breach produced different outcomes because the definition had shifted. We fixed it by replacing the static reference with a pointer to the current HHS guidance document and adding a field that required the assessor to note which version they were applying. That one change eliminated the inconsistency without restructuring the entire tree.
Get the Full Details

Common Mistakes That Break These Trees
The biggest mistake is treating every scenario as if it needs the same depth of assessment. Not everything deserves a full decision tree traversal. I implemented a triage layer on top of our main tree that routed low-severity, high-frequency events through a simplified path. Instead of running every minor access request through twelve decision nodes, we'd check three quick filters first. If the request came from an internal system, involved non-PHI data, and had a recent compliance audit on file, it went straight to "low risk, standard controls apply." This cut average assessment time from about forty-five minutes to roughly eight minutes for that category of events. Another mistake is building the tree without input from the people who'll actually use it. I once watched a compliance team spend three weeks designing a risk decision tree that ended up being abandoned because the security engineers who would run it daily found the terminology completely disconnected from how they documented incidents. The tree used phrases like "likelihood of adverse occurrence" instead of "past incident history." The engineers didn't know what category that fell under. Simple terminology fixes resolved the issue in an afternoon. There's also a hidden issue with static trees and dynamic threats. A Risk Assessment Decision Tree that you never revisit becomes outdated quickly. Threat landscapes shift, regulations change, your own infrastructure evolves. I've seen trees that were effective for two years then produced unreliable results because the underlying assumptions about threat probability had drifted significantly. The fix is a scheduled review cadence, not a permanent document. Quarterly reviews caught most of the drift in my experience. Annual reviews missed enough that the tree started producing stale risk ratings without anyone noticing.
When a Decision Tree Isn't the Right Tool
Sometimes you don't need a decision tree at all. If your risk scenarios are highly variable with many interdependent factors, a decision tree forces them into false linearity. In those cases, a risk matrix or a scoring model with weighted variables produces more accurate results. I switched one of our assessment workflows from a tree to a weighted scoring system when we started evaluating cloud architecture changes. The dependencies between misconfiguration risk, data exposure, and third-party dependencies couldn't be cleanly routed through sequential yes-or-no branches. A weighted model handled the overlap without breaking. Decision trees also struggle when the number of possible scenarios exceeds roughly fifty distinct paths. Beyond that, maintenance becomes a full-time job and consistency degrades because different assessors interpret ambiguous branches differently. At that scale, you're better off building a knowledge base with search and conditional logic rather than a traditional tree structure.
Where to Get a Risk Assessment Decision Tree Template
There isn't a single download that works across industries. A manufacturing safety tree and a data privacy tree share the same underlying logic but have completely different branch questions and risk ratings. What I can tell you is that a basic structure usually takes between two to four hours to build if you're starting from scratch and have clear scenario definitions. It takes significantly longer if you need regulatory alignment built in from the start. Most organizations end up building their own. NIST and ISO publish frameworks that inform the structure, but they don't hand you a ready-to-use tree. You adapt the framework to your specific risk universe. If you want a starting point, the NIST SP 800-30 risk assessment guide has decision logic you can map directly into a tree format. It's not a template you download. It's a methodology you convert. The practical takeaway is that a Risk Assessment Decision Tree is only as good as its question ordering, its branch clarity, and how frequently you update it. Build it slowly. Test it against actual past incidents to see if it produces the same conclusions your team already reached. Fix the gaps. Then schedule the next review before you forget it exists.