The difference between risk assessment and risk analysis isn't what most people think
I've watched team after team waste weeks going back and forth because they can't agree on whether they're doing an assessment or an analysis. They'll spend hours debating methodology while the actual work stalls. The problem usually comes down to one thing: nobody can articulate where assessment ends and analysis begins in their own framework. Here's how I think about it, and how I've explained it to people who need it to be clear enough to put into a process document.
Risk Assessment Vs Risk Analysis: Where the Line Actually Is
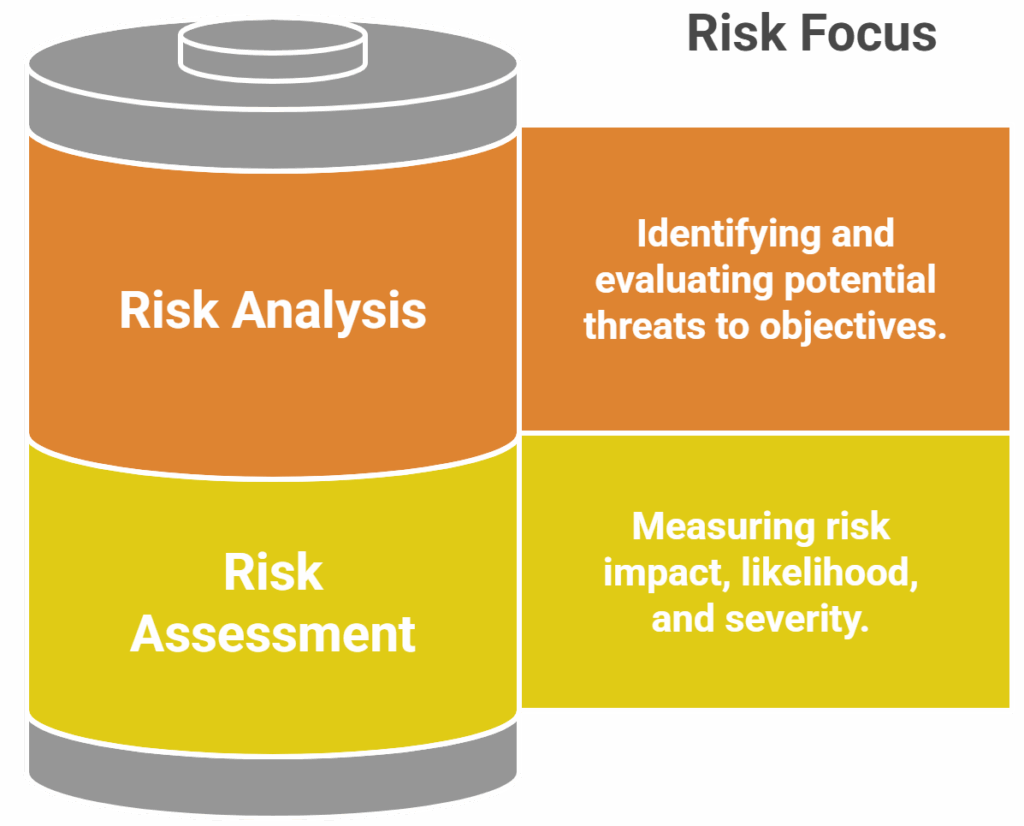
A risk assessment answers the question "what could go wrong, and how bad would it be?" It's broader, more qualitative, and happens first. You're identifying threats, understanding context, and getting a high-level sense of exposure. Think of it as the map you draw before you start driving anywhere. Risk analysis is narrower. It's the work you do after the assessment tells you which risks deserve attention. You're quantifying, modeling, calculating probabilities, running sensitivity tests, and trying to narrow uncertainty enough to make a decision. This is where you put numbers on things that were just descriptions during assessment. The confusion comes from the fact that both involve evaluation. In practice, assessment and analysis often overlap because teams don't have clean phase gates. But if you're writing a procedure and someone asks whether a specific activity belongs in the assessment or the analysis phase, here's the test: if you're still figuring out what the risk even is, you're assessing. If you already know what the risk is and you're measuring it, you're analyzing.
How to actually run both without losing your mind
I've used a method that works consistently across different environments. Start with assessment by listing every scenario you can think of, no matter how unlikely. Don't judge them yet. Just get them on paper or in a spreadsheet. For each one, note three things: what triggers it, what would happen if it occurred, and how likely you think it is on a rough scale of low, medium, or high. Once you have that list, you move into analysis mode. Pick the top five to ten risks from the assessment and give them proper numbers. This means assigning probability ranges, estimating financial or operational impact with actual figures, and running whatever model your organization uses. Monte Carlo simulations work for mature teams. Decision trees are fine for smaller scopes. If you're just starting out, a simple expected value calculation is enough to distinguish significant risks from noise. Here's something most guides won't tell you: the analysis phase should always feed back into the assessment. When you finish crunching numbers on those top risks, you'll likely discover that some of your original qualitative judgments were wrong. A risk you scored as high probability might turn out to be low once you actually estimate it. Document those shifts. That's part of the process, not a sign you did it wrong.
Get the Full Details
A specific problem I ran into
I was working on a data center migration assessment for a client who insisted on jumping straight to quantitative analysis. They had a budget for specialized risk modeling software and wanted to use it immediately. We identified about forty potential risks during assessment, and they wanted to analyze all forty numerically. The problem is that quantitative analysis requires data quality that rarely exists at the beginning of a project. You end up feeding garbage numbers into a sophisticated model and getting garbage back with fancy decimal places. The workaround was to categorize the forty risks into three buckets first. Tier one risks were things we already had solid historical data for, like hardware failure rates from vendor documentation. Tier two risks needed expert judgment but we could estimate with reasonable confidence. Tier three risks were largely unknown unknowns where any number would be essentially made up. We ran full quantitative analysis only on tier one, used a hybrid approach for tier two, and kept tier three purely qualitative throughout. That saved roughly eighty percent of the analysis time while giving us actionable results for the risks that actually mattered.
Counter-intuitive things beginners miss
One thing that surprises people is that a thorough risk assessment can sometimes produce fewer actionable insights than a rushed one. The reason is that comprehensive assessments tend to generate large lists of low-severity risks that consume attention without improving decision-making. When I review assessment outputs, I look for the ratio of significant risks to total risks identified. If it's lower than about one in five, the assessment is probably over-scoped and generating noise rather than signal. Another thing: most organizations treat risk analysis as a documentation exercise rather than a decision tool. They produce a risk register with calculated scores and file it away. But a risk analysis that doesn't directly influence budget allocation, scheduling, or scope decisions is just expensive report writing. Every number you calculate should connect to at least one decision that someone has to make. If it doesn't, you've wasted time.
When these methods fail
Let me be blunt about the limitations. Quantitative risk analysis breaks down in environments where historical data is absent or unreliable. This happens frequently in projects involving new technology, novel processes, or regulated industries with limited comparable cases. In those situations, the confidence intervals become so wide that the numbers are essentially meaningless. Monte Carlo outputs might look impressive with their probability distributions, but if your input distributions are guesses, your output distribution is just a well-dressed guess. Qualitative assessment has its own failure mode. It's highly dependent on the experience and bias of whoever is doing it. I've seen assessments where a senior engineer's personal fears inflated certain risks far beyond what the data supported. Conversely, teams with nothing but positive experience tend to systematically underestimate risks they're familiar with. The structured nature of both methods helps but doesn't eliminate this. If you're dealing with genuinely uncertain environments where both data and expertise are thin, neither approach works well on its own. The alternative is to lean heavily on scenario planning and stress testing rather than trying to assign probabilities to events that are impossible to forecast. This means defining a small number of coherent future states and testing how your plans hold up in each one, instead of trying to calculate expected values for everything.
The practical takeaway
Assessment comes first and stays wider. Analysis follows and goes deeper on selected items. They feed each other throughout the lifecycle of whatever you're working on. Most of the time the bottleneck isn't understanding the concepts, it's knowing when to stop assessing and start analyzing. The rule I use is simple: when you have enough understanding of a risk to estimate it numerically with any confidence, move it to analysis. When you're still trying to figure out what the risk is, you're still assessing. Neither process eliminates risk. They just make it visible enough to decide whether to accept it, mitigate it, transfer it, or avoid it. The goal isn't to produce a perfect risk model. The goal is to produce enough clarity that your next decision isn't a guess.