Breaking Down Risk Management Controls Types Without the Fluff
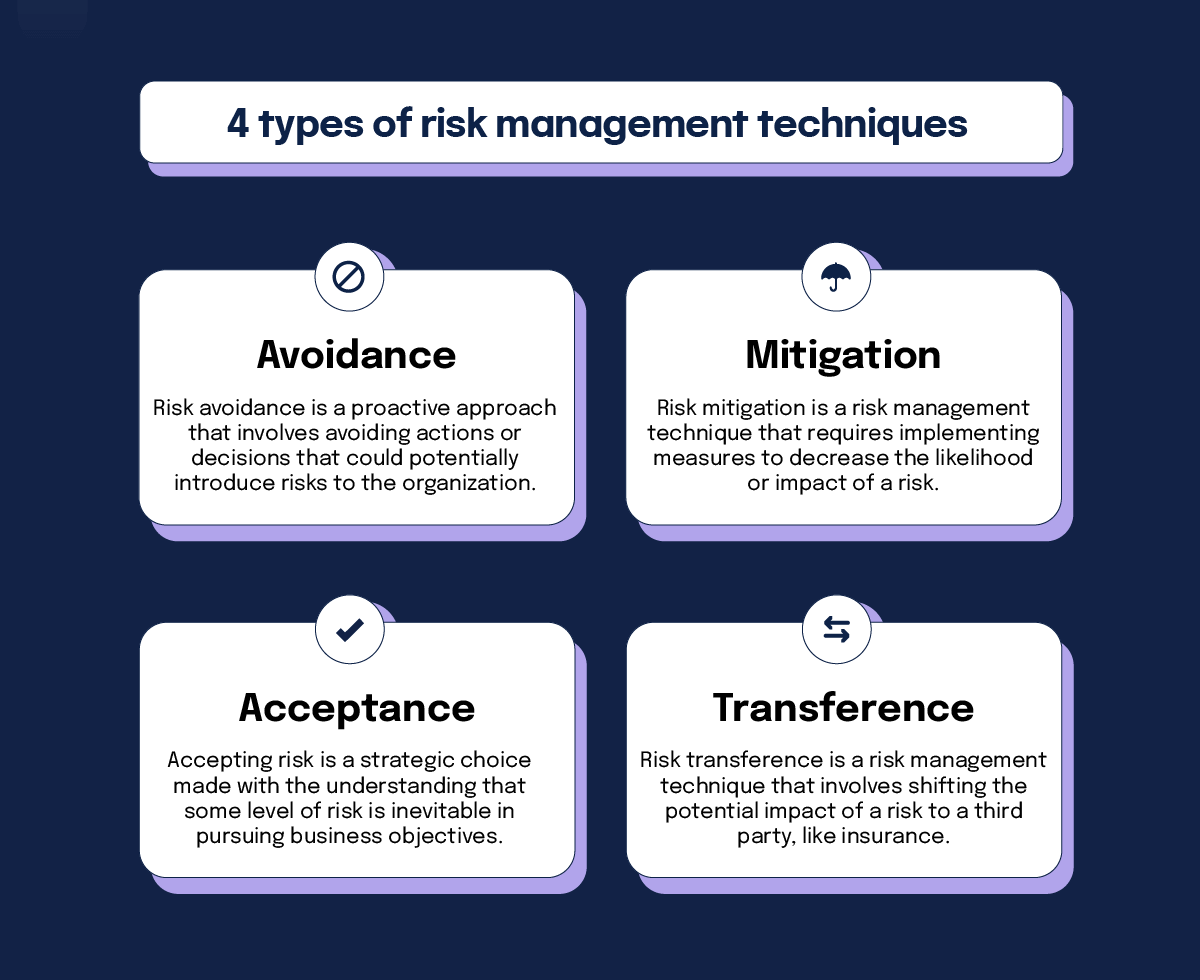
Most people treat controls like a checklist. They pick the shiny ones from a vendor brochure and call it done. That approach leaves gaps. I've spent years watching organizations implement controls that looked good on paper and failed when a real incident hit. The reason is usually that they never stopped to think about what each control is actually for. There are four main Risk Management Controls Types that show up in practice, and they're not interchangeable. Using the wrong one for a given risk is like putting a lock on an open window. The door gets secured but nobody checks the window.
Preventive Controls — Stopping Things Before They Happen
Preventive controls are the ones most people reach for first. Access controls, encryption at rest, MFA, change management processes, firewall rules. They're designed to stop an event from occurring in the first place. The logic is sound but incomplete on its own. I worked on a project where we implemented strict preventive controls across a banking client's environment. We locked down user access, enforced encryption everywhere, deployed DLP tools, and hardened every server. Six months later, a junior developer pulled production data through an API endpoint that wasn't in scope. The preventive controls hadn't been mapped to that endpoint because it was considered "low risk." The data walked right out. Preventive controls only protect what you've explicitly accounted for. They leave blind spots wherever your inventory is incomplete. The hard truth: you can never fully inventory everything in a complex environment. Networks grow. Shadow IT appears. APIs multiply. Relying solely on preventive controls gives you a false sense of security. The controls exist, but the risk map is outdated the day you finish building it.
Detective Controls — Finding What Slipped Through
Detective controls exist because preventive controls alone aren't enough. SIEM systems, log monitoring, intrusion detection, periodic audits, anomaly detection models. These don't stop anything. They tell you something happened after the fact. The value is in speed of detection and quality of the signal. Here's what most people get wrong about detective controls: they assume more data means better detection. In practice, alert fatigue is the real problem. A well-tuned SIEM that generates 50 actionable alerts per day is worth more than a noisy one generating 5,000. I once spent three weeks tuning a detection rule that kept firing on legitimate admin activity. The underlying issue wasn't the tool—it was that the baseline behavior of that particular admin group had drifted over two years and nobody had updated the correlation logic. Detective controls also have a timing problem. Detection latency matters. Finding a breach in 48 hours versus 48 seconds makes a massive difference in containment cost. Most organizations measure how much they spend on detection tools but rarely track their mean time to detect. That metric is what actually separates a manageable incident from a boardroom-level event.
Get the Full Details
Corrective Controls — Fixing What Detective Controls Found
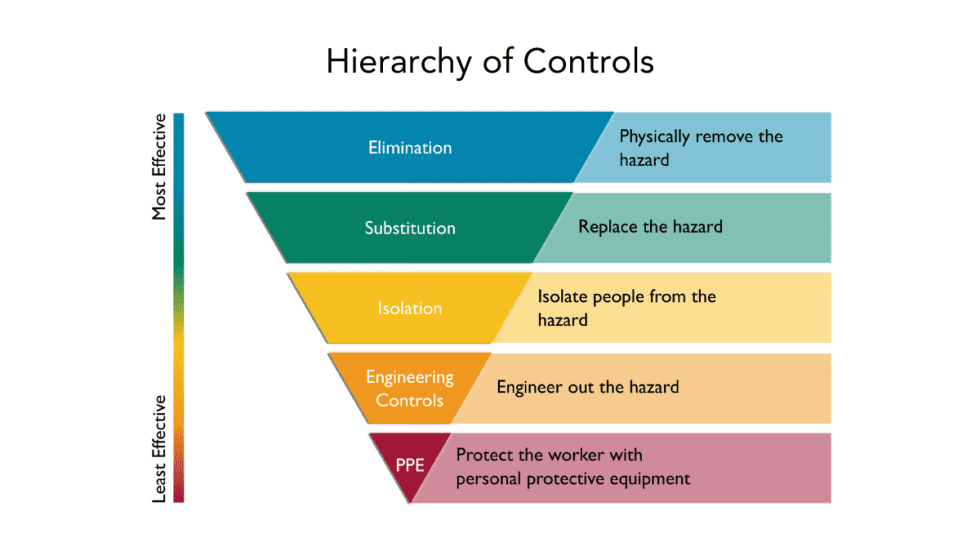
Corrective controls are the least discussed but often the most critical. Incident response playbooks, backup restoration procedures, failover mechanisms, patch deployment workflows, remediation runbooks. These kick in after detection confirms something went wrong. The goal isn't prevention or discovery. It's restoring normal operations and reducing damage. I saw an organization that had excellent preventive and detective controls but no functional corrective controls. When a ransomware attack hit, their detection team identified the threat within minutes. Their response team had no documented procedure for containment. They spent four hours debating whether to isolate the affected segment or shut down the entire network. By the time they decided, the lateral movement had spread across three production environments. The incident lasted 72 hours total because the corrective side was never exercised or tested. Corrective controls need to be practiced. A backup that hasn't been restored in a drill is just data sitting on a disk. An IR plan that's never been walkthroughed is fiction. I recommend running tabletop exercises quarterly at minimum, with actual failover tests twice a year. This usually takes about 2-3 hours per session but surfaces gaps that no amount of planning catches on paper.
Compensating Controls — When the Perfect Control Isn't Possible
Compensating controls are the ugly siblings of the group. They exist when you can't implement the ideal control due to technical, operational, or budgetary constraints. An older system that can't support encryption at rest might instead use network segmentation and strict access lists to achieve an equivalent level of protection. A legacy application without native MFA might sit behind a reverse proxy that enforces it. The problem with compensating controls is that they become permanent without ever being questioned. I've seen compensating controls that were put in place five years ago, meant to last six months, still running today because nobody bothered to reassess. They create a false impression of coverage. The original risk may have evolved, but the compensating control sits there looking like it's doing real work. Compensating controls need a sunset clause or at least an annual review. Document why they exist, what risk they're compensating for, and when you plan to implement the primary control. If the primary control is never coming, document that decision and have it reviewed by someone who wasn't involved in the original choice. That second pair of eyes usually spots the assumptions you've gone numb to.
The Real Problem Nobody Talks About
The biggest issue I see isn't that organizations don't understand these four types. It's that they implement controls in isolation without mapping them to specific risks. A control without a risk owner is just an expense line item. The control might work technically but it doesn't actually reduce the risk you're trying to manage. Every control should trace back to a risk statement. That risk statement should tie to a business objective. When you lose that chain, controls become performative. Auditors check them off, but the actual risk landscape hasn't moved. Counter-intuitively, having fewer well-mapped controls is almost always better than having many unmapped ones. A thin set of controls with clear risk ownership and measurable effectiveness beats a thick set that nobody can explain under pressure. I've seen teams cut their control count by 60% and improve their overall risk posture because they removed the fluff and focused on what actually mattered.
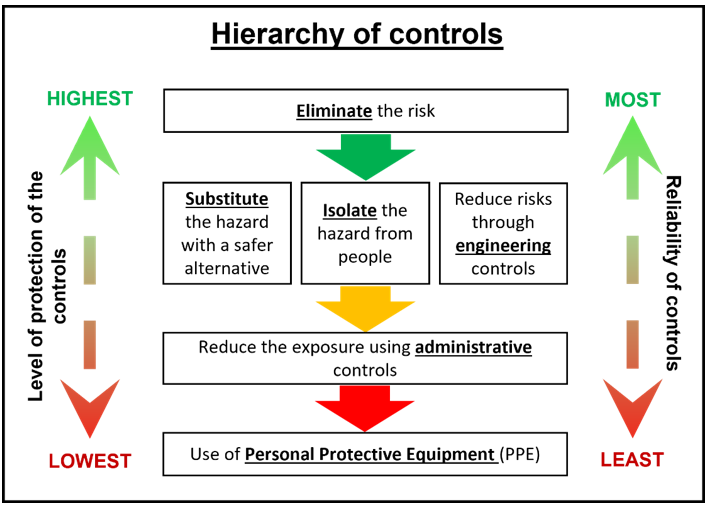
Another thing beginners miss: controls interact with each other. Adding one control changes the risk profile in ways that may require adjusting others. A new access control might make your audit logging less useful if it changes how user sessions are recorded. A compensating control for encryption might increase your detection burden because the traffic pattern changes. Controls are not independent. They form a system, and the system has emergent properties you need to account for. Finally, the downside of any control framework is that it creates a ceiling on your maturity. Organizations that treat controls as a static thing to "complete" stop looking for new risks. The framework becomes a comfort blanket rather than a living tool. The best risk programs I've worked with treat their control framework as incomplete by design. They expect to find gaps. They budget for it. They build the process of finding and fixing those gaps into their routine rather than treating it as a special project. If you're building or reviewing your control framework, start by listing your top five risks. Map each existing control to one of them. If a control doesn't map to anything, question whether it should exist. If a risk has no controls covering it, that's your next priority. Simple process. Hard to execute consistently because leadership tends to fund the controls that look impressive rather than the ones that matter.