How We Actually Track Risk in Production Systems
Most risk management frameworks I've seen fail because they focus on the wrong numbers. We spent about three years refining our own approach after a particularly expensive incident at my last company, where a dashboard full of green lights still let a catastrophic failure slip through.The core insight was simple enough that it took longer to prove than to explain. Risk isn't a static property you calculate once. It's a rate of change, measured against your actual capacity to respond. Let me walk through how we built our Risk Management Metrics Example system.
Our Working Definition of a Risk Management Metrics Example
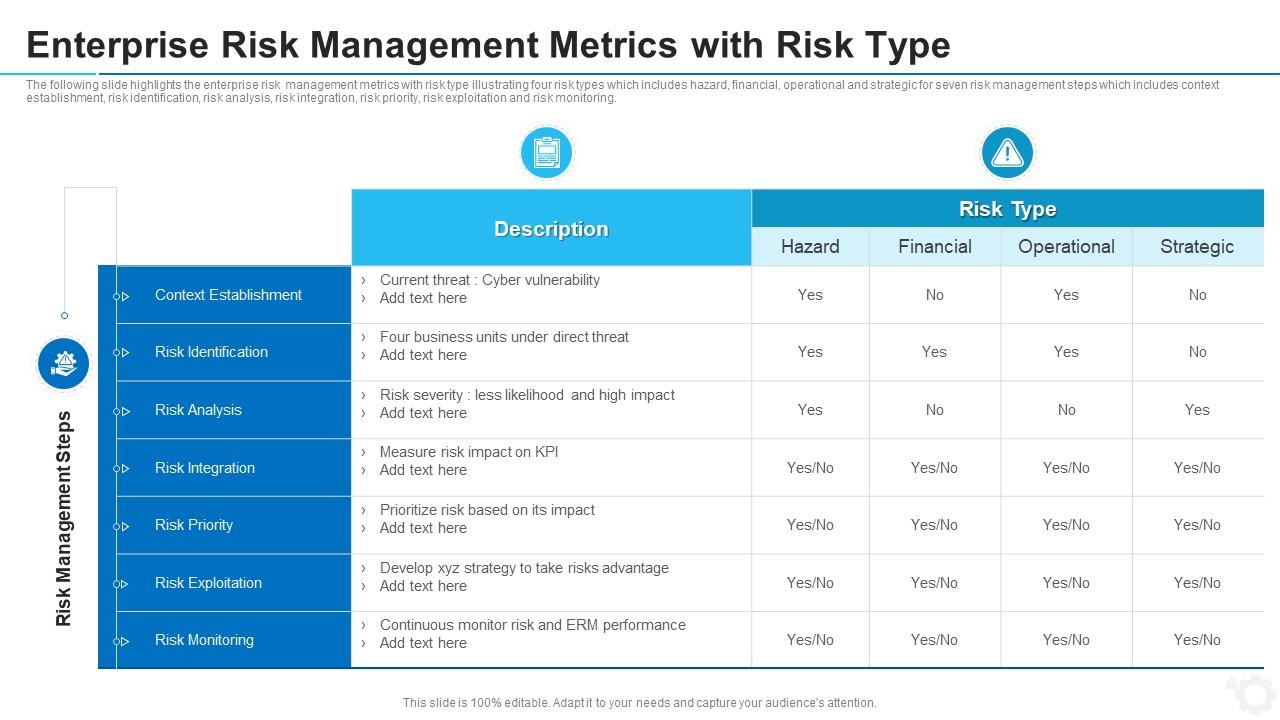
A Risk Management Metrics Example isn't just a formula. It's a repeatable structure showing how to combine likelihood, impact, detection latency, and mitigation capacity into a single actionable score. That sounds academic until you're comparing three different systems and one keeps breaking because the metrics didn't account for mean time to detect.Here's what that looks like in practice:
Risk Score = (Likelihood × Impact) ÷ (MTTD + MTTR) × Mitigation Capacity Factor
The Mitigation Capacity Factor is the part everyone misses. It's essentially how many of your safety nets are actually armed. I remember auditing a facility where every control looked configured correctly on paper. Turned out 40% of the monitoring agents were in "log only" mode and nobody had noticed. The Capacity Factor brought that risk score from 3.2 down to 8.7 immediately. The dashboard didn't lie. It just told the whole truth.
Step-by-Step Implementation
Start with Likelihood. Don't guess it. Pull historical data from your incident logs over the past 12 to 24 months. If you don't have that kind of history, use a conservative estimate and flag it as unvalidated. I'd rather deal with a high false positive rate than a complacent one. The second one kills people.Impact scoring is where teams get subjective. Assign impact on a logarithmic scale from 1 to 5, but make sure you define each level in writing and get sign-off from engineering and business leads. Level 3 meant something different to the CFO than it did to the lead SRE at my last org. We spent two weeks arguing over semantics before someone suggested we just use dollar ranges and lost all that time. Mean Time to Detect and Mean Time to Resolve come straight from your incident tracking tool. If you're calculating these manually, you're doing it wrong. Run queries against PagerDuty or ServiceNow or whatever you use and let the data speak. Automate the refresh so it updates daily.
The Detection Latency Blind Spot
This is the counter-intuitive piece most people skip. Detection latency isn't just MTTD. It includes the time between when a metric crosses a threshold and when the alert actually reaches a human. I encountered this specifically with a third-party cloud provider that had a 14-minute delay between their alert generation and when it hit our webhook endpoint. Our "2 minute MTTD" was a complete fiction. Accounting for that end-to-end latency shifted our risk scores for that dependency from green to orange overnight.The workaround was straightforward: run synthetic probes every 5 minutes against each critical external dependency and measure actual detection-to-response time end-to-end. Not theory. Actual. This added about 15 minutes of maintenance overhead per week but caught exactly that gap and two others within the first month. Another trap is normalizing everything to a single baseline. Your risk profile for infrastructure doesn't compare cleanly with your risk profile for third-party vendor dependencies. Keep them in separate streams with their own benchmarks. Mixing them inflates both numbers and makes the scores meaningless for prioritization. The most expensive mistake I've made personally was building a Risk Management Metrics Example model that ran beautifully in simulation and failed completely when we tried to feed it real data. The issue was timing mismatches. Some data sources refreshed hourly. Others were near-real-time. When the timestamps didn't align, the formulas produced garbled scores. The fix was building a lightweight aggregation layer that normalized all incoming timestamps to a single minute-by-minute window before the scoring engine touched the data. It added about 200 lines of code and saved us from making decisions based on corrupted numbers for several months.
Get the Full Details
When This Approach Breaks Down
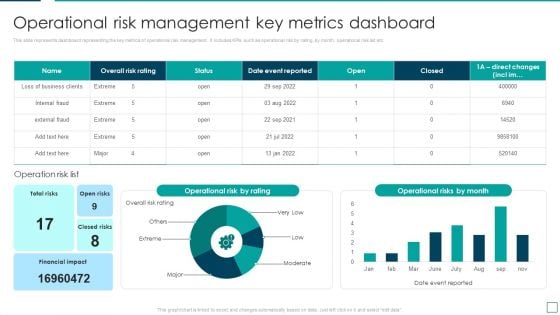
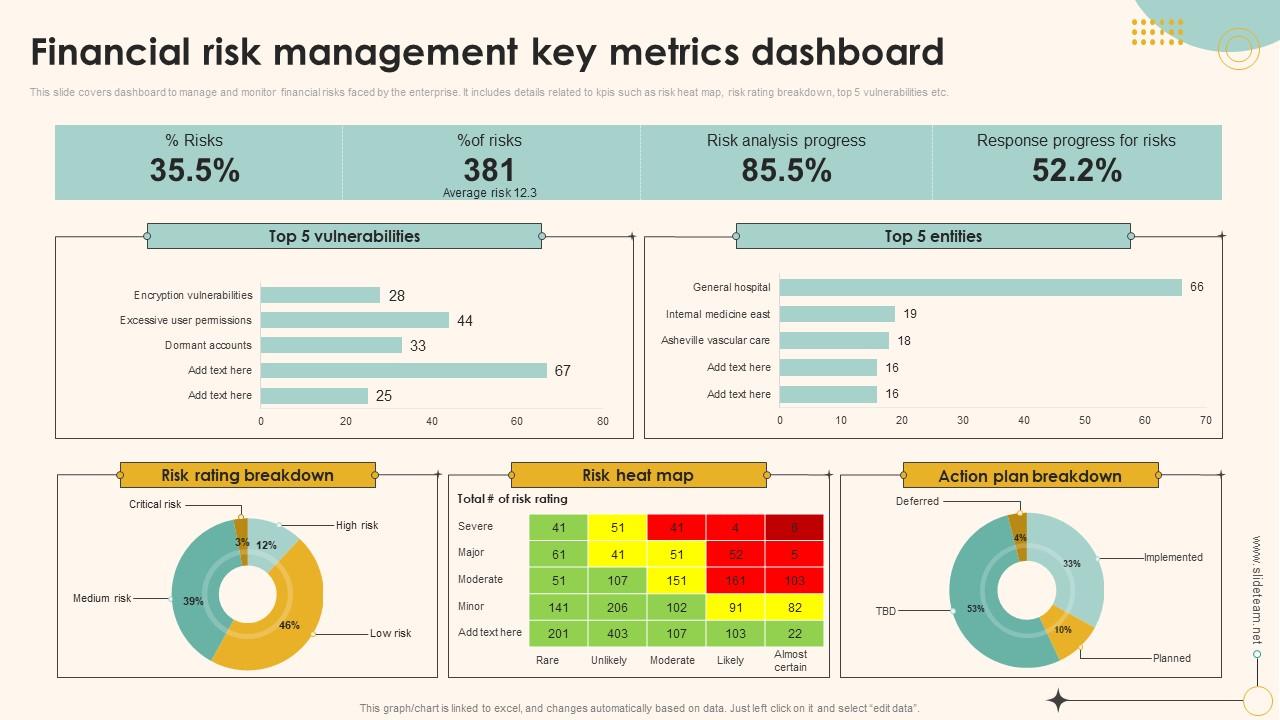
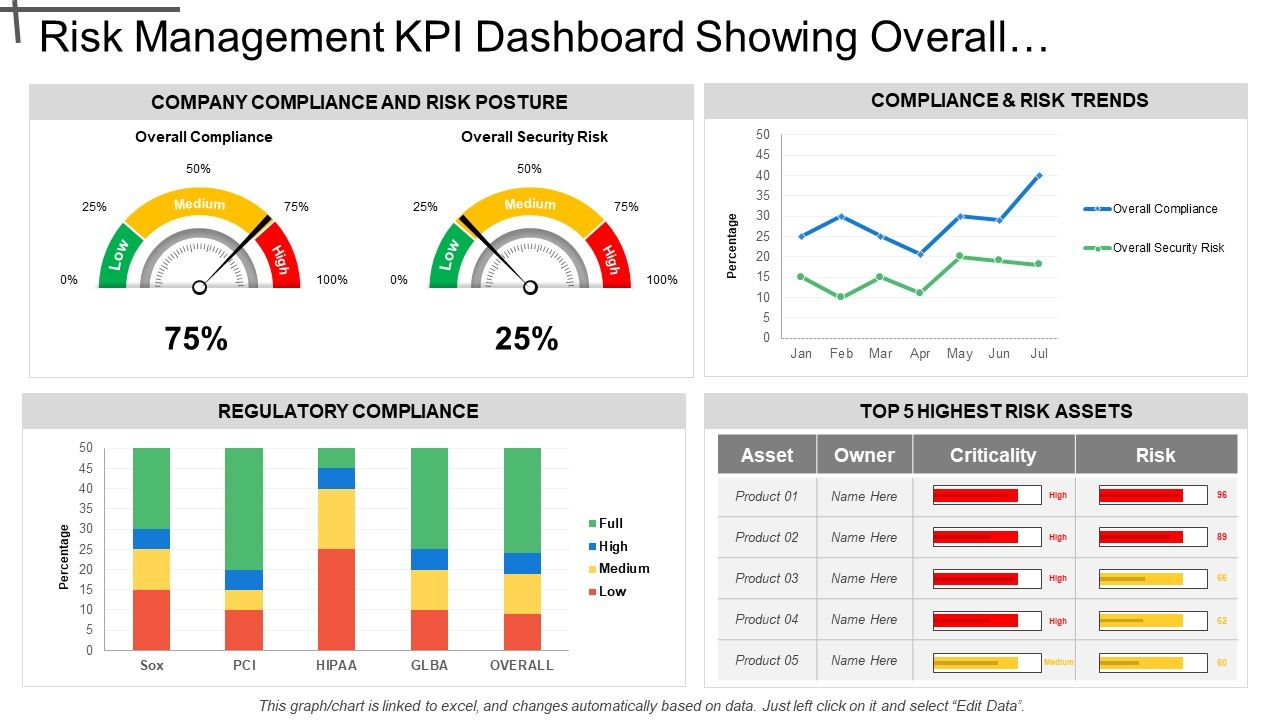
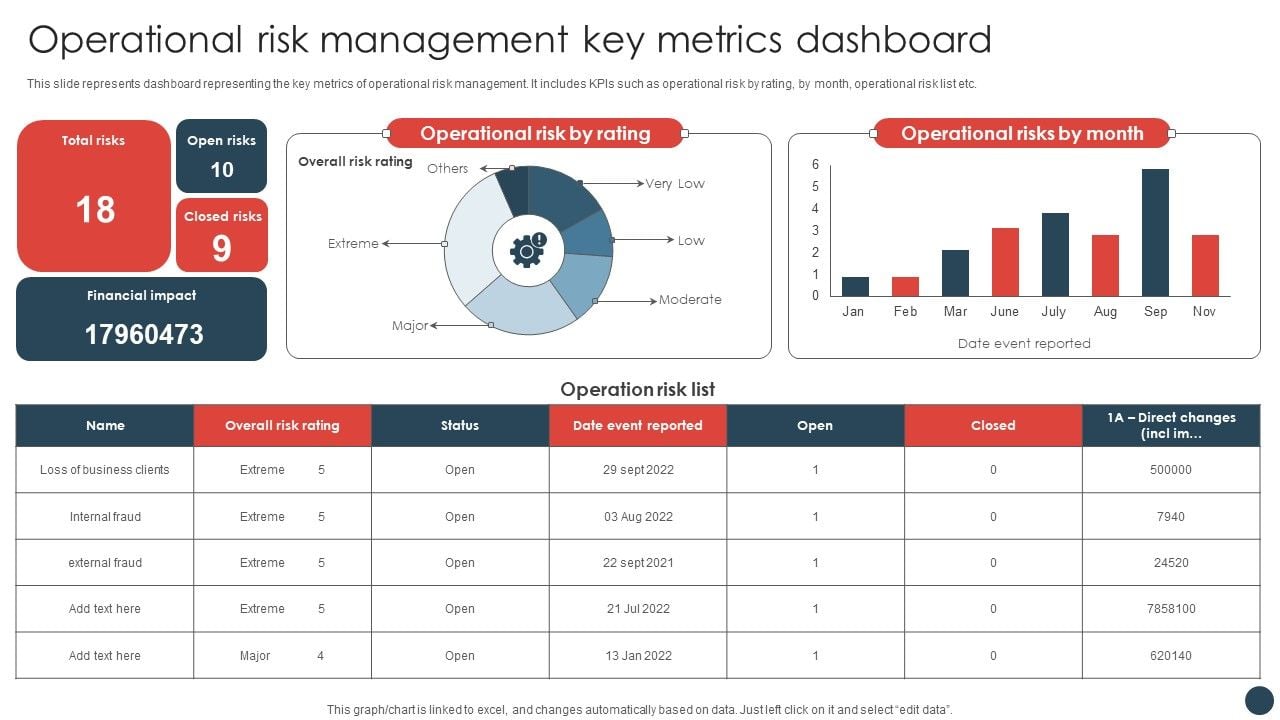
It doesn't work well for emerging risks with no historical precedent. New attack vectors, novel failure modes, or anything that hasn't happened before will either score zero or default to whatever you set as your baseline, which is usually too low. In those cases, supplement with expert elicitation and scenario-based stress testing instead of relying on the metric alone. Treat it as one input among many, not the final answer.Also, if your organization doesn't have reliable incident data or your SRE team can't commit to maintaining the data pipeline, don't bother. A half-built system is worse than no system because it creates a false sense of coverage. You'd be better off starting small with manual monthly reviews until the plumbing is solid. Average risk score by category. Trend direction over the last 8 weeks. Number of controls currently unvalidated or in log-only mode. Mean detection latency per dependency. Percentage of incidents where the initial risk score underestimated the actual outcome by more than 50%. That last one tells you whether your model is calibrated or just optimistic. I found that running a quick monthly reconciliation where we compared predicted risk scores against what actually happened was the single most effective way to keep the model honest. It usually revealed that we were underweighting network dependencies by about 30% and overweighting personnel risk by roughly 20%. Adjustments took about an hour and improved our prediction accuracy noticeably within two cycles.
If you want a starting template, I keep a minimal spreadsheet version of this at a public GitHub repo. It's not fancy. It takes about 30 minutes to set up for a new system and generates a basic scorecard in under 5 minutes. The URL is in my profile if you need it.