What Actually Happens When You Build a Risk Model
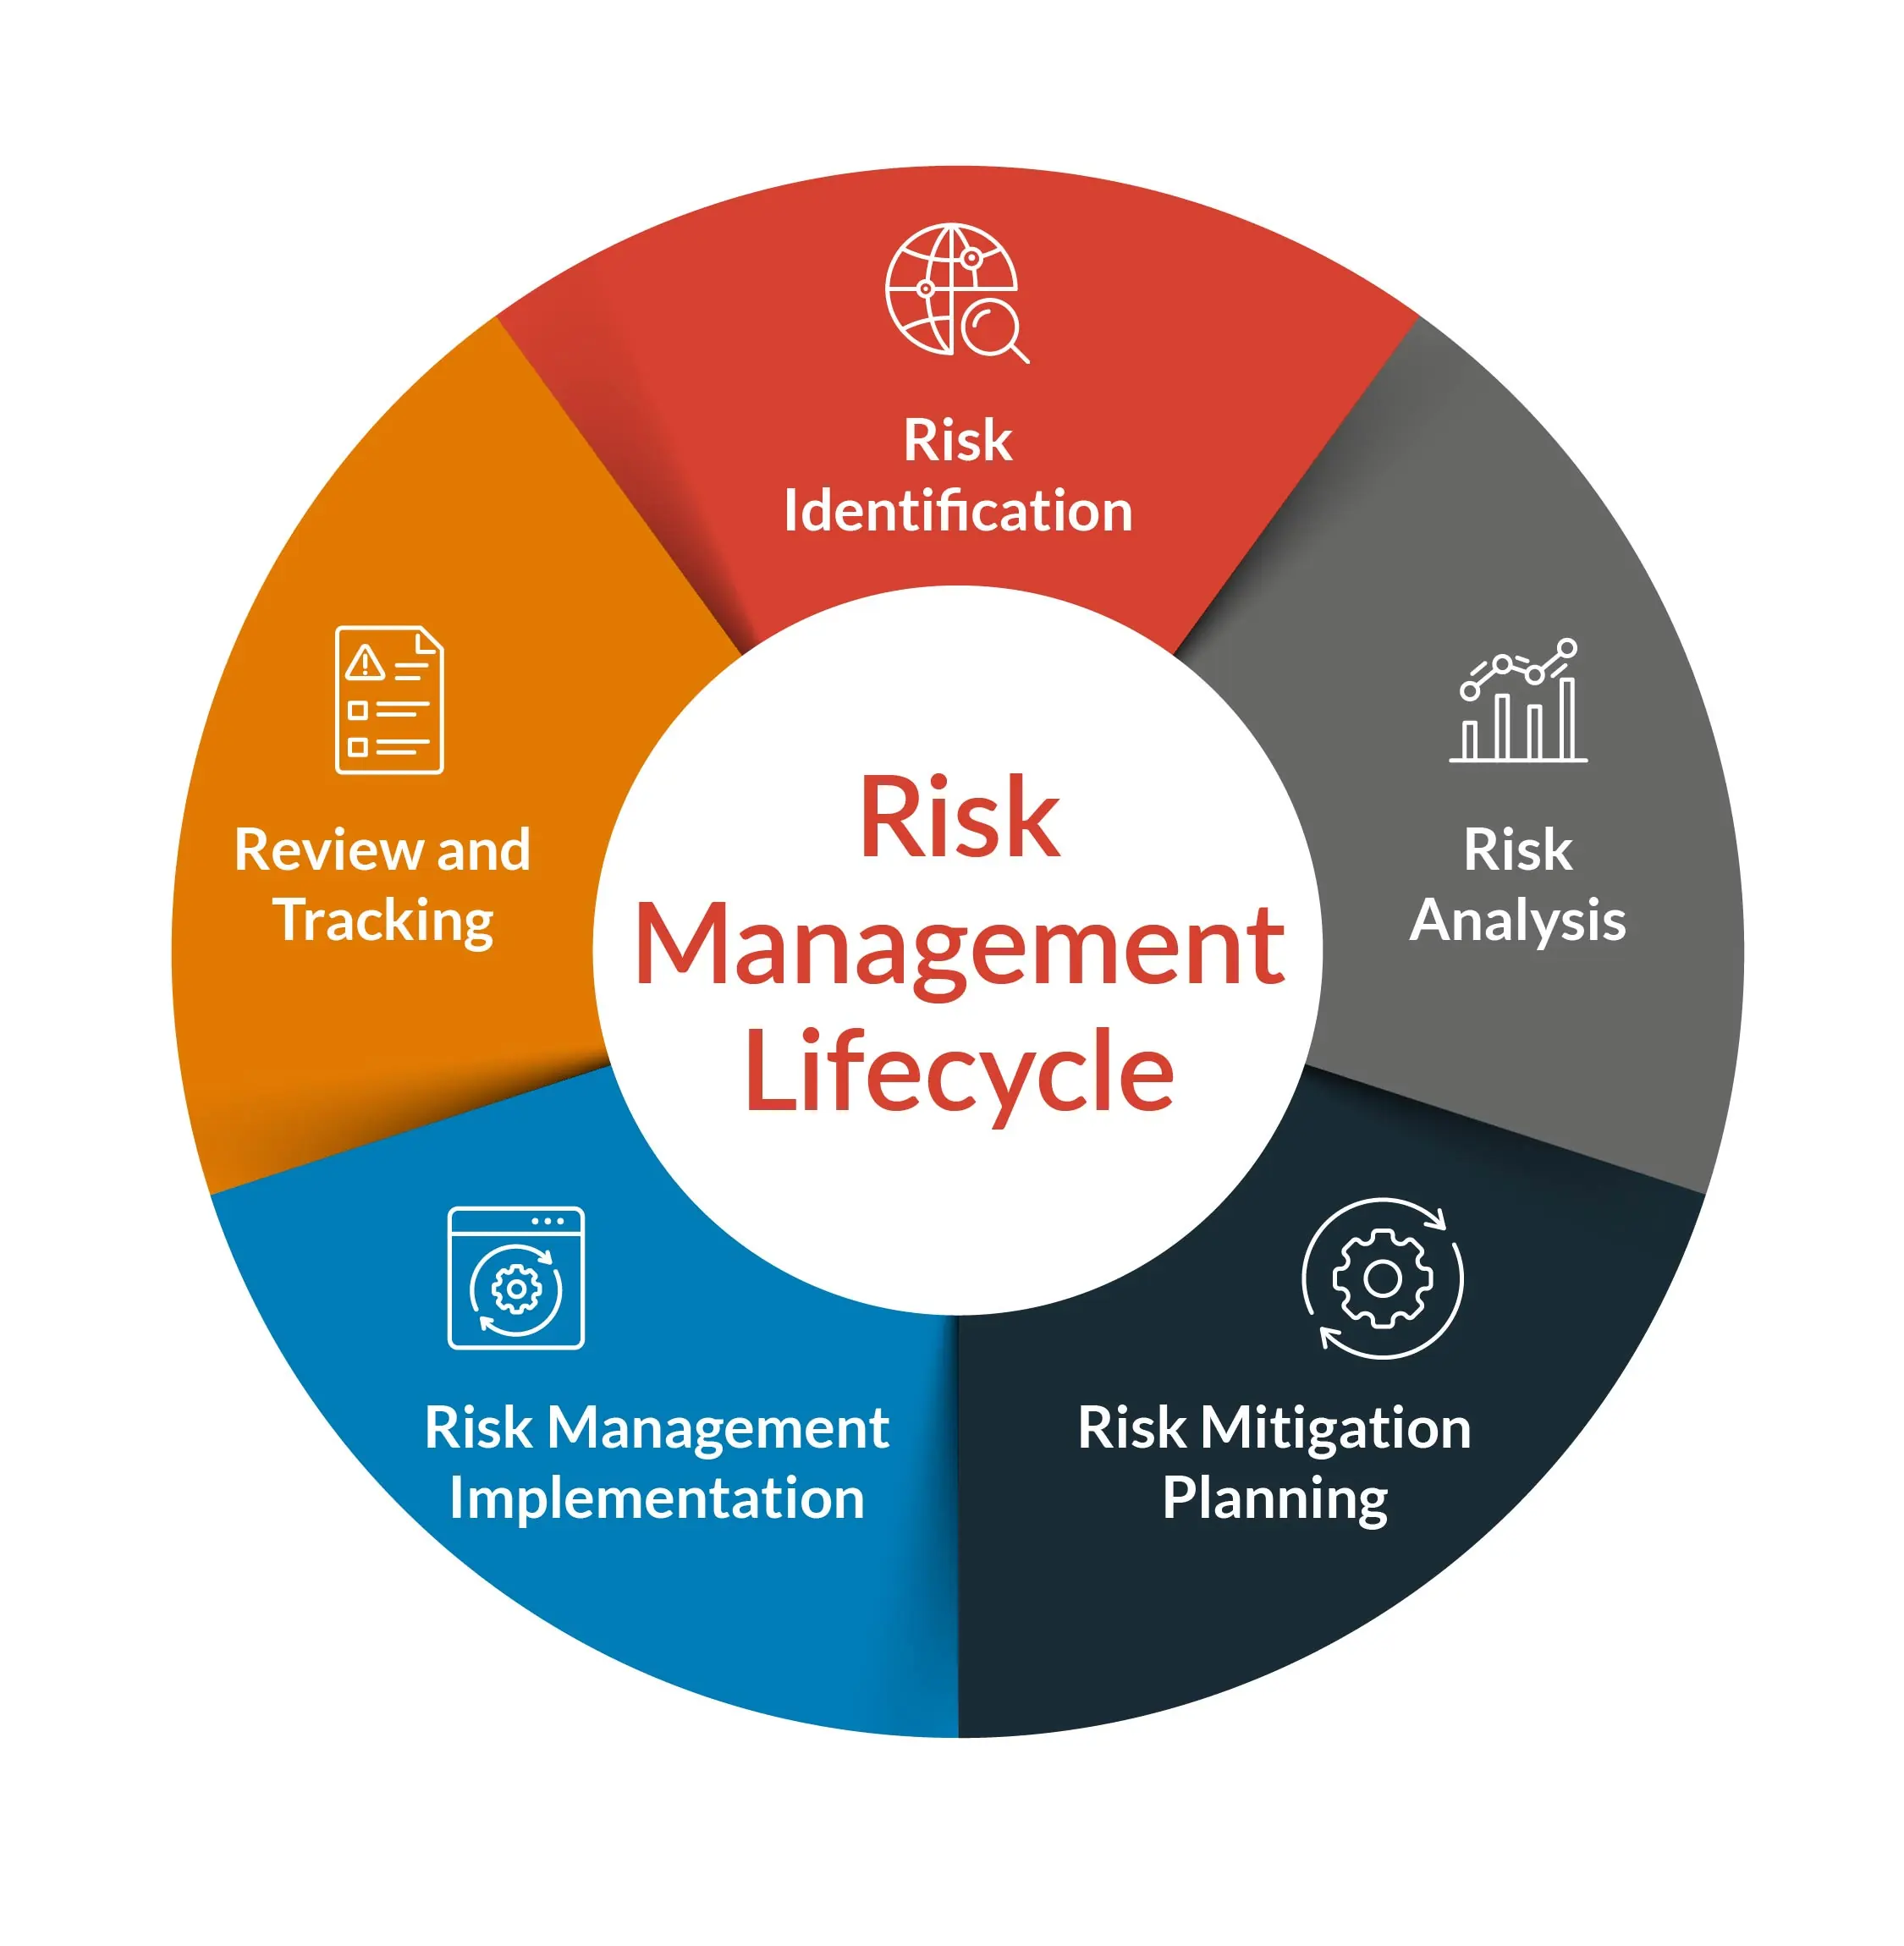
I still remember a portfolio we were modeling for a mid-market credit fund. The VaR numbers looked fine on paper. Then we hit a market stress scenario where two apparently uncorrelated asset classes moved in lockstep because of a third factor neither of us had adequately weighted. The model underestimated tail risk by roughly 30%. That was the year I stopped trusting any single model output without running at least two alternative calibration approaches first. Risk modeling isn't one tool. It's a stack of decisions about what to measure, how to measure it, and how to handle the gap between your model and reality. Most practitioners break it into four stages: data preparation, model specification, validation, and ongoing monitoring. Each stage has specific failure modes that compound if you skip them. Data preparation is where the most damage happens silently. Missing values, survivorship bias in backtests, and stale correlation matrices are the usual suspects. A common approach is to use historical simulation with a rolling window of 2-3 years for liquid assets and longer windows for less liquid instruments. The window length matters more than people admit. Shorter windows catch recent regime shifts but produce noisy estimates. Longer windows smooth noise but blind you to structural breaks.
Model specification means choosing between parametric and non-parametric approaches, deciding on distributional assumptions, and selecting the right risk metric. Value at Risk remains the most widely used metric despite its well-known flaws. Expected Shortfall has gained traction after regulatory shifts, particularly under Basel III. The choice between them affects capital allocation and can change trading decisions by meaningful margins. Validation is the stage most teams rush through. Stress testing, backtesting, and benchmarking against simpler models should be routine, not optional. I've seen teams skip backtesting because the model produced clean outputs. Clean outputs are the opposite of what you want to see in a living model. Real risk data is messy, and if your validation process doesn't reflect that mess, your model is probably overfit.
Practical Implementation Steps
Here's how this actually plays out day to day. Start with a clean data inventory. Document what you have, what you don't have, and where the gaps are likely to distort results. For a typical institutional portfolio, this means pulling historical prices, credit spreads, volatility surfaces, and macroeconomic indicators into a structured format. Pandas or a similar data framework works fine for smaller portfolios. Larger teams use dedicated data pipelines with versioned datasets. Next, define your risk metrics and time horizons. Are you looking at daily VaR for regulatory capital? Weekly stress scenarios for internal decision-making? Quarterly tail risk assessments for long-term allocation? The answer determines your entire methodology. Don't try to serve all three with one model. It rarely works well for any of them. For implementation, I usually start with a Monte Carlo framework for complex portfolios and switch to analytical approximations for simpler ones. Parametric VaR using covariance matrices is fast and sufficient for linear portfolios with normal return distributions. But that assumption breaks down quickly in equity or credit markets during stressed periods. When I need better tail behavior, I move to historical simulation with bootstrap resampling or a copula-based approach for capturing asymmetric dependence.
Get the Full Details

Copulas deserve more careful treatment than most models get. They let you model the dependence structure separately from marginal distributions, which is useful when correlations behave differently in up and down markets. Gaussian copulas are the default in many textbooks and some production systems. They fail spectacularly in tail events, which is the exact moment you need them most. I prefer t-copulas or Archimedean copulas for credit risk work because they capture tail dependence better.
Common Pitfalls I Keep Seeing
The biggest mistake I encounter is treating model validation as a checkbox exercise rather than a diagnostic tool. If your model passes every validation test, something is wrong. It means you're either not testing hard enough or your model is too simple to fail the tests you're running. Backtest exceptions should follow a binomial distribution under the null hypothesis. When they cluster, that's not noise. That's your model telling you something is structurally mis-specified. Another frequent issue is ignoring regime dependence. Market correlations change during stress. A correlation matrix estimated from calm periods systematically underestimates co-movement when it matters most. I use a Markov-switching framework or an exponential weighted moving average covariance matrix to address this. The EWMA approach is simpler and covers most practical needs. The switching model is more accurate but requires more data and tuning. Model risk itself is rarely discussed adequately. Every model rests on assumptions that are technically false. The question is whether the assumptions are useful for the intended purpose. I once ran a model that perfectly predicted out-of-sample returns during a calm period and then collapsed entirely when the regime shifted. The model wasn't wrong during the calm period. It was just incomplete. It never accounted for a liquidity shock scenario that materialized six months later.
Tools and Workflow Considerations
You don't need expensive software to do decent risk modeling. Python with NumPy, SciPy, and statsmodels covers most needs. For production-grade systems, you'll want something with audit trails and version control, which pushes teams toward platforms like RiskMetrics, MSCI RiskManager, or custom-built systems in R or Python with proper CI/CD pipelines. For downloading reference implementations, the Risk Modeling Assessment And Management toolkit available on GitHub includes open-source examples for Monte Carlo simulation, copula estimation, and backtesting frameworks. The code isn't polished for production use, but it's useful for understanding the mechanics before building something custom. I typically adapt these templates rather than writing from scratch. Automating the validation pipeline matters more than most teams invest in it. Set up automated backtesting that runs overnight and flags exceptions within an hour. Track your backtest results over time to identify patterns in failures. A model that fails consistently on Fridays is giving you information. A model that fails randomly is just broken. Distinguishing between those two cases requires consistent monitoring infrastructure, not manual checks.
When to Stop Trusting the Model
This is the part nobody writes about in textbooks. There are conditions where no model will help you. Hyper-inflationary environments, sudden sovereign defaults, and systemic liquidity freezes all break standard risk models simultaneously. The 2008 financial crisis and the March 2020 COVID crash are recent examples where correlation structures disintegrated and models based on historical relationships produced dangerously optimistic estimates. In those situations, the best approach is scenario analysis combined with stress testing that goes beyond historical precedents. Pure historical simulation cannot help you when history provides no relevant precedent. The workaround is to build forward-looking stress scenarios with explicit assumptions about transmission mechanisms, then model those scenarios separately from your baseline risk estimates. Overlay the two when assessing total portfolio exposure. The practical takeaway is that Risk Modeling Assessment And Management is less about finding the perfect model and more about maintaining disciplined processes around model construction, validation, and escalation. Your model will be wrong. The goal is to be systematically wrong in ways you can detect and correct rather than being wrong in ways that surprise you.