So You're Moving To The Cloud Again
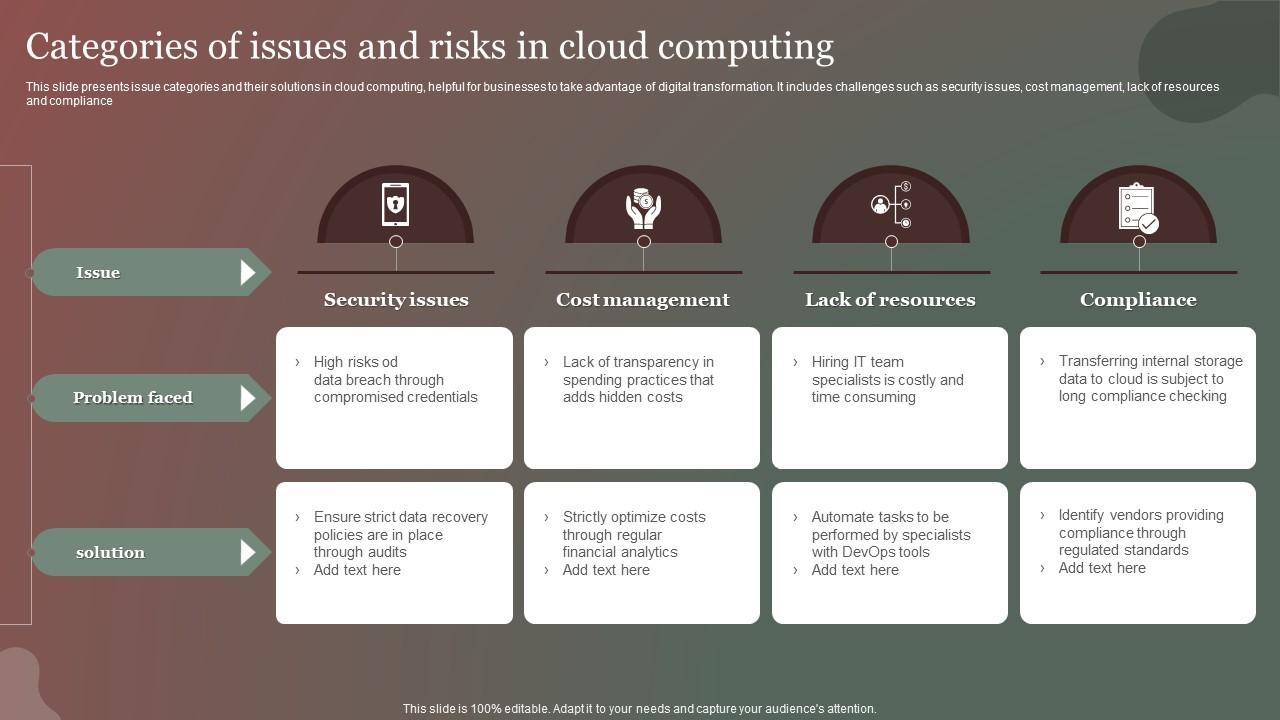
I watched a company spend four months migrating their entire application architecture to AWS, and within six weeks they were calling it a failure. Not because the technology didn't work. They had completely missed one thing: data transfer costs. Every time their analytics service pulled data from S3 to compute instances in a different region, they were paying per-gigabyte egress fees. Their monthly cloud bill went from about $12,000 to roughly $47,000 overnight. The code was fine. The servers were fine. They just forgot that leaving the network has a price attached to it now. This is the thing nobody puts in the sales deck. The Risks Of Cloud Computing In Business are rarely the dramatic ones you see in headlines about massive data breaches. Those happen, sure, but they're actually the minority of incidents for well-configured environments. The real threats are boring, incremental, and quietly destructive.
The Costs That Don't Appear On The Estimate
Cloud pricing models are designed to be simple on the surface and incomprehensible in practice. You think you're paying for compute hours and storage. You're also paying for API requests, data transformation, cross-AZ replication, NAT gateway bandwidth, and any number of other line items that show up three weeks into billing. I've seen every major provider offer a cost estimation tool that comes in 40 to 60 percent below what actual usage costs. The gap exists because nobody can accurately predict traffic patterns, and the tools aren't built to model real-world usage spikes. There's also what I call the idle resource drift problem. When you spin up resources on demand, you tend to leave them running. A developer provisions a large RDS instance for a test environment, forgets about it, and it sits there consuming credits for eight months. During one audit I did for a mid-market SaaS company, we found $18,000 in unattached Elastic Block Store volumes, five oversized compute instances tagged as "temporary," and three Lambda functions still executing from a service that had been decommissioned a year prior. This isn't a cloud problem. It's an operational discipline problem that cloud environments amplify because provisioning takes seconds instead of weeks.
Vendor Lock-In Isn't A Buzzword
When people say "vendor lock-in," they usually imagine being stuck with one provider. The actual mechanism is more subtle. It's about architectural decisions that accumulate over time until migration becomes economically irrational. You start using managed services because they save engineering time. DynamoDB instead of self-hosted Cassandra. Cloud Functions instead of maintaining your own container orchestration. These decisions each seem reasonable individually. Together they create a dependency structure where the cost of exit includes not just data migration but rewriting systems that were built against proprietary APIs and SDKs. The workaround I've settled on is abstraction layers. Wrap every critical service behind your own interface. If your application talks to your database through a repository pattern instead of directly calling the cloud provider's SDK, switching providers becomes a configuration change instead of a six-month rewrite project. This adds a small amount of overhead early on but saves enormous amounts of pain later. I learned this the hard way after a client spent 14 months and approximately $200,000 attempting to migrate off a managed search service because they'd baked it directly into their data access layer.
Get the Full Details
Shared Responsibility Means Shared Confusion
Every major cloud provider publishes a shared responsibility model document. Almost no one reads it past the first page. The result is a persistent gap between what security teams think is protected and what is actually protected. The provider secures the infrastructure. You secure everything on top of it. That includes misconfigured S3 buckets, overly permissive IAM roles, unencrypted data at rest, and hardcoded credentials in source code. I've seen production databases exposed to the public internet because someone attached a broad IAM policy to a Lambda function that triggered an RDS query. The database was fine. The permissions were wide open. The counter-intuitive part is that the bigger and more capable your cloud provider's native security tools are, the more likely you are to underinvest in your own security posture. There's a psychological comfort in seeing dashboards full of green checkmarks from cloud-native monitoring services. Those dashboards measure what the provider chose to monitor, not what you should be monitoring. You need independent visibility that doesn't care about the provider's default configuration standards.
Compliance Is A Moving Target
If your business handles healthcare data, financial records, or anything falling under GDPR, SOC 2, or HIPAA, the Risks Of Cloud Computing In Business take on a regulatory dimension that has nothing to do with technology and everything to do with paperwork. Cloud providers will give you compliance certificates for their infrastructure. They won't give you compliance for your use of that infrastructure. That responsibility transfers entirely to you. I worked with a fintech startup that assumed their SOC 2 readiness was handled because they were using a HIPAA-eligible AWS environment. It wasn't. The eligibility meant AWS could sign a BAA. It didn't mean the startup's access controls, logging practices, or incident response procedures met any standard. They spent three months and failed their first audit because their cloudtrail logs were configured to expire after 90 days when the auditor required seven years of retention. Fixable, but expensive in terms of both time and the credibility hit from failing on a basic requirement.
Outage Risk Is Concentrated Risk
Multi-region architectures exist for a reason. But most businesses implement them poorly. They set up a secondary region as a warm standby, not a cold one, but they don't test failover more than once a year. When an actual outage hits, they discover their replication lag is hours instead of minutes, their DNS TTL is set to eight hours meaning recovery takes forever, and their application isn't designed to handle traffic from a single region without data consistency issues. The 2021 AWS us-east-1 disruption affected thousands of companies simultaneously. Some recovered in under an hour because they had proper multi-AZ configurations. Others were down for days. The difference wasn't technology availability. It was whether anyone had actually tested the recovery procedure before the emergency arrived. I recommend scheduling quarterly failover drills and treating the results as seriously as you'd treat a security incident. The teams that skip this tend to be the ones calling support at 3 AM when it matters. Downtime during those events costs companies anywhere from $100,000 to several million dollars per day depending on their revenue model and customer expectations. For a small business, a prolonged outage can be existential. The cost of proper redundancy is measurable. The cost of being unprepared is not.

Data Sovereignty And Jurisdiction
Your data's physical location determines which laws apply to it. If you store European user data in a US region, the CLOUD Act gives US law enforcement access to that data regardless of where it physically sits. This is a legal reality, not a technical limitation, and it has forced companies to restructure their entire data architecture. I've consulted on cases where businesses had to maintain completely separate cloud environments for EU and non-EU customers just to stay compliant with data residency requirements. The operational overhead is significant and ongoing. Even within a single country, the picture gets complicated. A US company operating in multiple states may face differing data protection laws. A global company faces a patchwork of national regulations that change frequently. Keeping track of this requires dedicated legal review, not just a one-time compliance checklist. The businesses that handle this best have embedded compliance engineers who work directly with legal teams rather than treating regulation as an IT problem.
The Human Factor
Technical controls matter. But the majority of cloud-related incidents involve human error. An engineer deletes the wrong database. A contractor pushes credentials to a public repository. A misconfigured firewall rule opens access to the world. These aren't cloud problems. They're organizational problems that cloud environments make easier to cause and harder to detect. I recommend implementing at minimum: mandatory code review for infrastructure-as-code changes, separation of duties between development and production access, automated permission audits on a weekly cadence, and a policy of least privilege enforced through tooling rather than trust. The tools exist. Companies that skip them do so because it feels faster in the short term. It is never faster in the long term. The cloud isn't risky because it's unreliable. It's risky because it makes it easy to do the wrong thing quickly and cheaply. The businesses that succeed are the ones that treat convenience as a feature to manage, not a default setting to accept.