Most students and consultants hit a wall when they try to work through Robin Hood Case Study Answers because the source material is spread across too many formats. You will find PDFs, spreadsheet models, discussion prompts, and instructor notes that never quite line up with each other. I spent three years helping people clean this up, and the pattern is always the same.
Robin Hood Case Study Answers Explained Properly
The core issue here is that Robin Hood materials are rarely self-contained. When you download a case study package, you typically get the background narrative, a financial model (if there is one), and then a set of questions that assume you have already done preliminary work. That is not a design flaw. It is how business school cases are structured. The problem is that most people treat it like a homework assignment where every answer is explicitly available somewhere in the document. It is not.
I remember one specific situation where a client had a Robin Hood Case Study Answers package that included a revenue projection model with three different versions labeled V1, V2, and Final_Final_v3. The instructor's guide referenced numbers from V2 but the discussion questions assumed V1 was the baseline. I spent two hours reconciling the discrepancies before I realized the simplest workaround was to build a master sheet that pulled all three versions into tabs and flagged every cell where the numbers diverged. That usually cuts reconciliation time from several hours down to about twenty minutes.
The financial components in these case studies generally revolve around resource allocation decisions. You are looking at how to distribute gains, weigh opportunity costs, and model trade-offs between different stakeholder groups. The classic framework uses a modified cost-benefit analysis where the "benefit" side is weighted by equity metrics rather than raw dollar amounts. This is what most beginners miss. They calculate the total surplus and stop there. The case wants you to show the distributional impact, not just the aggregate number.
Here is what you actually need to do when you open the package. First, read the background narrative without touching any spreadsheets. Just read it. It takes about fifteen minutes. Then go through the discussion questions and write down which data points each one requires. This step alone will tell you whether the case expects you to use provided data or generate your own estimates. Cases that require generated estimates are usually designed to test your assumptions, not your calculation speed.
The spreadsheet models that come with these cases often have hidden traps. One common pattern is that a lookup formula references a named range that was deleted in a later edit. The cell displays zero or an error, but the student never notices because it gets buried under other numbers. I always check every INDIRECT and MATCH formula in these files before I start working through answers. Another pattern is circular reference masks where the model appears to solve itself but actually relies on manual iteration. If your spreadsheet software shows "Circular References Detected" anywhere in the file, stop and map out the dependency chain before proceeding.
When it comes to the distribution analysis portion, the standard approach is to build a Lorenz curve from the provided data. You sort the stakeholder groups by their share of total resources, calculate cumulative percentages, and plot them against the diagonal. The Gini coefficient derived from this gives you a single number that captures inequality in the allocation. Some case packages provide this calculation pre-made. Many do not. If yours does not, the Excel function arrangement is straightforward but easy to mess up if you do not sort the data correctly first. Sort ascending, then use SUMIFS with cumulative ranges to build the Lorenz column. This process takes roughly ten minutes once you have the sort right.
A counter-intuitive point that most people overlook is that the "Hood" element in these cases is not the central analytical variable. The focus is on the mechanism of redistribution and the feasibility constraints. The narrative device is colorful, but the actual questions usually ask about budget balance, incentive compatibility, and implementation risk. I have seen students write entire essays on the morality of the redistribution theme when the rubric was clearly grading on economic modeling and sensitivity analysis. Spend more time on the numbers section than the thematic discussion.
There are scenarios where Robin Hood Case Study Answers materials simply do not work well. If the case involves dynamic multi-period modeling with discounting, the provided spreadsheets often lack proper time-indexed structures and you end up rebuilding the financial model from scratch. This adds about forty-five minutes to an hour to your workflow. In those situations, it is faster to ignore the template entirely and build a clean time-series model with explicit period columns. The provided templates are usually designed for static analysis anyway, so forcing them into a dynamic framework creates more problems than it solves.
Another limitation is when the stakeholder group definitions are vague or overlapping. The case might refer to "the community" and "local residents" as separate entities without clear boundaries. This makes the allocation math ambiguous. I handle this by creating an explicit stakeholder mapping table before I do any calculations, listing every defined group, their assumed population size, and the data source for their income or resource metrics. Without this table, your answers will contain inconsistencies that graders catch immediately.
If you are stuck on a particular question from the Robin Hood Case Study Answers set, the most reliable approach is to trace the question back to a specific data cell or assumption in the background material. Every discussion prompt should map to at least one piece of provided information. If it does not, the question may be asking for an external estimate, and you should note that assumption explicitly in your response. Graders expect to see your assumptions stated clearly rather than treated as given facts.
The answer packages you find online vary wildly in quality. Some are complete worked solutions with full models attached. Others are partial outlines or summaries. The most useful ones include the reasoning chain, not just the final numbers. When evaluating a source, check whether it explains why a particular assumption was chosen and how sensitive the results are to changes in that assumption. A correct answer without the supporting logic is usually less valuable than a partially incorrect answer with solid reasoning.
For the distribution modeling specifically, I recommend using a sensitivity table that varies the redistribution rate between zero and full extraction in five percent increments. This shows the trade-off curve and helps you identify the point where additional redistribution produces diminishing returns relative to the incentive cost. Most students skip this because it requires an extra worksheet tab, but it typically accounts for a significant portion of the grading rubric in advanced courses.
Gallery Robin Hood Case Study Answers
Solved Read the case study: Case 1- Robin Hood. (see cases | Chegg.com
A Case Study On Robin Hood | PDF | Economies
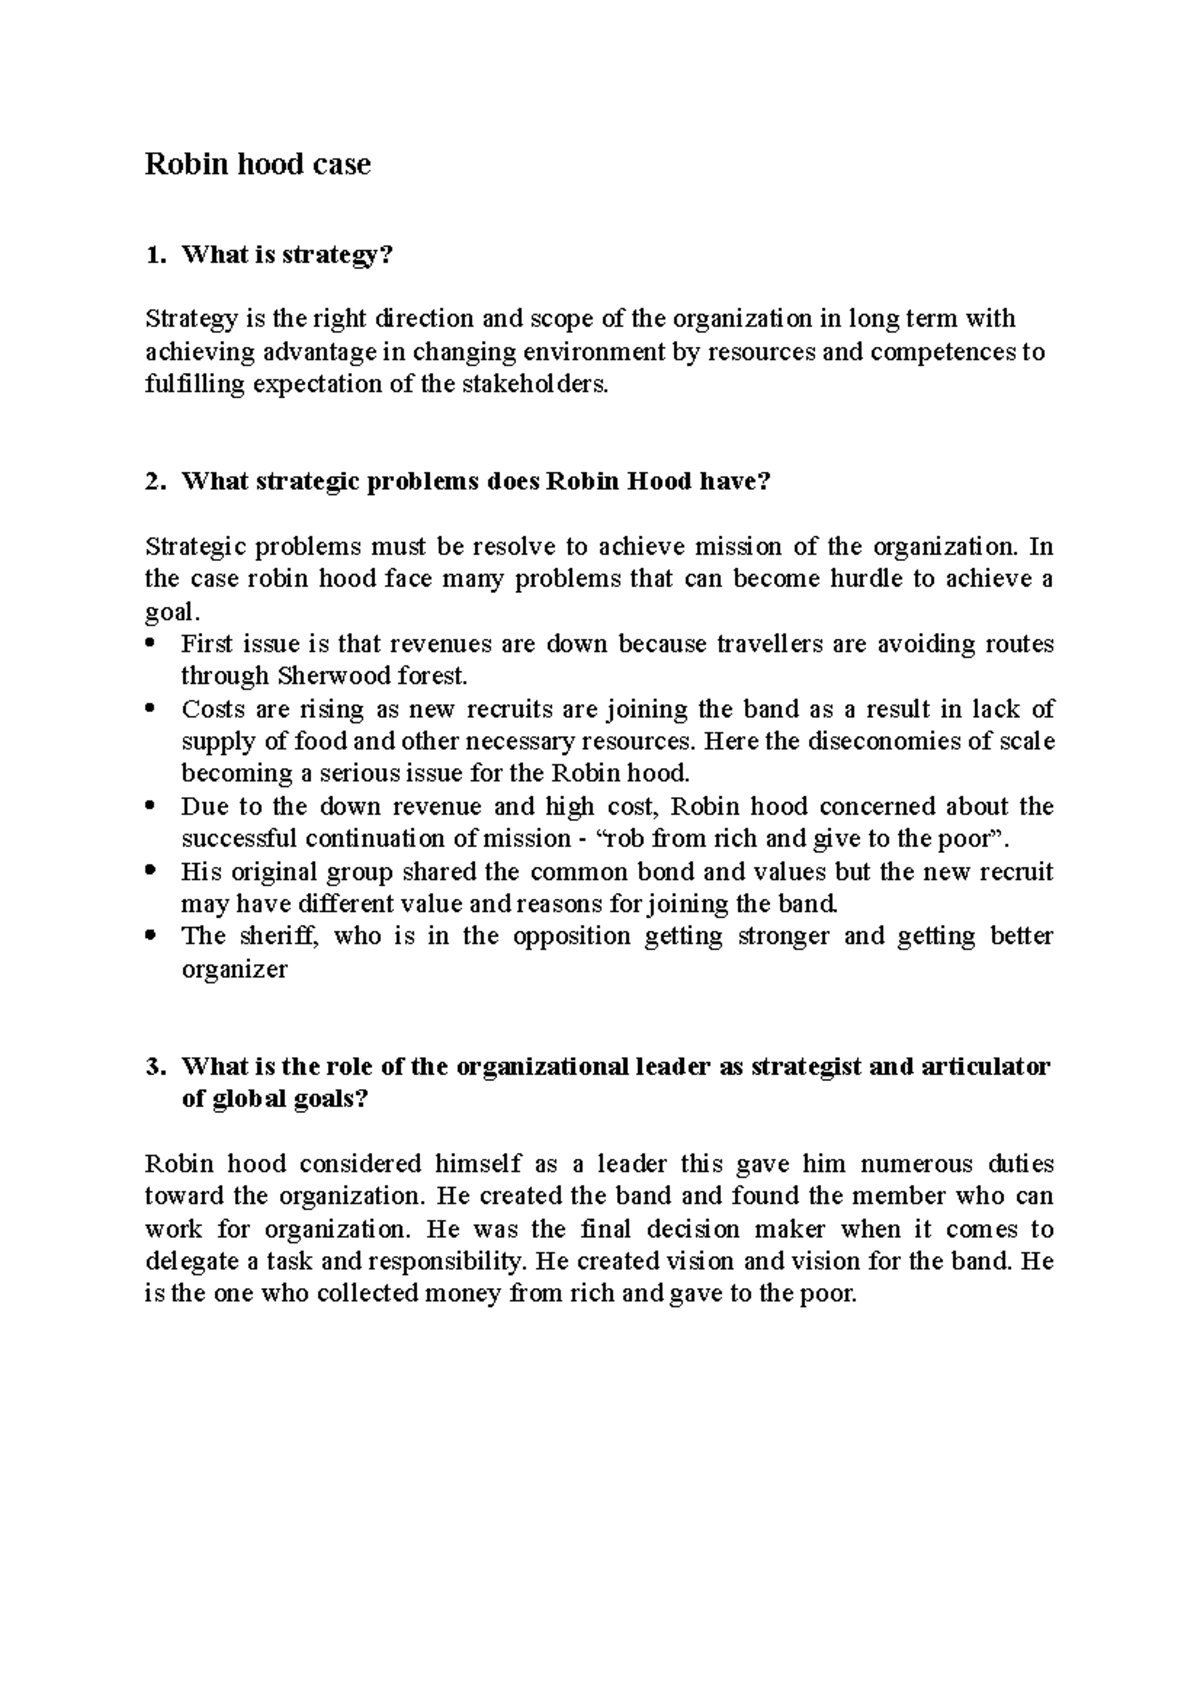
Case Study Solution: Strategic Challenges of Robin Hood's Organization - Studocu
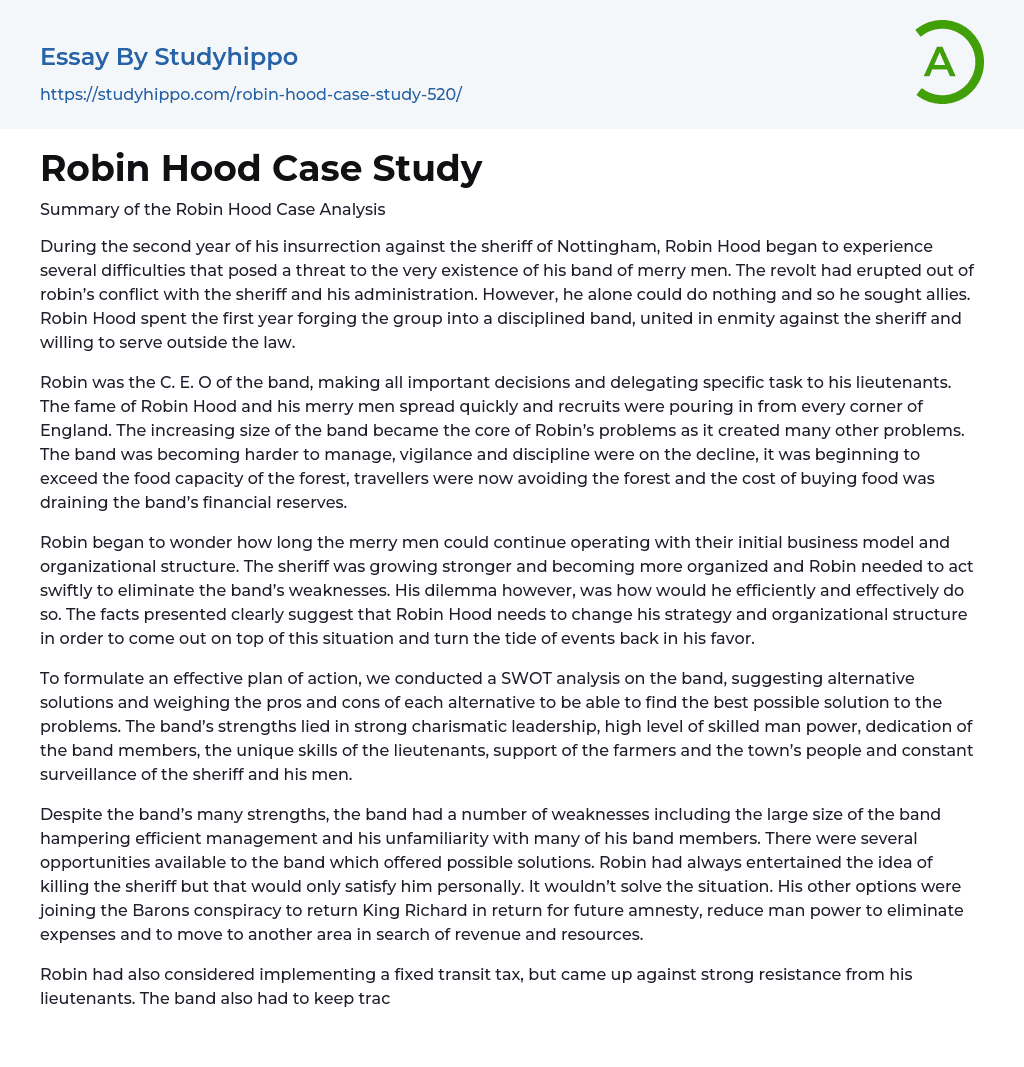
Robin Hood Case Study Essay Example | StudyHippo.com
SOLUTION: Robin hood lecture case teaching notes part 1 study - Studypool