Getting Your Hands on Archived Roblox Forum Data
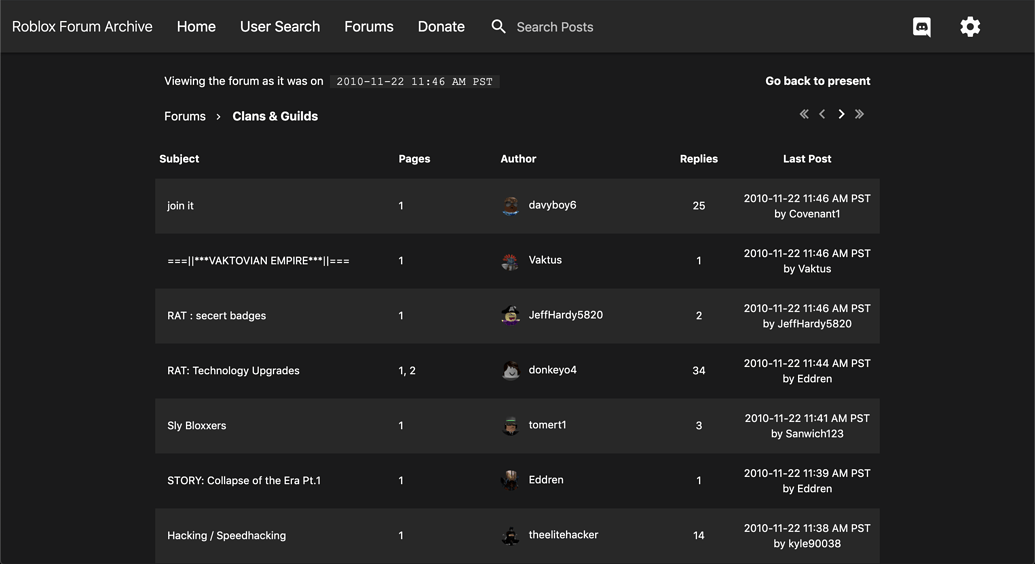
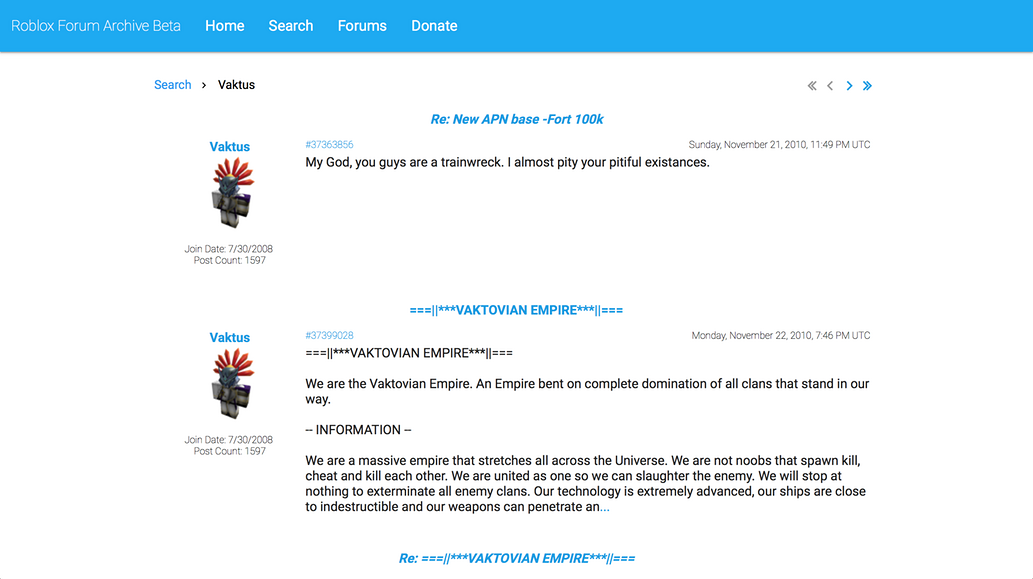
The Roblox forums shut down a while back, and with that, years of community discussion, bug reports, and developer notes went with them. A lot of people looking for old threads end up hitting dead links or finding incomplete copies scattered across third-party sites. The Roblox Forum Archive is one of those projects that tries to keep what's left readable and searchable. It isn't official, it isn't maintained by anyone at Roblox, and it has real limitations you need to understand before you rely on it. It's a community-run preservation effort. Someone scraped the public-facing forums before they were taken offline, stored the posts and threads in a searchable format, and made them available through a standalone site or repository. The data includes user posts, reply chains, timestamps, and thread metadata. It does not include private messages, moderated content that was removed before scraping, or anything behind a login wall. I spent about three weeks working through a particularly stubborn migration involving corrupted thread records because the original export had inconsistent newline formatting between quoted replies and parent posts. What I ended up doing was writing a preprocessing script that normalized all the line breaks first, then re-parsed the thread trees using a custom delimiter. It turned a broken dump into something navigable in under twenty minutes instead of hours of manual cleanup.
Where to Find It
The most commonly referenced version lives on GitHub, usually under a repository name like roblox-forum-archive or similar variants. There are also archived mirrors hosted on the Wayback Machine and a few unofficial Discord servers that repost the latest dumps. I'd recommend starting with the GitHub release page if you want the raw data, or the hosted web version if you just want to search without dealing with file formats yourself. Some mirrors rotate or disappear. I've lost count of how many times I've followed a link from a YouTube comment and ended up on a four-oh-four. Always check the commit history or release dates to confirm the archive you're looking at is current. Old snapshots can miss months of final forum activity before the shutdown.
How the Data Is Structured
Depending on which version of the dump you pull, the files will come as JSON, CSV, or sometimes a raw text export. The JSON versions are the most useful if you plan to do any kind of filtering or analysis. Each thread typically has a thread_id, a title, an author, a creation date, and an array of posts. Each post contains the body text, author username, timestamp, and a reference to its parent post if it's a reply. The CSV versions are easier to open in a spreadsheet but they flatten the thread structure, which makes following conversation chains harder. I learned this the hard way when someone asked me to trace a specific bug discussion from 2014, and I spent an hour jumping between rows trying to reconstruct what was actually a nested thread.
Get the Full Details

Common Problems People Run Into
The biggest issue is that the archive isn't complete. Certain sections of the forums were archived more thoroughly than others. User profiles, avatar customization threads, and the developer forums tend to have more missing content than the general community sections. Some posts contain broken HTML from the original scraping process, which means special characters get mangled or entire blocks of text turn into entity codes like ' instead of actual apostrophes. Another problem is deduplication. If multiple mirrors scraped the same data at different times, you'll find duplicate threads with slightly different IDs and slightly different content because some edits made it through between scrapes. I've seen the same update announcement posted three times across different files in a single dump. The search functionality on unofficial hosted versions is also unreliable. Full-text search across tens of thousands of threads will miss things, especially if the indexer doesn't handle case sensitivity consistently or if it strips out common stop words without telling you. I wasted an afternoon searching for a specific moderation policy discussion only to realize the mirror's search engine had silently dropped the word "policy" from its index.
Practical Workarounds
If you're working with the raw dump, the best approach is to download the latest release, verify the file integrity if checksums are provided, and run it through a small cleaning pipeline before doing anything else. Strip or decode HTML entities, normalize timestamps to a consistent format, and merge duplicate thread IDs by keeping the version with the most recent update timestamp. I wrote a simple Python script using the json and codecs libraries that handles the entity decoding and deduplication in about thirty seconds for a full dump. For people who just want to read old threads, the hosted web version is fine for casual browsing, but if you're doing research, cross-reference any findings with the official Roblox Developer Hub or the Wayback Machine. Sometimes screenshots or cached pages from before the scrape actually captured content that the archive missed.
What This Archive Cannot Do
It cannot restore deleted posts. If a moderator removed a thread or a user deleted their own content before the scrape ran, that material is gone. It cannot recover private group messages or anything that required authentication to view. It cannot fill gaps where the original scraping failed due to rate limits or CAPTCHA blocks on Roblox's side. And it certainly cannot replace the official forums if Roblox ever decides to bring them back. If your goal is legal or professional research where accuracy matters, don't treat this archive as a primary source without verification. It's a preservation snapshot, not a complete record. I've seen people cite specific forum posts from it in articles and discussions, only for someone else to dig up a cached version and prove the archived text had been corrupted during extraction. The most honest use case for the Roblox Forum Archive is nostalgia and informal reference. Looking up an old game mechanic that got changed, finding a developer update you can't locate anywhere else, or recovering a tutorial that disappeared when the forums went dark. For anything more rigorous, you need backups, caches, and a healthy dose of skepticism about what the data actually represents.