How Roger Burlton Business Architecture Actually Works
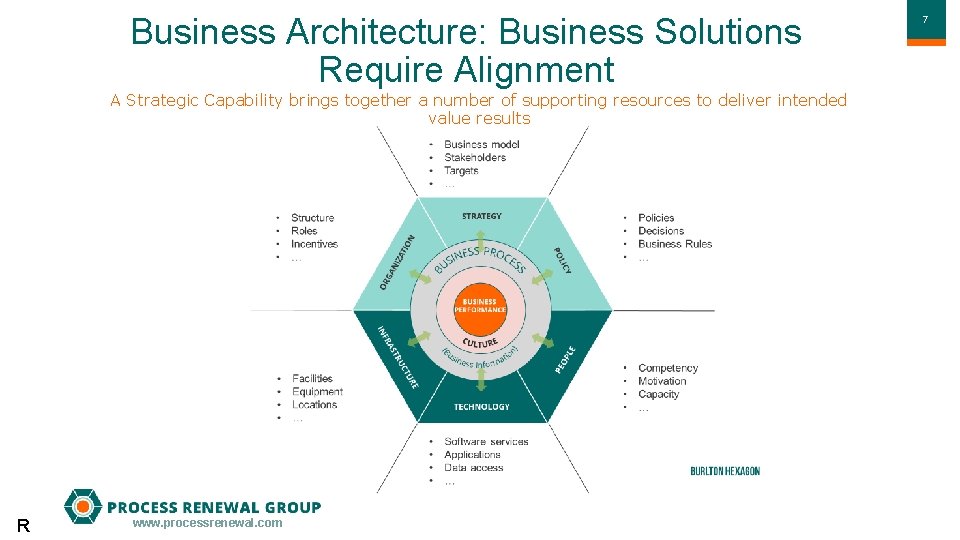
The way I've seen it applied in practice is fairly mechanical. You start with the business process models, usually captured in BPMN or a similar notation, and then you layer on the information objects and organizational roles that participate in those processes. That gives you a complete picture of how the business operates without immediately jumping into systems or technology. Most people get this wrong by starting with databases or application diagrams instead of the underlying business logic. I've been working with this approach for a while now, and the thing that makes it different from other business architecture methods is the emphasis on information as a first-class citizen alongside processes and organization. Burlton's original work treats information objects, the data that flows through processes, as something you model independently rather than as an afterthought to process diagrams. This matters because most enterprise architecture frameworks treat data as a technical concern that belongs in a separate domain.
Getting Started With Roger Burlton Business Architecture
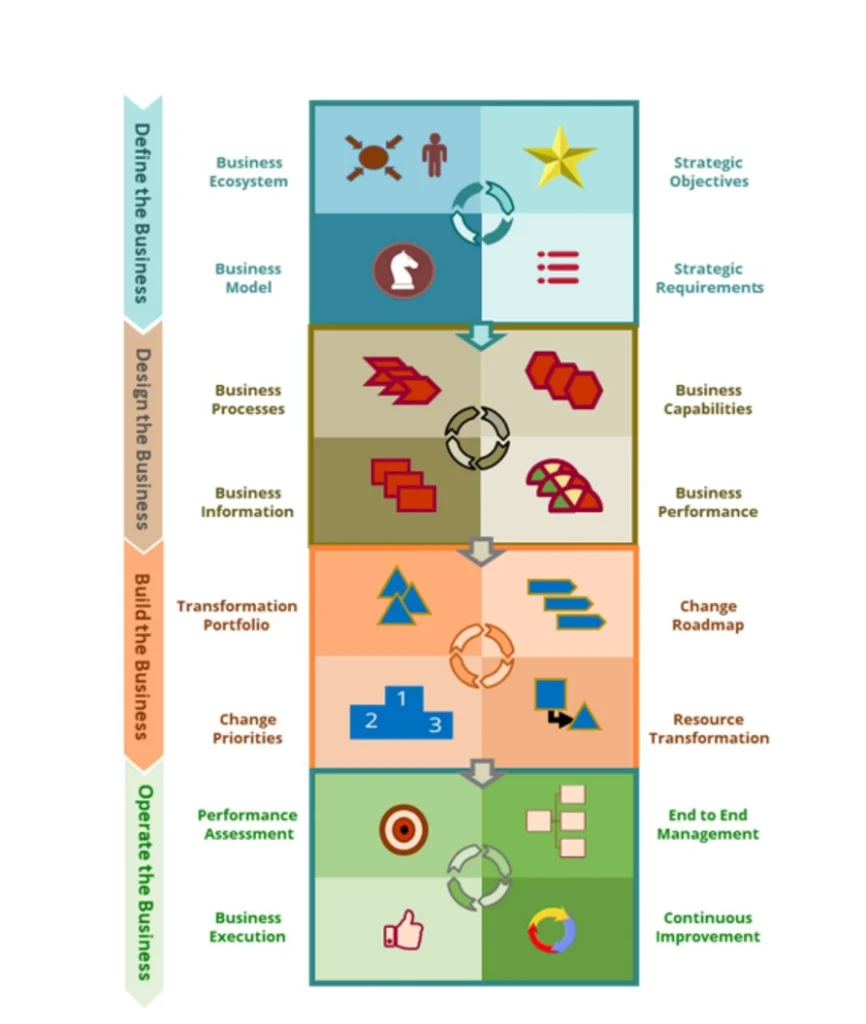
Here is what the workflow looks like when you are actually doing it. First, you identify the major business capabilities your organization needs. These are typically things like Order Management, Customer Service, Claims Processing, or whatever the core domains are for your industry. You don't start with a process model. You start with the capability map and then drill down. From the capability map, you decompose each capability into process components. This is where the method gets specific. Each process component should have a clearly defined input, a set of activities, and a clearly defined output. The input and output are always information objects. This constraint alone prevents a lot of the vague process documentation you see everywhere. The next step that most people skip or rush through is defining the organizational roles. Not the org chart positions, but the roles that participate in each process. A single person might play multiple roles, and a single role might be played by multiple people. This distinction matters more than you would think when you are trying to trace responsibility across a process.
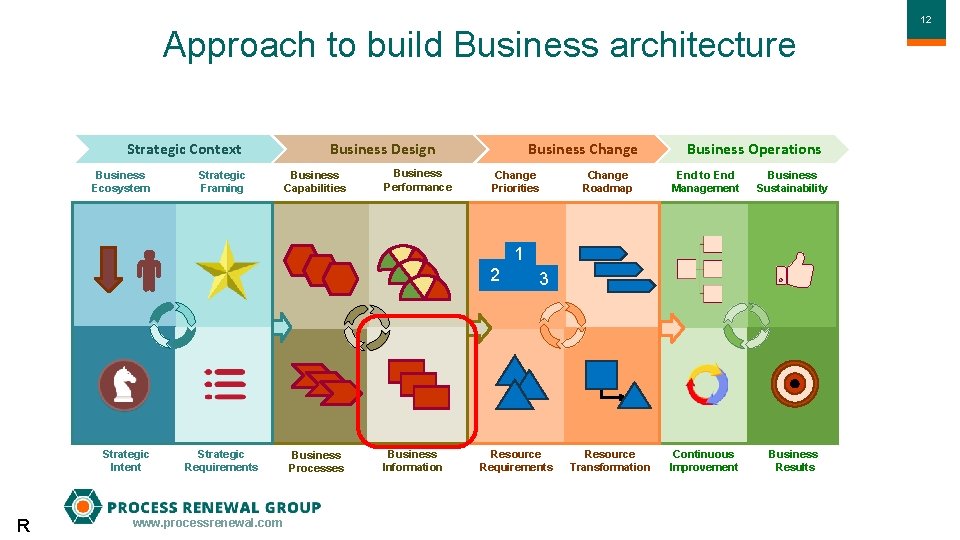
Then you model the information objects themselves. This is the part that feels tedious if you are new to it, but it is where the real value lives. Each information object needs an identifier, a name, a type, and a lifecycle. The lifecycle describes states and transitions. A Purchase Order goes from Draft to Approved to Confirmed to Closed, for example. Knowing the lifecycle of your key information objects tells you more about your business than any process flowchart ever will. I ran into a specific problem once where a client had over three hundred process models spread across five departments, and none of them agreed on what a "customer" meant. One department modeled Customer as a person, another as an organization, and a third had both but with different identifiers. When we went back and applied the information object modeling discipline from this method, we found there were actually six distinct concepts everyone was collapsing into one label. It took about two weeks of work to sort through that mess. Before that, integration projects between those departments kept failing because the data simply didn't map correctly. One counter-intuitive thing about this method that beginners miss is that the process models become less detailed the more senior you go in the capability hierarchy. The top level capability maps are deliberately abstract. They are not meant to show activities or decision points. They show the scope and boundaries of each capability. If your capability map has more than about twelve items per top-level domain, it is probably too detailed and you need to regroup.
Get the Full Details

Another thing that catches people out is the relationship between information objects and business processes. In Burlton's framework, information objects exist independently of the processes that use them. This means you can reuse the same Customer information object across Order Management, Billing, and Support processes without duplicating its definition. Most architecture tools and methodologies don't enforce this separation, and that is where the mess starts accumulating over time. The main limitation of this approach is that it requires a level of discipline that most organizations struggle to maintain. The information object lifecycle modeling in particular tends to get dropped after the initial architecture exercise because it feels like extra work with no immediate payoff. But the payoff is real. When you later need to do system integration or regulatory compliance work, having that information model already defined saves weeks of effort that would otherwise go into rediscovering what each data element actually means. There is also the question of tooling. You can do this method by hand with basic diagramming tools and a spreadsheet for the information object catalog. The method does not require any specific software. However, if you are working in a large enterprise, you will eventually want something that can maintain relationships between the capability maps, process models, and information objects. Tools like ARIS, Signavio, or even a well-structured ArchiMate model in an enterprise architecture platform can work. The method itself is tool-agnostic, but the practical reality is that maintaining coherence across hundreds of models by hand becomes unsustainable past a certain scale.
I have seen this approach work well in mid-size organizations with twenty to two hundred people where the business architecture team can maintain direct contact with the domain owners. In very large enterprises with thousands of employees across multiple business units, the method still applies but you need to delegate the information object governance to the domain level rather than centralizing it. Trying to centralize all information object definitions in a large organization is how these programs die. If you want to read the original material, Roger Burlton's book Business Process Architecture is the primary reference, and there are later papers and articles that extend the framework. The core concepts have not changed significantly since the original publications, which is unusual for this field.