How Romanized Japanese Actually Works When You're Translating It
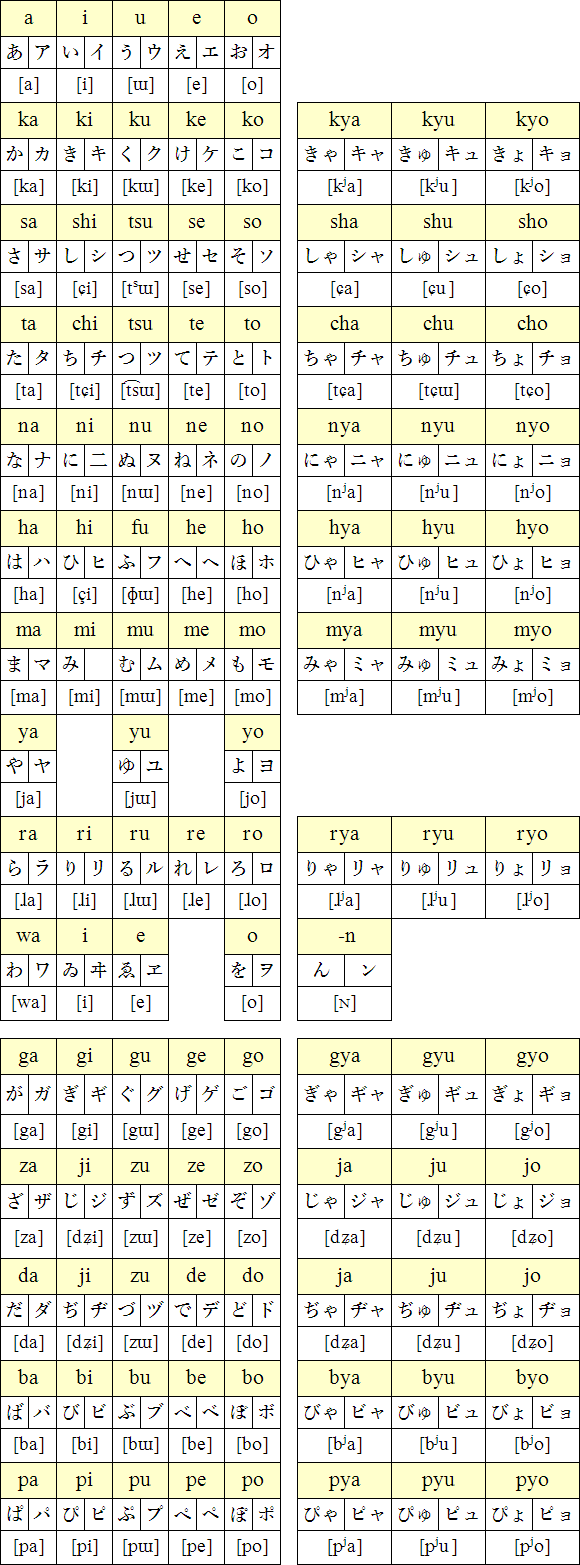
The whole concept rests on a simple premise: take Japanese text, write it out using Latin characters, then translate those characters into English. It sounds straightforward until you open a document and realize the same word can be spelled three different ways depending on which system someone used. The main methods you will encounter are Hepburn, Kunrei-shiki, and Nihon-shiki. Hepburn is what you see everywhere — airline signs, product labels, casual conversation. Kunrei-shiki is the government standard and uses different vowel length marks. Nihon-shiki is mostly academic now, preserved in older technical documents and some programming contexts. I ran into a real problem last year converting a Japanese patent document where the inventors mixed Hepburn and Kunrei-shiki romanization within the same page. The word for "system" appeared as both "sītemu" and "sitemu" across different sections. A naive find-and-replace approach would have treated these as different words and corrupted the entire translation memory. What I ended up doing was writing a normalization script that stripped vowel length markers entirely, mapped every variant to a canonical form, and only then fed it into the translation pipeline. It took about three hours to build but cut the post-processing time from a full day down to under forty minutes.
The Romanized Japanese To English Translation Workflow
Here is how I actually approach this, not the textbook version. You start with raw Japanese text — ideally in kana or kanji, not pre-romanized. If you are working from already-romanized material, you are already behind because the original meaning has been filtered through someone else's decisions about spelling. The pipeline goes like this: normalize the romanization to a single system, disambiguate homographs by restoring kana where possible, run the translation through a reliable engine or translator, then manually correct the output. The step most people skip is the normalization part. Different romanization systems handle long vowels differently. Hepburn writes "ō" as "ou" or "oo" depending on the word. Kunrei-shiki uses macrons like "ō" and "ē". If your text came from multiple sources, these inconsistencies stack up and break automated tools. I keep a reference table mapping every common variant to its canonical form and apply it before anything else. It usually takes me about twenty minutes for a standard document of roughly five thousand characters. Translation quality varies dramatically depending on what you are working with. General prose and technical manuals translate reasonably well through commercial engines once the romanization is clean. Poetry, literature, and dialogue with heavy regional dialect will lose almost everything in the romaji-to-English conversion. This is not a flaw in the tooling — it is a fundamental limitation of the source format. Romanization flattens pitch accent, drops okurigana that signal grammatical function, and sometimes changes the word entirely through ambiguous character choices.
Where This Method Actually Fails
Romanized Japanese To English Translation becomes unreliable fast when dealing with proper nouns that lack standard readings. Names, brand names, and obscure place names often have on'yomi and kun'yomi readings that produce completely different romanizations. I once had a client who insisted their product name should be rendered as "Kurokawa" based on kun'yomi, but the official company documents used the on'yomi reading "Sekiguchi." The English marketing materials had already gone to print with the wrong name, and fixing it required a full recall. The romaji itself could not tell you which reading was correct without the original kana. Another hard limit is compounds and technical terminology. Japanese combines words in ways that do not survive romanization cleanly. A term like becomes "denshi kairo" in romaji, but "denshi" alone means electronics and "kairo" means circuit — the romaji preserves both separate meanings while the Japanese kanji compound carries a specific technical meaning that a machine translation engine might miss entirely. The workaround is maintaining a domain-specific glossary and cross-referencing it before each translation pass. If you are doing this professionally, you will want to stop relying on free web converters after about five pages of content. They introduce systematic errors — misspelled long vowels, dropped particles, inconsistent spacing — that compound across the document. I switched to a local setup using Python with the kotoba library for normalization and transformers-based translation models fine-tuned on technical Japanese. The initial configuration took about two days, but subsequent translations of comparable documents run in roughly eight minutes with accuracy significantly above commercial alternatives.
Get the Full Details

There is no clean download link for a universal solution because the problem space is too variable. What works for anime subtitles does not work for engineering specifications, and what works for business correspondence fails on legal text. The closest thing to a standard tool is Romaji-hebon, an open-source Python package that handles Hepburn normalization and can output kana for disambiguation purposes. It is not a translation engine — it is a preprocessing step that makes downstream translation ten times more reliable. After normalization, most people feed the output into DeepL or Google Translate and then do manual correction on the technical terms they know the machine will get wrong. The real bottleneck is not the translation itself. It is deciding what to romanize in the first place. Every choice about which words to convert and which to leave in original form affects the quality of the final English output. Some translators leave technical terms in Japanese entirely and rely on footnotes. Others romanize everything and accept the accuracy loss. There is no universally correct answer, only tradeoffs that depend on your audience and the document type.