The Problem with Your Current RCA Process
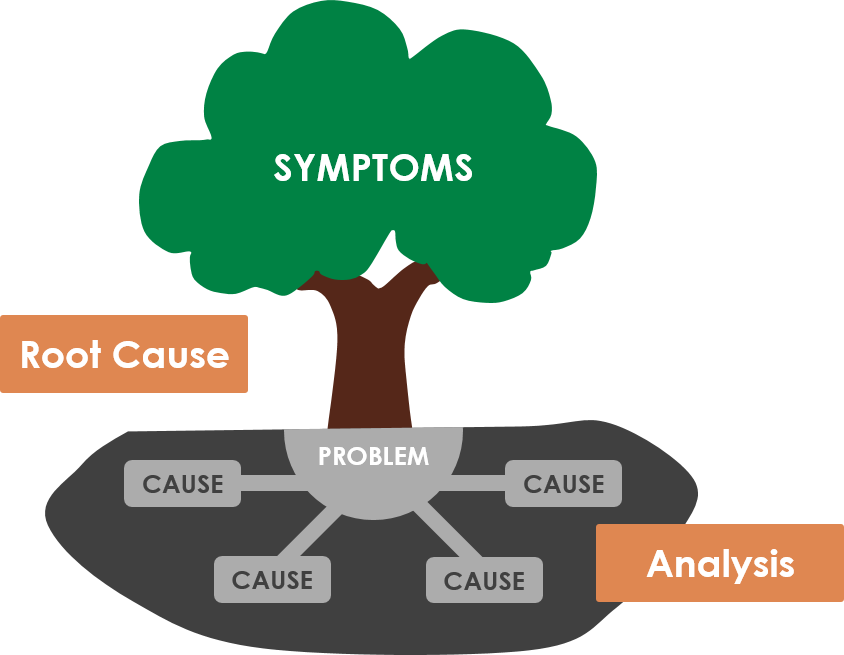
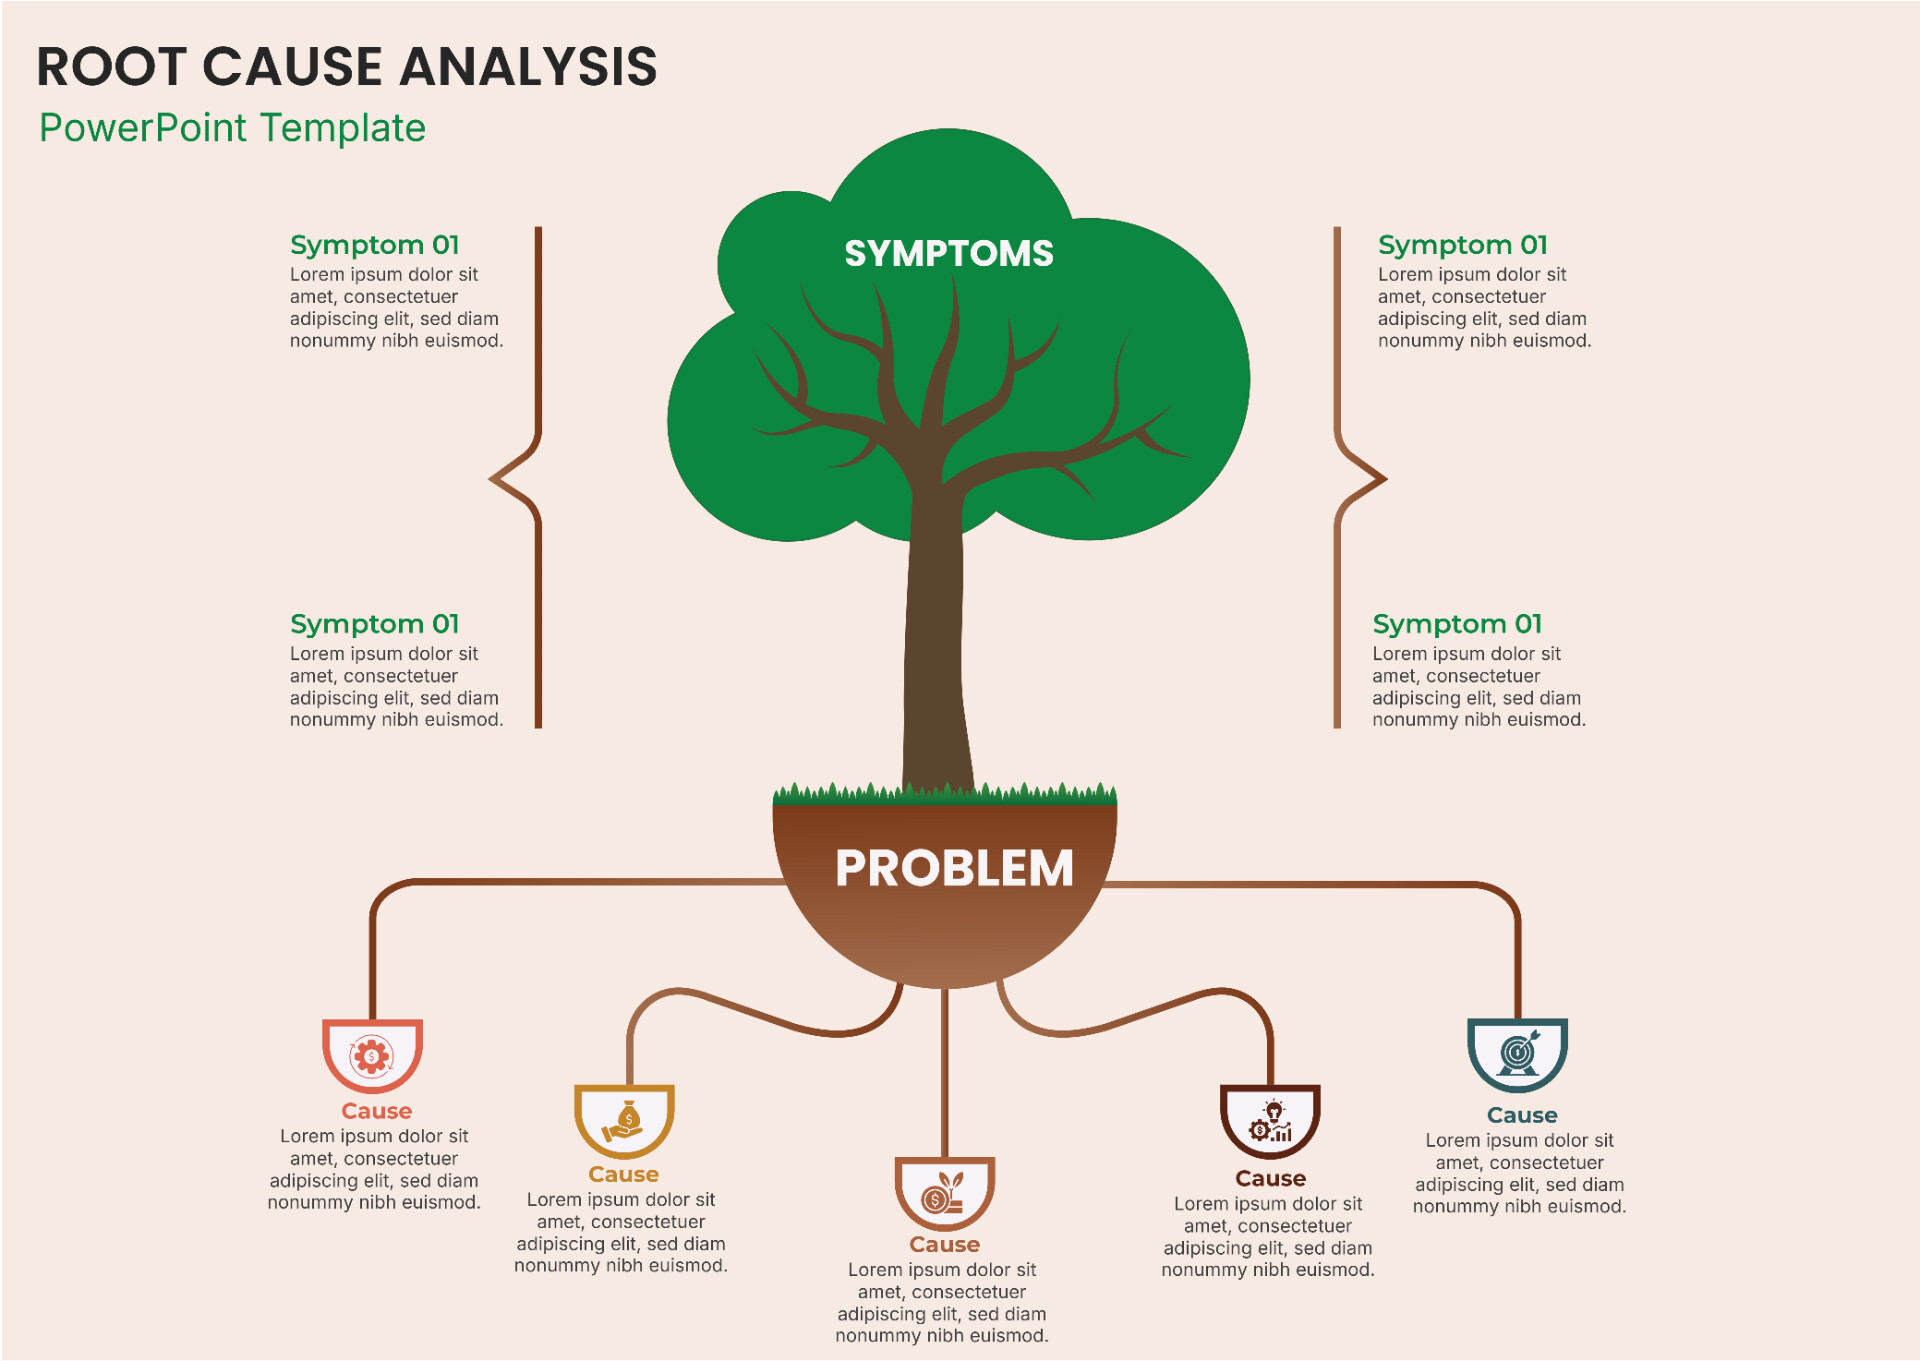
You've probably seen teams waste hours in meetings arguing about whether a server outage was caused by a memory leak or a deployment bug. They produce pages of notes, then nothing follows because nobody can trace the logic chain. This is where a structured approach actually helps instead of feeling like paperwork. A Root Cause Analysis Tree Template is just a visual framework that forces you to map causes hierarchically rather than dumping everything into a bullet list. You start with the problem statement at the top, branch into immediate causes, then keep drilling down until you hit something actionable. The template part means someone already built the skeleton so you're not drawing boxes from scratch every time.
Using a Root Cause Analysis Tree Template Correctly
I spent three years doing incident response for a SaaS company before anyone bothered to give us an actual template. We just used whiteboards and sticky notes, which worked fine until we had to explain to stakeholders why the same database lock issue kept recurring. That was the moment I realized we needed something repeatable. Here's how it actually works in practice. You open your template and fill in the problem statement first. Not "system was down" but "primary order processing API returned 503 errors for approximately 47 minutes on November 12th between 2:14 AM and 3:01 AM UTC." Specificity matters because vague problem statements produce vague root causes. People skip this step and regret it later. Then you branch out. For each major cause category, you ask "what made this happen?" and keep going. The classic five whys approach fits inside this structure naturally. But here's the thing most people miss: you should have at least two parallel branches from the start. Any real incident has multiple contributing factors, and forcing them into a single linear chain hides important relationships.
I learned this the hard way during a production incident where our logging pipeline failed silently. The initial tree pointed straight to a configuration change in Fluentd. We deployed the fix, felt good about it, and then watched the same symptom recur three weeks later. The second incident revealed we'd completely ignored the disk I/O saturation branch that was equally responsible. Our first tree had been too narrow because we started with a premature conclusion.
Get the Full Details
Why Templates Often Fail in Practice
The biggest issue I see is that people treat the template as a form to fill out rather than a thinking tool. They rush through it in twenty minutes during a rushed post-mortem and produce a tree that looks clean but contains zero new information. Everything on it was already known. The value comes from the structure forcing you to examine connections you'd otherwise gloss over. Another common mistake is stopping too early at the first technical cause. "Memory leak in the worker process" sounds like a root cause until you trace it back to the missing connection pool reset in the deployment script, which traces back to no code review requirement for infrastructure changes. The actual root cause is a process gap, not a code bug. Fix the process and you prevent fifteen similar incidents instead of just patching one. Templates also create a false sense of completion. A beautifully formatted tree doesn't mean you've done your analysis. It means you have a document. The actual analysis happened during the discussion that produced the branches. If nobody argued during that process, you probably didn't dig deep enough.
What to Look for in a Practical Template
Most downloadable templates you find online are either too simple or way too complex. The simple ones are just a flowchart with four boxes. Useless for anything beyond trivial issues. The complex ones have seventeen categories and require a legend to understand. Also useless because nobody fills them out. A good template has clean branching structure, enough categories to cover technical and procedural causes without being prescriptive, and space for evidence references. You want columns or sections where you can note the data supporting each branch point. "Assumed due to team consensus" is not a valid entry. Some tools I've seen work well include templates built into incident management platforms, though they tend to be generic. Others use dedicated diagramming tools with pre-built RCA shapes. The format matters less than discipline in using it consistently across incidents.
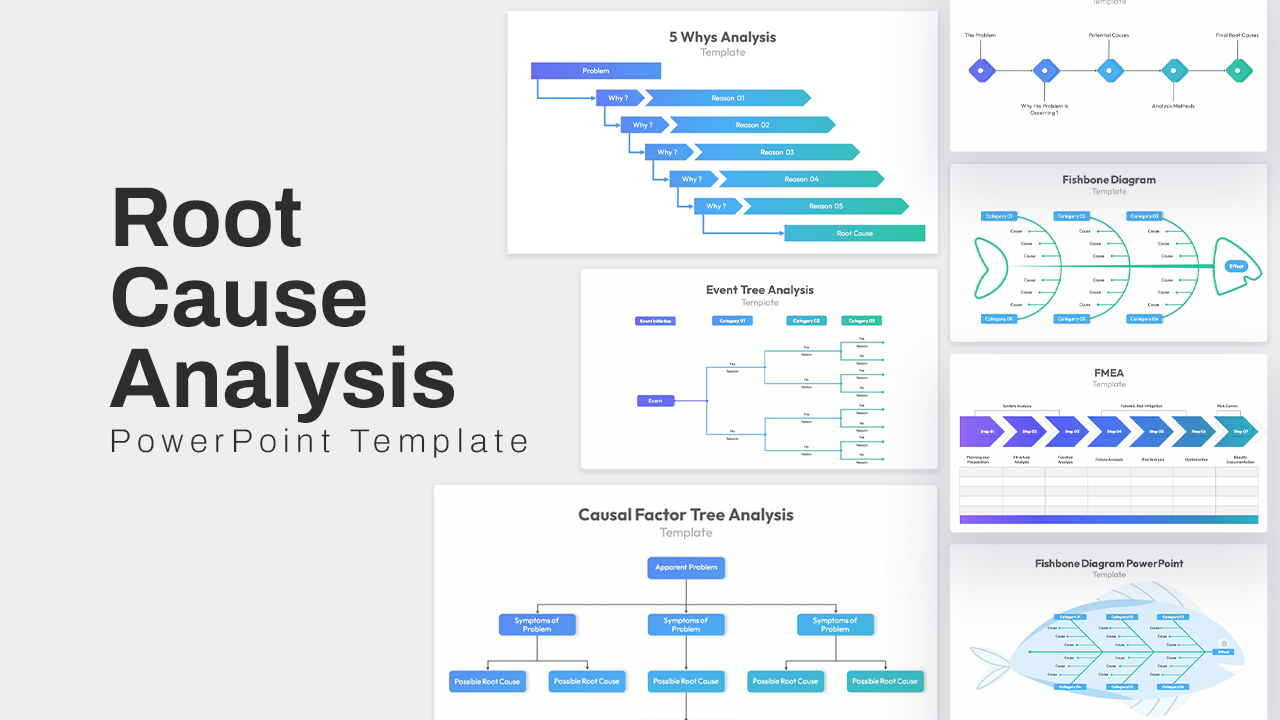
If you're looking for something to start with, search for Root Cause Analysis Tree Template on diagramming sites or incident management communities. Many teams share their internally developed versions on GitHub or in engineering blog posts. I'd recommend adapting someone's template rather than building from scratch the first time. Copying a working structure saves about forty-five minutes of setup and usually results in better output because the template already encodes some hard-won structure. The template I ended up using for most of my time at that company was a modified Ishikawa combined with decision tree logic. It handled multi-branch cases better than pure fishbone diagrams and was faster to fill out than full fault tree analysis. Not perfect, but good enough to actually use repeatedly, which is more than most teams achieve.