Why Most Sales Skills Assessment Templates Are Useless
You have probably seen them. A beautifully formatted spreadsheet with columns for product knowledge, objection handling, and closing ability. Someone in enablement spends two weeks building it, the leadership team sends it around with a memo, and then nobody actually uses it past the first quarter. I have watched this happen at three different companies. The problem is not that the template is bad. The problem is that the template was built for an audit, not for a conversation. I ended up redesigning our assessment process after the second failed rollout. We had hired eight SDRs in a single quarter and needed a way to tell which ones would actually convert without waiting three months of quota time to find out. The existing template had a 47-question survey, a role-play scoring sheet, and a manager observation rubric. It took roughly 90 minutes to complete and produced results that correlated with actual performance at about 0.12. That is basically random. We threw it out and built something smaller that actually tracked the behaviors that matter.
Building a Sales Skills Assessment Template That Actually Works
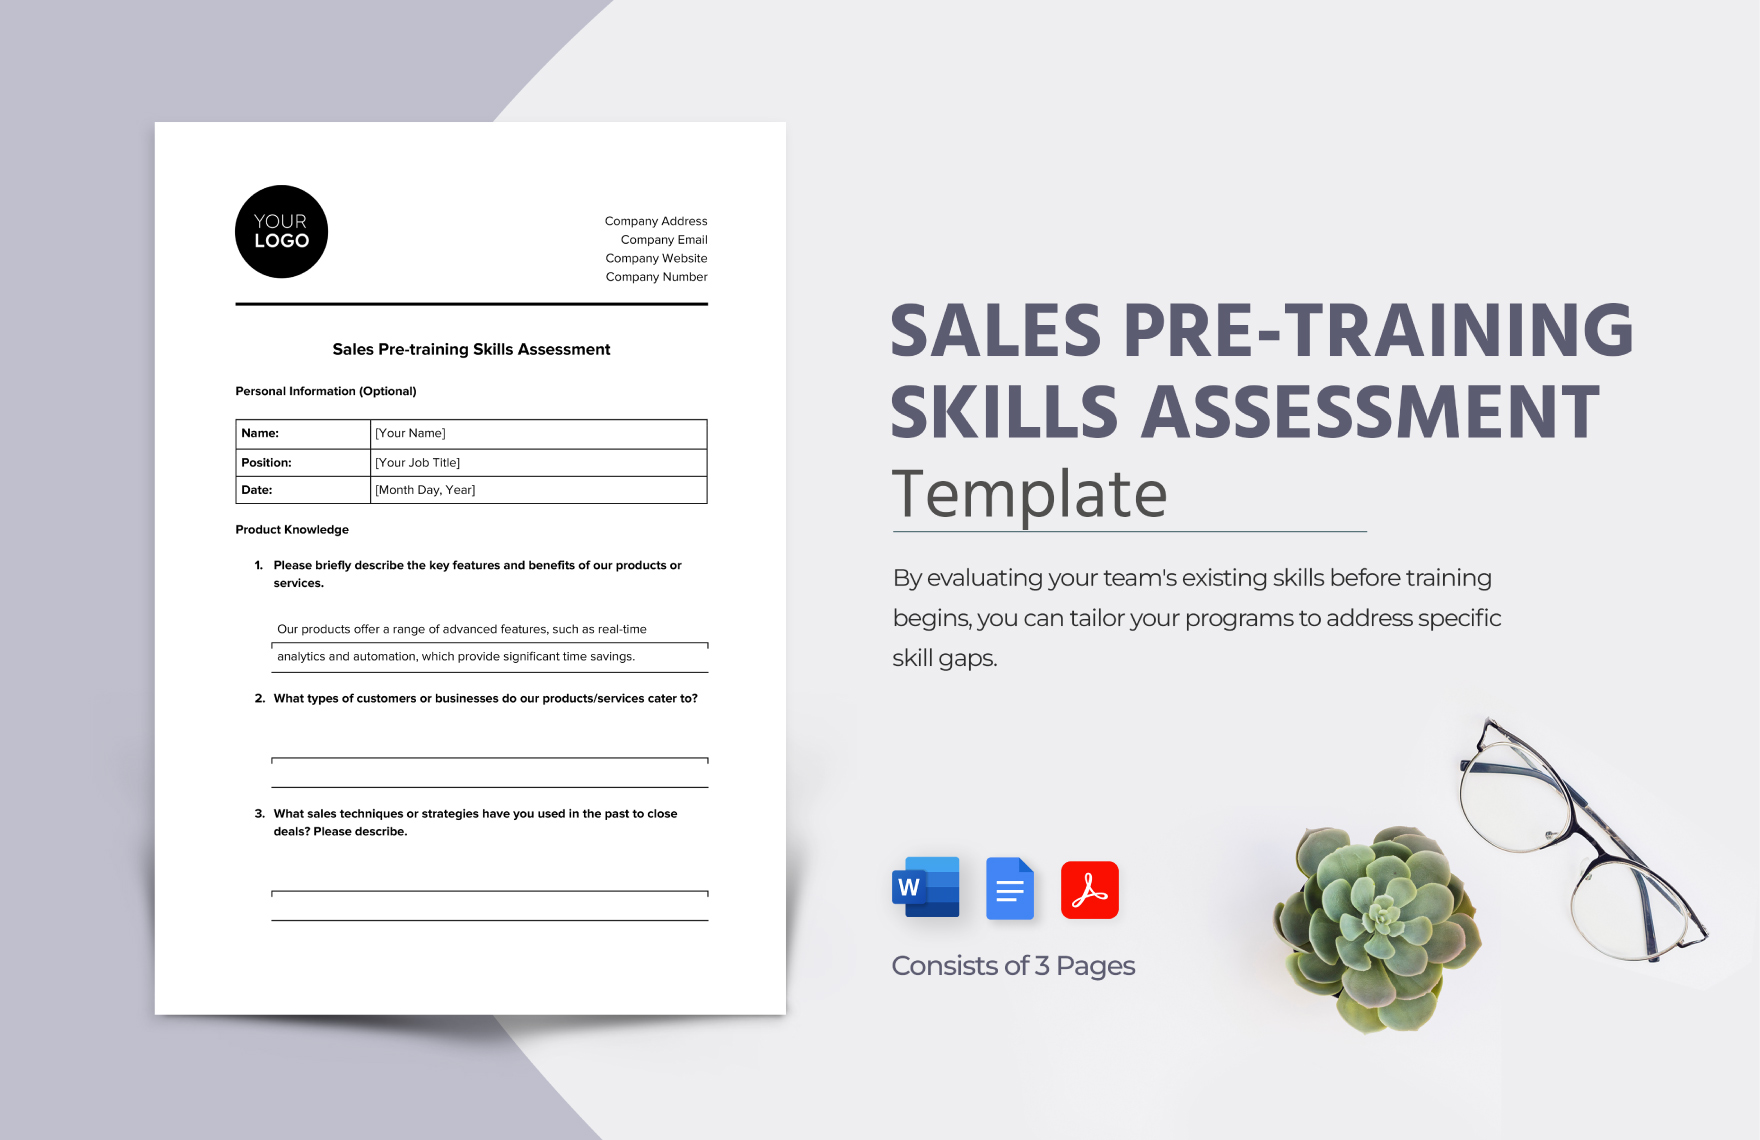
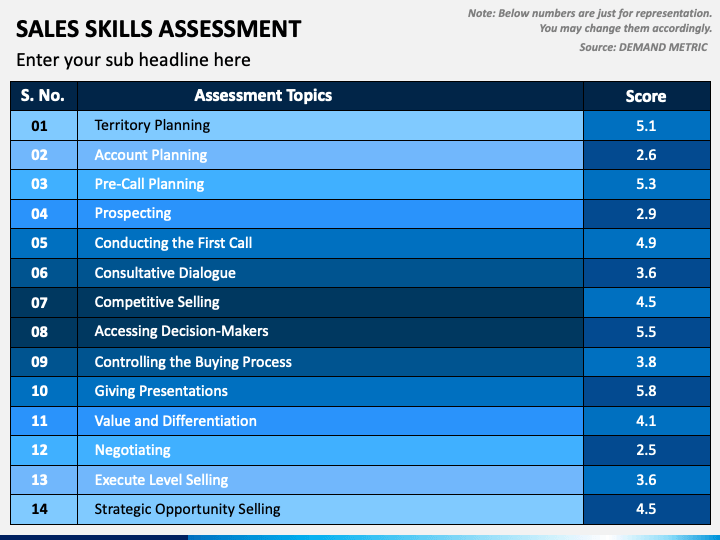
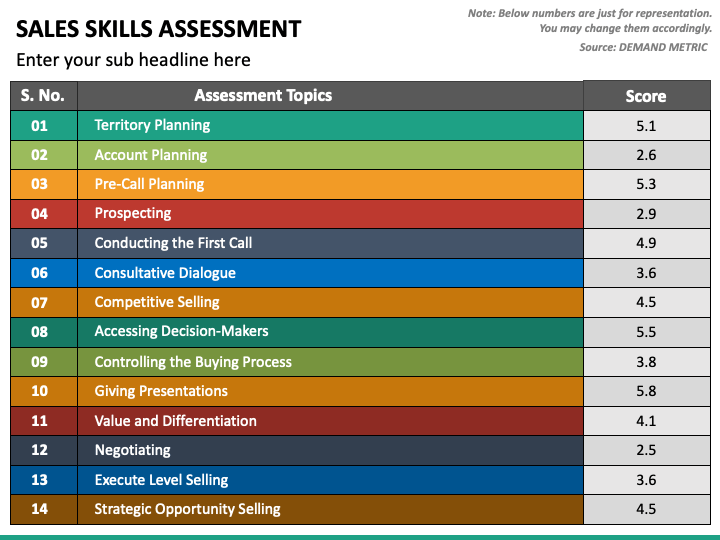
Start by identifying the skills you can observe directly. Most templates go straight for product knowledge quizzes and personality assessments. Those are fine as supporting data. They do not tell you whether someone can run a discovery call or handle price objections without freezing. Start with the observable behaviors instead. The core skills are discovery question quality, active listening, handling objections, and closing intent. Everything else is secondary. I suggest a four-part structure. The first part is a recorded call review where assessors score the candidate on a simple five-point scale for specific behaviors. Not overall performance. Specific behaviors. Did they ask open-ended questions in the first three minutes? Did they uncover a budget signal? Did they confirm next steps? This takes about 12 minutes per call. The second part is a live role-play with a calibrated scenario. The third is a product knowledge check, but keep it to the ten questions that actually come up in real conversations. The fourth is a manager written assessment based on probationary-period observations if the hire is already onboarded. The scoring needs to be normalized across raters. I learned this the hard way when two different sales managers gave the same role-play a 4 out of 5 and a 2 out of 5 because they were using different internal definitions of what a 4 looks like. I created a one-page rubric that defines each score level with a concrete example. A score of 3 is not "adequate." A score of 3 is "asks one open question but quickly pivots back to features." A score of 4 is "asks two to three qualifying questions and responds adaptively to the answer." This reduced rater variance from roughly 1.8 points of standard deviation down to about 0.6 within a month. It is not perfect but it is usable.
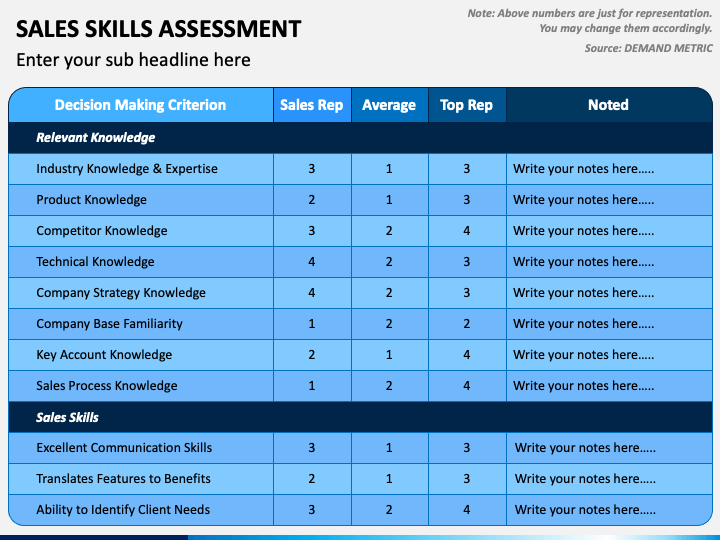
There is a section in the template for a composite score. Do not use a simple average. The composite should weight the recorded call review at 40 percent, the live role-play at 30 percent, product knowledge at 15 percent, and the manager observation at 15 percent for existing hires. For external candidates, the manager portion drops to zero and the remaining weights shift proportionally. This weighting came from running a regression analysis on our prior year hiring data. Discovery call quality and role-play performance had the highest correlation with 90-day quota attainment. Product knowledge had a low correlation. Weighting them equally was throwing accurate signal away. I should mention the edge case that caught us off guard. We once assessed a candidate who scored extremely poorly on the live role-play but perfectly on the recorded call review and the written assessment. She had been on camera for the role-play and froze. She was not a bad rep. She just performs badly under direct observation. We ended up doing a shadow call where she listened to a live call with her prospective manager without being recorded or identified, and her written analysis of that call was sharp. We hired her. She made quota by month four. The workaround is to add a low-stakes observation component when there is a significant mismatch between the recorded call performance and the live role-play score. It is not in the standard template but you should add it as a branch condition. The template itself is a simple document. Four sections, each with its own scoring sheet, a calibration guide, and a notes column. Do not make it a 40-page workbook. Nobody fills it out past page two. I have seen enablement teams build assessment toolkits that required three different people to complete three different documents across two weeks. By the time the data came back, the hiring decision was already made and the form was just compliance theater. You want one document. One hour of real work. Decisions that make sense.
Get the Full Details

There are limitations to this approach. The biggest one is rater consistency. Even with a calibrated rubric, two people will still see the same call differently. There is no fixing that entirely. You can reduce it through calibration sessions where assessors watch the same recording and discuss their scores until they land within one point of each other. That usually takes 30 minutes and pays for itself immediately. Another limitation is that the template assumes you have recorded calls to review. If your CRM does not capture call recordings or your team is remote with no call logging, the first section becomes useless and you lose the highest-correlation data point. In that scenario, the live role-play carries more weight, and you should adjust the composite formula accordingly. The template is designed for a typical B2B sales organization with a representative-driven model. It does not work well for highly technical roles that require deep engineering knowledge, nor does it work for inside sales environments where the sales cycle is under five minutes and the skill set is entirely different. If you are assessing account executives for enterprise deals, the product knowledge section needs to include competitive positioning scenarios. If you are assessing SDRs, the discovery section should focus on qualification speed and pipeline generation rather than consultative questioning depth. I keep the document in Google Sheets because it needs to be editable by anyone on the team and shareable with hiring managers who do not have access to the CRM dashboard. The scoring sheets use conditional formatting so that anyone opening it can instantly see which candidates are passing or failing each section. There is no automated calculation that replaces human judgment, but the visual feedback helps during calibration meetings where you are comparing six candidates side by side. That is the actual value of the template. Not the scores. The conversation the scores start.