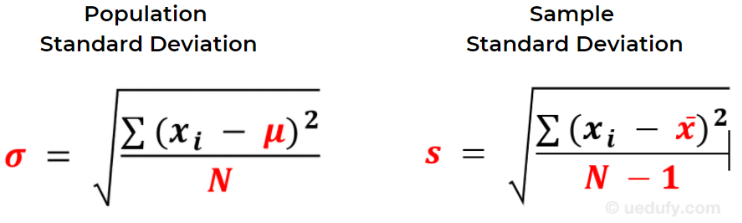
Getting the denominator right is where most people mess up
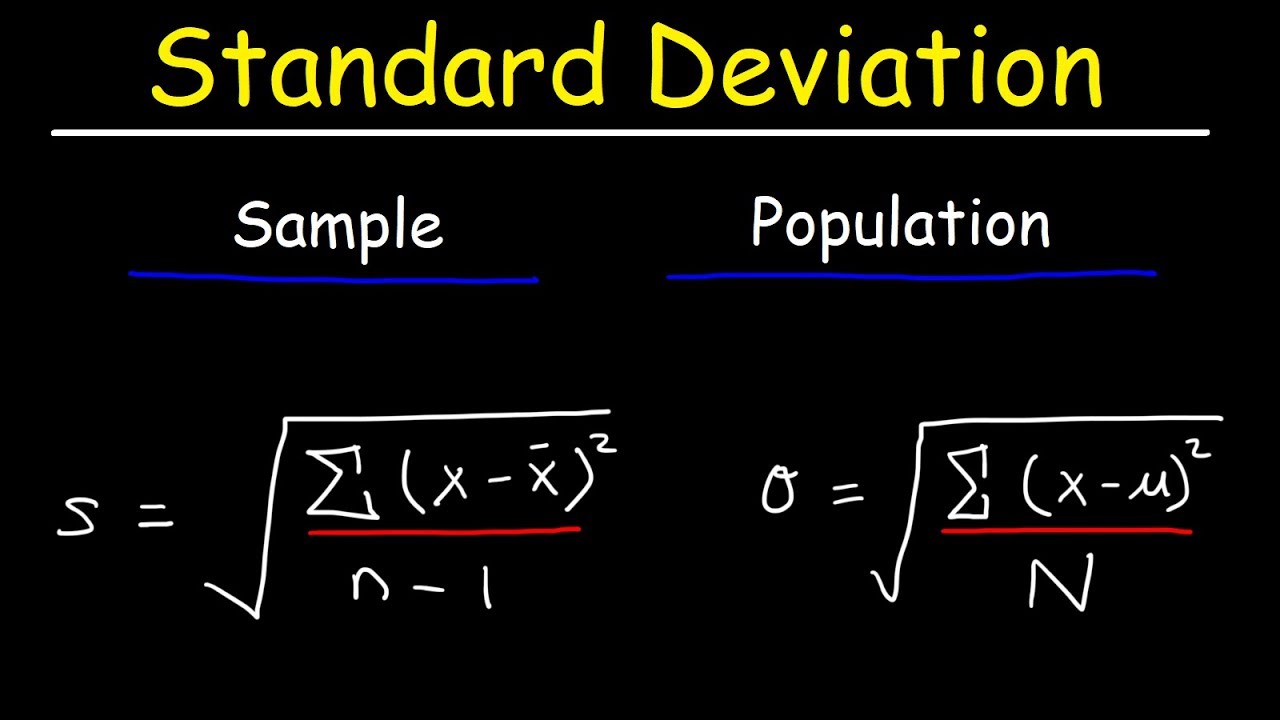
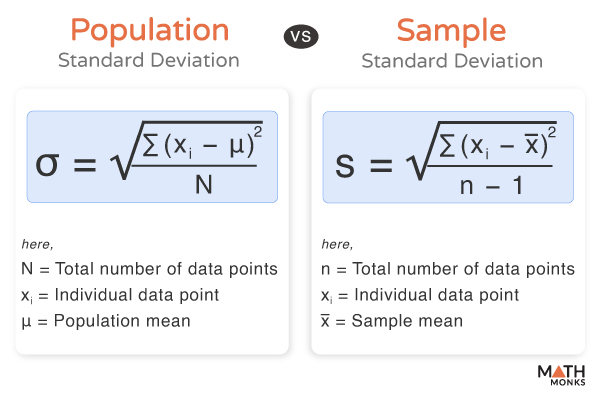
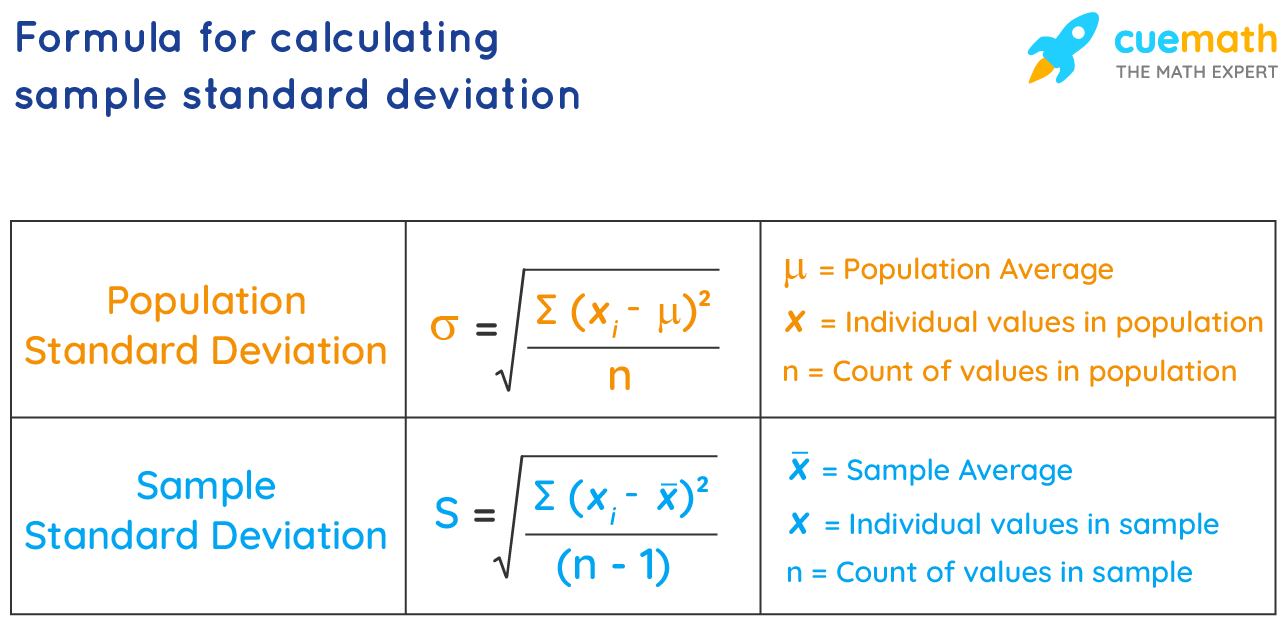
I see the same mistake repeatedly in code reviews and spreadsheets. Someone calculates the average of squared deviations, divides by the total number of observations, and presents it as the standard deviation of their dataset. The problem is that this is technically the population standard deviation formula applied to data that is actually a sample from something larger. The fix is straightforward but easy to overlook under a deadline. When you work with Sample And Population Standard Deviation, the mathematical difference is just one number in the denominator. Population standard deviation divides the sum of squared deviations by N, the total count. Sample standard deviation divides by n minus one instead. That minus one is called Bessel's correction, and it adjusts for the fact that a sample mean sits closer to the data points than the true population mean does, which otherwise compresses the variance estimate.
Sample And Population Standard Deviation
Here is the practical workflow I use. You start by calculating the mean of your data. Subtract that mean from every observation, square each result, add them all together, divide by n minus one if you are treating the data as a sample, or divide by N if you truly have the complete population, then take the square root. The output is your standard deviation expressed in the same units as the original data. In Excel or Google Sheets, the functions are stdev.s and stdev.p for sample and population respectively. In Python's numpy, you use std with the ddof parameter set to zero for population or one for sample. R has sd for sample and you adjust manually for population. Every tool gets it wrong at least once for someone because the default behavior varies between them. I ran into a specific issue last year when I was analyzing defect rates from a manufacturing batch. We had recorded measurements from 47 units out of a production run of roughly 3,000. My initial analysis used the population formula, probably because I was working from a template someone else built. The sample standard deviation came out to about 2.3 percent, while the population version gave me 2.24 percent. It looked minor until I used those numbers to calculate a tolerance interval for quality control. The difference shifted our upper control limit by enough to flag false positives on the assembly line, costing us roughly half a day of unnecessary line adjustments before someone caught it. The workaround was simply auditing every formula against the question of whether the data represented the full population or a subset, and adding a comment in the spreadsheet that stated which assumption each calculation was built on.
The deeper issue most people miss is understanding when the distinction actually matters. With a sample size above a few hundred, the difference between dividing by n and dividing by n minus one becomes numerically trivial. At n equals 30, the correction changes the result by about 1.7 percent. At n equals 10, it is nearly a 10 percent difference. Most introductory courses gloss over this gradient and treat it as a binary rule, which creates confusion when someone applies sample standard deviation to a dataset that actually constitutes the entire population of interest. Another thing that gets overlooked is that standard deviation assumes a roughly symmetric distribution. If your data is heavily skewed, the standard deviation becomes a misleading summary statistic even when calculated perfectly. I have seen people report standard deviations for revenue data, response times, and customer lifetime values without checking the shape of the distribution first. A median with interquartile range tells you far more in those cases. Box plots or a quick skewness check takes about 30 seconds and prevents a lot of bad decisions downstream. There is also a computational edge case worth noting. When you have a very large dataset and the mean is a large number, subtracting it from each observation before squaring can introduce floating point precision errors in some software implementations. The two-pass algorithm, where you first compute the mean and then compute squared deviations, is generally more numerically stable than the single-pass formula, though most modern libraries handle this internally. If you are writing your own implementation from scratch, stick with the two-pass approach and be aware of the scale of your data.
Get the Full Details

The main limitation of standard deviation as a concept is that it only captures spread around the mean. It tells you nothing about multimodal distributions, heavy tails, or outliers beyond what the squared terms implicitly include. If your goal is anomaly detection or robust comparison between groups, consider supplementing it with median absolute deviation or interquartile range. These are not replacements, they are complements, and using both gives you a fuller picture without adding much complexity. For reference, here are the two formulas side by side. Population standard deviation is the square root of the sum of squared deviations from the mean divided by N. Sample standard deviation replaces N with n minus one in that denominator. That is the entire technical distinction. Everything else is interpretation and context. If you want to implement this yourself, the numpy documentation covers the ddof parameter clearly, and the scipy.stats module provides additional distribution analysis tools if you need to go further than a simple standard deviation report.