What You Actually Need To Know Before You Run Any Analysis
The sampling distribution for mean is just the distribution of all possible sample means from repeated samples of a fixed size drawn from a population. That is the entire concept. Everything else is derivation, application, or things that go wrong when people rush it. I will walk through how it works, where the standard deviation of that distribution comes from, and what happens when you try to use it on data that does not behave nicely. Most people get this right in theory and mess it up in practice because they skip over the assumptions.
How To Build A Sampling Distribution For Mean Step By Step
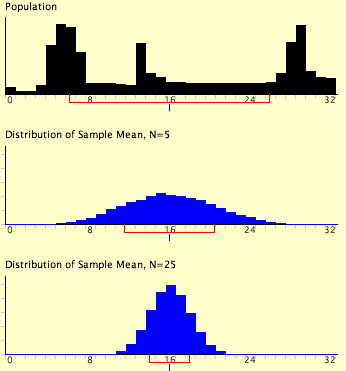
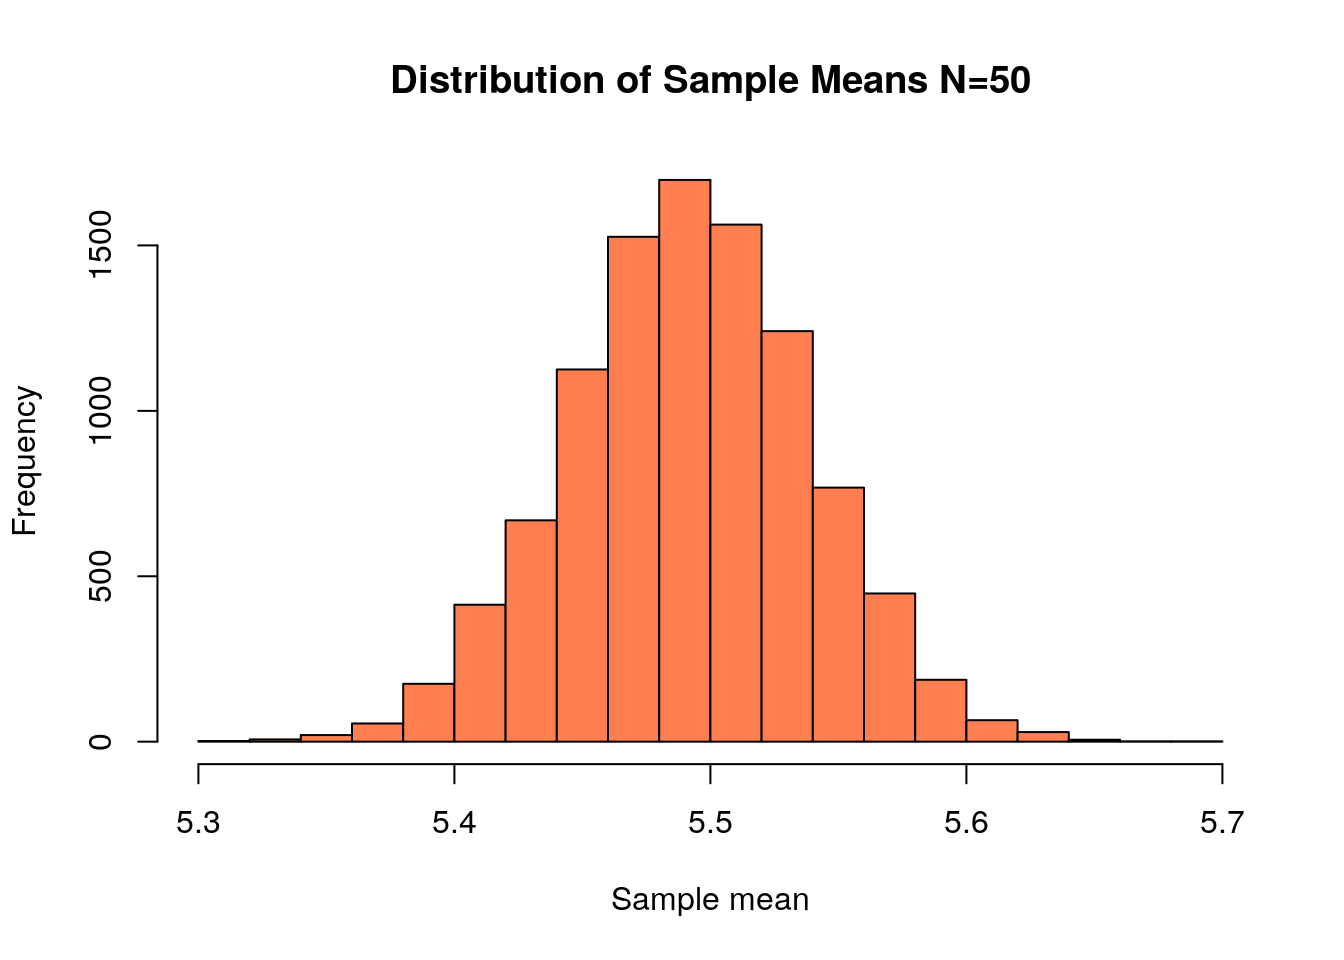
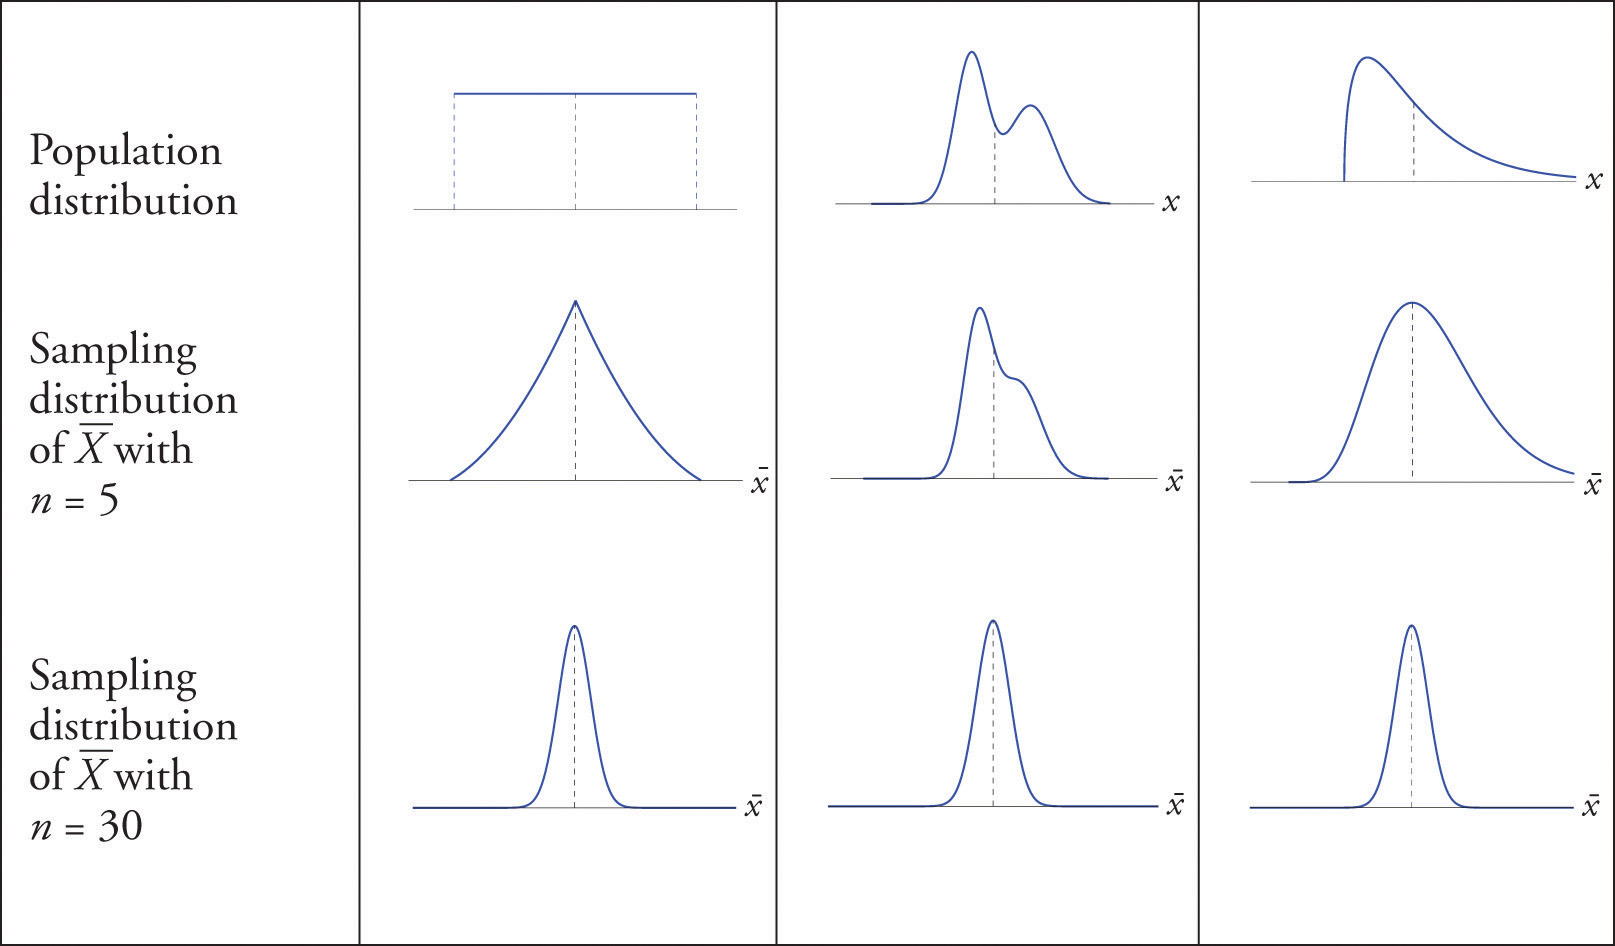
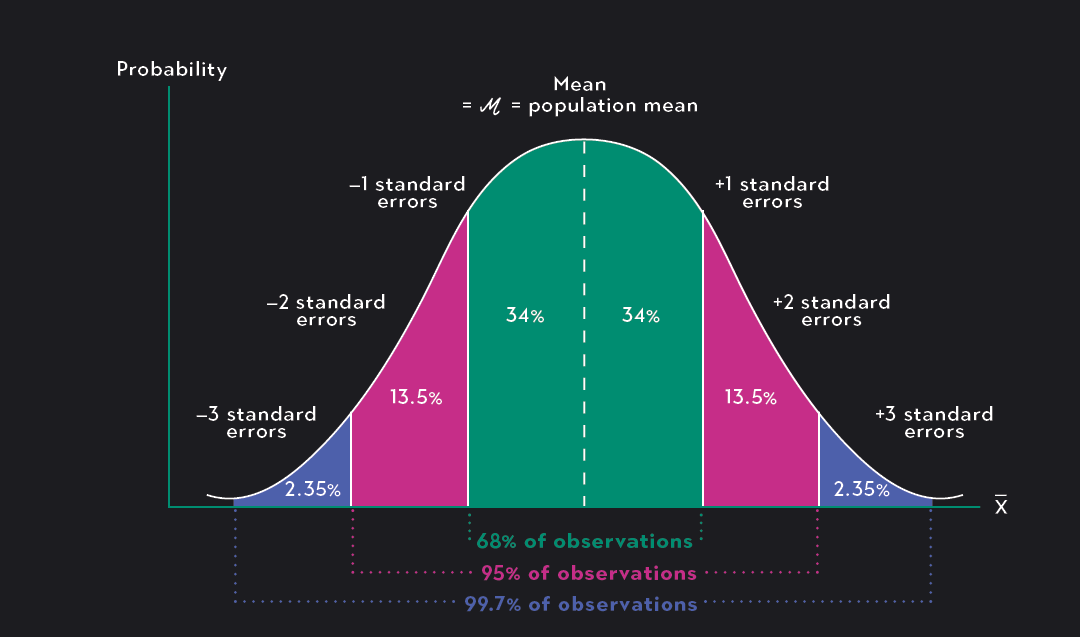
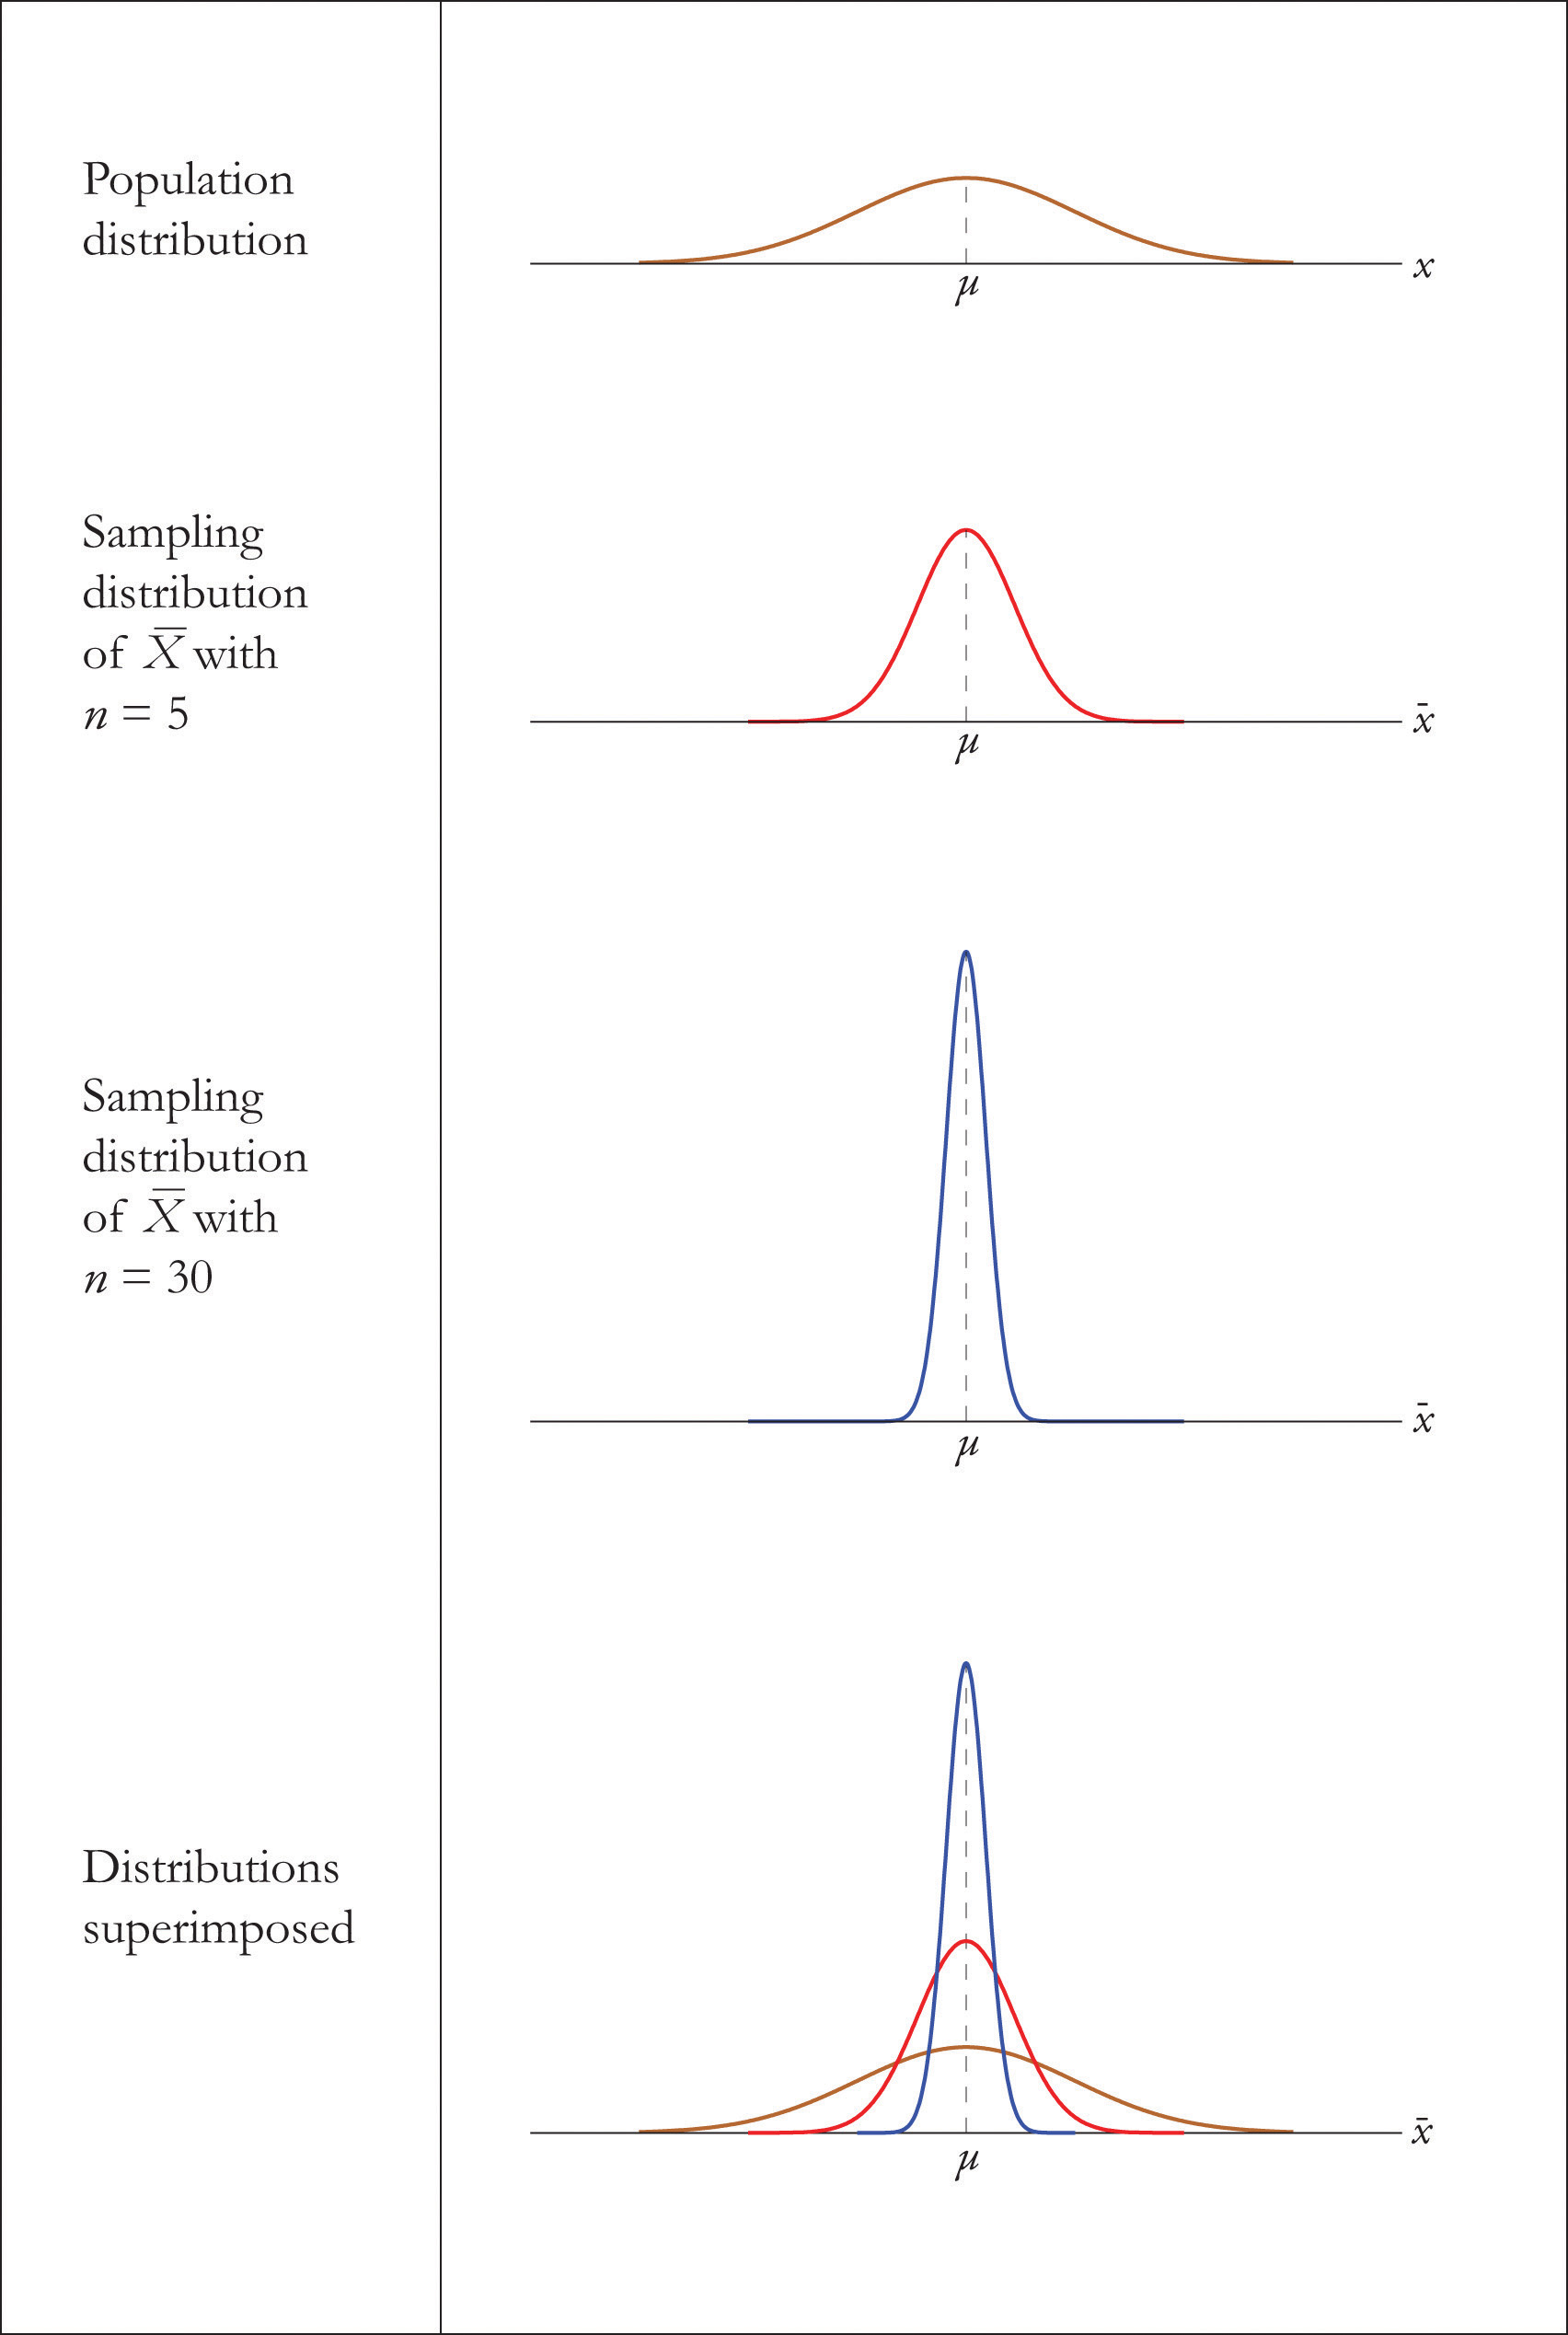
Start with your population. It can be real data or a simulated one. Pick a sample size n. Draw a random sample, calculate the mean, set it aside. Repeat this enough times — ideally thousands — and collect every mean you calculated. Plot those means as a histogram and you have your sampling distribution. In practice you do not actually repeat the physical sampling. You use the math. The central limit theorem tells you that if n is large enough, the sampling distribution of the mean will be approximately normal regardless of the shape of the original population. The mean of that sampling distribution equals the population mean. The standard deviation of that sampling distribution is the population standard deviation divided by the square root of n. This last part is called the standard error, and it is the number most people confuse with the regular standard deviation. Standard error = / n
That formula assumes you know the population standard deviation. When you do not, which is almost always, you substitute the sample standard deviation s and the distribution becomes a t-distribution instead of a normal one. The difference matters when n is small.
Get the Full Details
Why Your Results Look Wrong Even When the Math Is Right
I ran into this on a project a few years back where I was analyzing customer churn rates across regions. The underlying data was heavily right-skewed with a long tail of extremely long customer lifespans. Sample sizes per region ranged from about 30 to 90. My initial pass used the normal approximation for the sampling distribution of the mean and produced confidence intervals that were too narrow. The coverage was roughly 88 percent instead of the intended 95 percent. The fix was two-fold. First, I switched to the t-distribution with the appropriate degrees of freedom for each region. Second, I ran a bootstrap resampling procedure with 10,000 iterations to verify the interval widths. The bootstrap intervals were slightly wider than the t-based ones and matched the observed coverage much more closely. For anyone doing this at scale, bootstrapping takes about 10 to 15 minutes on a modern laptop for datasets of this size, compared to the near-instant calculation of the standard error formula.
Sampling Distribution For Mean: The Nuances Nobody Highlights
There are two things that tend to surprise people when they actually work with this concept beyond textbook problems. First, the rate at which the sampling distribution converges to normality depends heavily on the skewness and kurtosis of the population. A uniform distribution reaches approximate normality with a sample size around 25 to 30. An exponential distribution might need 50 or more. Heavy-tailed distributions like a Pareto or Cauchy can make the central limit theorem converge so slowly that no realistic sample size is sufficient. In those cases the sampling distribution for mean still exists but it will not look normal, and using z or t intervals will give you misleading results. Second, the standard error shrinks at a diminishing rate. Doubling your sample size reduces the standard error by about 29 percent, not 50 percent. Going from n=100 to n=400 cuts the standard error in half, but that requires four times the data collection effort. This is not a theory problem. It directly affects how much funding or time you need to allocate when designing a study. If your stakeholder says they want twice the precision, tell them they need four times the sample size, not twice.
Another practical issue is independence. The standard error formula assumes each observation in the sample is independent. If your data has any kind of clustering or autocorrelation, the effective sample size is smaller than the raw count. I once worked with survey data where respondents were grouped within schools, and the intraclass correlation was around 0.08. Treating the 600 responses as 600 independent observations understated the standard error by roughly 40 percent. The correction involved using a design effect multiplier of 1 + (average cluster size - 1) × , which in that case was about 1.6. Dividing the effective sample size by that factor gave a standard error that matched what a proper multilevel model produced.
When This Approach Breaks Completely
There are scenarios where relying on the sampling distribution of the mean is simply not appropriate and you should not force it. If your population distribution is extremely heavy-tailed and your sample size is under 100, the normal approximation can be dangerously inaccurate. Small sample sizes combined with high skewness are the most common combination that produces incorrect inferences. If you are working with binary or proportion data and the expected number of successes or failures is below 5, the normal approximation to the binomial breaks down. Use an exact binomial test or a beta-binomial model instead. When you need to make inferences about something other than the mean — medians, variances, percentiles — the sampling distribution of the mean is irrelevant. Bootstrap methods or permutation tests are more appropriate there. I usually default to bootstrapping for anything involving a median or a ratio of means because it bypasses the distributional assumptions entirely and gives you a direct empirical sampling distribution.
Finally, if your data are not randomly sampled from the target population, no amount of statistical machinery will fix the fundamental bias. A convenience sample of 10,000 observations will give you a very precise estimate of the wrong thing. The sampling distribution will be tight around a biased center, and confidence intervals will look deceptively reliable.
A Quick Reference For What To Check Before Proceeding
Before you calculate a standard error or build a confidence interval around a mean, verify these conditions in order. Check that your sample was drawn randomly or at least representatively from the population you care about. If the sampling frame is biased, stop here and address the selection issue first. Assess the shape of your data. Plot a histogram or a kernel density estimate. If the distribution is roughly symmetric and unimodal, proceed. If it is skewed, check the skewness value. A skewness magnitude below 1 is generally fine for sample sizes above 30. Between 1 and 3 requires larger samples or a transformation. Above 3 probably needs a nonparametric approach.

Verify independence. If your data are clustered, time-series, or spatially correlated, compute the design effect or use a model that accounts for the dependency structure. Decide whether you know the population standard deviation. In virtually all real-world cases you do not, so use the t-distribution with n minus 1 degrees of freedom. Only in rare situations, such as when you are working with a long historical record of process control data, does the population standard deviation approximate well enough to justify using the normal distribution. Calculate the standard error using s divided by the square root of n. If you have clustered data, adjust the effective sample size first. If your sample is small and the data are skewed, run a bootstrap to validate the result.
The math itself is straightforward. The careful work is in checking the assumptions and recognizing when the situation requires something beyond the basic formula. That distinction is what separates a routine calculation from an actual analysis.