Sampling in Statistics PPT: How It Actually Works
You pick up a template deck labeled Sampling In Statistics Ppt and expect it to hand you something clean and usable. Most don't. The ones that do are either way too simple or they copy-pasted definitions from a textbook without connecting the dots for your audience. Here is how to build one that isn't embarrassing to present. Start with the problem the slide deck needs to solve. Are you teaching introductory undergrads? Training junior analysts? Presenting to a board that thinks sampling means picking random data points out of thin air? The audience determines everything about structure, depth, and whether you even need to define population, parameter, and statistic separately or if they already know them. I once spent three hours trying to adapt a five-year-old Sampling In Statistics Ppt file for a regulatory review meeting. The original deck claimed simple random sampling and systematic sampling produced the same margin of error at equal sample sizes. That is mathematically wrong unless the population is perfectly homogeneous, which it almost never is. Systematic sampling carries an implicit risk of periodicity bias. If your population has a hidden cycle that aligns with your sampling interval, your confidence intervals are lying to you. I rewrote those slides entirely and added a note about the Neyman-Rao adjustment for stratified designs because the audience needed to understand why our variance estimates differed between methods. It took forty-five minutes of actual work instead of thirty minutes of clicking through broken templates.
Building Your Sampling In Statistics Ppt: A Practical Walkthrough
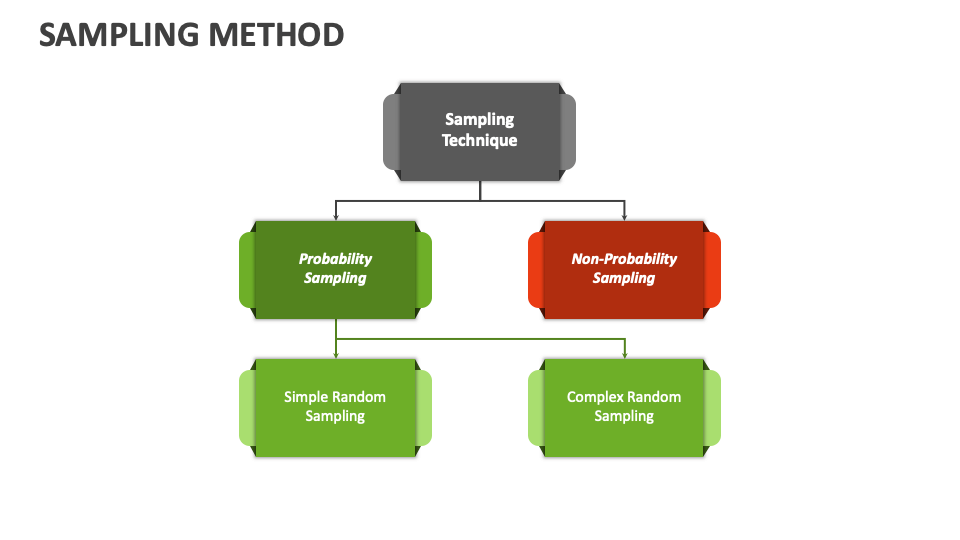
Open a blank presentation. Don't start with a title slide if you can avoid it. Start with a real dataset, one screen capture or a small table, and ask the audience to imagine selecting respondents from it. Concrete beats abstract every time. People remember the example where the 10th row happened to be an outlier because you designed the slide that way. They forget the definition of sampling frame. Slide two should cover sampling frames and why they matter more than anything else in the deck. A sampling frame is the actual list you draw from. If your frame excludes a segment of the population, no amount of fancy weighting fixes the fundamental coverage error. I learned this the hard way when a health survey used a telephone directory as its frame and systematically missed unlisted numbers. The initial response rate looked fine at seventy-two percent. After weighting adjustments, the true effective sample size dropped to something closer to fifty-eight percent of what we originally calculated. The was large enough that the published prevalence estimates were off by nearly four percentage points. That kind of thing doesn't show up in a clean textbook example. After frames, move into probability sampling methods. Cover simple random sampling, stratified sampling, cluster sampling, and multistage sampling. Present them in that order because each one solves a specific problem that the previous method introduces. Simple random sampling is clean in theory but expensive in practice when your population is geographically dispersed. Stratified sampling fixes efficiency but requires you to know meaningful strata beforehand. Cluster sampling sacrifices precision for cost but the design effect can inflate your variance estimates significantly. You need at least two slides to explain design effect properly because most people confuse it with standard error and apply it incorrectly in their own calculations.
For multistage sampling, include a concrete worked example. A national health survey that selects states, then districts, then households, then individuals within households demonstrates why the analysis isn't straightforward. The clustering means observations within the same household aren't independent. Ignoring that structure produces standard errors that are too small and p-values that are too optimistic. I've seen junior analysts publish results with false significance precisely because they ran a logistic regression on clustered survey data without using survey-weighted commands in Stata or R's survey package. The numbers looked normal. They weren't.
Get the Full Details
Non-Probability Methods and When They Actually Make Sense
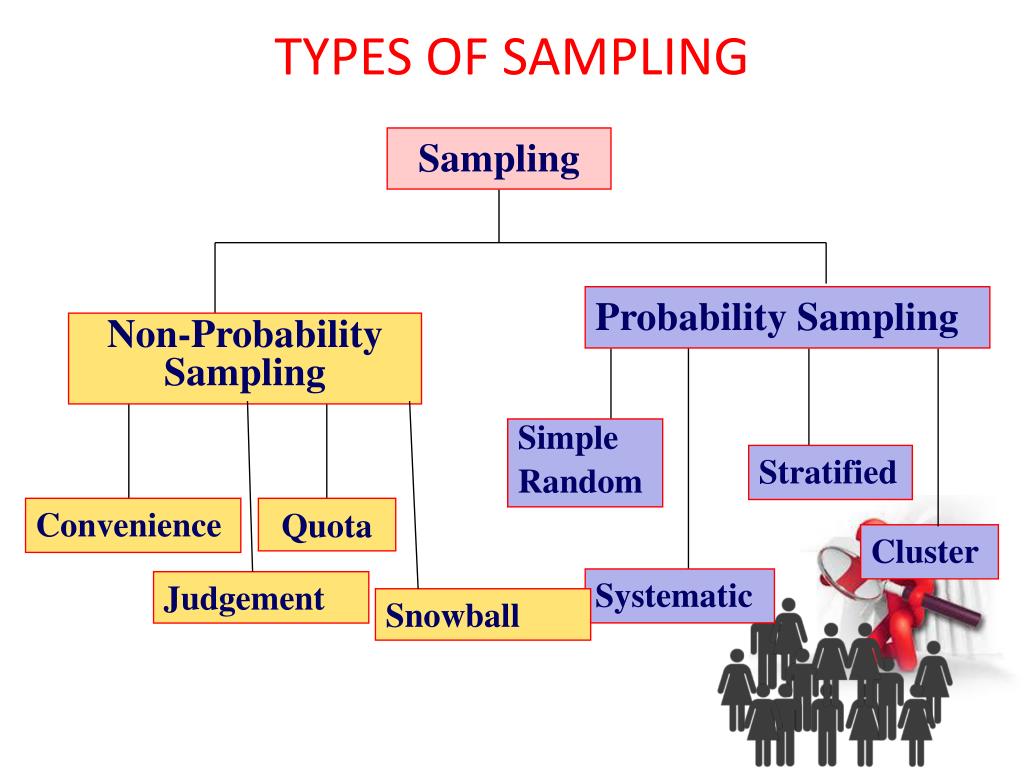
Convenience sampling, quota sampling, and purposive sampling belong in the deck even though everyone tells you to avoid them. They belong there because people use them constantly and need to understand what they're trading away. Convenience sampling gives you speed. Quota sampling gives you some control over demographic proportions without probabilistic selection. Purposive sampling lets experts target specific cases that would be invisible under random selection. The trade-off is always generalizability. You cannot calculate a sampling error for non-probability methods because the selection probabilities are unknown. That means no confidence intervals, no formal margins of error, no design-based inference. Some vendors and consultants pretend otherwise. They apply sampling weights to convenience samples and publish effective sample sizes as if the math still applies. It doesn't. I've flagged this in peer review and the authors either doubled down or quietly removed the misleading metrics. Both reactions tell you something useful about the field.
Sample Size Calculations Without the Textbook Confusion
Include a slide showing the basic sample size formula for a proportion: n equals Z squared times p times one minus p, all divided by E squared. Then immediately show why this formula breaks down in real survey work. It assumes simple random sampling, an infinite population, and perfect response rates. None of those assumptions hold in practice. Adjust for finite population correction when your sampling fraction exceeds five percent. Inflate for expected non-response by dividing your calculated n by the anticipated response rate. Account for design effect by multiplying by the cluster design effect, which ranges from one point five to three or more depending on how clustered your data actually is. I worked on a project where we calculated an initial sample size of eight hundred respondents for a political poll. After accounting for a twenty percent non-response rate, a design effect of two point one from clustered sampling, and the finite population correction for a known voter registry of two hundred thousand, the final required sample jumped to approximately one thousand four hundred. Eight hundred would have produced misleadingly tight confidence intervals. The difference between those two numbers is the difference between a defensible poll and one that looks precise but isn't.
Common Errors That Appear in Actual Presentations
One recurring mistake is presenting confidence intervals without specifying the confidence level. A ninety-five percent interval and a ninety-nine percent interval use different critical values and produce different widths. Another mistake is reporting point estimates alongside sample sizes that don't match the denominators used in the calculations. The denominator for a weighted proportion is not always the same as the unweighted respondent count. Some decks confuse standard error and standard deviation. They are different quantities measuring different things. Standard deviation describes variability in the population or sample. Standard error describes the variability of a statistic across repeated samples. Mixing them up in a single slide undermines the entire section that follows. Weighting without explanation is another failure mode. If you apply post-stratification weights, raking, or calibration weights, the audience needs to see what the margins were before and after adjustment. Weighting can stabilize estimates but it also increases variance. The effective sample size after weighting is usually smaller than the raw count. I add a dedicated slide to my presentations showing the before-and-after variance comparison because skipping it makes the weighting step look like editorial manipulation rather than a statistical correction.

What Makes a Good Sampling In Statistics Ppt Different
A useful presentation deck includes at least one scenario where the sampling method choices directly affect the conclusions. Show two analyses on the same data, one using naive simple random sampling formulas and one using the correct survey design approach. The estimated means might look identical but the confidence intervals will diverge enough to change the interpretation. That divergence is the single most educational moment in the entire deck. Keep the text density reasonable. Four bullet points per slide maximum. Any formula gets its own slide with the variables labeled. Tables should be readable on a projector without forcing the audience to lean forward. Use consistent color coding for different sampling methods across slides so the audience can track which method applies where without re-reading labels each time. Include a reference slide with citations to standard texts like Cochran's Sampling Techniques or Lohr's Sampling: Design and Analysis. You don't need to read from them during the presentation. The slide signals to anyone who knows the literature that you understand the source material and aren't reinventing terminology.
The Limitations Nobody Talks About
Even well-designed probability samples face coverage error, non-response bias, and measurement error. No sampling method eliminates all three simultaneously. Improving one usually worsens another in practice. Increasing follow-up attempts reduces non-response bias but raises costs and introduces volunteer bias among persistent respondents. Expanding coverage by adding internet panels reduces coverage error for younger demographics but introduces mode effects that are difficult to adjust for statistically. If your goal is generalizing to a clearly defined population, probability sampling with proper weighting is still the gold standard. If your goal is generating hypotheses or exploring patterns in hard-to-reach populations, non-probability approaches like respondent-driven sampling or quota sampling can be defensible, but you need to state the limitations explicitly and avoid language that implies broader generalizability than your method supports. A final practical note: most of the available Sampling In Statistics Ppt files online are either graduate-level lecture notes compressed into too few slides or introductory materials that skip the parts practitioners actually need. Building your own deck from scratch, even if it takes longer, usually pays off because you control the emphasis and you catch the errors before anyone else does.