What You Actually Need to Know Before Starting
Sap Data Intelligence Training isn't some self-contained course you enroll in and finish. It's more like a documentation labyrinth with a few official workshops thrown in for goodwill. The official material lives on the SAP Learning Hub and a handful of SAP Community pages, but the real knowledge—the stuff that stops your pipelines from breaking at 3 AM—has to be assembled from forums, GitHub repos, and years of other people's mistakes being posted publicly. I spent about six weeks mapping out a path that actually works for someone who already knows SAP on one side and Spark/Databricks on the other. Here's what that looked like.
Where to Start With Sap Data Intelligence Training
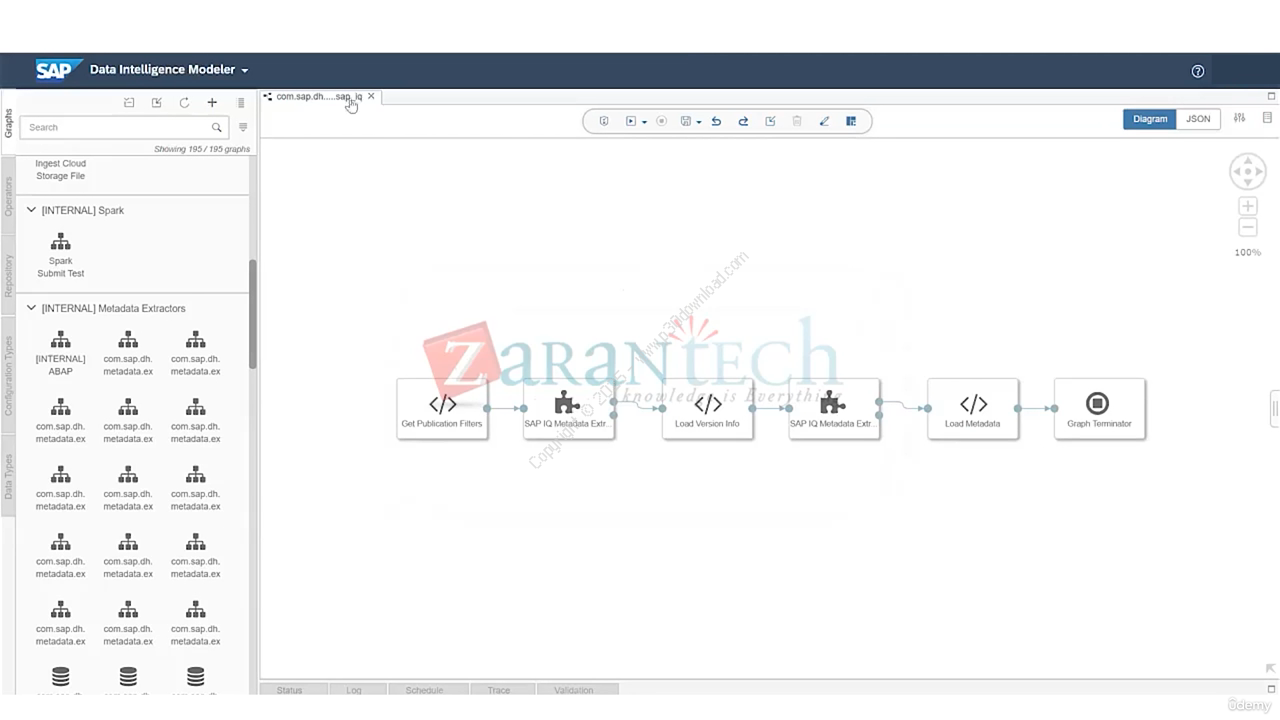
The official route begins with the SAP Learning Discovery zone. Search for "SAP Data Intelligence" and you'll find the "Visual Data Pipeline Developer" learning journey. It covers the basics: modeling graphs, dragging nodes onto a canvas, connecting to HANA, running a pipeline. The content is accurate. It's also thin on anything that deals with real-world scale. You'll finish it understanding how the tool works in a lab environment and still have no idea what happens when your graph has 40 nodes and one of them starts throwing intermittent connection timeouts. The more useful entry point is the SAP Data Intelligence documentation site itself. Start with the "User Guide" section, specifically the chapters on modeling and execution. Then immediately go to the "Administration Guide." Most training resources skip administration entirely, but you will need it. Understanding how the Kubernetes pods spin up, how the modeler talks to the graph server, and where logs actually live will save you more time than any node-placement tutorial ever will.
The Things Nobody Explains in the Official Material
One thing that trips up almost everyone: the difference between model execution and graph execution. When you're designing in the modeler, you test individual nodes. That works fine for a simple SQL query node pulling ten thousand rows. The moment you introduce a Python Script node that processes larger datasets, or you chain together a Kafka consumer feeding into a HANA insert, the modeler's test runner becomes practically useless. It doesn't reflect the actual resource allocation or the real serialization behavior between nodes. The workaround is to stop testing in the modeler for anything beyond the simplest nodes. Build the graph, deploy it, and use the trace and log features on the graph level instead. Enable the message trace on your connections, not just on individual nodes. You'll see where data actually stalls. Another counter-intuitive detail: the file system inside the containers is not persistent in the way you'd expect from a traditional ETL tool. If your Python Script node writes a temporary CSV and the next node reads it, that works until the pod reschedules. Then the file is gone and your pipeline fails silently on retry. I ran into this exact problem last year with a batch job that processed roughly 200,000 records per run. The pipeline succeeded 87% of the time and failed on the remaining 13% with no obvious error in the node logs. It took me three days to realize the intermediate temp file was disappearing because the pod had been rescheduled by Kubernetes between the write and read steps. The fix was straightforward once I understood it: route the intermediate data through a persistent volume claim mounted across both nodes, or better yet, push the data through a HANA table or S3 bucket instead of relying on container-local filesystems. That cut our failure rate to essentially zero.
Get the Full Details

Practical Learning Path That Actually Works
Here's the sequence I'd recommend, assuming you have access to an SAP Data Intelligence trial or on-premise instance: First, complete the official Visual Data Pipeline Developer learning journey on the Learning Hub. Don't skip it even though it's shallow. It gives you the vocabulary and the UI navigation speed that you'll need later when you're troubleshooting at eight in the morning. Then move to hands-on practice with a deliberately broken graph. Build a pipeline that consumes JSON from a public API, transforms it with a Python Script node, and loads it into HANA. Intentionally make it fail by introducing a schema mismatch and a missing dependency in the Python environment. The debugging process here teaches you more than any successful demo ever will. Learn how to read the execution log, how to SSH into a container from the modeler, and how to check the system load on your cluster from the operation board.
After that, study the administration side. Learn how to scale the worker nodes, how to configure authentication, and how the certificate management works. The certificate thing alone will bite you if you don't understand it. When your modeler can't connect to the graph server after a restart, it's almost always a certificate issue, not a network issue.
Where This Tool Falls Short
I should be honest about the limitations. SAP Data Intelligence is not a good fit for lightweight, ad-hoc data integration. If you need to move data between two systems quickly without a lot of orchestration overhead, tools like Apache Airflow or even simple Python scripts with requests and pandas will get you there faster and with less operational complexity. The learning curve is steep, the cluster requires real infrastructure to run properly, and the monitoring capabilities, while improving, still lag behind what you get from purpose-built data engineering platforms. It also doesn't integrate cleanly with non-SAP ecosystems. If your organization is heavily invested in Azure Data Factory, Databricks, or AWS Glue, pulling SAP Data Intelligence into that stack adds friction rather than value. The strength of this tool is when you're already deep in the SAP ecosystem—HANA, SAC, C/4HANA, and the like—and you need unified pipeline orchestration that understands SAP-specific data types and protocols natively. The community support is another gap. Compare the active discussion volume on Stack Overflow and GitHub for SAP Data Intelligence against something like dbt or Airflow and the difference is stark. When you hit an edge case, you're often on your own or digging through SAP Notes from 2019 that reference a version you're not even running anymore.
Resources That Are Actually Worth Your Time
Beyond the official SAP Learning Hub content, the SAP Community website has a dedicated section for Data Intelligence. The blog posts from SAP engineers there tend to be the most current and technically accurate information available. Look for posts about version-specific changes, especially when a new major release drops. GitHub repositories with sample graphs and pipeline templates are scattered but useful. Search for "SAP Data Intelligence pipeline examples" and you'll find several community-maintained repos. These aren't production-ready, but they're good starting points that save you from building every node from scratch. The SAP Help Portal remains the most reliable reference document. Bookmark the section on Python Script nodes and the section on message traces. Those two areas come up repeatedly in real-world debugging.
If you can get access to an SAP classroom course, it's worth it, but manage your expectations. The instructor-led sessions cover the tool well at an introductory level. The advanced topics—the kind that matter for production deployments—are still largely learned through trial, error, and reading other people's incidents posted on the community forums.