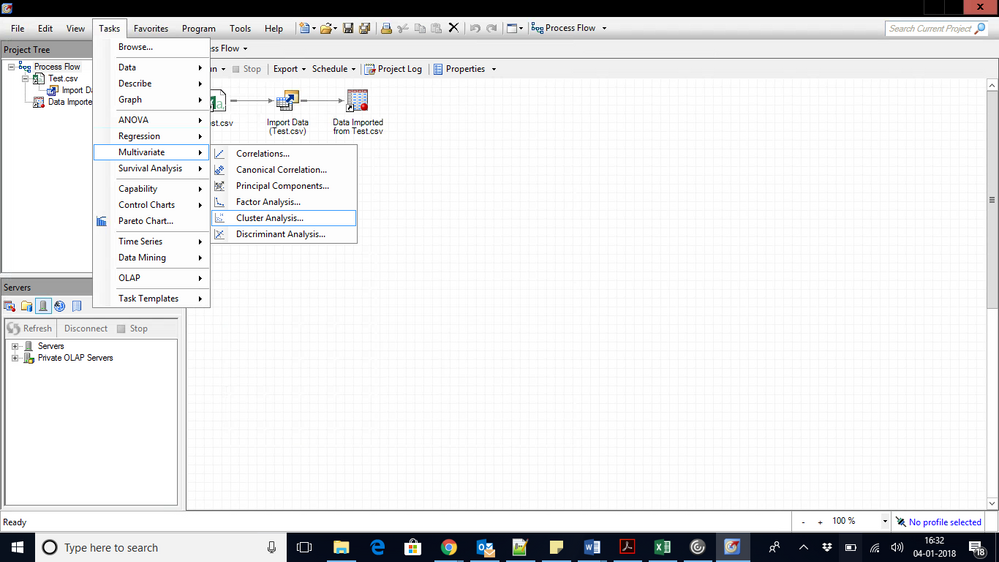
Running Cluster Analysis in SAS Enterprise Guide
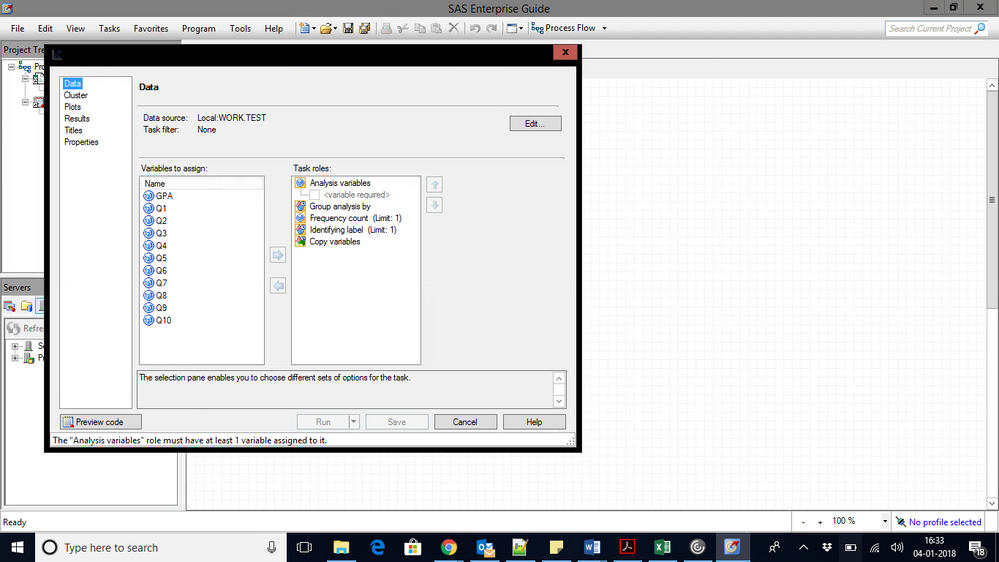
You open Enterprise Guide, navigate to the Tasks menu, and look for the clustering option. It is buried under Process Mining or the Analytics tab depending on your version. This is where most people hit their first wall. The interface does not hand you anything clean. You select a dataset, point it at a PROC CLUSTER–based task, and then you realize you have to wrestle with the output just to get a basic dendrogram out of it. At its core, cluster analysis in Enterprise Guide wraps the underlying SAS/STAT procedures—primarily PROC FASTCLUS for initial partitioning and PROC CLUSTER for hierarchical methods—inside a point-and-click framework. You supply a dataset, choose variables, pick a method, and the task generates code in the background. The guide then displays results through ODSTables, ODSGraphs, or a tree view if you are using hierarchical clustering. The actual mechanics are straightforward. The procedure computes distances between observations using one of several metrics: Euclidean is default, City Block is an option, and standardization matters enormously here. If your variables are on different scales and you skip the standardize step, the variable with the largest raw range dominates the distance calculation. I have seen this sink more projects than I care to count.
Here is the thing nobody tells you when they start using the tool: the point-and-click interface generates code that looks reasonable, but it often defaults to settings that are wrong for your data. The standardization checkbox in the task dialog is unchecked by default. It should almost never be left unchecked unless your variables are already on a comparable scale. Similarly, the number of clusters is rarely obvious from a single run. You typically need to execute the task multiple times with different K values and compare the pseudo-statistics that come out.
The Workflow I Actually Use
I start by cleaning the data. Missing values in a cluster analysis are not handled gracefully by the default settings. PROC FASTCLUS throws observations with any missing value into a separate handling path, and PROC CLUSTER simply drops them. If you do not inspect the missingness pattern first, you will end up with fewer clusters than you expect and no idea why. I run PROC MEANS with the MISSING option and check the N column before doing anything else. Then I standardize. I use PROC STANDARD before feeding the data into the clustering task. It is faster and more transparent than letting Enterprise Guide do it internally, and you can verify the output. The wizard generates a DATA step that calls PROC STANDARD, but if you control it directly you avoid the silent recalculation that sometimes happens when you rerun tasks after changing parameters. For the actual clustering, I start with PROC FASTCLUS to get a reasonable initial partition, then refine with PROC CLUSTER if I need a dendrogram or a hierarchical view. The Enterprise Guide task for hierarchical clustering produces the dendrogram graphic and the cluster membership table. The graphic itself is adequate for quick visual inspection, but it is not publication quality. I usually pull the cluster membership into a new dataset and generate a cleaner visualization separately.
Get the Full Details
Choosing K is the hardest part. The pseudo-statistics—pseudo F, pseudo T-squared, C-stats—help but they are not decisive. I run the task for K equals 3 through 8, write the results to a dataset, and then plot the within-cluster sum of squares against K to look for the elbow. It is a mundane process, but it works more often than the alternatives. The heuristic approach in the task dialog will suggest a K based on the largest change in clustering metric, but that suggestion is frequently off by one or two clusters.
A Problem I Hit With Sas Enterprise Guide Cluster Analysis
There was a specific case where I was analyzing customer transaction data with roughly 400,000 rows and 23 numeric variables. The hierarchical clustering task in Enterprise Guide hung for over an hour and then failed with an out-of-memory error. The issue was not the data size alone—it was the distance matrix. PROC CLUSTER with the average linkage method tried to allocate a 400,000 by 400,000 matrix, which is roughly 1.2 terabytes of storage in floating point. The software would not handle that regardless of how much RAM you had available. The workaround was to use PROC FASTCLUS first to reduce the dataset to representative centroids, then run PROC CLUSTER on those centroids instead. The initial FASTCLUS pass with K set to 50 took about three minutes. The subsequent hierarchical clustering on 50 points produced the dendrogram I needed in under thirty seconds. I then mapped each original observation back to its FASTCLUS cluster and used the centroid dendrogram to interpret the structure. It is not perfect—some nuance is lost—but it is practical.
Things That Go Wrong and How to Fix Them
The first common failure is ignoring outliers. A handful of extreme observations can distort the distance calculations so badly that the remaining observations form meaningless clusters. I usually run PROC UNIVARIATE on each candidate variable before clustering and cap values at the 1st and 99th percentiles. Winsorization, not deletion. Deleting outliers indiscriminately removes real signal. The second issue is collinearity. If two variables are highly correlated, they effectively double-weight that dimension in the distance calculation. I run PROC CORR and remove or combine variables with correlations above 0.85. Principal component analysis is a common alternative approach here, and Enterprise Guide has a PCA task you can run beforehand to produce uncorrelated components, then cluster on those instead. Another thing to watch: the task generates a cluster summary table, but it does not validate cluster quality by default. You need to look at the inter-cluster distances and the compactness measures yourself. If the smallest inter-cluster distance is less than the average within-cluster distance, you probably have overlapping clusters that should be merged. The software will not warn you about this.

When the Tool Breaks Completely
SAS Enterprise Guide is not built for massive datasets or production-grade reproducible pipelines. It is a front-end wrapper. If you need to cluster ten million rows, automate weekly re-clustering, or integrate the analysis into a CI/CD pipeline, you are better off writing the PROC statements directly in the code editor and running them through SAS Studio or batch mode. The task interface adds overhead at every step—parameter validation, UI refresh cycles,ODS output capture—and it silently changes behavior when you upgrade versions. I have seen clustering tasks that worked in Guide 8.3 produce different default options in Guide 9.4 after a patch, and the generated code was subtly different enough that the results shifted without anyone noticing immediately. If you are working with high-dimensional data—more than about fifty variables—the curse of dimensionality makes distance-based clustering unreliable regardless of the software. In those cases, dimension reduction is mandatory before clustering, and the Enterprise Guide interface gives you no assistance with that decision. You need to know when to stop and write the code manually.
Practical Steps to Get a Result
Create or select your input dataset. Ensure all variables are numeric. Handle missing values explicitly—either impute them or remove the observations. Run PROC STANDARD to standardize the variables. Execute PROC FASTCLUS with a preliminary K to check cluster stability. Write the centroids to a dataset. If you need a dendrogram, run PROC CLUSTER on the centroids with the method you prefer. Extract the cluster assignments and merge them back to the original data. Validate the clusters by comparing means across groups using PROC UNIVARIATE or PROC MEANS. Document the parameter choices because the next person who runs this task will not see your reasoning in the .egp file. The process is not glamorous. It takes longer than you expect on the first run because you are learning what the default settings assume. But once you have the pattern down, you can produce a defensible clustering result in roughly twenty to thirty minutes for a moderate-sized dataset on a typical workstation. The Enterprise Guide interface saves you from writing the boilerplate, but it also hides enough that you need to understand what is happening underneath or you will trust output that looks convincing and is actually wrong.


