Setting Up a Basic SAS Program
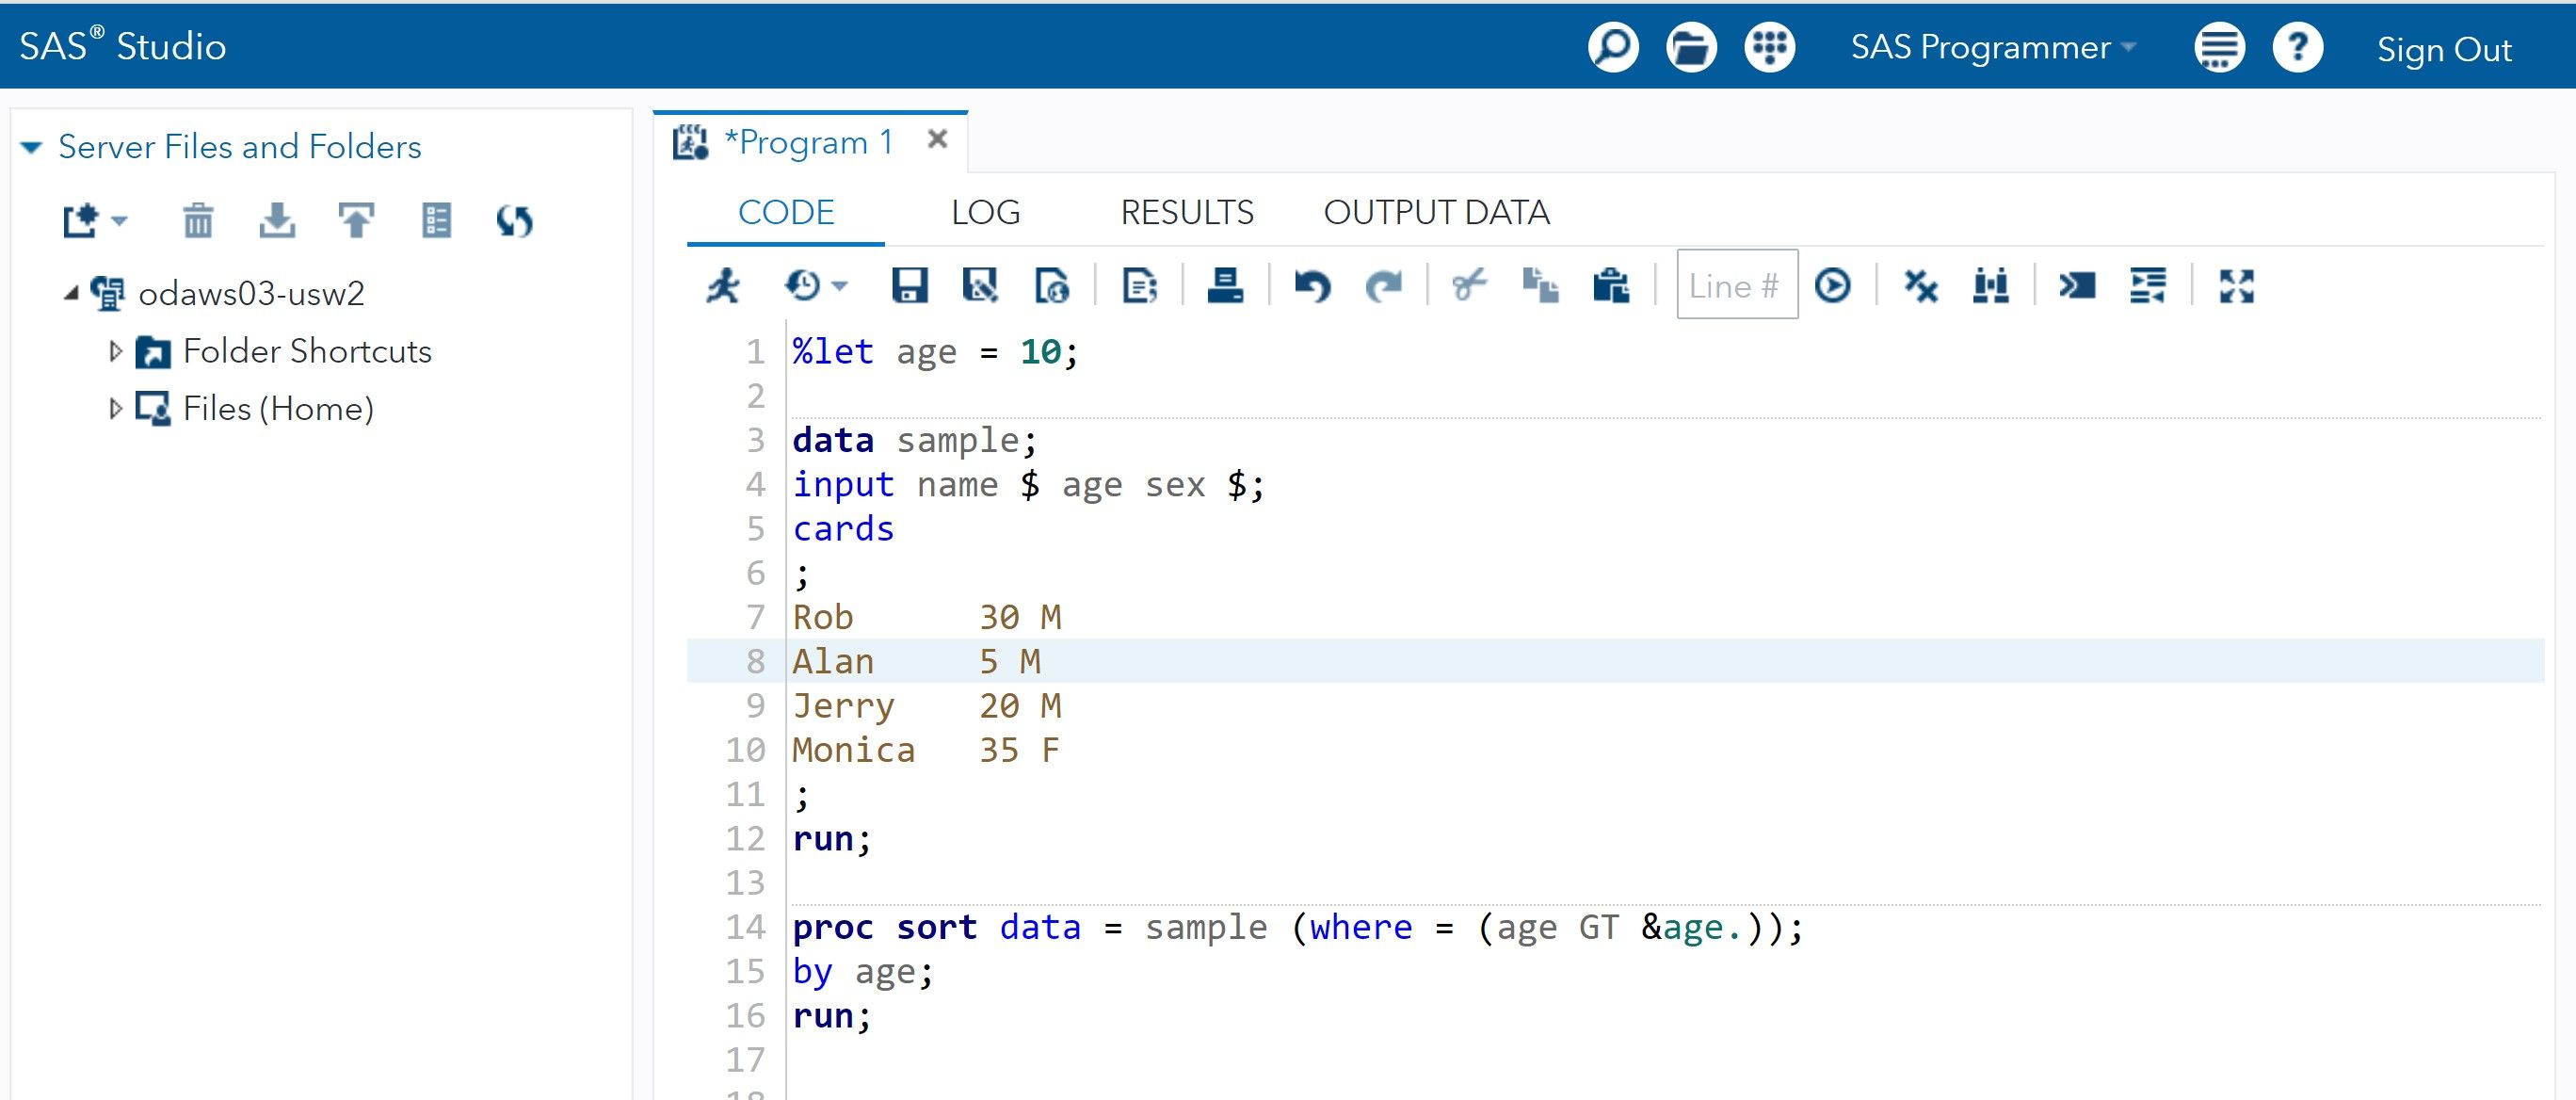
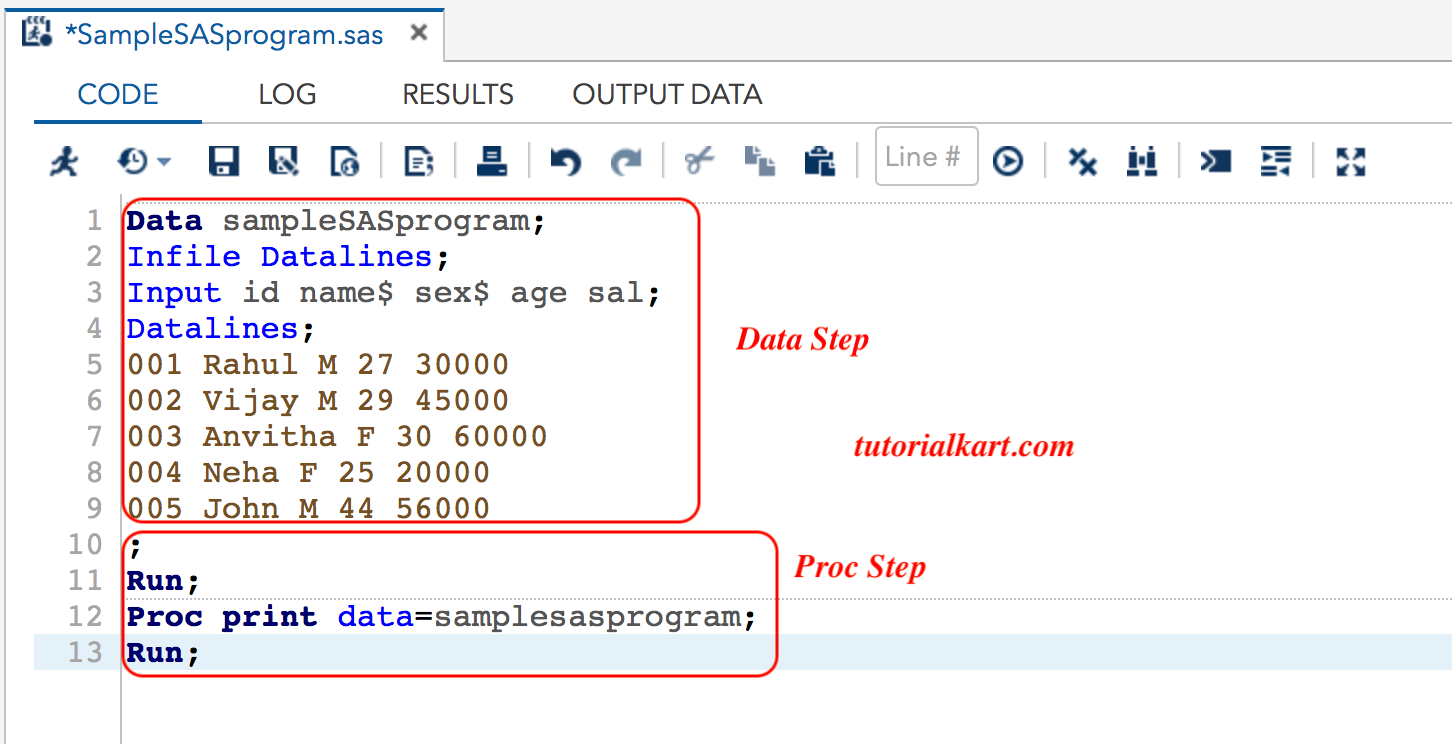
SAS (Statistical Analysis System) is a software suite built for data manipulation, statistical analysis, and reporting. It runs on Windows, Linux, and mainframes. The core language is procedural, meaning you write step-by-step instructions that execute sequentially. Unlike Python or R, where you can throw together a quick script and iterate in seconds, SAS compiles and executes in distinct phases. That structural quirk shapes everything about how you write code. A typical program starts with a LIBNAME statement to point at your data source, followed by a DATA step to read, transform, or create datasets. Then you move into PROC steps for analysis. Here is a minimal working example that reads a CSV file, filters records, and produces a frequency table:
Sas Programming Language Example: Basic Data Step and Proc Freq
data work.sales_filtered;
infile "/path/to/sales.csv" dsd firstobs=2;
input customer_id $ region $ product $ amount date :date9.;
format date date9.;
where region in ("West", "East") and amount > 100;
run; proc freq data=work.sales_filtered;
tables region * product / nocum nopercent;
run; The DSD option in the INFILE statement tells SAS to treat commas as delimiters and to handle quoted strings properly. Firstobs=2 skips the header row. The :date9. informat reads dates in DDMMMYYYY format. Without that colon modifier, SAS would try to interpret the raw text literally and give you missing values.
I spent about forty-five minutes last month debugging a dataset import that was silently dropping 3,000 rows. The issue was a trailing space in a character variable that my WHERE clause didn't account for. SAS treats "West" and "West " as different values. The fix was adding a STRIP() function around the comparison: where strip(region) in ("West", "East"). That cost me an hour of my day, but it is the kind of detail that catches everyone at some point.
Get the Full Details

Understanding the DATA Step Mechanics
The DATA step is where most of the work happens. It reads observations one at a time from an input dataset or external file, applies transformations, and writes them out. SAS maintains an implicit loop. You do not write DO WHILE or DO UNTIL unless you need one. Each iteration processes one observation. The program automatically returns to the top of the step until the input is exhausted. One thing beginners miss is that SAS compiles the entire DATA step before it begins executing. During compilation, it determines the length of character variables, the order of variables in the output dataset, and the types of all variables. This means if you use a LENGTH statement, it must appear before the first reference to that variable in the step. If you put it after, SAS has already assigned a default length of eight characters and your truncation problems are already baked in. Another counter-intuitive behavior involves the automatic variables _N_ and _ERROR_. The _N_ counter increments once per iteration of the DATA step. The _ERROR_ flag is set to 1 whenever SAS encounters a data irregularity, like attempting to convert a character string to numeric. The flag resets to 0 at the start of each new iteration. I once had a report where half the numeric conversions failed silently because a source field had leading whitespace in about twelve percent of the records. The data step never flagged it as an error condition across the board because _ERROR_ reset each iteration. The workaround was to add an explicit check with an IF _ERROR_ then call symputx to log which observation caused the problem.
PROC Steps and Output Management
Procedures in SAS are modular. Each PROC step does one type of analysis and produces output in ODS (Output Delivery System) format. By default, output goes to the RESULTS window in SAS Studio or Enterprise Guide. You can redirect it to HTML, PDF, RTF, or Excel using ODS statements. This is useful when you need to generate reports programmatically without manual export steps. For example, wrapping a PROC REPORT step with ODS PDF lets you produce a printed document directly. The code below generates a simple summary table and saves it as a PDF: ods pdf file="/path/to/output/report.pdf";
proc report data=work.sales_filtered nowd;
column region product sum(amount);
define region / group;
define product / group;
define amount / sum;
run;
ods pdf close;
The nowd option suppresses the default listing output and sends everything to the ODS destination. Without it, you get both a PDF and a listings file, which doubles your disk usage and slows things down on large reports. Macro variables are another piece of the toolchain that deserves attention. They let you parameterize your code. A simple macro variable can hold a date range, a file path, or a list of regions. You define them with %LET or through PROC SQL INTO. Using them keeps your code reusable and makes it easier to run the same analysis across different time periods without rewriting the WHERE clause.
Performance Considerations
SAS handles large datasets well, but it has limits. The platform processes data in memory and temporary disk storage under WORK. On a standard workstation, a dataset larger than available RAM will spill to disk, which slows processing significantly. I ran a merge operation on two 15GB datasets last year on a machine with 32GB of RAM. The job took about six hours because SAS was constantly swapping. Splitting the merge into smaller chunks by region cut the runtime to roughly forty minutes. Indexing helps for retrieval but not always for bulk operations. Creating an index on a variable used in a WHERE clause can speed up subsetting, but the index itself must be read into memory. For a dataset with ten million rows and a low-cardinality index like REGION, the performance gain is negligible. The overhead of maintaining the index often outweighs the benefit unless you are doing frequent individual lookups rather than full-table scans. One bottleneck that is easy to overlook is the default encoding. SAS defaults to Latin1 for file I/O unless you specify otherwise. If your source data contains accented characters or non-ASCII symbols and you do not set the proper encoding in the OPTIONS statement, the data arrives mangled. The fix is a single line at the top of your program: options setenv=LATIN1; or options encoding=utf8; depending on your source. I have seen this cause subtle corruption in customer name fields that took two days to trace back to an encoding mismatch between the export tool and the SAS session.
Limitations and When to Look Elsewhere
SAS is not the right tool for every job. It is expensive to license, especially for cloud-based deployments. The syntax is verbose compared to modern alternatives. If you need rapid prototyping, interactive visualization, or machine learning workflows with frequent model iteration, Python or R will save you significant time. SAS shines in regulated environments where audit trails, reproducibility, and data governance matter more than development speed. Industries like pharmaceuticals, banking, and insurance use it because the platform enforces consistent processing and provides documented validation paths. If you are starting fresh and do not have a SAS license, you can download a free educational version from the SAS website. The trial includes SAS University Edition, which runs in a virtual machine. It is sufficient for learning the language but not for production-scale work. For serious analysis, you need institutional access or a commercial license.