Reading Source Code for SCA: What Actually Matters
Most people treat SCA as something that just scans packages and spits out vulnerabilities. That's a third of the picture. The other two-thirds involve understanding what your code is actually doing with those packages, whether it's calling vulnerable functions, passing unvalidated data through tainted sinks, or shipping configs with hardcoded secrets. Without looking at the source, you're flying blind on a lot of real risk. I've spent years pulling apart dependency trees and tracing call graphs across monorepos. Here's how the source side of SCA actually works when you stop glossing over it.
What Is Sca Source Code Analysis
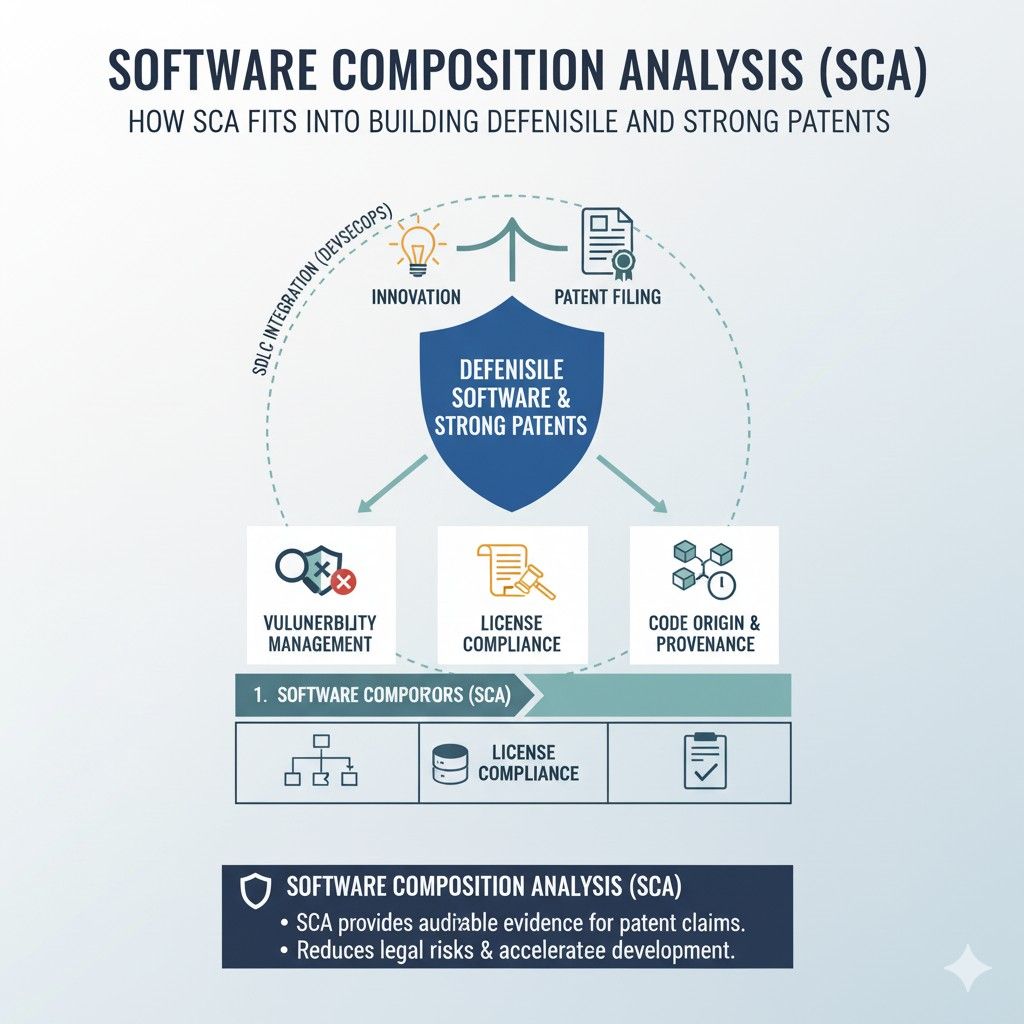
It's the practice of examining your application's own code to understand how dependencies are consumed, where vulnerabilities can be reached, and what custom logic might introduce risk that a package-level scan would miss entirely. Traditional SCA tools look at your lockfile and compare hashes against vulnerability databases. Source code analysis looks at your code and traces which of those packages get invoked, with what inputs, and under what conditions. The output isn't just a list of vulnerable packages. It's a map showing you whether a vulnerable function in a package like Log4j is actually reachable from your codebase, whether someone is sanitizing the input before it gets passed through, and whether you're using the risky code path or one that was patched in a later version.
How It Works Under the Hood
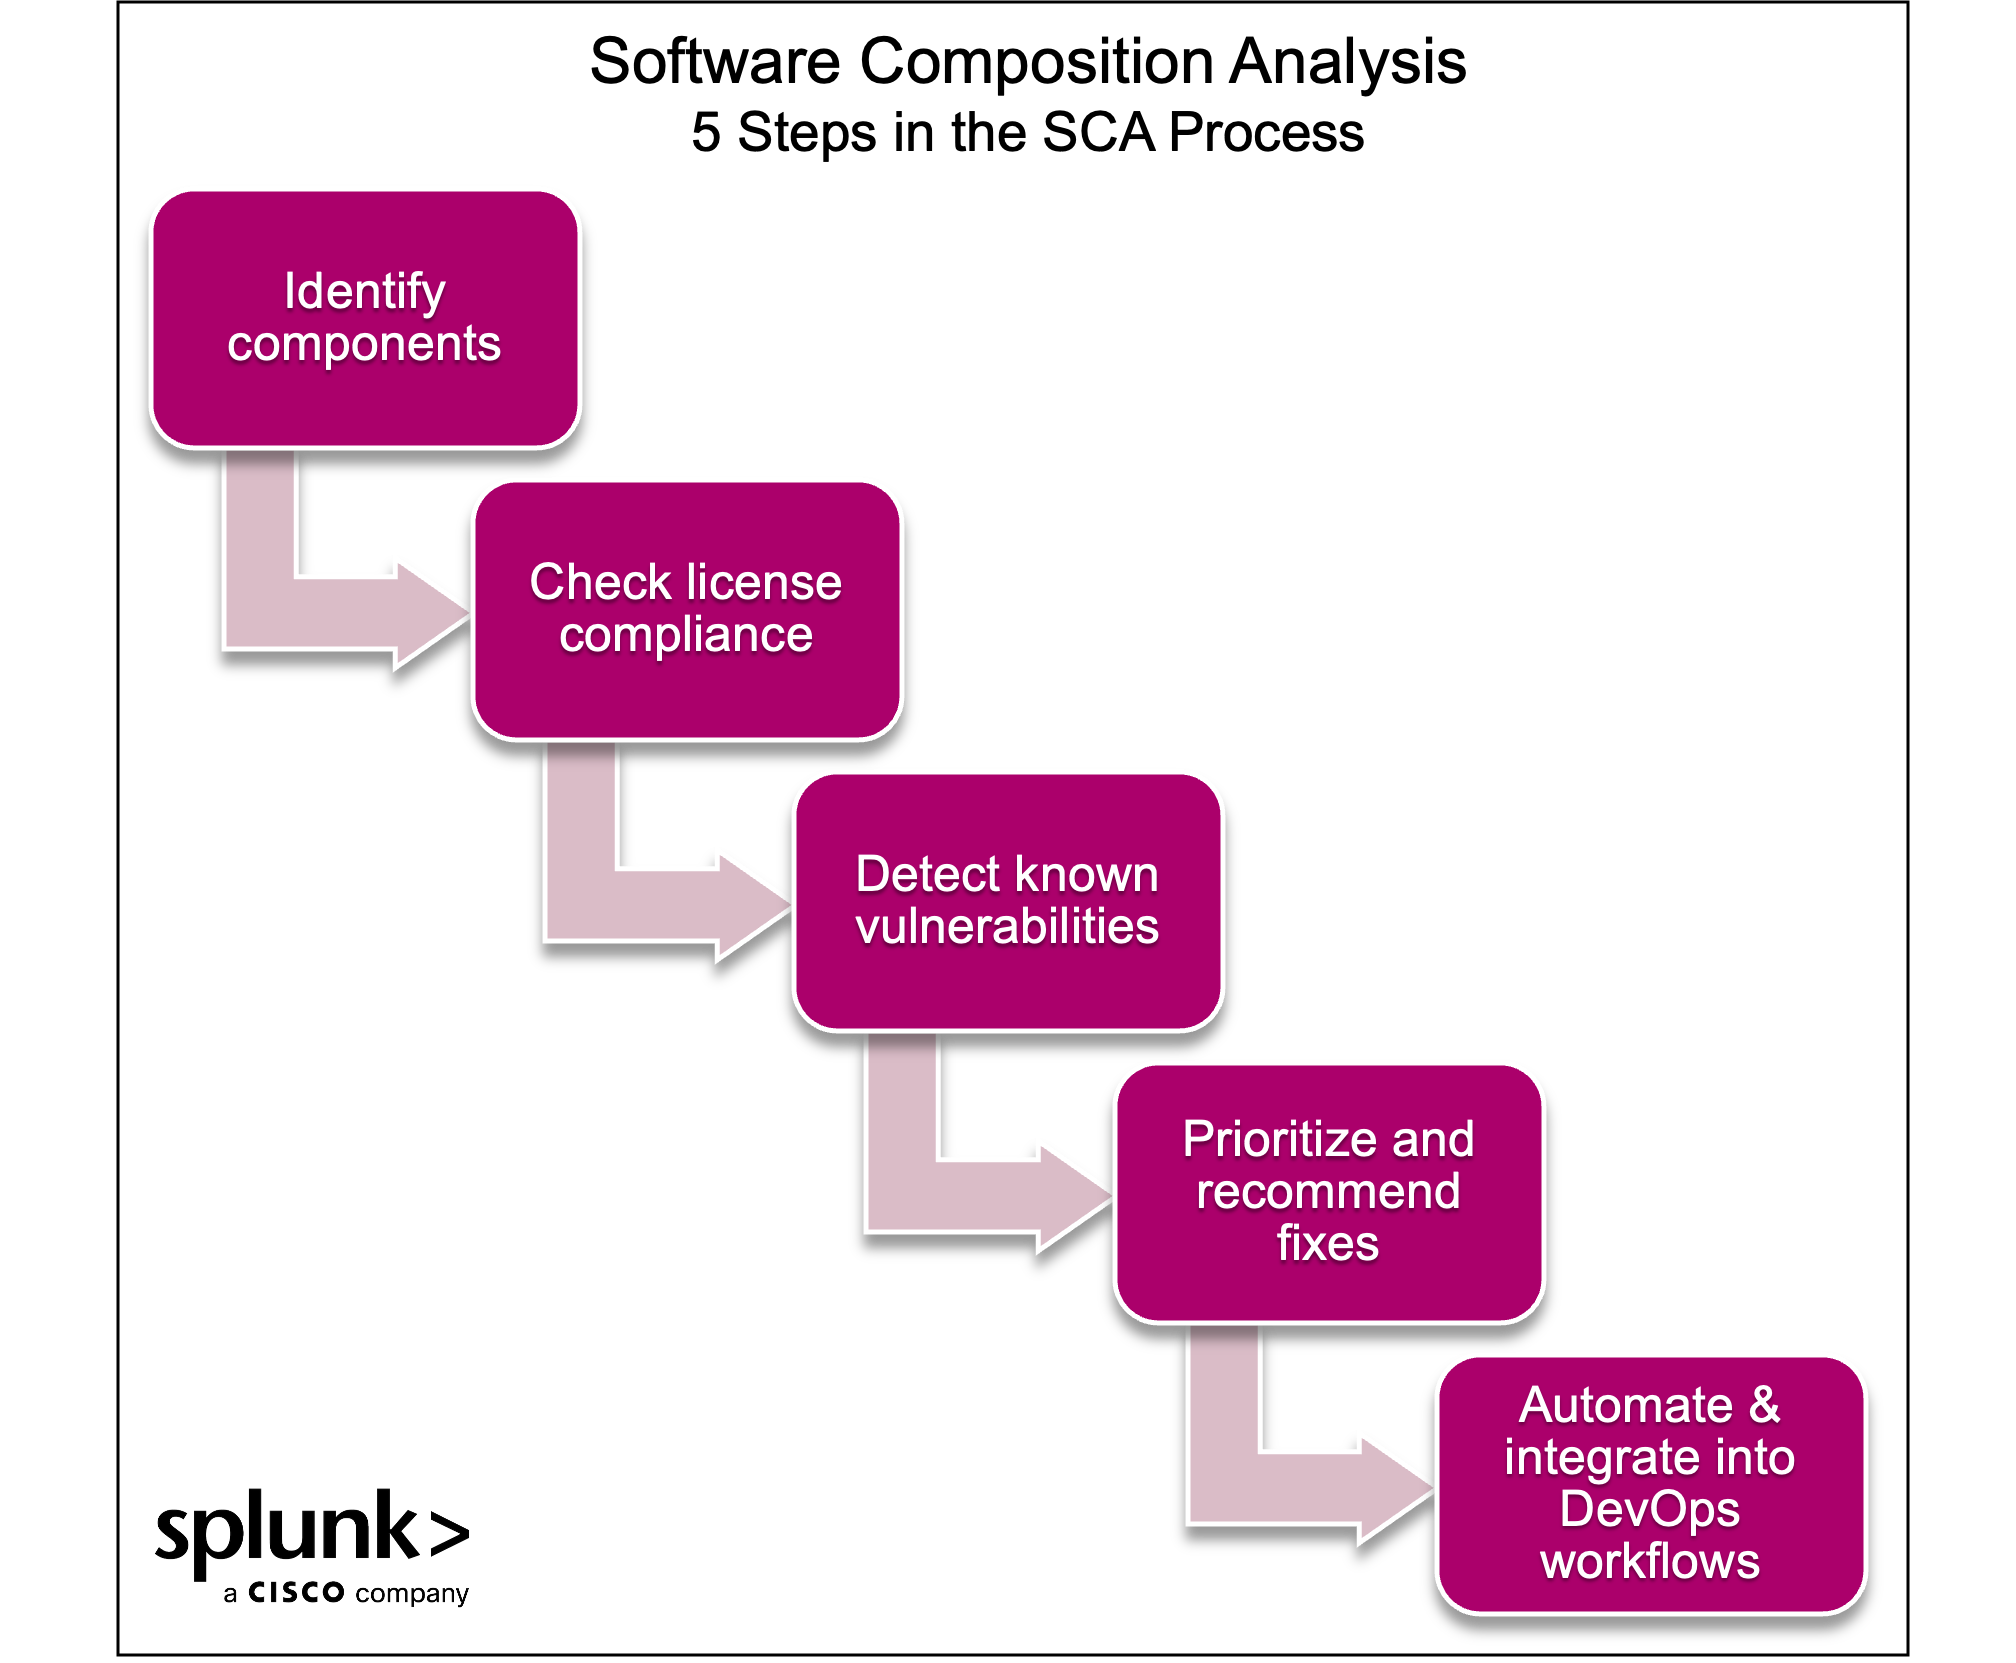
Source code analysis for SCA typically runs through three stages. First, your code gets parsed into an abstract syntax tree or control flow graph depending on the tool. Second, the tool traces data flow from sources — user input, environment variables, file reads — through your code to sinks where external libraries get called. Third, it cross-references those call sites against known vulnerability signatures to see if tainted data reaches dangerous functions. Some tools do this statically, analyzing code without running it. Others instrument runtime behavior to build call graphs from actual execution. Both approaches have trade-offs. Static analysis catches more code paths but generates false positives when it encounters conditional logic it can't resolve. Dynamic analysis is more accurate about what's actually reachable but only covers what your test suite exercises. I remember working on a Java project where a static analyzer flagged a critical vulnerability in commons-text, but my manual trace of the source code showed that every call path to the vulnerable GossipDigestAbsDigest function went through a middleware layer that stripped the special characters the exploit required. The package was technically vulnerable, but our code made exploitation impractical. That gap between static findings and actual risk is exactly why source code analysis matters.
Get the Full Details
Setting Up Source Code Analysis in Your Pipeline
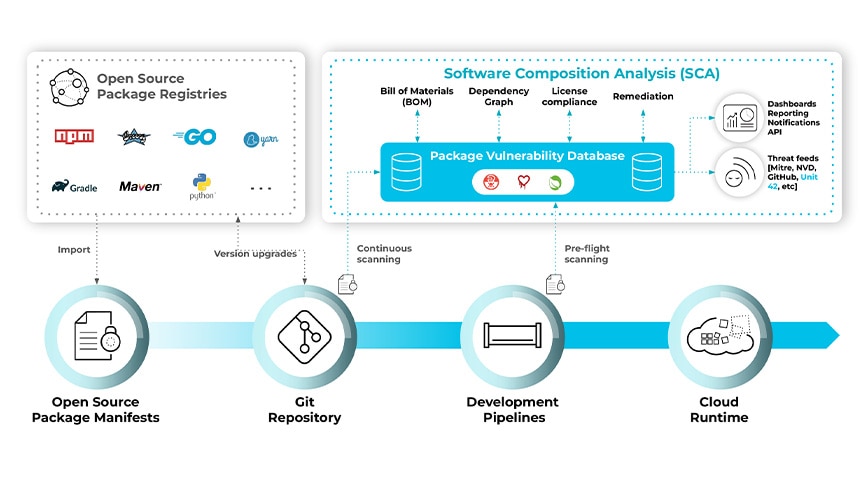
Start by picking a tool that fits your stack. Semgrep is straightforward for generic pattern matching across languages. CodeQL gives you deeper graph-based analysis but has a steeper learning curve. Snyk and SonarQube both offer source-aware SCA as part of their platforms if you want something more packaged. Configure your scanner to parse your actual source files, not just your dependency manifest. In most tools this means pointing it at your root directory rather than just your package.json or requirements.txt. Make sure it's configured to include test files too, because attackers don't care which folder your vulnerable code lives in. I once skipped including test utilities in a scanner config and missed a credential leak that had been sitting in a test helper for eight months. Here's the part nobody likes: you need to tune your rules. Out-of-the-box policies will flag everything from hardcoded API keys to unvalidated deserialization calls, which sounds useful until you're getting 4,000 results and can't tell what actually matters. I started by running the scanner against a known-good commit in my repo, collecting the baseline findings, and then building exclusion rules around patterns I verified as safe. This cut my noise from roughly 3,000 findings down to maybe 150 that needed actual review.
Common Mistakes That WASTE Your Time
The biggest one is treating source code analysis as a one-time setup. Your code changes constantly. New packages get added, refactors happen, someone copies a snippet from Stack Overflow. If you're not re-scanning on every pull request or at minimum daily, you're just maintaining a stale report. The analysis itself takes longer than you think. A full pass across a mid-sized Python codebase with around 200 dependencies and 50,000 lines of code typically runs in about 8 to 12 minutes on a decent runner. JavaScript projects with heavy transpilation can take 20 minutes or more because the AST has to account for the compiled output, not just the source. Another mistake is assuming the tool understands your framework's conventions. Flask apps, Django projects, React components, Spring Boot services — each has patterns where data flows through hooks, decorators, or middleware that most scanners don't natively understand. I spent two weeks chasing false positives in a FastAPI project where route handlers used a custom decorator that the scanner interpreted as a new entry point for every request. Once I wrote a Semgrep rule to recognize that decorator pattern, the noise dropped by about 60 percent.
Advanced: Building Custom Detection Rules
This is where source code analysis becomes genuinely useful instead of just another checkbox. Generic rules catch generic problems. Custom rules catch the problems your codebase actually has. For Semgrep, you write rules in YAML that describe patterns using the language's syntax. A typical rule for finding unsafe use of a library function looks like this: you define the pattern as a function call with a specific signature, then specify a metadata tag linking it to a CWE or CVE, and add a fix suggestion if you know one. Writing these takes patience. The first rule might take an hour. By the tenth you're doing them in fifteen minutes. CodeQL requires writing queries in a dedicated query language that operates on the code's graph representation. The learning curve is real, but the queries you write can capture relationships that no pattern-matching tool can. A query I wrote for tracking SQL injection vectors through a Java ORM layer — following parameter binding through three layers of repository methods and service calls — took about six hours to get right. It caught an injection point that every other tool in our pipeline had missed.
When Sca Source Code Analysis Fails You
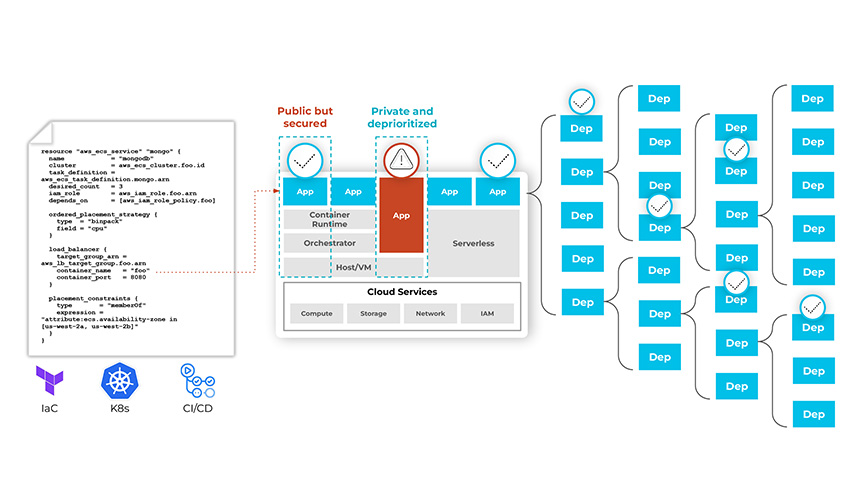
Let me be straight about the limitations. If your codebase is heavily obfuscated, minified, or uses dynamic code generation — eval calls, reflection-heavy frameworks, runtime code assembly — static analysis breaks down. You're not going to get meaningful results from a tool trying to trace data through JavaScript that constructs function names at runtime. In those cases you need instrumentation or fuzzing instead. Another hard limit: SCA source analysis doesn't understand business logic. It can tell you that user input flows into a database query without sanitization. It can't tell you whether that query is supposed to accept that input in your specific application context. A junior developer reading the findings will waste hours investigating a finding where the "injection" was actually a controlled lookup by primary key. A senior engineer knows to check the schema and the function's purpose first. This distinction matters more than the tool you pick. There's also the problem of transitive dependencies in your own code. In monorepos where internal packages depend on each other, many tools only analyze the top-level code and skip the internal dependency chain. You end up with gaps where a vulnerability in an internal package never gets traced to its consumption point. I worked around this by configuring our scanner to treat internal packages as first-class dependencies with their own lockfiles, which added about four minutes to each scan but closed a real coverage hole.
Practical Workflow That Actually Sticks
Run the scanner on every pull request. Block merges on critical and high findings until they're reviewed. Don't block on info or low — those can go into a weekly triage batch. This keeps the backlog from becoming unmanageable while ensuring the real problems don't ship. Assign findings to the people who own the relevant code. A security team member flagging a finding means nothing if the engineer who wrote that module never sees it. Integrate the results directly into your PR comments or your issue tracker so the context travels with the work. Review findings in batches. Individual triage is slow. Block out thirty minutes twice a week and work through all open findings at once. You'll pattern-match faster when you've seen ten similar issues in a row than when you're evaluating them one in isolation spread across two weeks.
Track your metrics. I found that measuring the time from finding creation to remediation was more useful than counting total findings. Our average went from about eleven days down to four days over six months as we got better at triage and built custom rules for our most common issues. The raw number of findings didn't change much, but the throughput did.

The Bottom Line
Source code analysis adds real value to SCA when you invest in making it accurate for your codebase. Generic scans give you a starting point. Custom rules, proper configuration, and a workflow that forces review and remediation is what turns it into something actionable. Tools will always overreport. Your job is to build the filtering and follow-up process that surfaces the actual risk instead of drowning in noise. If your codebase uses dynamic language features heavily or you're working with compiled binaries where source isn't available, the analysis will have gaps. Accept that limitation and supplement with runtime monitoring, fuzzing, or manual review where it matters most. No single tool covers everything, and pretending otherwise just leads to complacency around the things you aren't checking.