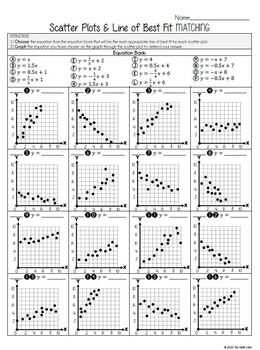
How Scatter Plots Actually Work For Making Predictions
Most people learn scatter plots in a statistics class and move on without really understanding what they're good for or where they fall apart. I've graded more student work and reviewed more business presentations than I care to count, and the gap between what people think scatter plots can do and what they actually can do is huge. The Scatter Plots And Predictions Answer Key most instructors hand out tends to focus on drawing a line of best fit and calling it a day. That approach works for homework but falls apart fast in real applications. Let me walk through how this actually functions when you're using it for real prediction work rather than filling in a worksheet.
Scatter Plots And Predictions Answer Key: What It Actually Covers
When I put together an answer key for scatter plot prediction work, I'm not just listing correct coordinate pairs or ideal regression equations. The core concepts that matter are correlation strength, directionality, outlier influence, and the difference between interpolation and extrapolation. Those four things separate people who use scatter plots correctly from people who make confidently wrong predictions. Here is the method I use when teaching this. Start with raw data. Plot it. Then assess whether a linear model even makes sense before you calculate anything. Most beginners skip straight to calculating slope and intercept without looking at the shape of the cloud. I force them to sit with the plot for at least two minutes before touching any formula. You'd be surprised how many people put a straight line through clearly exponential data and then wonder why their predictions are nonsense. Correlation coefficient, r, is useful but it lies to you if you let it. A high absolute value of r does not guarantee that prediction will be accurate. It only tells you about linear association in your sample. The actual predictive power depends on the standard error of the estimate, which is almost never included in basic answer keys but is the thing you should actually care about.
The Prediction Workflow That Actually Works
Take your bivariate dataset. Assign your independent variable to the x-axis and your dependent variable to the y-axis. The predictor goes on the horizontal axis by convention, though you should think carefully about which variable you believe actually drives the other. This distinction matters more than people admit when building a prediction model. Calculate the line of best fit using least squares regression if the relationship appears linear. The equation takes the form y = mx + b, where m is the slope and b is the y-intercept. Plug in values of x that fall within your observed range to generate predictions. This is interpolation. Interpolation is reasonably reliable when your data is dense and the relationship is stable. Extrapolation outside your data range is where predictions go to die, and I cannot stress this enough. Every answer key I have ever written includes a warning about extrapolation, and every student or professional I have worked with seems to ignore that warning until they get burned. Residual analysis is the step nobody does but everyone should. After fitting your line, calculate the difference between each actual y value and your predicted y value. Plot those residuals against your x values. If the residual plot shows a clear pattern, your linear model is wrong. If the residuals look randomly scattered around zero with roughly constant spread, you have a decent model. This single diagnostic check catches far more bad models than looking at r-squared ever would.
Get the Full Details

I ran into a specific problem last year with a client dataset where the scatter plot looked perfectly reasonable at first glance. The correlation was strong, the r-squared value was 0.87, and the prediction intervals seemed tight. I plotted the residuals anyway because that is just habit at this point, and there it was: a clear curved pattern. The relationship was actually quadratic, not linear. The high correlation was misleading because the data happened to fall along a gentle curve that a straight line approximated decently over the observed range. We refitted with a polynomial term and the prediction error dropped by about forty percent. That single residual plot saved us from making some very expensive forecast calls.
Common Pitfalls That Ruin Predictions
Simpson's paradox is the most insidious one. When you combine groups that have different underlying relationships, the overall scatter plot can show a correlation in the opposite direction of what each subgroup actually exhibits. I saw this once with hospital readmission data where the aggregate plot suggested a certain treatment reduced readmissions, but breaking it down by patient severity revealed the opposite was true for every subgroup. The answer key approach of just computing one correlation and moving on completely misses this. Another pitfall is assuming that correlation implies any predictive reliability. You can have a statistically significant correlation with a sample size large enough that even trivial associations become significant. With enough data points, nearly everything appears correlated. The practical significance, measured by how much variance your model actually explains and how narrow your prediction intervals are, is what determines whether your scatter plot prediction is useful. Outliers deserve special attention. A single extreme point can pull your regression line significantly, especially in small datasets. I usually recommend calculating the regression with and without the outlier to see how much influence it has. Cook's distance is the proper metric for this, though most introductory materials skip it entirely. If a point has a Cook's distance greater than 1, it has substantial influence on your model and your predictions. Decide intentionally whether to keep it or remove it. Do not just delete outliers because they make your model less clean. That is data manipulation, not analysis.
When Scatter Plot Predictions Fail Completely
Non-linear relationships are the obvious failure mode. If your data follows a curve, exponential growth, or a sine wave, a linear regression line will produce systematically biased predictions. The fix is to try transformations: log, square root, or reciprocal transforms on one or both variables often linearize stubborn relationships. If transforming does not help, switch to a non-linear model or a non-parametric approach like loess smoothing. Heteroscedasticity is another failure condition that standard answer keys rarely mention. This is when the spread of your residuals changes across the range of x values. Predictions become unreliable in regions where the variance is high because your confidence intervals are actually much wider than the model assumes. Weighted least squares regression can address this, but again, this is advanced territory that most educational materials skip. Catostrophic extrapolation happens when you predict far outside your data range and the model produces values that are technically consistent with the regression equation but completely unrealistic. I had a sales forecast where the model predicted negative revenue three years out because the decline trend was linear. Negative revenue is impossible. The model was mathematically correct and practically absurd. Always sanity-check your predictions against domain knowledge.
Practical Resources and Answer Key Construction
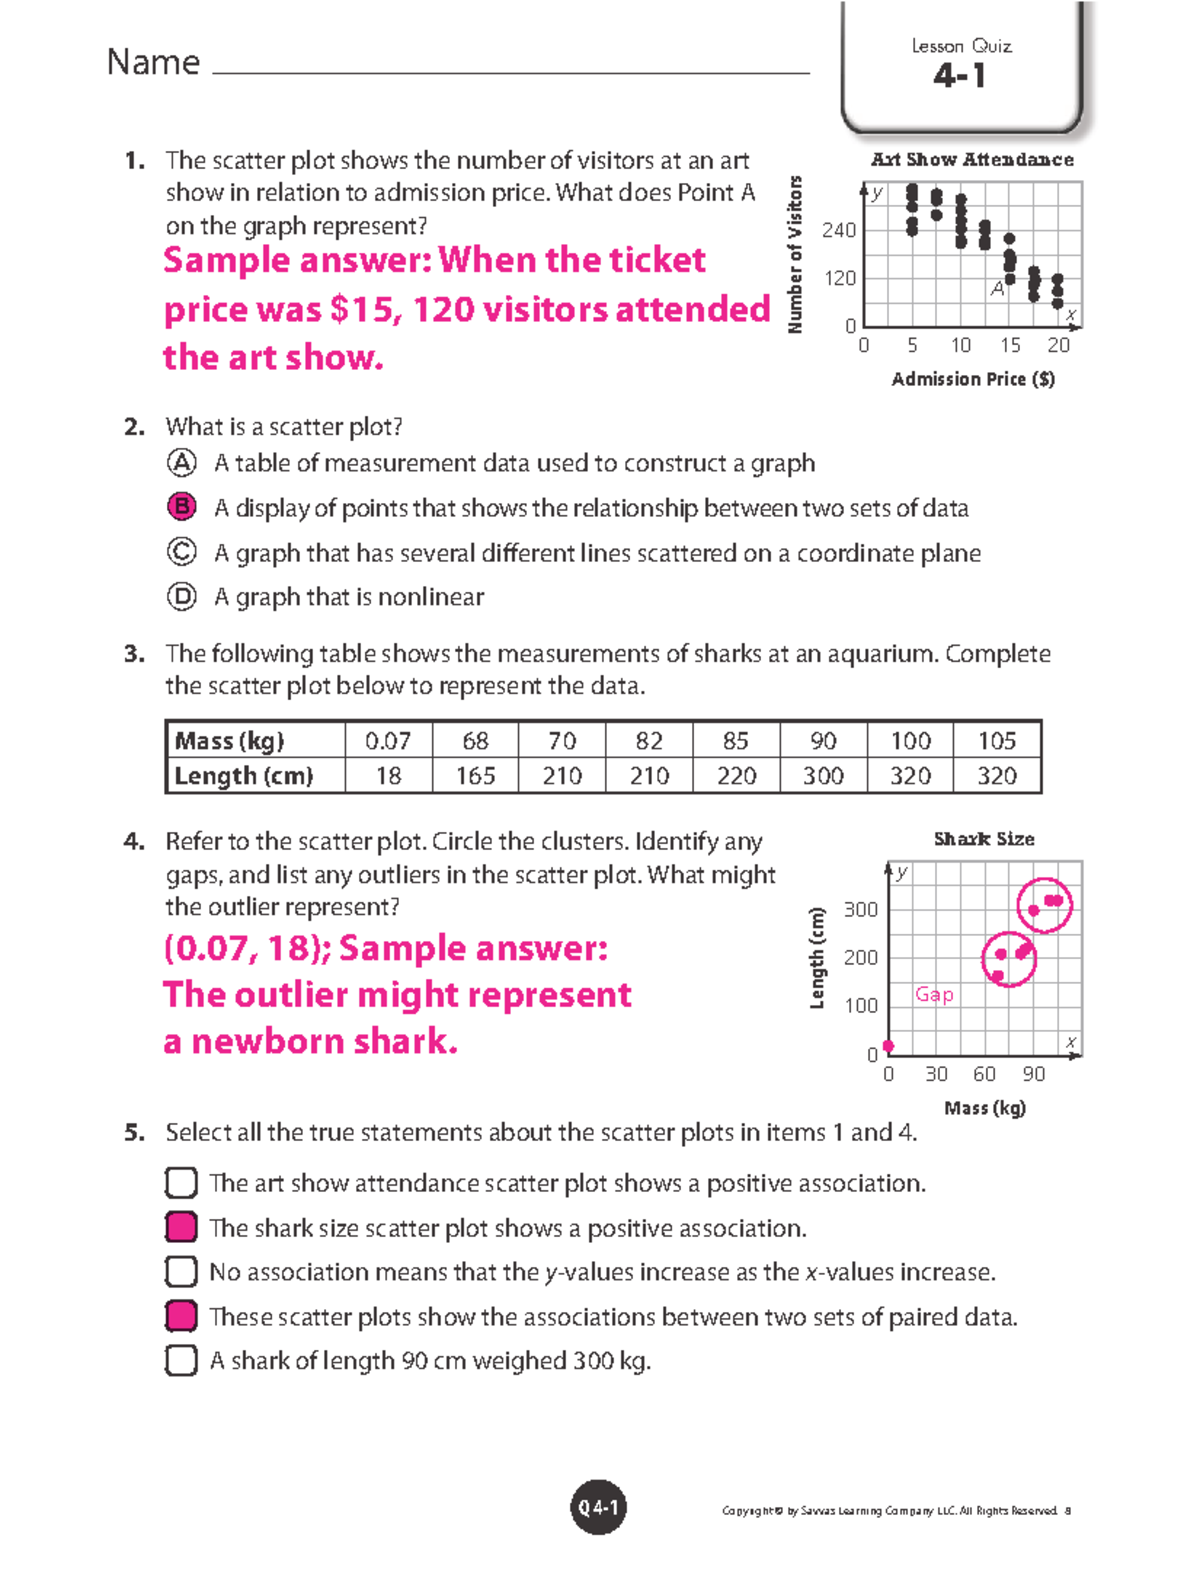
If you are building or using a Scatter Plots And Predictions Answer Key for teaching or self-study, include questions that test residual analysis, not just calculation. Have students interpret what a residual plot reveals. Ask them to identify whether interpolation or extrapolation is being used. Require them to discuss the impact of outliers on their predictions. These are the skills that actually transfer to real work. For people who need ready-made materials, several open educational repositories host scatter plot worksheets with answer keys. The OpenStax statistics collection has a solid section on bivariate data and linear regression with problems and solutions. Khan Academy also provides practice sets with built-in answer verification. I tend to modify any generic answer key I find because the standard problems rarely include edge cases like outliers or non-linear patterns that show up in actual data. My own answer keys always contain at least one deliberately problematic dataset where the correlation looks good but the residual plot tells a different story. Students who catch that discrepancy learn more than anyone who just computes a line and moves on. The discomfort of discovering your model is wrong is the exact feeling you want to build early, before you are relying on these predictions for decisions that matter.
Tools Beyond Manual Calculation
You do not need to compute regression by hand anymore. Python's scipy.stats.linregress function, R's lm() function, and even Excel's TREND and FORECAST functions all handle the arithmetic instantly. The value you provide is in interpreting the output, not in performing the calculations. Spend your mental energy on the residual plots, the outlier diagnostics, and the domain-level sanity checks. Those are the things that separate a competent analyst from someone who just knows how to press a button. Prediction intervals are another thing beginners consistently overlook. A point estimate from your regression line tells you the predicted value for a specific x, but it does not tell you how uncertain that prediction is. The prediction interval widens as you move away from the mean of your x values, which is another mathematical reason why extrapolation is dangerous. Your answer key or workflow should always report intervals, not just points. I do not use scatter plot predictions lightly anymore. I have seen too many projects fail because someone trusted a line drawn through a messy cloud of points without checking the assumptions. The method itself is sound when applied correctly, but the margin for unnoticed mistakes is surprisingly wide. Take the time to check the residuals, question the outliers, and respect the boundaries of your data. Everything else is just arithmetic.


