So you want to work as a Science Data Analyst
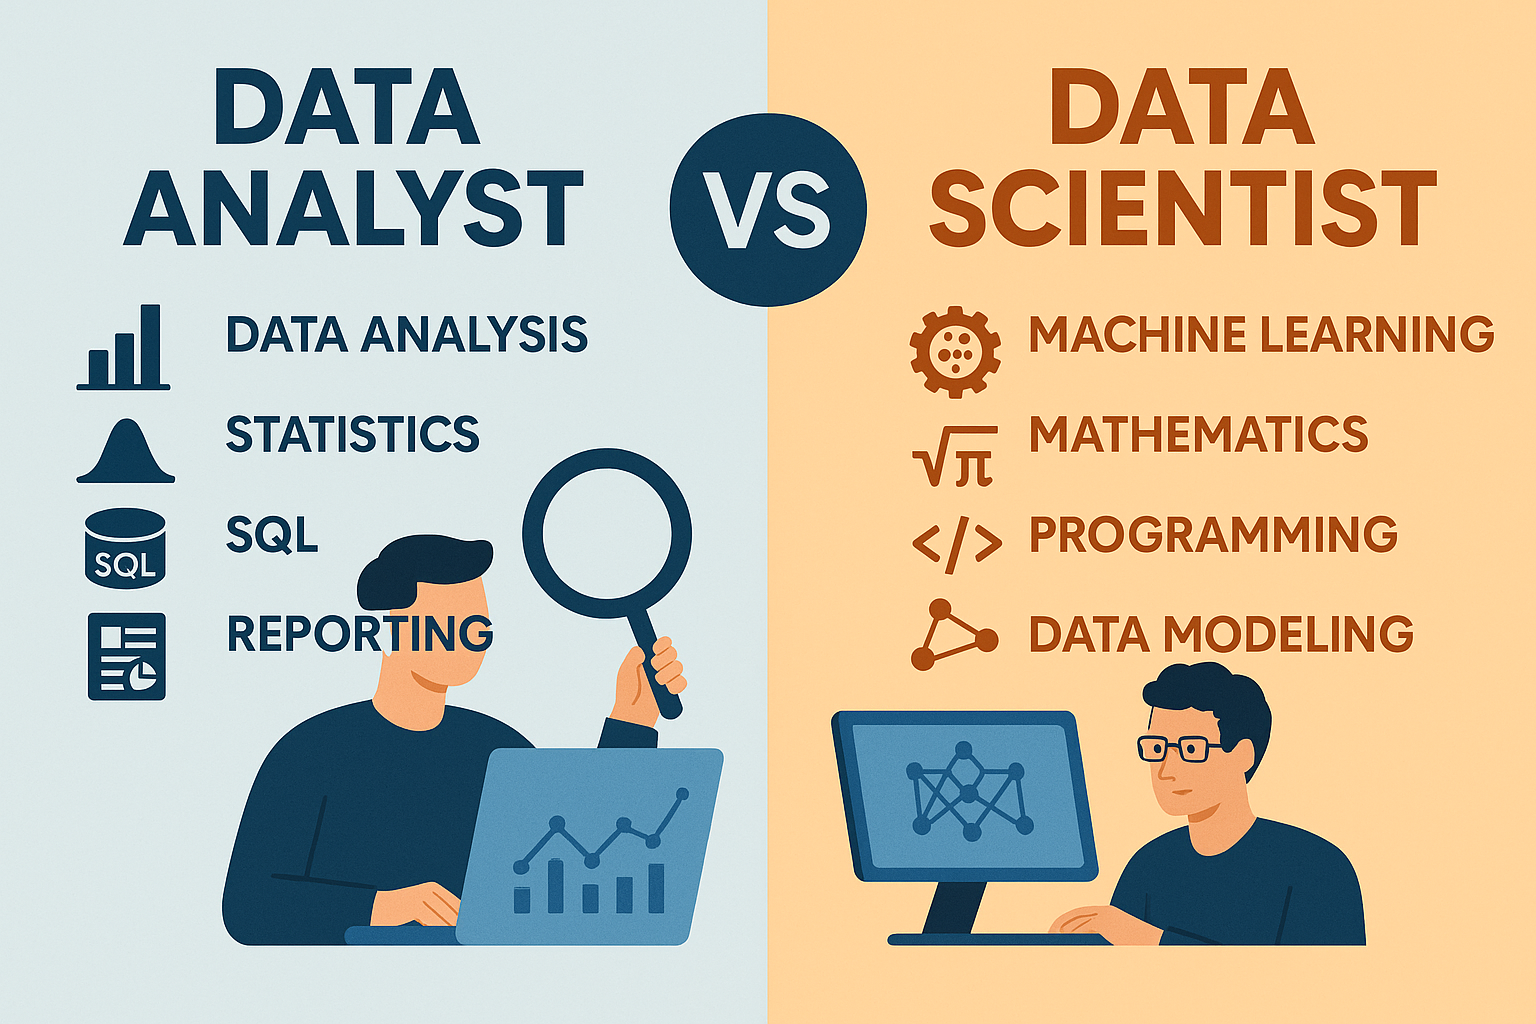
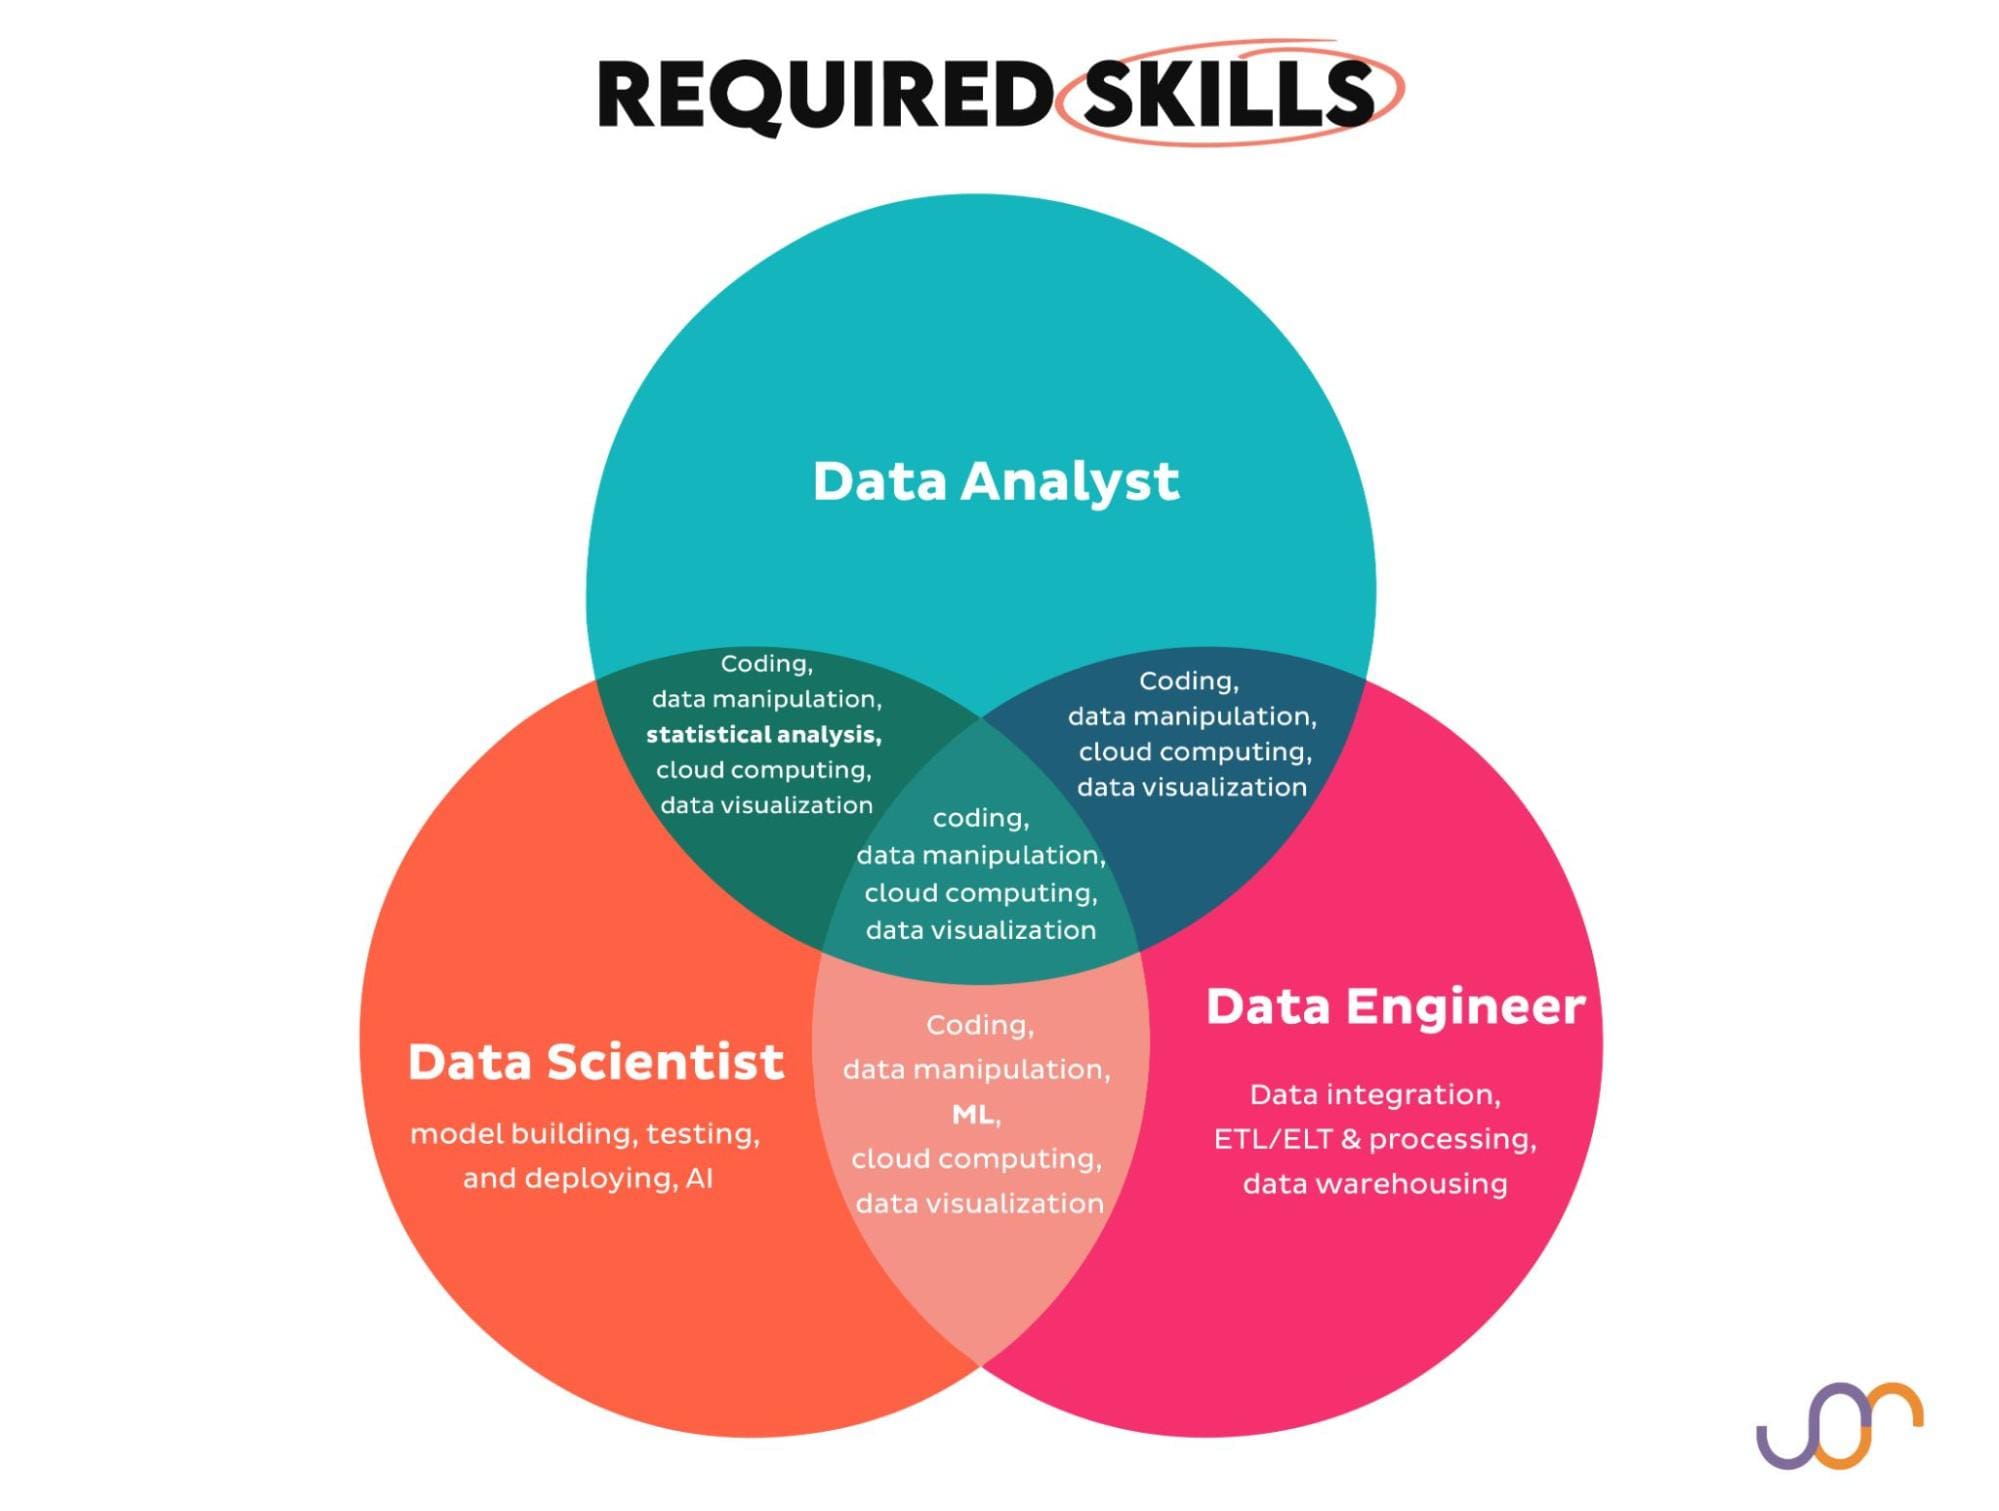
It is a role that sits somewhere between a domain scientist and a software engineer, and most people land there by accident. You start doing someone else's data cleaning because they are busy. Then you build a pipeline because doing it by hand is slow. Then someone notices you can make graphs that actually mean something and starts calling you a scientist. That is roughly how it happens in my experience. The job title varies by department. In academia you might be called a research data analyst. In government or defense contracting the title stays closer to Science Data Analyst. In pharma or materials science it is often just data scientist, which is annoying because nobody can tell you what the difference is. The work is fairly consistent across all of them. You take raw data from instruments or experiments, clean it, validate it, analyze it, and produce outputs that other people use to make decisions. Those other people might be postdocs writing papers, process engineers adjusting manufacturing parameters, or compliance officers checking regulatory boxes. You answer to all of them, usually without much help with prioritization.
The tools depend heavily on the field. Bioinformatics people live in R and Python with pandas, numpy, and scikit-learn. Atmospheric scientists lean on Python too but also spend time with netCDF files and xarray. Chemistry and materials science folks often work in MATLAB alongside Python. Environmental data analysts might be handling large geospatial datasets with GDAL or rasterio. There is no universal stack.
The practical skill set that actually matters
Everyone says learn Python and statistics. That is correct but incomplete. The things that separate people who last in this role from people who burn out in six months are the unglamorous ones. Data cleaning and validation is roughly sixty to seventy percent of the work. You will spend hours dealing with malformed instrument exports, columns that shift position between runs, metadata stored in PDFs instead of databases, and measurements where the unit changed mid-experiment without anyone updating the documentation. Learning to write robust import functions and validation checks is more valuable than any machine learning model you will ever fit. Statistical thinking is non-negotiable. You need to understand confidence intervals, hypothesis testing, multiple comparison corrections, and when a p-value is actually meaningless. More importantly you need to understand experimental design. Most people who hand you data did not design a proper randomized experiment. You need to be able to look at a dataset and say out loud what biases are likely present, even if you cannot fix them.
Get the Full Details

Domain literacy is the third pillar. You do not need a PhD in the subject, but you do need to speak the language enough to ask useful questions. If you are working with climate data and do not know the difference between weather and climate, you will make mistakes that take weeks to catch. If you are working with genomic data and cannot parse a FASTA file, you are going to waste a lot of time. Software engineering basics round it out. Version control, writing functions instead of copy-pasting code blocks, using virtual environments, and writing tests for your data processing pipelines. This is where most science data analysts are weakest and where the job becomes infinitely more painful than it needs to be.
How to actually get into this role
If you already have a science degree, the transition is easier than if you are coming from pure computer science. Take a graduate-level statistics course if you can. Learn Python thoroughly enough to be dangerous. Build one real project that involves messy real-world data, not the Titanic dataset everyone uses as an example. Publish it or present it somewhere. Even a poorly formatted blog post is better than nothing. If you are coming from a technical background without domain experience, pick a field and commit to it for six months. Read review papers in that field. Learn the standard file formats. Do not try to be generalist from day one. The people who survive long-term in this work tend to specialize early and then broaden out. There are certification programs like the Google Data Analytics Certificate or IBM Data Science Professional Certificate. They teach you enough to be competent at the entry level but they will not make you employable on their own. Treat them as structure for learning, not as credentials that open doors.
A tool I actually use regularly
I should mention that many people in this space end up building their own lightweight analysis frameworks rather than adopting commercial products. A common pattern is a Python project structured around a config file, a data loader module, a processing pipeline, and an output formatter. Tools like Python with packages like pandas, numpy, xarray, and scikit-learn form the backbone of most workflows I have seen. For the actual analysis and visualization, I rely heavily on Python's scientific stack. There is also R for statistical work, particularly in biological and environmental fields. Many organizations also use MATLAB in engineering contexts. None of these are downloadable as a single product called "Science Data Analyst" because that is a job function, not a piece of software. But the ecosystem around it is well documented and freely available.
A specific problem I ran into and how I solved it
About two years ago I was working with time-series sensor data from an environmental monitoring station. The instruments logged data in CSV format, but every quarter the manufacturer released a firmware update that changed the column naming convention slightly. The new columns had different names for the same measurements, and some were renamed while others stayed the same. This happened during a project where we needed continuous data going back five years for trend analysis. The initial approach was to write separate import scripts for each firmware version and stitch the results together. That worked for a while but became unmaintainable as new versions rolled out. The real solution was building a normalization layer that mapped every observed column name variant to a canonical schema. I used a lookup table stored as a JSON file, with version detection logic that read the file header and applied the appropriate mapping before any processing happened. This reduced future firmware-change work from about three days of debugging to about twenty minutes of updating the mapping file. The counter-intuitive part is that the firmware change was a blessing in disguise. It forced us to confront the fact that nobody had been validating column names against the documented schema, and we discovered two instruments had been silently reporting data in millivolts instead of volts for six months. Fixing that was important.
Things beginners consistently get wrong
The first mistake is treating data cleaning as a preliminary step that you should rush through to get to the "real" analysis. Cleaning is the analysis. The conclusions you draw are only as good as the data you feed them, and bad data produces confident but wrong answers faster than anything else. The second mistake is falling in love with sophisticated models before understanding the distribution of the data. I have seen people apply gradient boosting to small environmental datasets with twelve variables and two hundred observations and then report the feature importance scores as if they were findings. They are not. They are artifacts of overfitting. Start with linear models and baseline statistics. Understand what your data can actually support before reaching for anything complex. The third mistake is not documenting your pipeline. If someone else cannot reproduce your analysis from raw data to final output without asking you questions, your work is not complete. Use environment files, document every transformation, and store intermediate results so that debugging is possible.
Where this role falls short
Science Data Analyst positions in smaller organizations often suffer from ambiguous scope. You are expected to be the expert in everything data related, from database administration to statistical consulting to dashboard development. This leads to context switching that destroys productivity. The average person in this role loses roughly forty-five minutes every time they switch from deep analytical work to answering a quick question about a spreadsheet formula. There is also a persistent funding problem in academic and government settings. Data infrastructure is expensive and underfunded. You will often be asked to manage terabytes of research data on a laptop or a shared network drive with no backup. This is a real risk to reproducibility and career longevity. Push back on infrastructure needs early, even if you lose the argument. Having it on record matters. Finally, the field is crowded with people who completed a four-week online course claiming to be data analysts. This devalues the actual skill set. The people who distinguish themselves are those who can explain why their analysis is trustworthy, not just what the numbers say.

Salary and career trajectory expectations
Entry-level positions in the United States typically range from fifty-five thousand to seventy-five thousand dollars depending on location and sector. Government roles pay less than private industry but offer better stability and benefits. Mid-career analysts with five to eight years of experience usually earn between eighty thousand and one hundred twenty thousand. Senior roles that include team leadership or deep domain specialization can go higher, but the ceiling is lower than pure software engineering tracks. The career path tends to branch into either deeper specialization in a scientific domain, movement into data engineering or MLOps, or transition into management. Each path has trade-offs. Specialization increases your value per project but narrows your options. Data engineering pays better but involves less statistics. Management pays the most but removes you from the actual analytical work, which is what most people enjoy about this job in the first place.
Resources worth using
The Python programming language with its scientific ecosystem remains the most versatile foundation. R is still dominant in certain biological and social science niches. Documentation for both is excellent. The book "R for Data Science" by Hadley Wickham and the "Python Data Science Handbook" by Jake VanderPlas are both freely available online and cover the core material well. Beyond those, the specific tools you need will depend entirely on your domain, so investing time in learning the standard libraries used in your field directly is more productive than generic tutorials.