What Actually Goes Into a Science Experiment Data Table
A Science Experiment Data Table is a structured grid for recording observations, measurements, and sometimes derived values during an experiment. It sounds simple. The reason people struggle with it is that a poorly designed table can ruin your analysis phase, even if the raw data collection was perfect. I built too many of my own to pretend otherwise. The first thing you need to decide before opening any spreadsheet software is what your independent variable is and how many levels it has. Put that across the top row. Then figure out your dependent variable and put that in the first column. Everything else slots into the grid between them. Let's say you are measuring plant growth under different light intensities. Light intensity goes across the top as your independent variable with values like 100 lux, 300 lux, 500 lux, and so on. Plant height in centimeters is your dependent variable, listed down the rows. Each cell holds the measurement at that combination. Add columns for standard deviation if you ran replicates. Add a notes column for things that do not fit neatly into numbers, like a leaf yellowing event or a watering mistake.
I learned the hard way that the notes column exists for a reason. During a chemistry lab where I was tracking reaction rates across temperatures, one trial at 40 degrees C showed an anomalously fast rate. Because I had a notes column, I recorded that the reagent bottle had been sitting open too long. Without that note, I would have included the outlier in my final calculation and produced a misleading result. Here is a practical structure that works across most undergraduate and high school experiments: Independent variable header row with labeled units. Dependent variable column with labeled units. Replicate columns if you ran multiple trials. A calculated column for averages or rates. A notes column for anomalies. Do not skip the units. Missing units is the single most common error I see in student submissions and it makes the table nearly useless to anyone reading it later.
Common Mistakes People Make With Data Tables
Most people build their table after collecting data instead of before. This leads to mismatched column widths, inconsistent decimal places, and missing headers that force you to guess what a number means weeks later. Build the table first. Fill it in as you measure. If you are using a spreadsheet, set the column widths and number formatting before you type a single value. Another mistake is overcomplicating the structure. Some people try to force everything into one wide table when two separate tables would be cleaner. If your experiment has two distinct dependent variables, like mass change and pH shift measured at the same time points, put them in separate tables. Mixing them creates confusion during analysis and makes copying data into graphing tools unnecessarily painful. I recently worked with a dataset where someone had combined five different experimental conditions into one massive table with merged cells. Extracting the data for regression analysis took me about forty minutes because every other row needed manual cleanup. A properly structured table from the start would have cut that to under three minutes.
Get the Full Details
From Table to Analysis Without Losing Your Mind
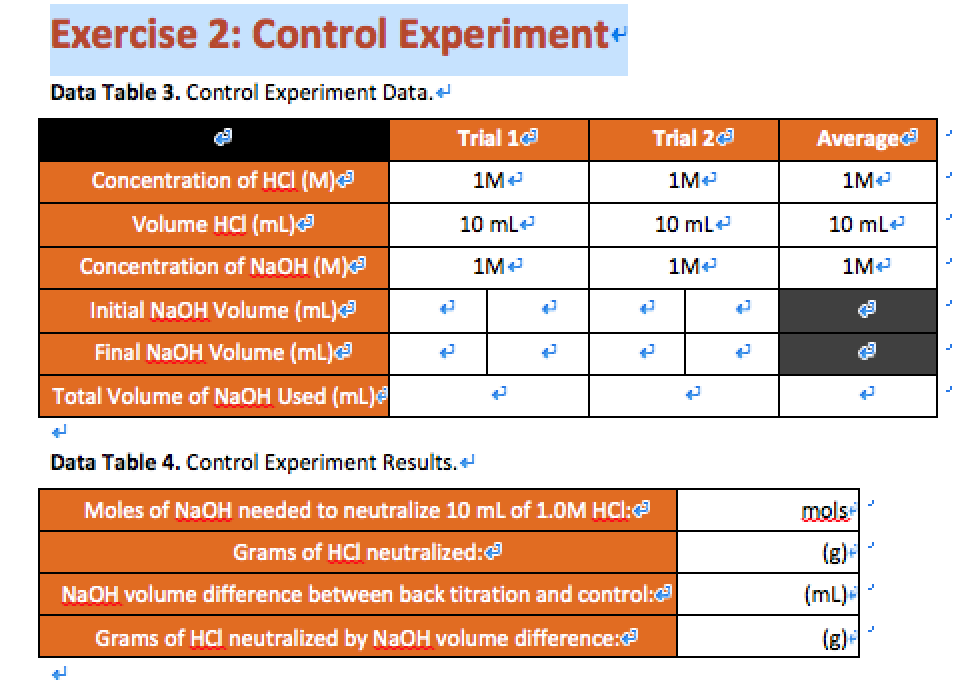
Once your table is built correctly, moving to analysis should be straightforward. In Google Sheets or Excel, you can set up quick formulas for mean, standard deviation, and standard error. Use the AVERAGE, STDEV.S, and CONFIDENCE.T functions rather than calculating by hand. This saves time and reduces arithmetic errors. If your experiment involves time-series data, add a column for elapsed time and use it as your x-axis when plotting. Do not rely on row numbers as your x-axis unless your sampling interval is perfectly regular and unchanging. One skipped measurement and your graph is misaligned. For experiments with more than three independent variables, a traditional flat table becomes unwieldy. At that point, consider a nested or transposed layout, or move to a tool that supports pivot tables. The Science Experiment Data Table concept still applies, but the format needs to adapt to the complexity.
Limitations You Should Know About
A data table is not a replacement for proper statistical analysis. It organizes your numbers. It does not tell you whether your results are significant. You still need to run the appropriate tests outside the table. Also, a table cannot capture qualitative observations well unless you dedicate space for them, which is why the notes column matters more than people give it credit for. Another limitation is that tables do not scale indefinitely. Once you cross roughly fifty rows and ten columns, readability drops and manual entry errors increase. For larger projects, a database or a structured metadata file alongside your spreadsheet is the better approach. If you want a starting template, search for "Science Experiment Data Table" in Google Sheets or Excel template libraries. Most offer a clean layout with headers and unit columns already in place. Download one, strip it down to what you actually need, and build from there.