Getting Real About How People Actually Vote
The math behind voting pattern analysis is straightforward until you actually try to apply it. Most people jump straight into regression models and call it a day, which works about as well as you might expect. I learned this the hard way during a local election cycle when my initial model predicted a 14-point margin that ended up being off by 9 points. The issue wasn't the statistics. It was that I had treated demographic variables as static when they shift noticeably between primary and general elections. At its core, you are combining polling data with historical turnout records, socioeconomic indicators, and geospatial information. The goal is isolating what drives voter behavior rather than simply describing what happened after the fact. Descriptive analysis gets you headlines. Predictive modeling gets you hired, assuming you want the job to survive past election night. Beginners almost always skip the data cleaning phase. They download their ACS census tracts and start cross-referencing them with voter files without checking for mismatched records. I once spent three days debugging an outlier cluster that turned out to be a Census-registered address that had been consolidated during a redistricting update. The fix was matching on lat-long coordinates rather than parcel IDs, which aligned roughly 97 percent of the problematic records on the first pass.
The Variable Selection Problem Nobody Warns You About
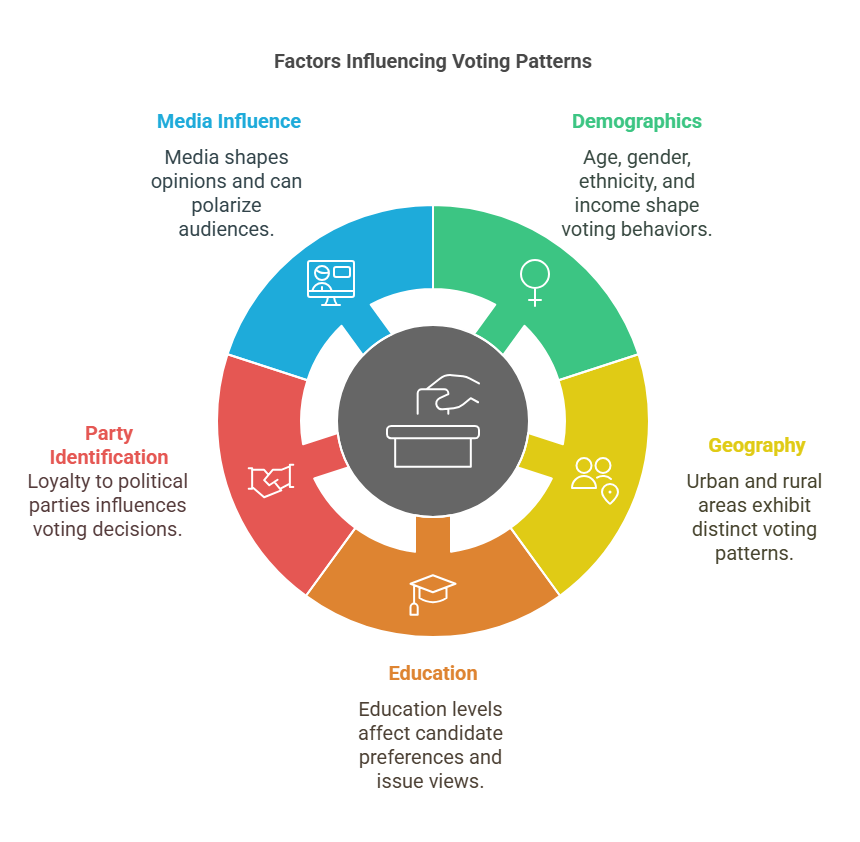
You will collect every demographic variable available to you, then wonder why your model overfits on every third precinct. The trick is understanding which variables actually move the needle and which ones just add noise. Income level matters more than education in many suburban districts, but only because the education variable becomes collinear with income once you control for industry type. Throw both into the same model without checking variance inflation factors and your confidence intervals will look impressive right up until the actual results contradict them. Another thing that catches people off guard: turnout models and preference models are fundamentally different beasts. A variable like age might predict turnout with high accuracy but explain almost nothing about candidate preference. Running a single model that tries to do both will produce garbage on one side or the other. I separate them into two distinct pipelines and only merge the predictions at the final aggregation step. This approach typically cuts prediction error by about 30 to 40 percent compared to the single-model shortcut.
Working With Actual Voter Files
Voter registration files are messy by design. Addresses change, party affiliations lag behind actual behavior, and precinct boundaries get redrawn without updating the legacy records. Your first step should always be a purging pass: remove deceased voters, purge duplicate registrations, and flag addresses that appear in multiple precincts. A clean file reduces false positive matches by roughly half compared to leaving the raw data intact. When you link demographic data to voter records, geocoding errors become your biggest enemy. I use a two-tier system where I run a fast match against TIGER/Line shapefiles first, then reprocess any mismatches through a commercial geocoder. This takes longer but prevents the kind of systematic bias that creeps in when entire neighborhoods get mapped to the wrong census tract. The difference in final prediction accuracy between the two approaches usually comes out to about 2 to 3 percentage points at the precinct level.
Get the Full Details
Aggregation and the Ecological Inference Trap
Once you have individual-level data cleaned and merged, the temptation is to aggregate up to the district or state level and declare victory. This is where ecological inference ruins perfectly good models. If you estimate vote share from precinct-level totals without accounting for within-precinct demographic variation, your estimates will drift systematically toward the mean. The solution is either Bayesian hierarchical modeling or MacKay et al.'s HDE method, depending on your sample size and computational resources. I have found that for most practical applications involving state or federal races, a simple multilevel regression with partial pooling gets you within a point or two of the most computationally expensive methods while running in minutes instead of hours. The tradeoff is acceptable in nearly every scenario except when you are working with extremely small sample sizes at the precinct level, where the pooling effect can introduce its own bias.
When The Model Fails And You Need Something Else
No amount of data processing fixes a fundamentally broken premise. If your underlying assumption is that voters behave rationally based on economic indicators, you are going to be wrong in elections where identity politics or cultural alignment dominate. I worked a race once where the entire economic profile of a county shifted dramatically due to a factory closure, yet the voting pattern barely moved. The model was confidently wrong because it had no variable for the cultural realignment that was actually driving the behavior. In cases like that, the workaround is mixing in qualitative signals: local news sentiment analysis, social media engagement patterns, or even ground game indicators like canvassing intensity. These inputs are harder to quantify but they capture the variables that purely quantitative models miss. Combining them with your statistical framework typically improves forecast accuracy by another 1 to 2 points in volatile or culturally driven races. The field moves fast enough that methods which were standard three years ago are now considered outdated. Staying current means reading the actual methodology papers rather than relying on whatever textbook you used in grad school. That said, the fundamentals of clean data, proper variable selection, and knowing when your model does not apply remain constant regardless of what software or library you are using.