What People Actually Mean When They Say "Variation" in Science
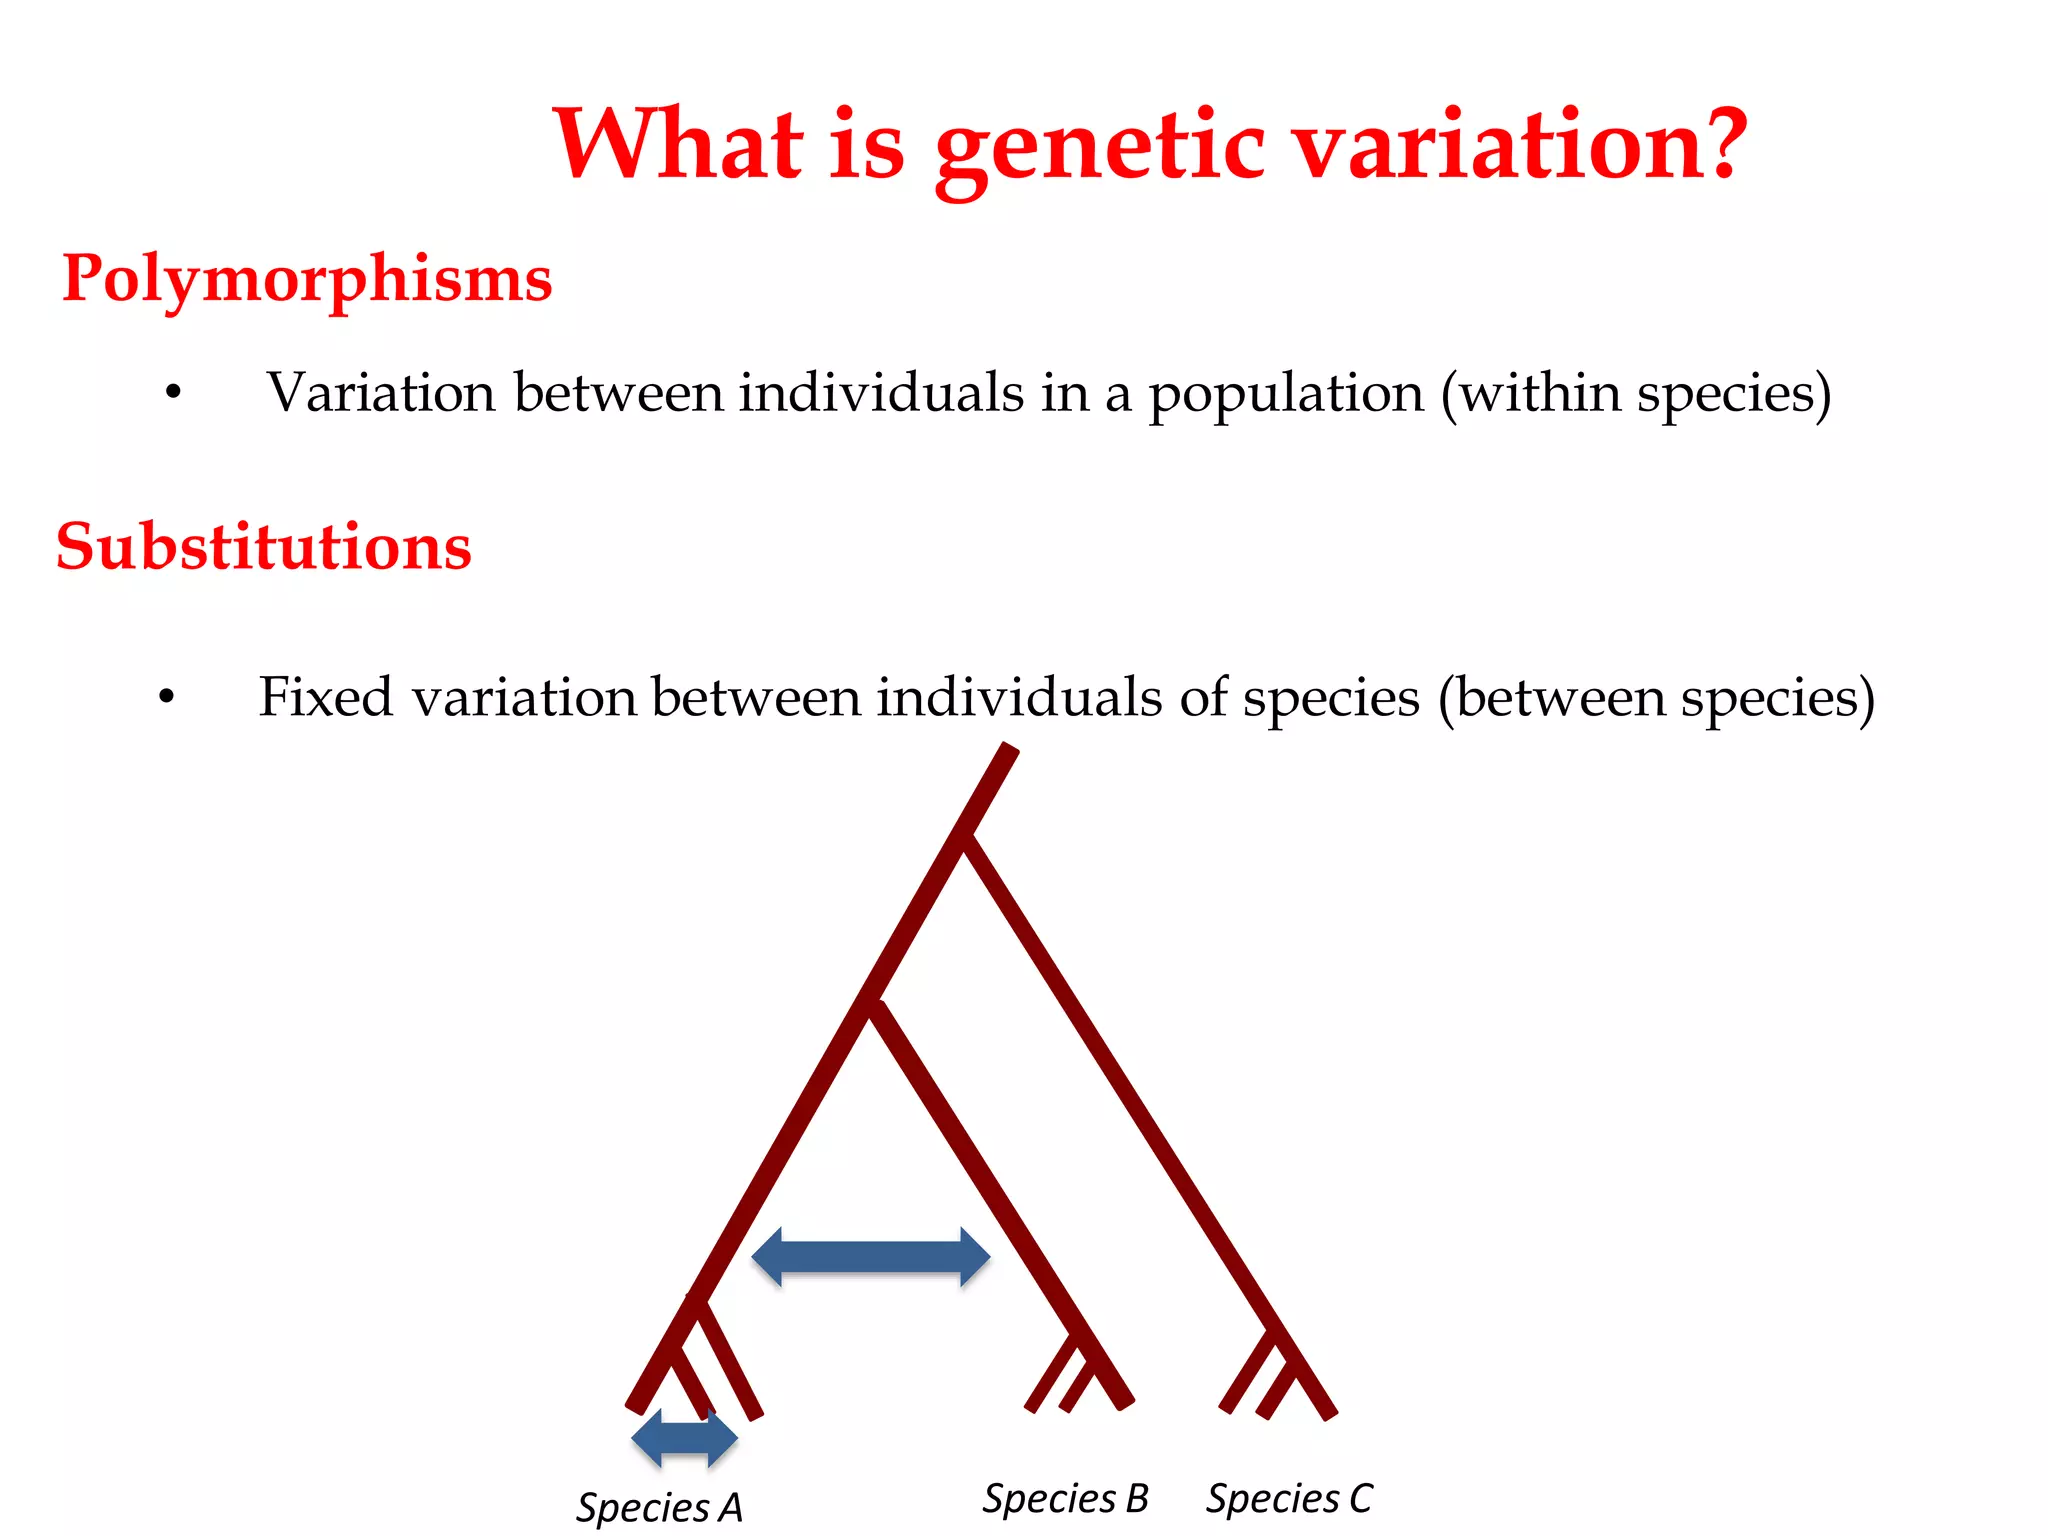
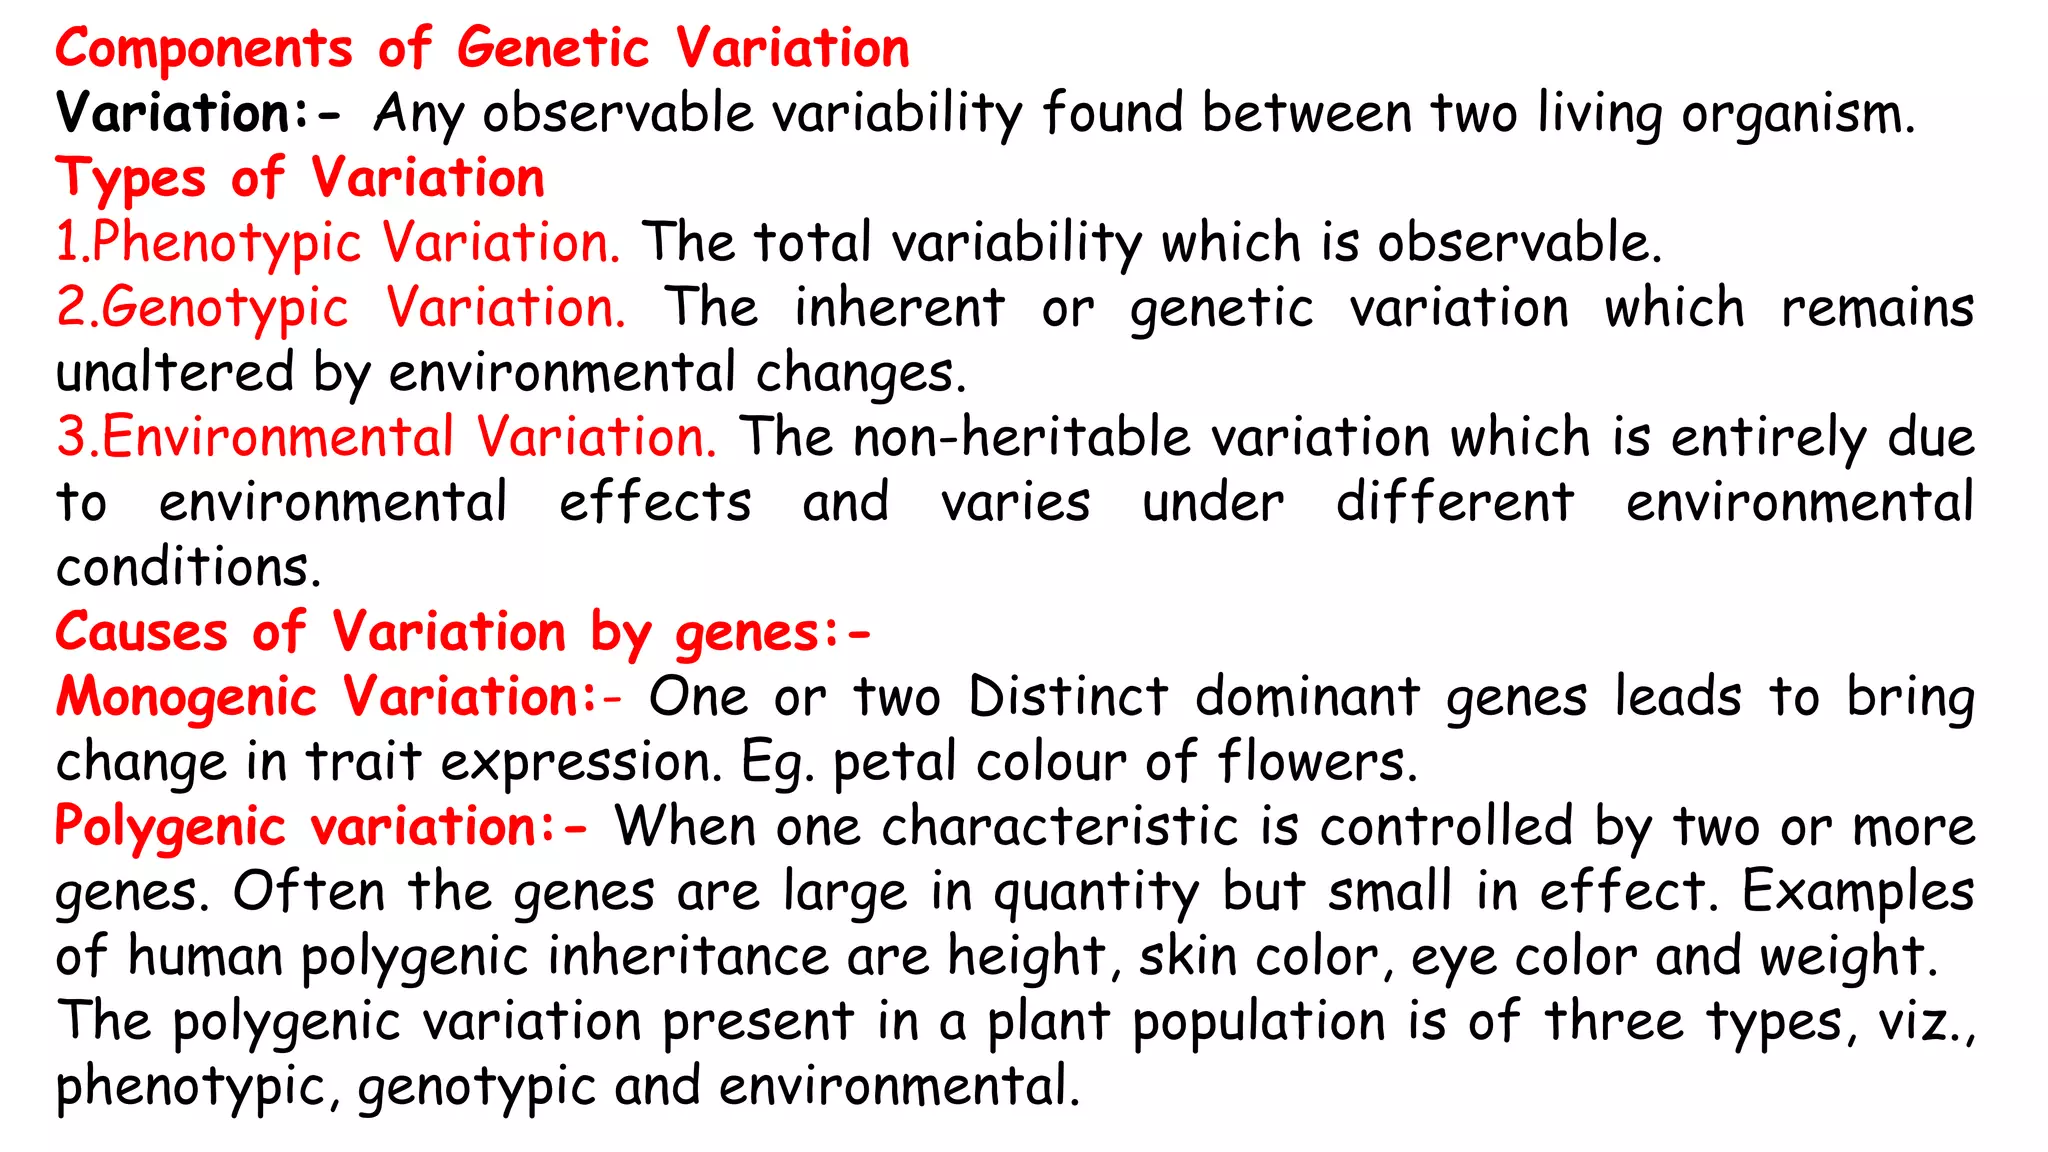
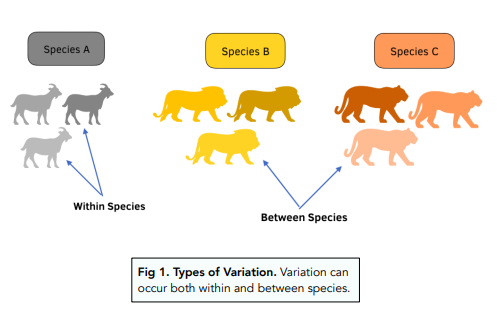
It depends on which department you're in. In biology, variation refers to differences in traits among individuals of a population. In statistics, it's about how spread out data points are from a central value. They overlap, but they're not the same thing, and mixing them up is an easy way to mess up an analysis. The formal definition is straightforward enough: variation is the degree of difference observable among individuals or data points within a defined system. But the messy part comes after you've written that down on paper. You need to figure out what kind of variation you're actually dealing with, because the methods for quantifying each type are completely different. Genetic variation involves differences in DNA sequences across individuals. It's measured in terms of allele frequencies, heterozygosity, and nucleotide diversity. Phenotypic variation is about observable traits, which can be continuous like height or discrete like blood type. Environmental variation is the portion of phenotypic difference caused by external factors rather than genetics. And then there's sampling variation, which is just the noise introduced when you measure a subset instead of a whole population.
I spent three months once trying to figure out why my variance estimates kept coming out wrong on a plant growth study. Turns out I had confounded genetic variation with environmental variation without realizing it. The greenhouse had a temperature gradient from one end to the other, and my experimental layout was aligned with that gradient. So what I thought was genetic diversity was partly just plants on the hot side growing differently from plants on the cool side. I had to redo the randomization and block the design by position. Cost me about two weeks of lab time, but it was the only way to untangle the signals. One thing nobody tells you when they first learn about variation is that the mean and the variance are often correlated in real data. If you're working with count data or proportions, higher means tend to come with higher variances. Standard statistical tests assume these are independent, and when that assumption breaks, your p-values are unreliable. The workaround is usually a variance-stabilizing transformation or switching to a generalized linear model with the appropriate distribution family. For counts, that means Poisson or negative binomial. For proportions, a beta-binomial model does a lot more good than a standard t-test ever will. Another nuance that gets glossed over is that variation isn't always a problem to be minimized. In evolutionary biology, variation is the raw material that natural selection acts on. Populations with low genetic variation are at higher risk of extinction because they can't adapt. In quality control, you want to reduce variation, but in breeding programs, you sometimes intentionally maintain or increase it. Context determines whether variation is your enemy or your asset.
If you're trying to measure variation in a dataset, start by visualizing it. A histogram or a box plot will show you things that summary statistics hide. Then calculate the standard deviation and the interquartile range. The standard deviation assumes a roughly normal distribution, which most real data isn't. The IQR is more robust to outliers. For a quick sense of spread relative to the mean, the coefficient of variation divides the standard deviation by the mean and multiplies by 100 to give a percentage. That's useful when you're comparing variability across measurements with different units or scales. The biggest pitfall I see is people treating variation as a single number and moving on. It's rarely uniform across your data. There might be more variation in one group than another, or variation that changes across a range of conditions. That's called heteroscedasticity, and ignoring it invalidates a lot of common statistical tests. Levene's test or the Brown-Forsythe test can check for it. If your data is heteroscedastic, you either transform it or use methods that don't require homogeneity of variance, like Welch's ANOVA instead of a standard one-way ANOVA. For anyone working with biological samples specifically, I'd also flag that measurement error itself contributes to observed variation. You can't separate it out without a replication design. If you measure the same sample multiple times, the variance among those repeated measurements is your measurement error. Anything above that is real biological variation. Skipping the replication step means you're attributing instrument noise to actual differences, and your conclusions will be weaker than they should be.
Get the Full Details
There's no single tool that handles all of this automatically. R is the standard, and packages like lme4 for mixed models and car for diagnostic tests cover most of what you need. Python has scipy and statsmodels, which get you most of the way there but can be clunkier for the more advanced variance decomposition. If you're doing a lot of this work, learning R is worth the initial time investment. The learning curve is steep but the payoff in flexibility is real. Some methods completely break down with very small sample sizes. If you have fewer than ten observations per group, your variance estimates are going to be unstable no matter what you do. Bayesian approaches with informative priors can help in those cases, but you're making assumptions that need to be justified. It's better to collect more data than to patch a bad design with fancy statistics. The definition itself keeps getting refined as new fields develop. In ecology, there's discussion about three components: taxonomic, phylogenetic, and functional variation. In quantitative genetics, the classic partition is additive, dominance, and epistatic variance. None of these contradict the basic definition, they just add structure to it. Understanding which framework applies to your question matters more than memorizing the textbook line.
If you run into a situation where standard variance decomposition isn't giving you clean results, it's usually because your data violates the assumptions underlying the method more than you realized. Go back to the visualization step, check for outliers, test for normality and homoscedasticity, and make sure your experimental design actually matches the statistical model you're fitting. Most problems trace back to one of those four things.