Understanding how adaptation actually works in practice
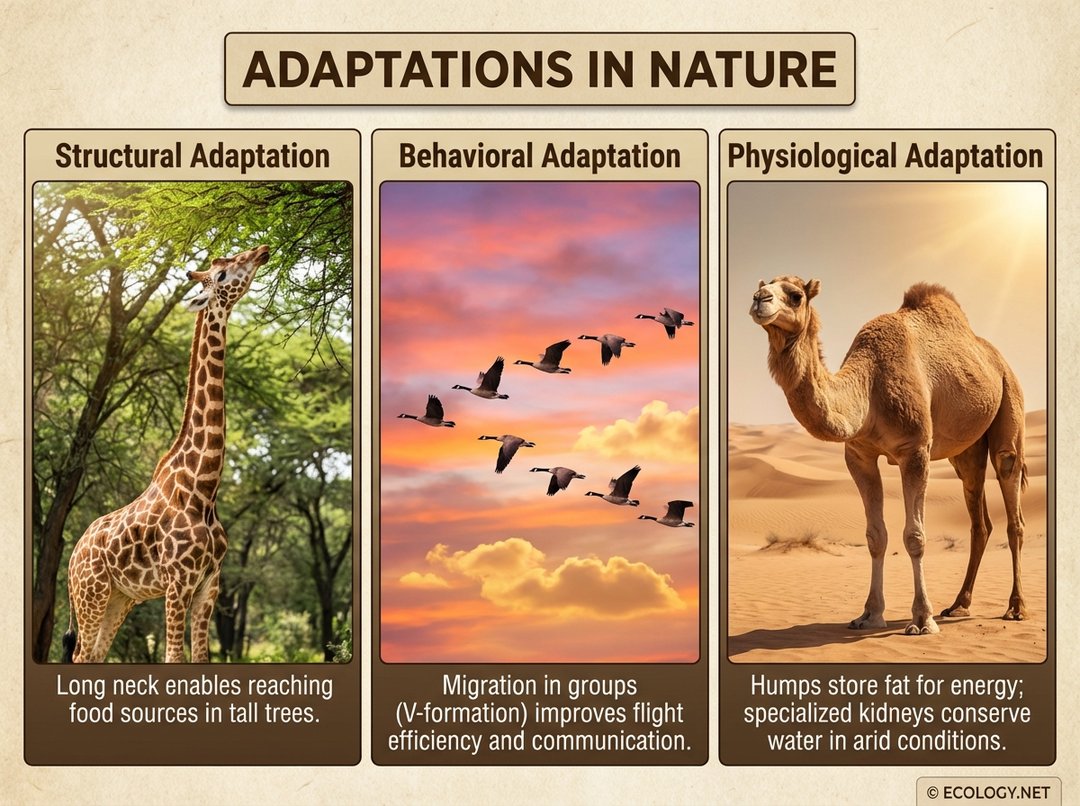
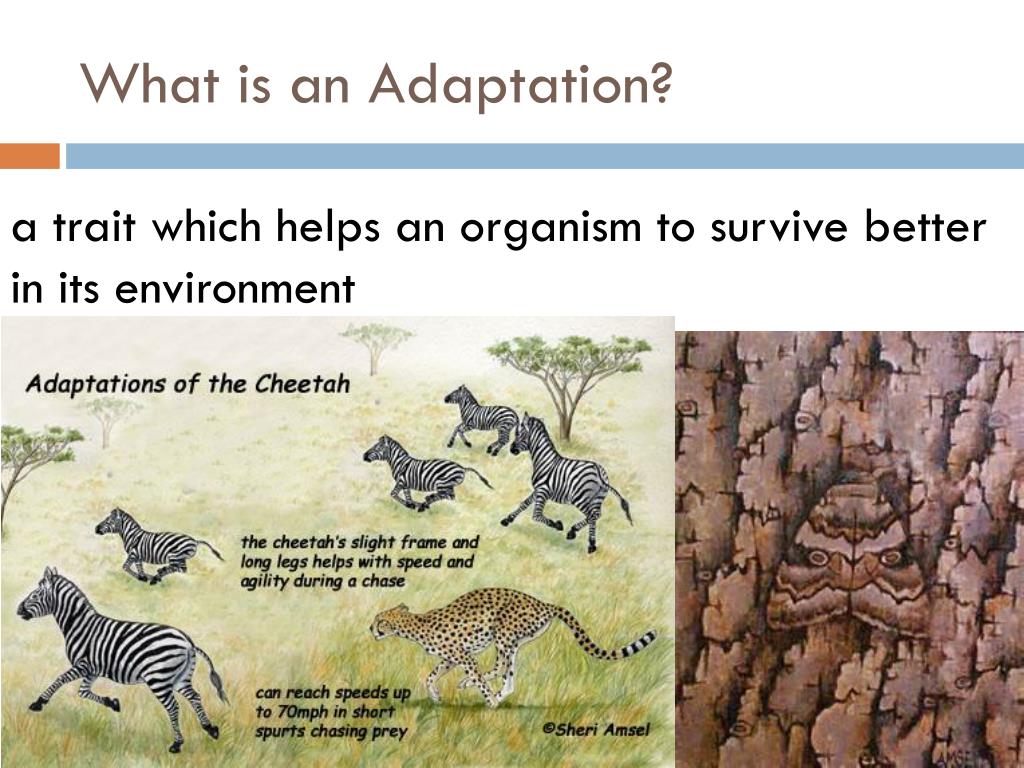
The scientific meaning of adaptation is straightforward on paper but gets messy the moment you try to apply it. At its core, adaptation describes a trait that has been shaped by natural selection because it improves an organism's reproductive success in a given environment. There are two ways the word shows up in the literature, and confusing them is the most common mistake I see people make. An adaptive trait is something currently under selection, while an exaptation is a feature that evolved for one purpose and got co-opted for something else later. Feathers are the classic example. They likely originated for insulation or display before birds used them for flight. Most intro textbooks gloss over this distinction, and it matters more than you'd think when you're reading research papers. I spent a few years working on microbial adaptation experiments, tracking how populations of E. coli responded to antibiotic pressure over hundreds of generations. The setup seemed simple enough. You plate bacteria on increasing concentrations of a drug and watch which mutations fix in the population. The problem is that adaptation doesn't always mean what you expect it to mean. In one project, I was studying resistance to ciprofloxacin and kept seeing the same resistant mutant dominate across multiple independent lines. When I checked the genome, the mutation was in a efflux pump regulator, not in the actual drug target. The bacteria weren't adapting by changing the target the drug binds to, they were adapting by pumping the drug out faster. This is a real-world example of a trade-off that most beginner guides skip over. Efflux pump upregulation confers broad resistance but carries a fitness cost in drug-free environments. If you're running adaptation experiments without measuring growth rates in parallel, you'll miss half the picture.
Scientific Meaning Of Adaptation Across Different Fields
Biology isn't the only discipline that uses this term, and each field means something slightly different. In physiology, acclimatization is often what people mean when they say adaptation, but these are not the same thing. Acclimatization is a reversible, non-genetic change within an organism's lifetime. Moving to high altitude triggers increased red blood cell production. That's physiological adjustment, not evolutionary adaptation. Evolutionary adaptation requires heritable genetic change across generations. The line between these two concepts gets blurry in the literature, and sloppy terminology causes real problems when you're trying to synthesize research across disciplines. In evolutionary psychology and behavioral ecology, the term gets even more contested. Every human behavior has been proposed as an adaptation at some point, and most of those proposals would not survive rigorous testing. The standard approach involves three things: demonstrating that a trait is not a random product of genetic drift, showing it solves a specific adaptive problem, and establishing that it has a genetic basis that selection can act on. I've seen entire graduate students lose a year on projects that collapsed because they couldn't rule out genetic drift as an alternative explanation. Statistical power matters a lot here, and most published studies on behavioral adaptations are underpowered relative to the claims they make. The mathematical side of adaptation tracking uses selection coefficients, usually denoted as s. If a mutation gives a 5% reproductive advantage, s equals 0.05. The fixation probability of a beneficial mutation in a population of size N depends heavily on whether 2Ns is much greater than 1. In small populations, even strongly beneficial mutations can be lost to drift. This is one of those counter-intuitive points that beginners consistently miss. Bigger isn't always better for adaptation speed. Very large populations generate more mutational supply, but they also have more standing genetic variation that can interfere through clonal interference, where multiple beneficial mutations compete with each other instead of combining. This actually slows the rate of adaptation in well-studied systems like RNA viruses.
If you're trying to measure adaptation in the lab, whole-genome sequencing paired with experimental evolution is the standard approach. You passivate cultures under controlled conditions, sequence populations at regular intervals, and track allele frequency changes. The workflow takes roughly 2 to 4 weeks depending on your organism's generation time. Be aware that sequencing depth matters significantly. At 50x coverage per timepoint, you'll detect alleles above 5% frequency. Below that threshold, stochastic sampling noise makes it hard to distinguish real selection from drift. I recommend aiming for at least 100x depth if you're working with populations under 10,000 individuals. The biggest limitation of current adaptation studies is that they mostly capture the easy part. Detecting a selective sweep tells you something happened, but it doesn't tell you why. Pleiotropy makes this worse. Most genes affect multiple traits, so a mutation that improves one function might simultaneously degrade another. The net effect on fitness depends on the environment, which means an adaptation in one context can be a liability in another. I encountered this directly when studying thermal adaptation in yeast. A strain that adapted well at 30 degrees Celsius lost nearly 40% of its fitness when shifted to 37 degrees, despite carrying what looked like clearly beneficial mutations based on growth curves at the original temperature. Environmental context is not a minor detail, it's the main variable that determines whether a trait is adaptive at all. Computational prediction of adaptive traits remains unreliable outside of very narrow cases. Machine learning models trained on protein sequences can identify conserved regions, but conservation does not automatically equal adaptation. Some regions are conserved because any change is deleterious, which is negative selection purging variation, not positive selection driving it. Tools like dN/dS ratios help distinguish these cases but require coding sequence data and reliable phylogenies, which you don't always have. For non-model organisms without good reference genomes, the whole approach breaks down fairly quickly.
Get the Full Details
A practical tip that nobody emphasizes enough: always include parallel lines in your experiments. Running a single evolutionary trajectory tells you almost nothing about reproducibility or the role of chance. Six to twelve independent replicates per condition is the minimum for meaningful statistical inference. Anything fewer and you cannot separate consistent adaptive responses from the random outcomes of drift and mutational opportunity. This adds cost and time but cuts through a huge amount of ambiguity that otherwise goes unnoticed until you're six months into analysis.