Running experiments on economies
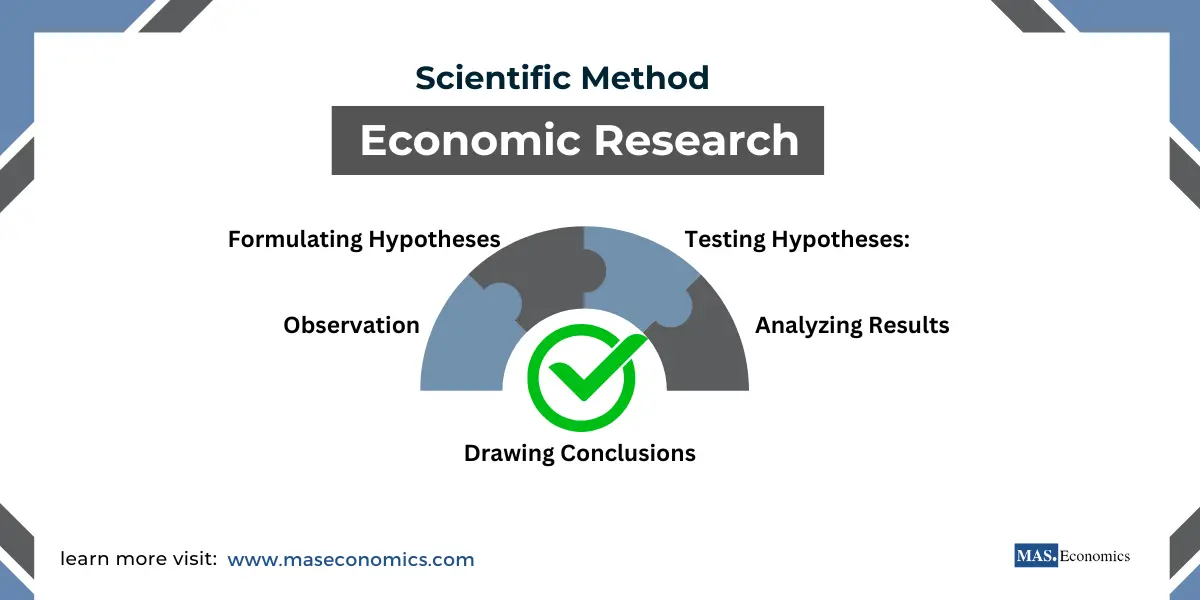
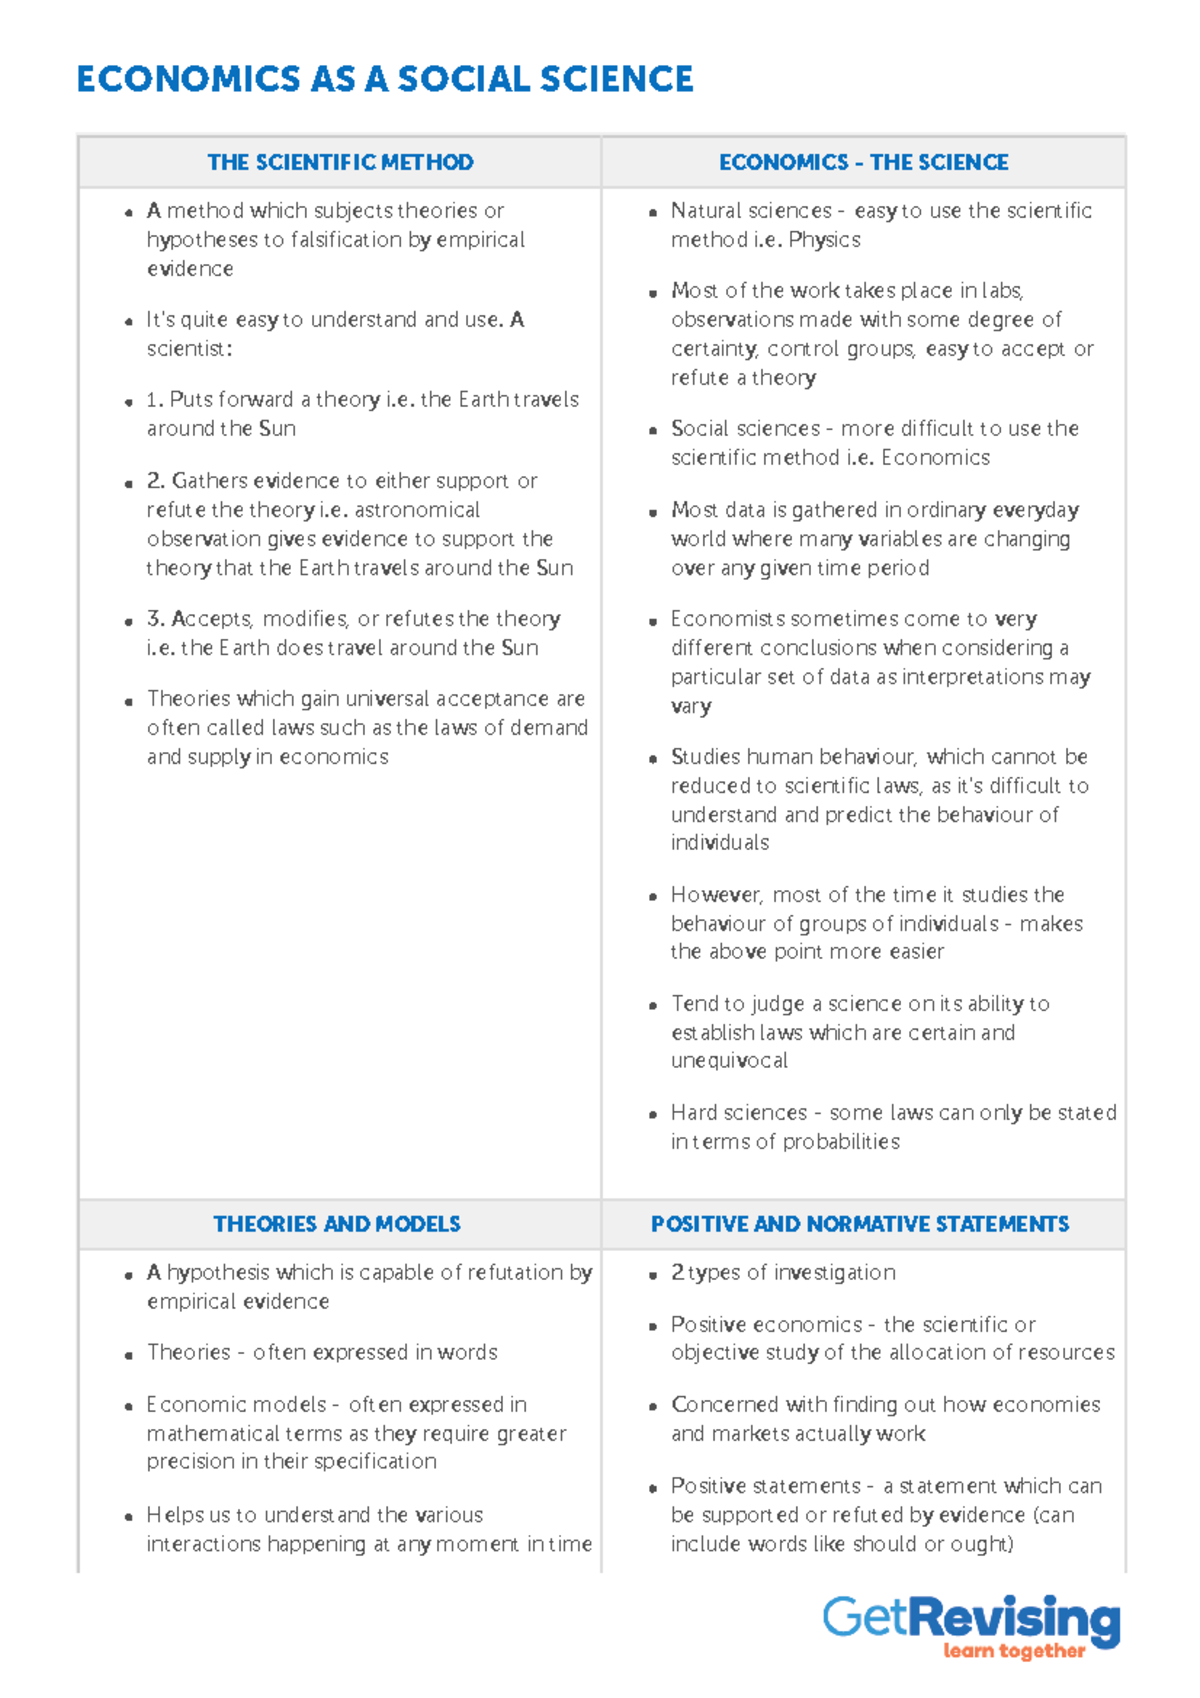
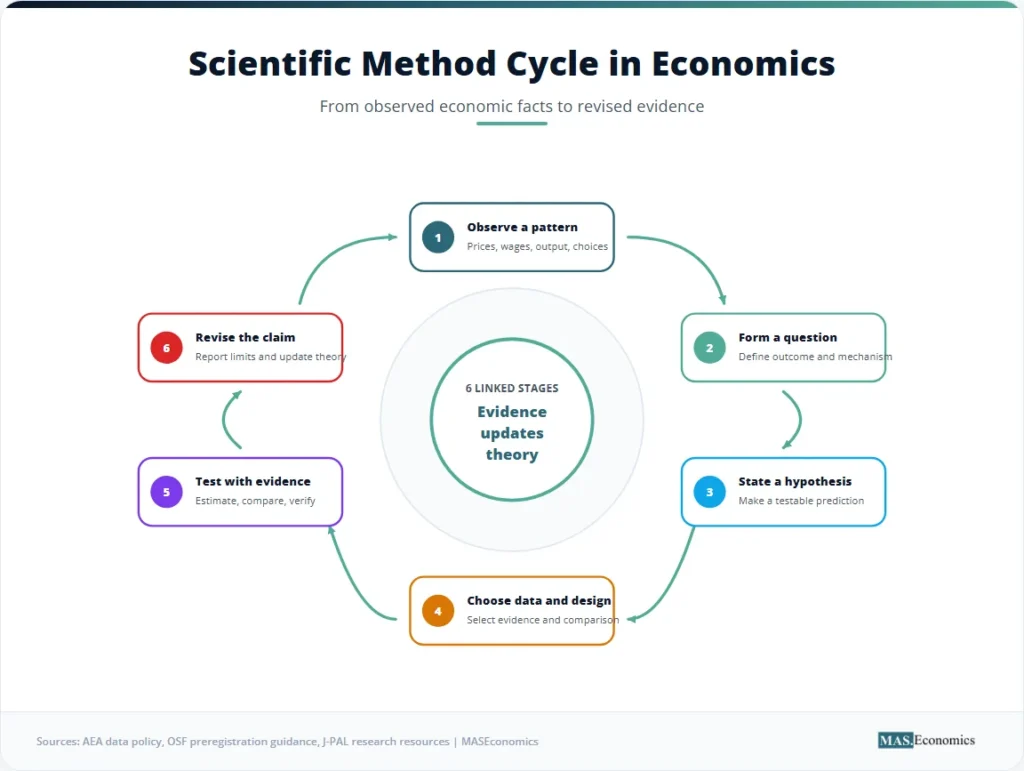
I spent three weeks debugging a regression that refused to converge on housing price elasticity, only to realize I had fed it cross-sectional data masquerading as panel data. That mistake cost me two weeks and a very tired grad student. It also taught me something about Scientific Method In Economics that no textbook covers: the method is only as solid as your data plumbing, and most failures happen before you write a single hypothesis. You don't need a fancy framework to do this. Observe something odd. Ask why. Build a model that explains it without inventing magic variables. Test it against data that could have falsified your claim. If it survives, publish it. If it doesn't, go back to step two and try again. The loop is old, but the discipline of actually following it in economics is rarer than people admit. Economics is different from chemistry because you can't isolate the universe in a lab. You work with messy human behavior, incomplete information, and institutional shocks that don't come with clean treatment indicators. The method still works, but you have to be honest about what counts as evidence. A correlation between coffee consumption and GDP growth means nothing until you can show the relationship isn't driven by a third variable like urbanization or education spending. That is the hard part.
How to actually run through the cycle
Start with a phenomenon you can measure. Things like inflation rates, employment changes, trade flows, or stock market reactions give you data. Behavioral questions about voter sentiment or consumer confidence work too, provided you have survey data or proxy measures. Pick one. Not three. Not five. Next, state a hypothesis in a way that could make you look wrong. This is where most students fail because they write hypotheses that absorb any outcome. Say your hypothesis is: raising the minimum wage by $1 increases unemployment by 0.5 percent within two years in low-income retail. If the data shows a 0.3 percent increase, your hypothesis is wrong, and that is useful. If it shows a 2 percent decrease, your hypothesis is also wrong, and that is also useful. Both outcomes teach you something. The only truly useless result is a hypothesis too vague to be tested. Build your model after the hypothesis, not before. Too many economists start with a DSGE framework and work backward to fit a story. The right order is story-first, model-second. Write down the mechanism in plain language. Then translate it into equations. If you cannot explain the mechanism without using jargon like "intertemporal optimization" or "rational expectations," your model is likely hiding more than it reveals.
Testing without fooling yourself
Data collection is where reality bites. I ran a difference-in-differences analysis on a policy intervention in a mid-size European country, matched matched municipalities before and after the change, and spent two days checking the parallel trends assumption. It failed. The treatment municipalities were already trending faster than the control group before the policy started. My initial result was garbage. I re-estimated using a synthetic control method instead, which built a weighted combination of untreated areas to approximate the counterfactual. The revised estimate was half the size of the original but actually credible. This is the kind of thing that makes the scientific method in economics feel more like detective work than calculation. You will encounter selection bias, omitted variable bias, measurement error, and instruments that are only weakly correlated with what they should predict. Each one can quietly invalidate your result if you ignore it. Randomized controlled trials exist in economics. They are powerful but expensive and often impossible for macro-level questions. Quasi-experiments are more common: natural disasters, policy changes, administrative cutoffs, war disruptions. These give you exogenous variation that looks like random assignment. But you still have to prove it. A border closure is not automatically exogenous. It might be a response to economic conditions you cannot observe.
Get the Full Details
What most beginners miss
The biggest blind spot is confusing statistical significance with economic significance. A coefficient can be significant at the one percent level and still be too small to matter in practice. I once saw a paper claim that a policy reduced poverty by 0.02 percent with a p-value of 0.001. Statistically solid. Practically irrelevant. Always report effect sizes alongside standard errors. Another trap is overfitting. If your model fits your sample perfectly but fails out of sample, you have tuned it to noise, not signal. Cross-validation is standard in machine learning but underused in economics. Apply it. Split your data. Train on one half. Test on the other. If your model collapses, go back to the drawing board. Robustness checks are non-negotiable. Run your analysis with different specifications, different samples, different controls. If your result disappears when you add just one more variable, your finding is fragile. Fragile findings waste other people's time. Robust ones survive scrutiny.
When the method breaks down
There are areas where the scientific method in economics hits a wall. Historical episodes are one. You cannot rerun the Great Depression. You cannot clone Argentina in 2001 and see what happens if Peronism takes a different path. Counterfactual reasoning is essential here, but it is inherently unverifiable. You can build plausible models, but you can never prove them wrong in the same way you prove a laboratory hypothesis wrong. Cultural and institutional factors are another boundary. Economic behavior changes when norms change. A survey conducted in one decade may not predict behavior in the next because social attitudes shift faster than institutions. The method assumes some stability in human preferences. That assumption is often false. Policy evaluation suffers from the Lucas critique. People change their behavior when they know a policy is in place. A model estimated on pre-policy data will mispredict post-policy outcomes because agents are optimizing differently. This is not a flaw in the method. It is a constraint you have to acknowledge explicitly.
A practical workflow
Write your research question first. Then search for existing studies that address it. Read them carefully. Identify what they leave unanswered. Formulate a hypothesis that fills that gap. Design your data collection strategy before you collect anything. Specify your empirical model in writing. Run diagnostics. Report everything, including failures. Replicate your analysis with a fresh dataset if possible. Publish your code and data so others can verify your work. This workflow takes time. A clean micro-econometric project usually requires three to six months from hypothesis to final draft. Macroeconomic work can take longer because data revisions and model recalibration are frequent. Do not rush. A result you can defend under pressure is worth more than a result you can publish quickly. The scientific method in economics is not glamorous. It involves debugging Stata scripts at midnight, arguing with reviewers about identification strategies, and accepting that most of your hypotheses will be wrong. But when you get it right, you learn something real about how the world works, and that is rare in any field.