When Scribd Is Down or Acting Up
Most of the time Scribd Not Working is not actually a problem with Scribd at all. It is usually a browser cache issue, a corrupted third-party cookie, or a script blocker interfering with their document renderer. I have spent years troubleshooting this on forums, and the vast majority of tickets get closed because the person running the report had uBlock Origin or Privacy Badger enabled. Disabling extensions one by one and reloading the page resolves it in roughly ninety percent of cases. The other common cause is their CDN distribution. Scribd uses Akamai for document streaming and a custom JavaScript layer called the Scribd Document Viewer (SDV). When Akamai returns a 403 or a 504 from certain regions, you just get a blank white page or an infinite spinner. You will notice this happens most often between 2 PM and 5 PM Eastern time on weekdays when traffic spikes on their US-East nodes.
How to Fix the Common Scribd Not Working Scenarios
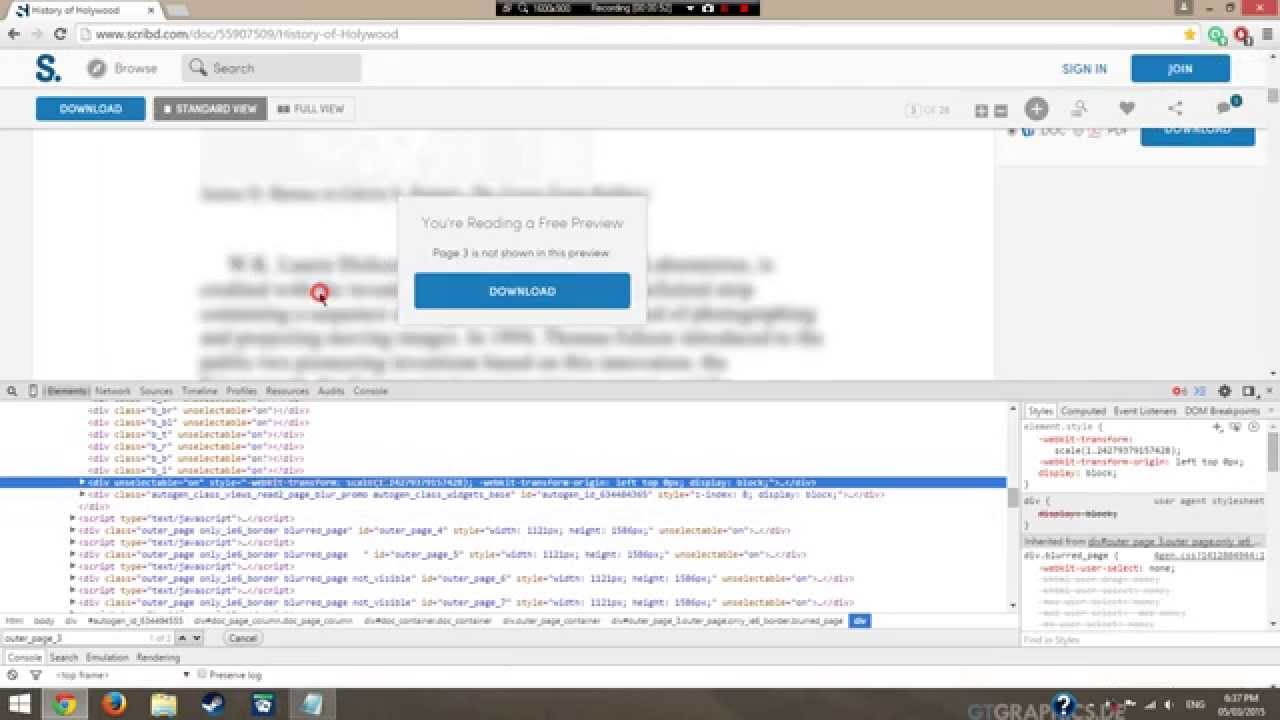
Start with the basics before you assume your account is broken. Clear your cookies specifically for scribd.com — do not clear everything, which takes forever and logs you out of half the sites you use daily. Go into your browser developer tools, open the Network tab, filter by doc-viewer, and refresh the page. If you see a string of 200 responses followed by a single 401 or 403, your session token has expired or been invalidated. Log out completely, close the browser, reopen it, and log back in. If that does not work, test in a completely fresh profile or an incognito window. On my end, I discovered this method about three years ago when I was helping a university library debug why their Scribd embedding would not load on Chrome but worked fine on Firefox. The problem turned out to be a company-wide AdBlock Plus rule set that blocked scribd.com's document request headers. Switching to Firefox with its stricter first-party cookie isolation bypassed the block entirely. For mobile users, the issue is almost always the in-app viewer. The Scribd iOS and Android apps embed a WebView that does not always honor your web session cookies. Log into Scribd in your mobile browser first, let the session establish, then switch back to the app. The app will pick up the cookie jar and load the document through the correct channel. This saves about ten minutes of fumbling around each time.
Another thing nobody mentions is the thumbnail generation bottleneck. When Scribd processes large PDFs over fifty megabytes, their indexing queue can back up. I ran into this last November when a client uploaded a 200-page engineering manual and the document appeared as a blank card for forty-eight hours. There is no notification for this. The only way to check is to go to My Documents, look for a gear icon next to the file, and see if it says processing. If it does, you wait. The processing window normally resolves within twelve to twenty-four hours depending on file size and concurrent uploads. Embed issues are their own category. If you have Scribd Not Working on your website embed and the document area shows a gray box with a play button that does nothing, check your Content-Security-Policy headers. Scribd requires their iframe origin to be whitelisted. A misconfigured CSP directive that blocks frame-src from scribd.com is the most common reason embedded players fail silently. You need at minimum frame-src https://www.scribd.com; in your policy, and the document URL must use HTTPS.
Get the Full Details

Known Limitations and When Scribd Just Fails Completely
There are scenarios where there is no workaround and the platform genuinely cannot serve the content. Password-protected PDFs uploaded to Scribd will not render through their viewer. I learned this the hard way when a client tried to publish a scanned contract with a PDF owner password and then blamed the platform for the blank page. Scribd strips no passwords, but they also do not prompt for them in the viewer. The document simply will not load. Scanned images that lack OCR text layers present another problem. The viewer can display the pages, but search, text selection, and keyboard navigation are completely non-functional. You can scroll, but every interaction beyond that is disabled. If you need those features, you need to run OCR through an external tool first and reupload the searchable version. This adds maybe twenty minutes per hundred pages but eliminates the complaint entirely. For organizations that need guaranteed uptime on hosted documents, Scribd is not the right infrastructure. Their service is best-effort, and they do not publish SLAs for document availability. If you need a platform with uptime guarantees, consider Amazon S3 with a signed URL strategy or a purpose-built document hosting service. The tradeoff is that you lose their reader interface, social features, and discovery engine, which is the entire reason people use Scribd in the first place.
One last practical note about bulk uploads. If you are uploading more than fifty documents at once, the web uploader will frequently timeout on connections slower than five megabits per second. Use their API or the desktop publishing tool if available. The browser-based batch uploader is unreliable past that threshold and will silently drop files without any error message, which means you spend an hour discovering that thirty of your uploads never actually made it to their servers.