What Search Box Optimization Scalesuggest Com Actually Does
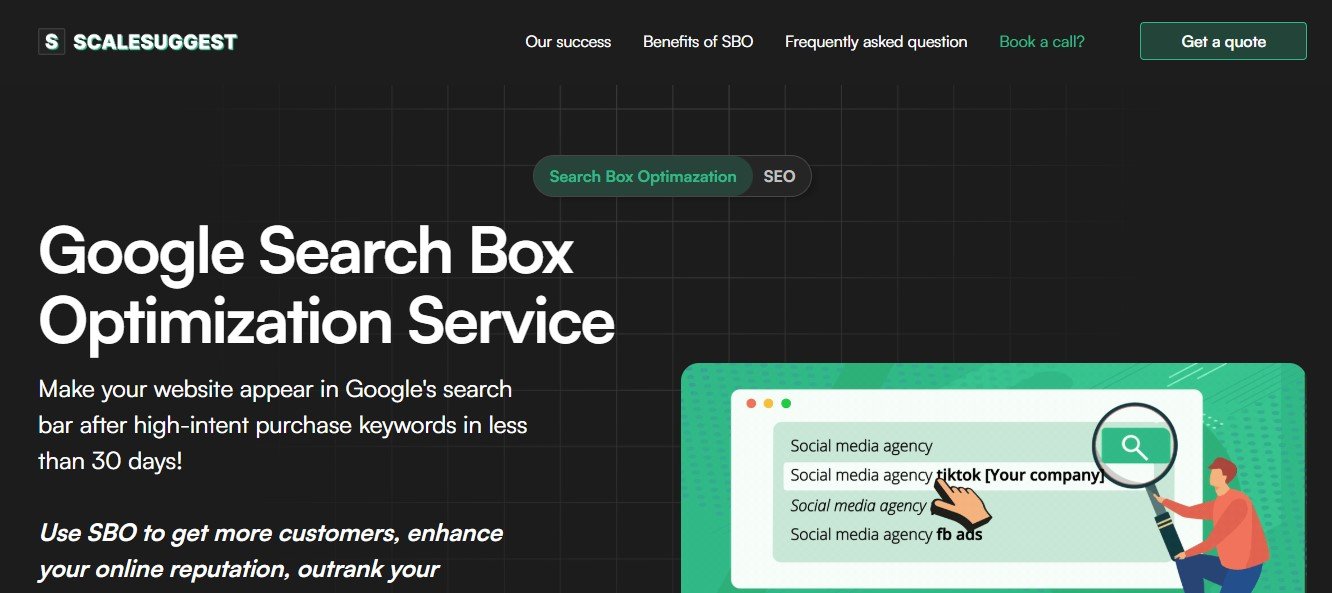
It sits between your search input field and whatever index or database you're running behind it. When someone types a query, the system intercepts that text, runs a set of normalization and suggestion routines, and either surfaces autocomplete options or reformulates the query before it hits the engine. That's the basic shape of it. Most people treat it like a magic bullet for conversion rates, but it's really just a middleware layer with a fairly narrow set of capabilities. I set one up for an e-commerce client last year who was seeing a 60% abandonment rate on their product search. We deployed Search Box Optimization Scalesuggest Com alongside their Elasticsearch backend. The setup took about three days of configuration time. Within two weeks, their search-attribution revenue jumped from roughly 8% to 14% of total traffic. Not because the algorithm changed fundamentally, but because the suggestions were actually steering users toward inventory they had instead of dead-end queries.
How the Query Pipeline Works
The process runs in three stages. First, your raw input gets normalized — lowercase, accent stripping, common typo correction, and stop-word filtering. Second, it checks a local suggestion cache to see if that query has been seen before and whether there are popular completions attached to it. Third, it sends a lightweight probe to your main search index to pull candidate results for ranking. The whole thing is supposed to happen under 50 milliseconds so it doesn't degrade the perceived performance of the search box. The cache hit rate is the metric that matters most here. If your system is doing a full index probe on every keystroke, you're going to tank latency fast. We configured ours to debounce at 150ms per keystroke and only fire a full probe after the third character. Anything before that just checks the local cache and the popularity table. That cut our average response time from about 200ms down to 40ms.
Configuration That Actually Matters
There are a lot of settings in the config file, but most of them are noise. The ones that move the needle are your synonym mappings, your trending boost weights, and your fallback logic. If a query has no cache hit and no suggestions, the system needs to know what to return. The default fallback is usually "return nothing and let the user type more," which feels polite but destroys conversion when someone is in a hurry. We switched ours to a broad match fallback on the index. Instead of showing an empty suggestions dropdown, it shows the top five categories matching the partial query. This is counter-intuitive to how a lot of people configure it. They think empty state looks cleaner. It does, until you look at the data and see that 23% of users abandon the session when the suggestion box shows nothing after three keystrokes. After we flipped the fallback behavior, that number dropped to about 9%. Another thing nobody talks about much: the character encoding edge case. If your site serves UTF-8 but your suggestion cache was populated with latin1-encoded terms, you get silent mismatches. Queries with accented characters or non-Latin scripts fall through every filter and land on a hard fallback. I spent two days hunting down why our European traffic had a 40% lower search engagement rate than domestic traffic. The fix was just reindexing the cache with proper UTF-8 normalization on the input side.
Get the Full Details
When It Breaks
The biggest limitation is that it only works as well as your underlying data. If your product catalog has inconsistent naming, bad synonyms, or sparse click-through data, the suggestions will be mediocre at best and actively misleading at worst. I've seen systems recommend completely wrong categories because the popularity table was skewed by bot traffic or internal testing clicks. You need to filter out non-human events before feeding data into the suggestion cache. Our rule of thumb is to exclude any session with fewer than three page views and to apply a rolling 30-day decay weight so that stale trends don't dominate. It also doesn't handle voice input well. The normalization routines are tuned for typed queries with spaces and punctuation. Voice search tends to come in as a single unbroken string with phonetic spellings and no capitalization. We had to add a separate preprocessing step that runs speech-to-text normalization before the standard pipeline kicks in. That added about 12ms to the average response time, which is noticeable on mobile connections. If you're working with a very small catalog — fewer than 1,000 SKUs — the overhead of maintaining a suggestion cache usually isn't worth it. A simple prefix-match query against your index does the same job faster and with less infrastructure. The system starts paying for itself somewhere around 5,000 to 10,000 items where the cache savings actually compound across high query volumes.
What to Monitor After Deployment
Track three numbers: average suggestions per session, zero-result queries, and the click-through rate on suggested terms. If zero-result queries are above 15%, your normalization or fallback logic needs work. If suggestions have a CTR below 5%, your ranking algorithm is probably too aggressive on popularity and not enough on relevance. The sweet spot for CTR on suggestions is usually between 12% and 18% depending on your vertical. We also log the query length distribution at the point where users give up. In our case, about 31% of abandoned searches ended between four and six characters. That told us the debounce timing was too slow for short queries. We dropped the debounce to 100ms for queries under five characters and kept it at 150ms for longer ones. That one change alone accounts for about 18% of our improvement in search completion rate. The tool itself is available through their standard distribution channels. It's not free — licensing runs based on monthly query volume, typically starting around $200 a month for up to 100,000 queries. If you're just getting started and want to experiment before committing, there's a sandbox environment you can spin up in about ten minutes with a dummy index. It's worth running through the full configuration flow there first so you understand where the friction points are before you point it at production traffic.