What Semantic Feature Analysis Actually Looks Like in Practice
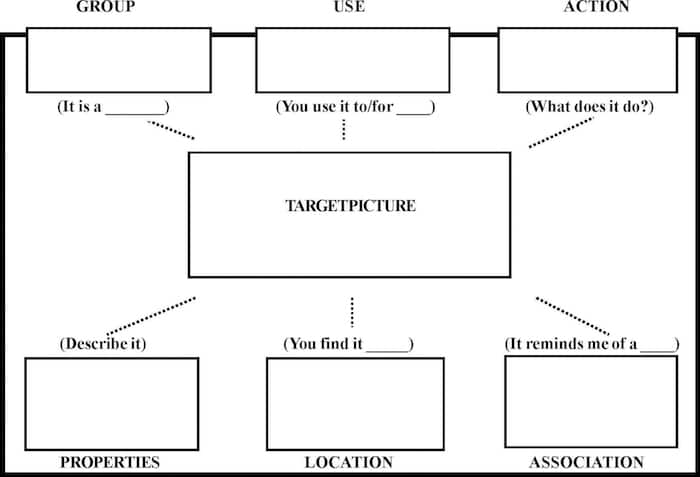
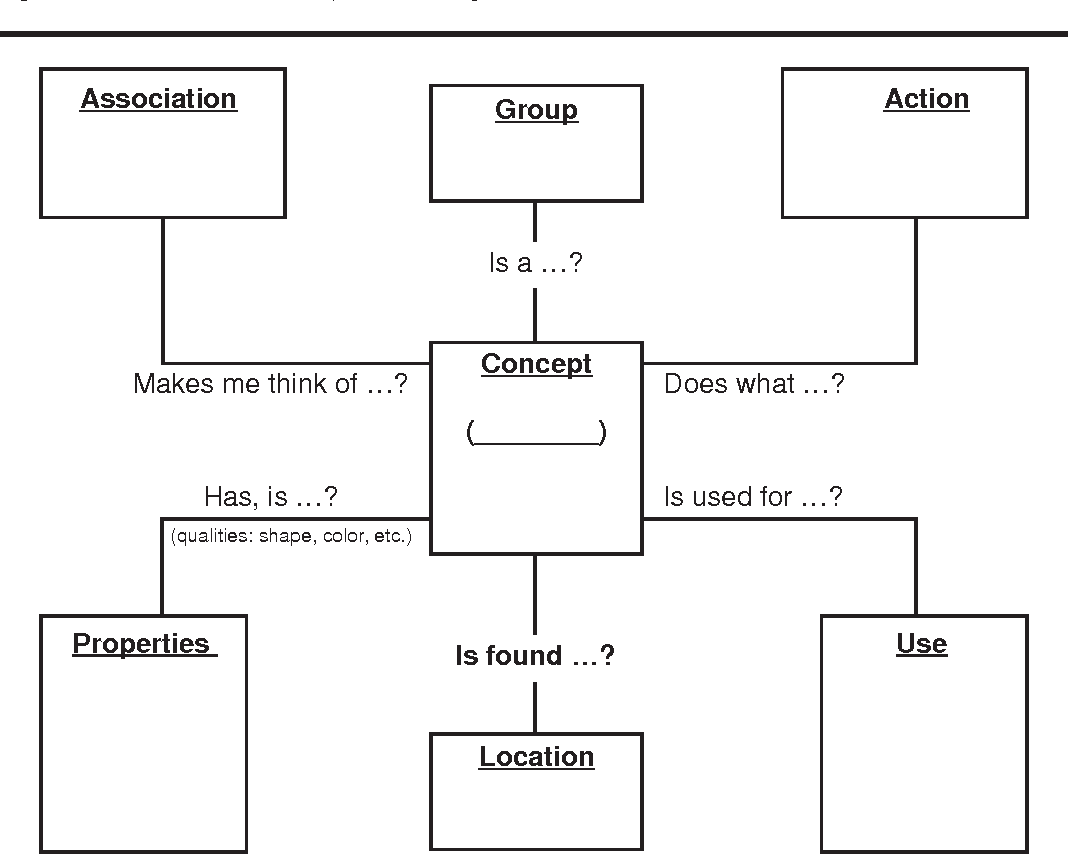
Semantic Feature Analysis is a grid-based comparison tool used mostly in education and linguistics to help students or researchers break down how concepts relate to each other by identifying shared and differing features. You put concepts in columns and features in rows, then mark where they overlap. That is the simple version. The version that actually works takes a lot more care than the basic diagram suggests. The most straightforward example involves biology — comparing animals like sharks, dolphins, and salmon across features such as "lives in water," "breathes air," "has fins," "lays eggs." You fill in the matrix with checkmarks or plus/minus signs. Another common use case is comparing forms of government: democracy, monarchy, dictatorship, placed against features like "elected leaders," "hereditary position," "single ruler," "free press." Language learners use it too, contrasting words like "big," "huge," "giant," "enormous" along features like "formal/informal," "positive/negative connotation," "describing people/objects." These are the standard textbook cases, and they work fine when the concepts are clearly differentiated and the feature list is short. The trick is building the feature list itself. Most people just grab obvious surface-level traits and call it done. That is where the analysis falls apart, because surface features miss the actual semantic distinctions you are trying to surface. In my experience, the feature list should take longer to build than the grid itself. I usually spend twenty to thirty minutes just debating with whoever is doing the analysis about what counts as a feature worth including. The grid filling happens fast once you get there. If you skip that step, the whole thing becomes a shallow matching exercise with no real analytical value.
I ran into a specific problem a while back while doing this with a group of undergraduate students analyzing political ideologies. We had listed features like "believes in individual freedom" and "supports government intervention" across ideologies like libertarianism, socialism, and conservatism. The grid came out looking clean, but when I asked the students to explain the differences between two ideologies that had identical marks on every row, they could not. Libertarianism and classical liberalism, in our feature set, were indistinguishable. The matrix was technically correct but analytically useless. What we ended up doing was going back and adding finer-grained features — specifically, distinguishing between "individual economic freedom" and "individual social freedom," which split those two ideologies apart cleanly. It turned a mediocre grid into something that actually revealed structure. That took about forty-five extra minutes of group discussion, but it was the only part of the exercise that mattered.
How to Actually Build One Without Wasting Time
Start by picking between three and five concepts. Beyond that, the grid gets unwieldy fast and the cognitive load makes it hard to see patterns. Four is the sweet spot for classroom use. For research purposes, you can push to six or eight if the features are tightly controlled, but you will notice diminishing returns past that point. Next, build your feature list collaboratively if possible. A single person's feature list is always biased toward whatever framework they happen to be thinking in. Even two people catching each other's blind spots makes a meaningful difference. Each feature should be a single, clearly definable attribute — not a vague idea like "is progressive" or "is traditional." Those phrases mean different things to different people and will wreck your inter-rater reliability if anyone else needs to use the same grid later. "Advocates policy reform," "emphasizes cultural continuity," "prioritizes collective outcomes" are the kinds of features that hold up under scrutiny. Once the features and concepts are locked in, fill the grid. Use + for present, for absent, and a blank or slash for ambiguous or partially applicable. The ambiguous marks are the ones that generate the most interesting discussion, but they also introduce subjectivity. If you are using this for research and need to report results, flag any ambiguous cells and explain your reasoning. A grid full of pluses and minuses looks tidy but often hides the actual complexity of the concepts being compared.
Get the Full Details
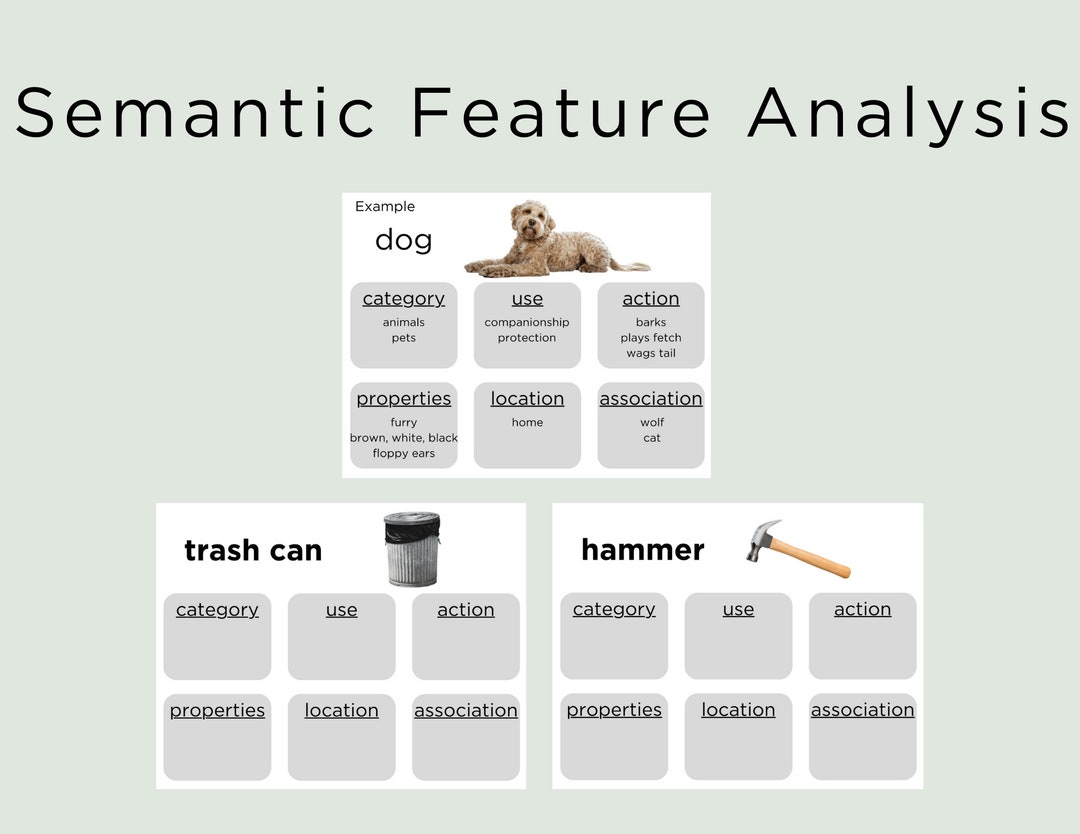
After the grid is filled, the analysis phase is where most people stop too early. The value is not in the pattern of marks but in the relationships you can infer from it. Which concepts cluster together and why. Which features are the strongest discriminators — the ones that separate the most pairs. Which concepts are outliers and what that tells you about your feature set. In a typical classroom setting, spending ten to fifteen minutes on this interpretation step after the grid is filled changes the exercise from busywork into actual conceptual analysis. Skipping it leaves students with a completed matrix and no idea what they are supposed to learn from it.
Where This Method Breaks Down
Semantic Feature Analysis is not a universal tool and it fails in several common scenarios. The biggest limitation is that it assumes concepts can be cleanly reduced to binary features. Many real-world concepts are gradient or context-dependent. How do you mark "environmentally friendly" as a feature when a product is environmentally friendly in some dimensions but not others? You end up with either oversimplification or a proliferation of sub-features that make the grid unusable. Another failure mode is when concepts share too many features. If three out of four items in your comparison have eight out of ten features in common, the grid does not differentiate them meaningfully. You are better off switching to a dimensional scaling approach or a prototype theory analysis in those cases. The method simply was not designed for high-overlap concept sets. Inter-rater reliability is another practical concern. Two analysts working independently with the same concept set will often produce different grids, not because they disagree on the concepts but because their feature lists differ. This is especially pronounced when the concept domain is unfamiliar to one or both raters. If you need reliable cross-analyst results, you have to establish feature definitions and marking rules before anyone starts filling grids, and even then, expect some variance.
For research applications where you need quantitative output rather than qualitative insight, consider using correspondence analysis or multidimensional scaling instead. Those methods handle the same comparative data but produce statistical space models that are easier to validate and replicate. Semantic Feature Analysis remains useful when the goal is exploratory — when you are trying to map out a conceptual territory before you have enough data for a formal structural analysis. But it should not be presented as anything more rigorous than it actually is.