Understanding Semi Conservative Dna Synthesis In Practice
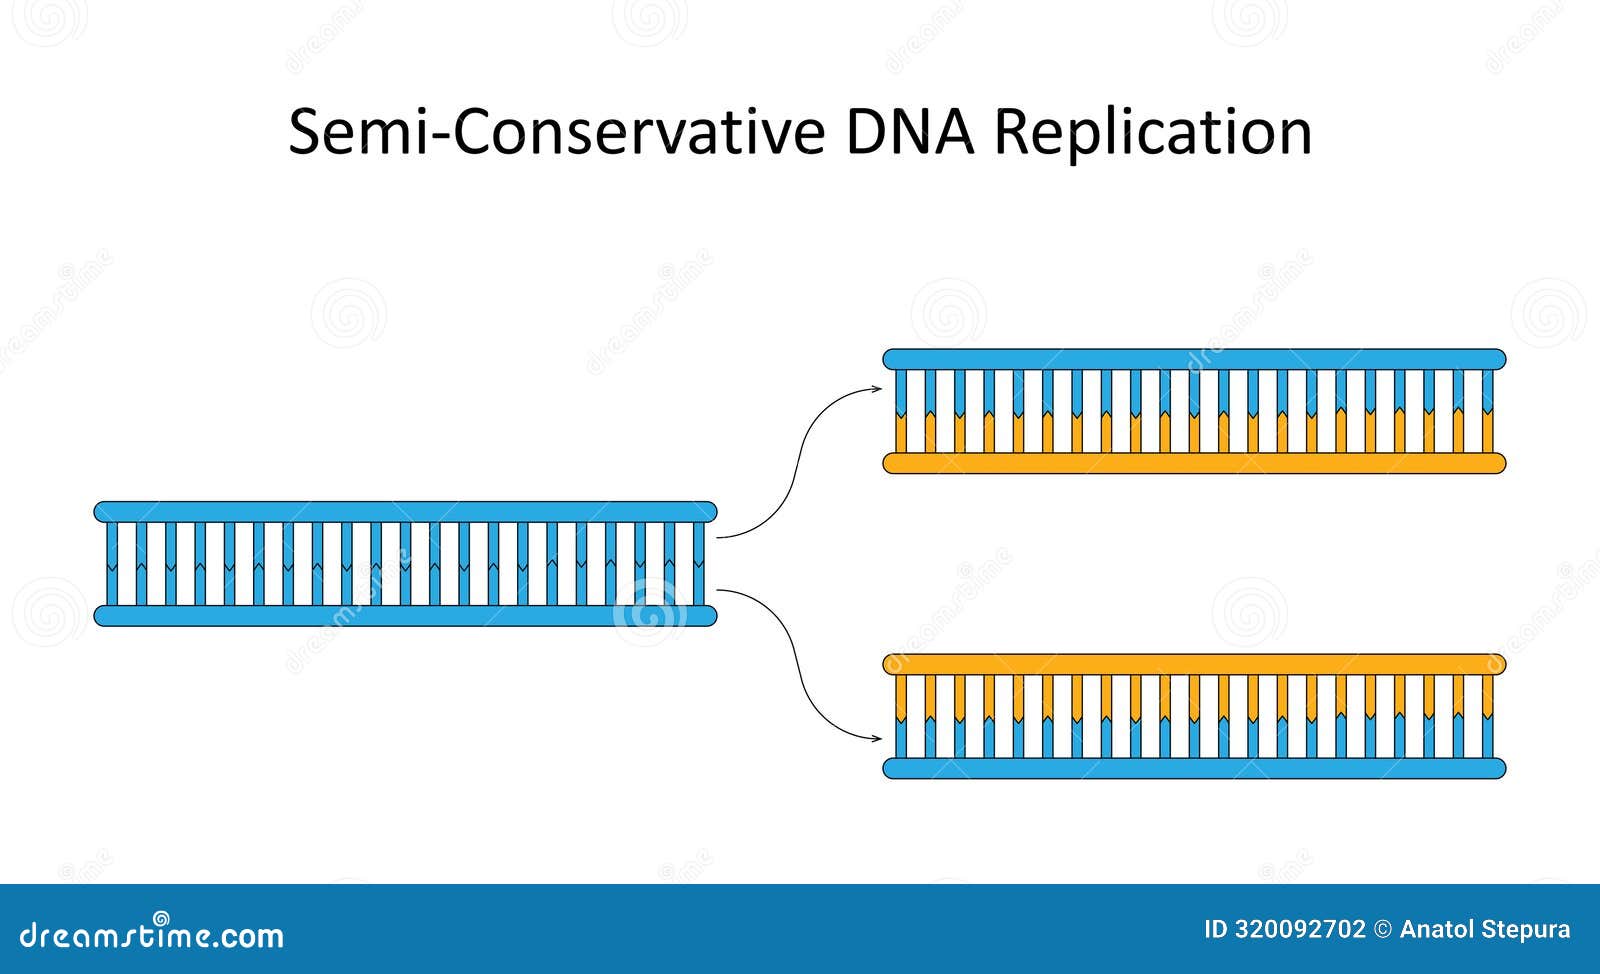
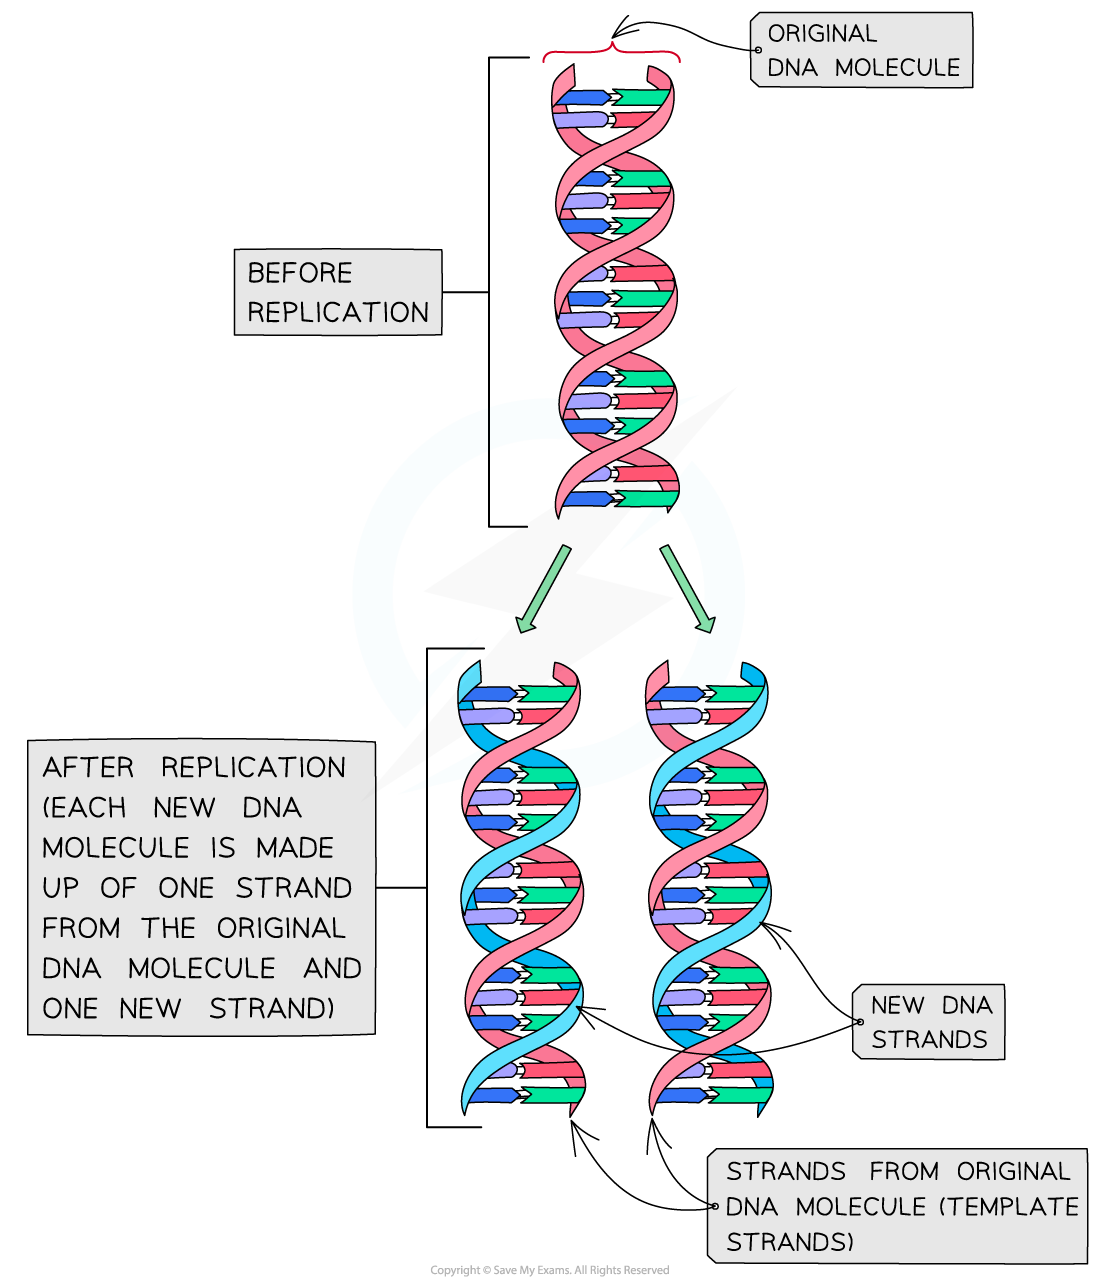
The basics of semi conservative replication are often taught with diagrams showing two perfect daughter helices splitting cleanly from a parent. Real life doesn't look that clean. When you're running a replication assay or preparing templates for sequencing, what actually matters is understanding the mechanics well enough to predict where things will go wrong. Each new DNA molecule retains exactly one strand from the original molecule, and one entirely newly synthesized strand. That's the model. The execution in the lab is where people get tripped up. During replication, helicase unwinds the double helix at the origin of replication. Single strand binding proteins stabilize the separated strands. DNA polymerase can only add nucleotides in the 5 prime to 3 prime direction, which creates the famous leading and lagging strand problem. The leading strand gets synthesized continuously toward the replication fork. The lagging strand comes out as Okazaki fragments that are later ligated together. Each resulting double helix contains one old strand and one new strand. That is what makes it semi conservative rather than conservative or dispersive, terms that came out of the Meselson Stahl experiment in 1958 using density gradient centrifugation with heavy nitrogen isotopes. In modern molecular biology workflows, this concept becomes relevant when you are working with replicated plasmid templates, doing site directed mutagenesis, or setting up rolling circle amplification. The semi conservative nature of replication affects how you interpret sequencing results, how you design primers, and how you understand the behavior of your template after multiple rounds of amplification.
I remember working through a cloning project where our sequencing traces came back looking inconsistent across different colonies. Same insert, same primers, same polymerase. After ruling out contamination and primer issues, I traced it back to incomplete separation of template strands during our denaturation step. We were running 94 degrees for 30 seconds, which is fine for most standard PCR but when you are trying to ensure complete strand separation for a subsequent replication based assay, that time and temperature combo left residual double stranded regions that the polymerase kept falling back onto instead of engaging the single strand template properly. Switching to 98 degrees for 10 seconds plus a longer initial denaturation of 2 minutes fixed it. The data cleaned up immediately. One thing beginners consistently miss is the directionality constraint. DNA polymerase cannot start synthesis de novo. It needs a primer with a free 3 prime hydroxyl group. RNA primers do this job in vivo, laid down by primase. In vitro you supply DNA primers. This means every stretch of new synthesis has a starting point that is technically not part of the original template strand. On the lagging strand, each Okazaki fragment begins with an RNA primer that eventually gets replaced. If you are doing any kind of precise end mapping or working with short amplicons, that primer addition and removal leaves behind subtle artifacts that show up as small deletions or sequence gaps if you are not accounting for them. Another counter intuitive point involves the fidelity differences between leading and lagging strand synthesis. Studies have shown that the lagging strand accumulates more replication errors because the repeated cycle of primer removal and gap filling introduces additional opportunities for polymerase errors and misincorporation. If you are cloning a gene and noticing higher than expected mutation rates in certain regions, consider whether those regions fall within sequences that would have been synthesized as part of lagging strand fragments during your amplification cycles. Using high fidelity polymerases and minimizing cycle count helps, but the asymmetry is real and it is not something most protocol guides mention.
When performing experimental validation of semi conservative replication, the standard approach involves labeling parental DNA with a heavy isotope like 15N, allowing one or more rounds of replication in light 14N medium, then analyzing the density of the resulting DNA molecules through cesium chloride gradient centrifugation. After one round you see a single intermediate band, confirming that each molecule contains one heavy and one light strand. After two rounds you get two bands, one intermediate and one light, in a one to one ratio. This pattern rules out both conservative replication, which would show one heavy and one light band after round one, and dispersive replication, which would produce a smear across densities rather than discrete bands. For modern applications where you are not running density gradients, the semi conservative principle shows up in techniques like strand displacement amplification and methods that rely on controlled denaturation and renaturation of DNA templates. If you are doing any quantitative work with copied templates, knowing how many replication rounds have occurred and whether your template integrity has held up matters more than people usually account for. Each round doubles the total molecule count but also doubles the cumulative chance of introducing errors, especially on the lagging strand equivalents in your synthetic system. The biggest bottleneck I have seen with semi conservative replication based methods is template degradation during repeated cycling. Every denaturation step puts stress on the DNA. High GC content regions resist complete denaturation at standard temperatures and can form secondary structures that stall polymerase. Low complexity sequences can cause slippage, leading to insertions or deletions that accumulate over successive rounds. I had a case where a 200 base pair AT rich region kept dropping out after six amplification cycles in a rolling circle setup. Adding betaine at 1.5 M and switching to a polymerase formulation with a helicase domain completely resolved the drop out. Standard Taq had no trouble with the rest of the template, just that one region. Betaine lowers the melting temperature differentially across the sequence, helping those stubborn AT clusters open up without requiring extreme temperatures that would damage the enzyme or the rest of the template over time.
Get the Full Details

If you need to work with very long templates or require near perfect fidelity across many replication rounds, consider moving away from standard PCR based approaches altogether. Long range polymerase systems with proofreading activity and specialized buffer conditions handle this better. For single molecule studies where you need to track individual parental strands through replication, bead based immobilization combined with fiber assays or next generation sequencing approaches give you strand specific resolution that bulk methods simply cannot provide. The bottom line is that semi conservative replication is not just a textbook diagram. It is a mechanical reality that shapes how your DNA behaves in every replication based protocol you run. Pay attention to primer design, denaturation conditions, polymerase choice, and cycle number. The details matter more than the general principle, and the principle itself is straightforward once you stop treating it like abstract biology and start thinking about it as a set of physical constraints you have to work within.