What You're Actually Doing When You Run a Sensitivity Analysis
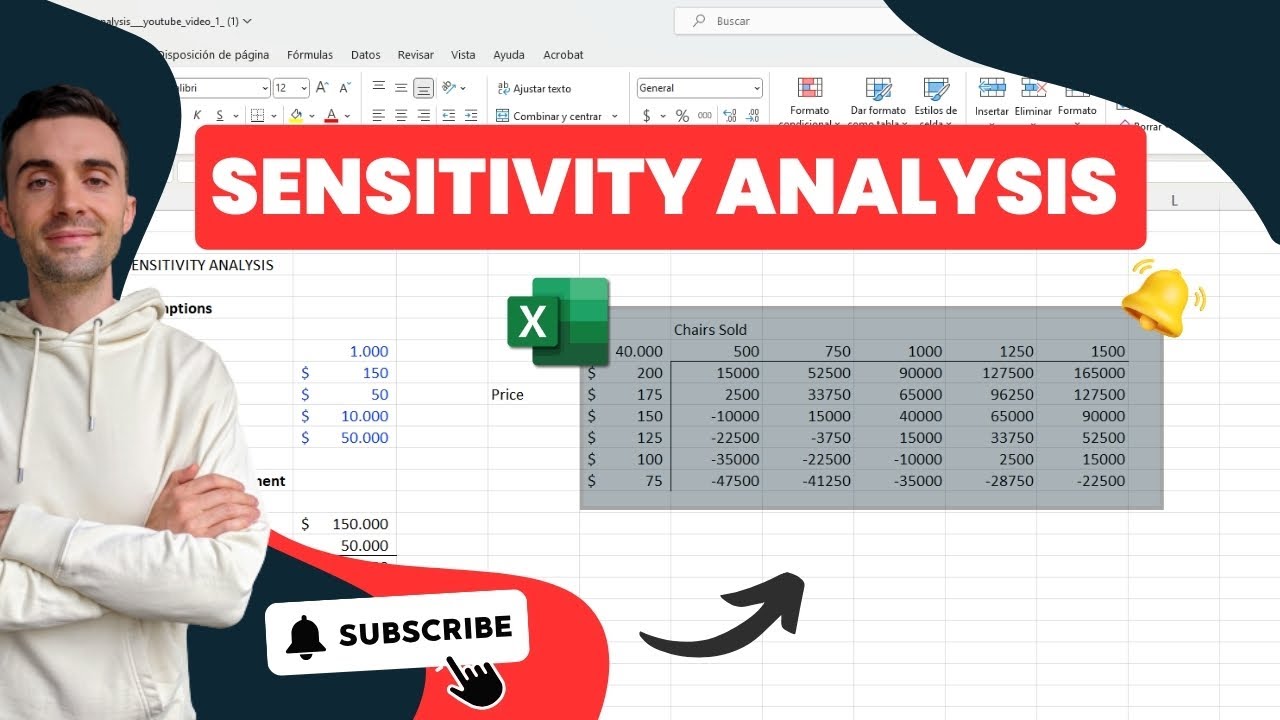
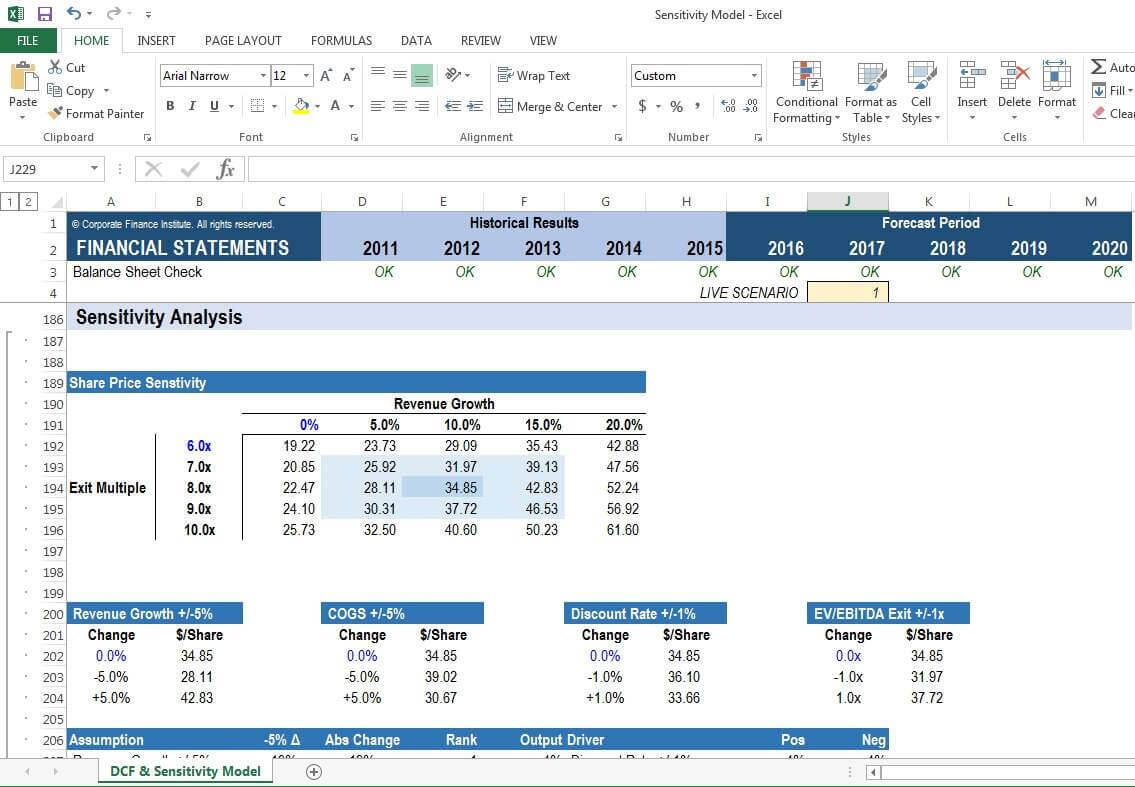
Sensitivity Analysis In Excel is just a systematic way of asking what happens to your output when one or more of your inputs change. That's it. People make it sound more complicated than it is because there are multiple approaches depending on how many variables you're juggling. If you have two variables and a single cell you want to track, Data Tables do the job. If you need to maximize or minimize something subject to constraints, that's Solver territory. If you're dealing with probabilistic inputs, you look elsewhere entirely. I built my first financial model in 2009 using nothing but Data Tables and a whole lot of copied cells. It took three days to set up and broke whenever someone changed a tab order. The modern version of the same thing takes about forty minutes if you know what you're doing.
Manual Approach: Setting Up a Two-Variable Data Table
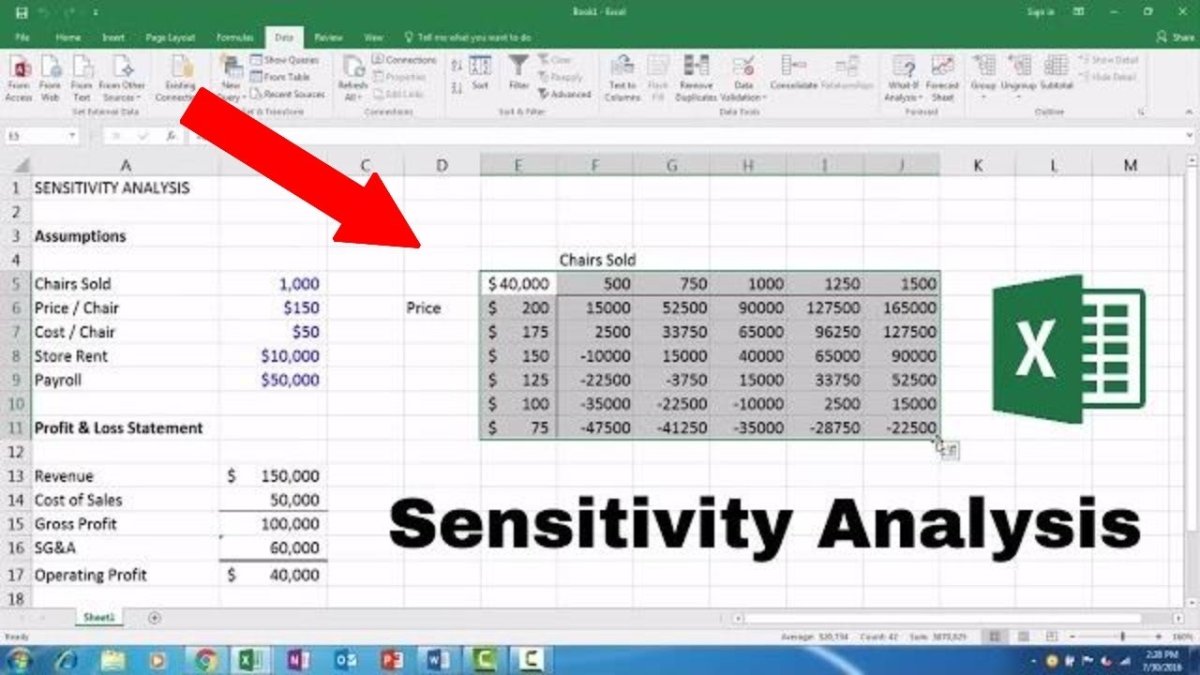
Here's the straightforward way to do it without any add-ins or macros. Let's say you have a discounted cash flow model where Net Present Value is calculated in cell B12, and you want to see how NPV changes when both the discount rate (B3) and the revenue growth assumption (B5) vary. First, lay out your grid. Put the discount rates across the top row starting from C2, and the growth rates down the left column starting from B3. These should be reasonable ranges based on your actual assumptions — don't just throw 1%, 2%, 3% in there unless that's actually plausible. Drag them from 5% to 15% in increments that reflect your uncertainty. Then put the NPV formula reference in the top-left corner of your grid at C2. Select the entire range including the formula cell, go to Data What-If Analysis Data Table, and fill in the Row Input Cell as B5 (the growth rate) and the Column Input Cell as B3 (the discount rate). Hit OK and Excel populates the whole grid.
That's the basic mechanism. It forces Excel to recalculate your entire model for every combination of inputs and writes the results into the table. The advantage is that it's dynamic — change your base model assumptions and the table updates. The disadvantage is that it's slow with large models because Excel recalculates every single cell in the table on every change.
Get the Full Details

When Your Model Has More Than Two Variables
People hit a wall here quickly. Data Tables cap out at two input variables. If you need to test discount rate, growth rate, and operating margin simultaneously, the native tool doesn't work. You have a few options, and most of them are ugly. The brute force method is building nested Data Tables inside another Data Table, which is possible but requires array formulas and creates models that are nearly impossible to audit. Another approach is writing a short VBA macro that loops through your input combinations and writes results to a worksheet. I've done this and the code is straightforward, but the maintenance burden is real — if your model structure changes, the macro breaks and you have to debug it. A practical workaround I discovered involved a scenario manager approach. Instead of running everything at once, I set up three separate Data Tables — one for each pair of variables — and left the third variable fixed at its base case. It meant three tables instead of one comprehensive cross-tabulation, but each one stayed clean, traceable, and fast. For most business models, that's sufficient. The interactions between variables are usually not dramatic enough to warrant the complexity of a full three-dimensional analysis.
Using Solver for Constrained Sensitivity Testing
Solver does something different. It's not a sensitivity analysis tool in the traditional sense — it's an optimization engine. But you can use it to answer questions like "how much can my revenue drop before NPV turns negative?" That's a form of sensitivity analysis, specifically a break-even or threshold analysis. Set up your model normally, then open Solver from the Data tab. Your objective is the output cell you care about, your variable cell is the input you're testing, and your constraint is the threshold value. For example, set the objective to B12 (NPV), the variable to B5 (revenue growth), and add a constraint that B12 equals zero. Running Solver gives you the exact break-even growth rate. This is more precise than eyeballing a Data Table and it works even when your model is complex. The catch is that Solver finds one solution based on your starting point, and if your model has multiple local optima or non-linear behaviors, it might miss the answer you're looking for. Always run it from different starting values to check. I lost a day once because Solver found a break-even point at 3% growth when the real answer was at 11% — there was a secondary equilibrium my model had that I hadn't noticed.
The Hidden Cost of Sensitive Models
There are things about sensitivity analysis in Excel that nobody warns you about. First, circular references. If your model has any kind of feedback loop — revenue drives hiring, hiring drives costs, costs drive pricing — Data Tables will either error out or give you wrong answers depending on your iteration settings. Turn on iterative calculation under File Options Formulas, set a reasonable maximum iteration count, and validate your results against a known baseline. I learned this the hard way when a consulting client sent me a model where the sensitivity table showed NPV increasing as the discount rate went up, which is backwards. The circular reference was amplifying errors across iterations. Second, precision decay in large tables. When you generate a 50 by 50 Data Table in a model with ten thousand cells, Excel's calculation engine starts dropping precision in ways that are invisible until you compare outputs against manual calculations. The differences are small — usually in the fourth or fifth decimal place — but they add up and can create false confidence in your results. If your table has more than 1,000 cells, verify the corner cases manually. Third, and this is the one that wastes the most time: volatility. Data Tables recalculate every time anything in your model changes, even if the changed cell has no logical connection to the variables in your table. For a simple model this is fine. For a model with fifty thousand rows and fifty thousand table cells, a single keystroke can trigger several seconds of recalculation. Turn off automatic calculation while building and editing, then switch it back when you're ready to generate the final table.
When Excel Is the Wrong Tool
Sensitivity Analysis In Excel works well for static, deterministic models with a handful of variables. It breaks down when you need to model correlated inputs, incorporate probability distributions, or run thousands of iterations. Monte Carlo simulation in Excel is possible with add-ins like @RISK or Crystal Ball, but those cost money and add licensing overhead. Free alternatives like OpenOffice Calc have limited support, and Python-based tools like NumPy and Pandas handle this kind of analysis far more efficiently. If your model requires more than three variables, involves time-series dependencies, or needs statistical rigor beyond a simple grid of outcomes, you're better off exporting your assumptions and running the analysis in a purpose-built environment. Excel is fine for presenting results to stakeholders who are comfortable with spreadsheets. It's not fine for generating them when the problem gets even moderately complex.